
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by SurePassExams: https://drive.google.com/open?id=1l8hKwlwbHb5pM5CrcGaaf48CSiTnQZdz
If you are still troubled for the Amazon MLA-C01 Certification Exam, then select the SurePassExams's training materials please. SurePassExams's Amazon MLA-C01 exam training materials is the best training materials, this is not doubt. Select it will be your best choice. It can guarantee you 100% pass the exam. Come on, you will be the next best IT experts.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> VCE MLA-C01 Exam Simulator <<
If you buy the MLA-C01 study materials online, you may concern the safety of your money. If you do have the concern, you can just choose us. We use the international recognition third party for the payment. It will ensure the safety of your money. We are pass guaranteed if you buy MLA-C01 Exam Dumps of us, we also money back guarantee if you fail to pass the exam. If you find that your rights haven’t got enough guaranteed, you can ask for refund, and the third party will protect your interests.
NEW QUESTION # 187
A company is planning to use an Amazon SageMaker prebuilt algorithm to create a recommendation model. The algorithm must be able to make predictions on high-dimensional sparse data. Which SageMaker algorithm should the company choose for the recommendation model?
Answer: A
Explanation:
The Factorization Machines algorithm in SageMaker is specifically designed for recommendation systems and works well with high-dimensional sparse data such as user-item interactions. It efficiently models variable interactions and is the best choice for building a recommendation model in this scenario.
NEW QUESTION # 188
A company has trained an ML model in Amazon SageMaker. The company needs to host the model to provide inferences in a production environment.
The model must be highly available and must respond with minimum latency. The size of each request will be between 1 KB and 3 MB. The model will receive unpredictable bursts of requests during the day. The inferences must adapt proportionally to the changes in demand.
How should the company deploy the model into production to meet these requirements?
Answer: B
Explanation:
Amazon SageMaker real-time inference endpoints are designed to provide low-latency predictions in production environments. They offer built-in auto scaling to handle unpredictable bursts of requests, ensuring high availability and responsiveness. This approach is fully managed, reduces operational complexity, and is optimized for the range of request sizes (1 KB to 3 MB) specified in the requirements.
NEW QUESTION # 189
A company uses AWS CodePipeline to orchestrate a continuous integration and continuous delivery (CI/CD) pipeline for ML models and applications.
Select and order the steps from the following list to describe a CI/CD process for a successful deployment.
Select each step one time. (Select and order FIVE.)
. CodePipeline deploys ML models and applications to production.
CodePipeline detects code changes and starts to build automatically.
. Human approval is provided after testing is successful.
. The company builds and deploys ML models and applications to staging servers for testing.
. The company commits code changes or new training datasets to a Git repository.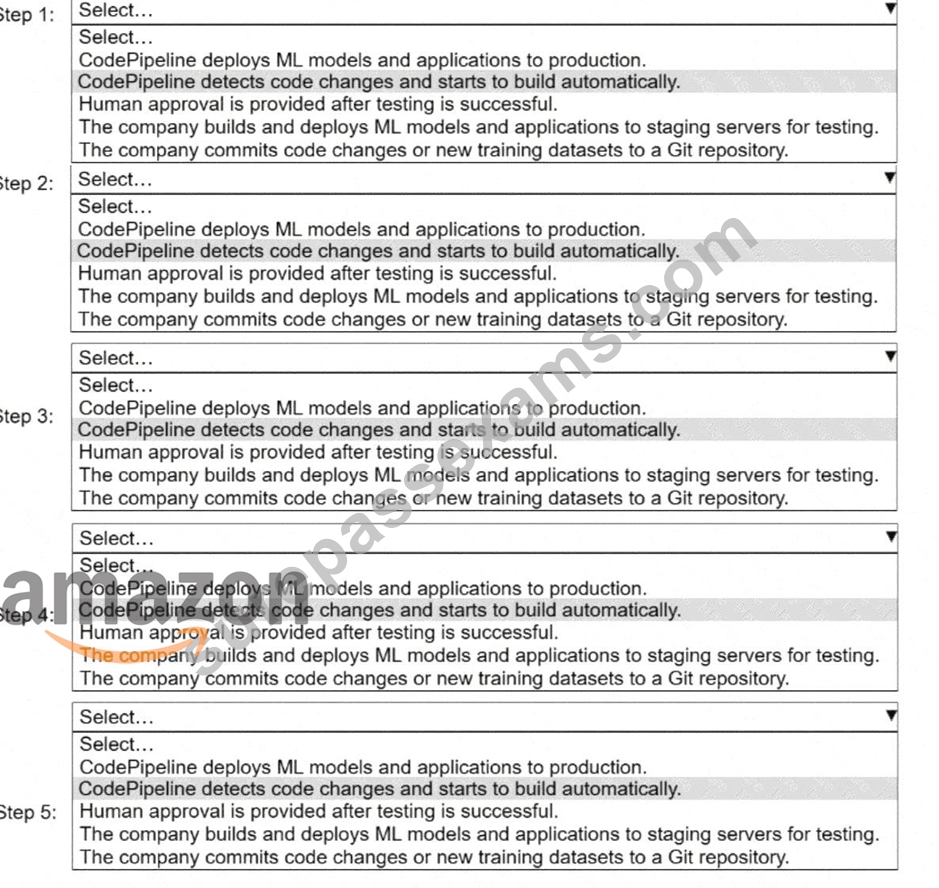
Answer:
Explanation: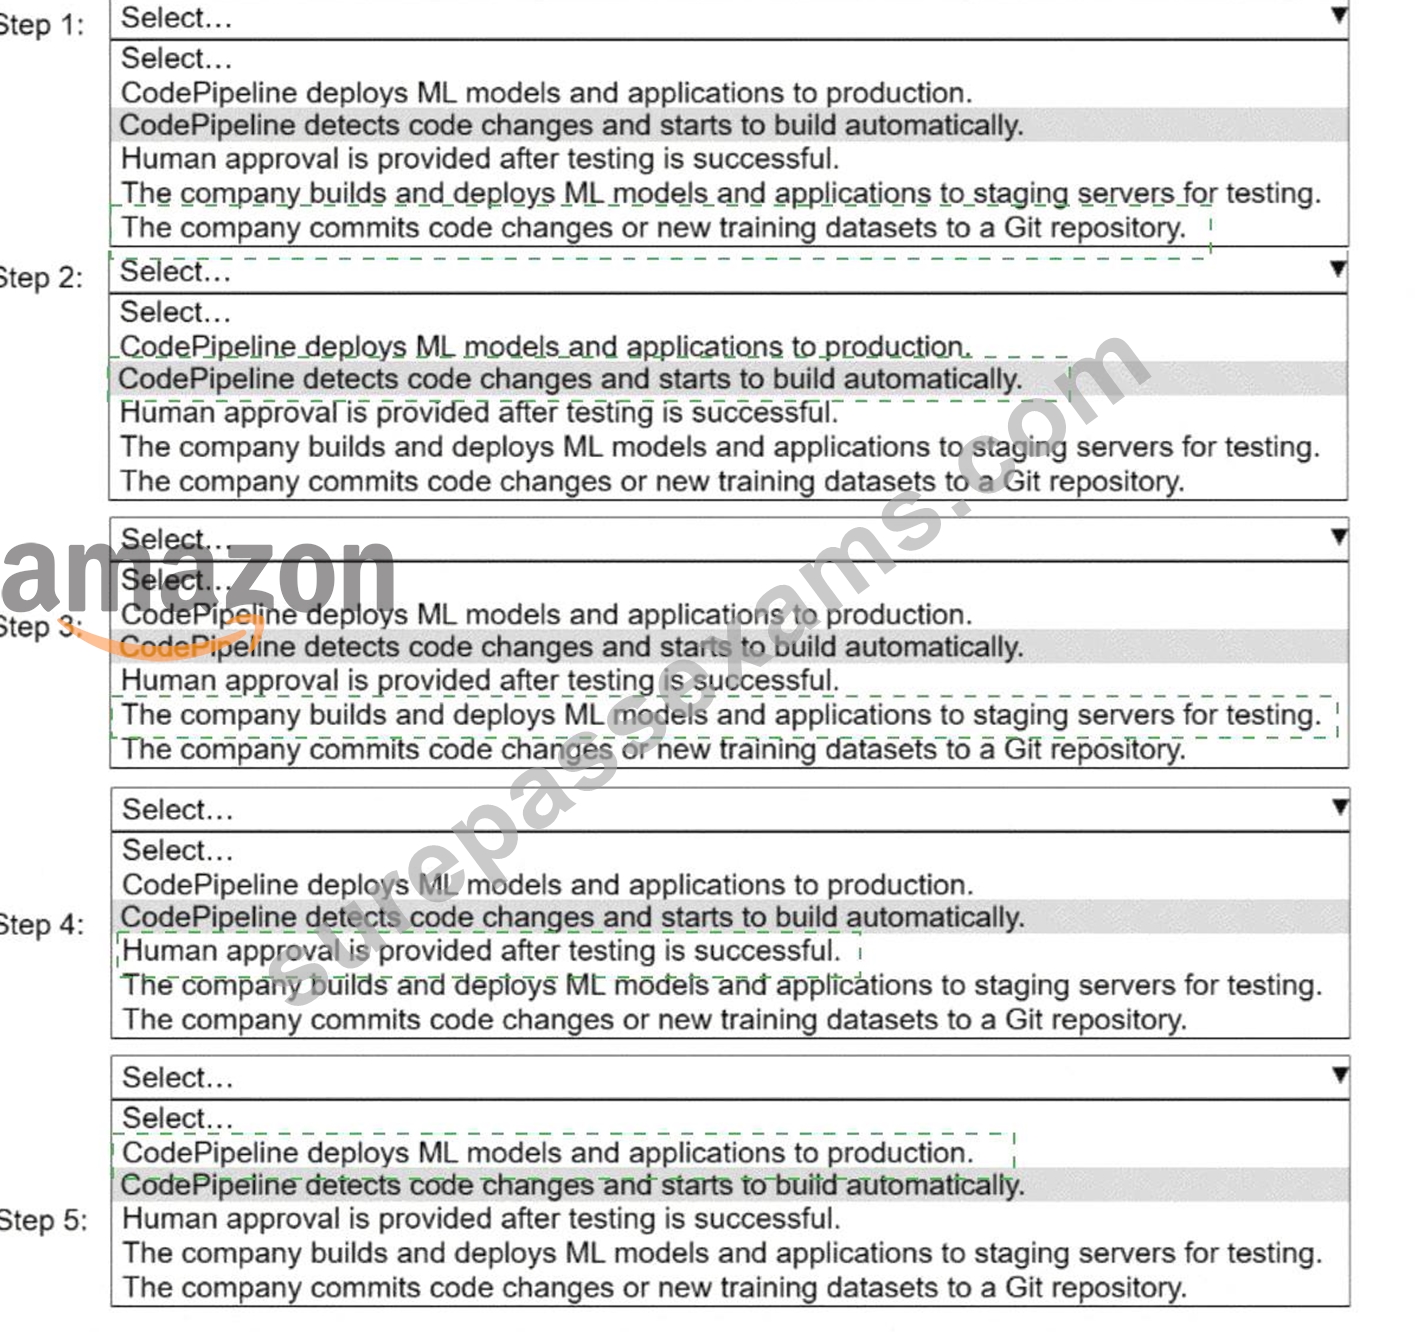
Explanation:
Step 1:
The company commits code changes or new training datasets to a Git repository.
This is the trigger point. A source code or data change initiates the CI/CD pipeline.
Step 2:
CodePipeline detects code changes and starts to build automatically.
CodePipeline monitors the Git repository (for example, AWS CodeCommit, GitHub, or Bitbucket) and automatically triggers the pipeline when changes are detected.
Step 3:
The company builds and deploys ML models and applications to staging servers for testing.
The pipeline runs build, training, and test stages (often using AWS CodeBuild and SageMaker) and deploys artifacts to a staging or test environment for validation.
Step 4:
Human approval is provided after testing is successful.
A manual approval action is a best practice for ML workflows to ensure governance, compliance, and quality checks before production deployment.
Step 5:
CodePipeline deploys ML models and applications to production.
After approval, the pipeline automatically deploys the validated model or application to the production environment.
NEW QUESTION # 190
A customer call center uses Amazon Transcribe to convert hundreds of audio recordings of conversations between customers and support agents to text files. The call center wants to use the text files to train an ML model. To comply with industry regulations, the call center must remove customer names, addresses, and phone numbers from the training text files.
Which solution will meet these requirements with the LEAST development effort?
Answer: A
Explanation:
Option B is correct because AWS Glue provides a built-in Detect PII transform that can detect, mask, or remove personally identifiable information with minimal custom development. AWS documentation says the Detect PII transform can process predefined AWS-managed PII entity types and supports actions such as removing or masking values. The examples in AWS docs explicitly mention sensitive entities such as phone numbers and addresses , which directly match the problem statement.
The question specifically asks for the least development effort . That wording makes AWS Glue Detect PII the strongest answer because it is a native transformation capability rather than a custom code-heavy workflow. AWS also documents fine-grained sensitive data detection features that let you apply actions per entity type, improving usability and reducing the need to build custom parsing and redaction logic yourself.
This is much easier than creating Lambda-based transformation code or custom text-cleaning logic inside another ML preprocessing tool.
The other options are less suitable. Amazon Bedrock Guardrails is not the standard AWS service documented for bulk ETL-style redaction of training text files in this context. S3 Object Lambda would require more custom engineering to inspect and redact each object. SageMaker Data Wrangler custom transformation would also involve extra implementation work compared with using a purpose-built Glue transform. Because the call center already has text output and simply needs regulated fields like names, addresses, and phone numbers removed before training, the AWS-native low-effort solution is AWS Glue Detect PII . Therefore, the best verified answer is B .
NEW QUESTION # 191
A company has a large, unstructured dataset. The dataset includes many duplicate records across several key attributes.
Which solution on AWS will detect duplicates in the dataset with the LEAST code development?
Answer: B
Explanation:
Scenario:The dataset contains duplicate records that need to be detected with minimal code development.
Why FindMatches in AWS Glue?
* Purpose-Built for Deduplication:The FindMatches transform in AWS Glue is specifically designed to identify duplicate records in structured or semi-structured datasets.
* Machine Learning-Based:It uses ML to identify duplicates based on configurable thresholds and provides flexibility for tuning accuracy.
* Low Code Overhead:Minimal development effort is required as Glue provides an interactive console for configuring and running FindMatches transforms.
Steps to Implement:
* Prepare the Data:Upload the unstructured dataset to an S3 bucket and define a schema if needed.
* Create a Glue Job:
* Use the AWS Glue Studio to create a job and select the FindMatches transform.
* Specify key attributes for deduplication.
* Run and Evaluate:Execute the Glue job, and review the results for duplicates.
* Resolve Duplicates:Export results to an S3 bucket or process them as needed.
References:
* AWS Glue FindMatches Documentation
* FindMatches Transform Example
NEW QUESTION # 192
......
This is a mutually beneficial learning platform, that's why our MLA-C01 study materials put the goals that each user has to achieve on top of us, our loyal hope that users will be able to get the test MLA-C01 certification, make them successful, and avoid any type of unnecessary loss and effortless harvesting that belongs to their success. Respect the user's choice, will not impose the user must purchase the MLA-C01 Study Materials. We can meet all the requirements of the user as much as possible, to help users better pass the qualifying exams.
MLA-C01 Exam Demo: https://www.surepassexams.com/MLA-C01-exam-bootcamp.html
2026 Latest SurePassExams MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1l8hKwlwbHb5pM5CrcGaaf48CSiTnQZdz