그리고 Pass4Test Databricks-Generative-AI-Engineer-Associate 시험 문제집의 전체 버전을 클라우드 저장소에서 다운로드할 수 있습니다: https://drive.google.com/open?id=1iW61mYqgsY--EDXYuSdPN6KlXfIJjHiU
자신을 부단히 업그레이드하려면 많은 노력이 필요합니다. IT업종 종사자라면 국제승인 IT인증자격증을 취득하는것이 자신을 업그레이드하는것과 같습니다. Databricks인증 Databricks-Generative-AI-Engineer-Associate시험을 패스하여 원하는 자격증을 취득하려면Pass4Test의Databricks인증 Databricks-Generative-AI-Engineer-Associate덤프를 추천해드립니다. 하루빨리 덤프를 공부하여 자격증 부자가 되세요.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Generative AI Engineer Associate |
| Real Exam Qty: | 45 |
| Available Languages: | Korean, Portuguese (Brazil), English, Japanese |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple Choice, Multiple Select |
| Exam Duration: | 90 minutes |
| Passing Score: | Scaled Score (approx. 70%) |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Exam Price: | $200 USD |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online (Proctored) or Test Center |
| Pre Condition: | None (Recommended: 6+ months hands-on experience) |
| Official Syllabus URL: | https://www.databricks.com/learn/certification/genai-engineer-associate |
>> Databricks-Generative-AI-Engineer-Associate최신 시험대비 공부자료 <<
Pass4Test는Databricks Databricks-Generative-AI-Engineer-Associate시험을 패스할 수 있는 아주 좋은 사이트입니다. Pass4Test은 아주 알맞게 최고의Databricks Databricks-Generative-AI-Engineer-Associate시험문제와 답 내용을 만들어 냅니다. 덤프는 기존의 시험문제와 답과 시험문제분석 등입니다. Pass4Test에서 제공하는Databricks Databricks-Generative-AI-Engineer-Associate시험자료의 문제와 답은 실제시험의 문제와 답과 아주 비슷합니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
질문 # 32
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: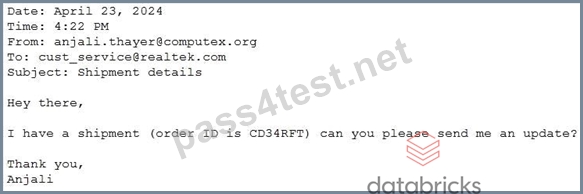
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
정답:A
설명:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
질문 # 33
A Generative AI Engineer has a provisioned throughput model serving endpoint as part of a RAG application and would like to monitor the serving endpoint's incoming requests and outgoing responses. The current approach is to include a micro-service in between the endpoint and the user interface to write logs to a remote server.
Which Databricks feature should they use instead which will perform the same task?
정답:D
설명:
* Problem Context: The goal is to monitor the serving endpoint for incoming requests and outgoing responses in a provisioned throughput model serving endpoint within a Retrieval-Augmented Generation (RAG) application. The current approach involves using a microservice to log requests and responses to a remote server, but the Generative AI Engineer is looking for a more streamlined solution within Databricks.
* Explanation of Options:
Option A: Vector Search: This feature is used to perform similarity searches within vector databases. It doesn't provide functionality for logging or monitoring requests and responses in a serving endpoint, so it's not applicable here.
Option B: Lakeview: Lakeview is not a feature relevant to monitoring or logging request-response cycles for serving endpoints. It might be more related to viewing data in Databricks Lakehouse but doesn't fulfill the specific monitoring requirement.
Option C: DBSQL: Databricks SQL (DBSQL) is used for running SQL queries on data stored in Databricks, primarily for analytics purposes. It doesn't provide the direct functionality needed to monitor requests and responses in real-time for an inference endpoint.
Option D: Inference Tables: This is the correct answer. Inference Tables in Databricks are designed to store the results and metadata of inference runs. This allows the system to log incoming requests and outgoing responses directly within Databricks, making it an ideal choice for monitoring the behavior of a provisioned serving endpoint. Inference Tables can be queried and analyzed, enabling easier monitoring and debugging compared to a custom microservice.
Thus, Inference Tables are the optimal feature for monitoring request and response logs within the Databricks infrastructure for a model serving endpoint.
질문 # 34
A Generative AI Engineer I using the code below to test setting up a vector store: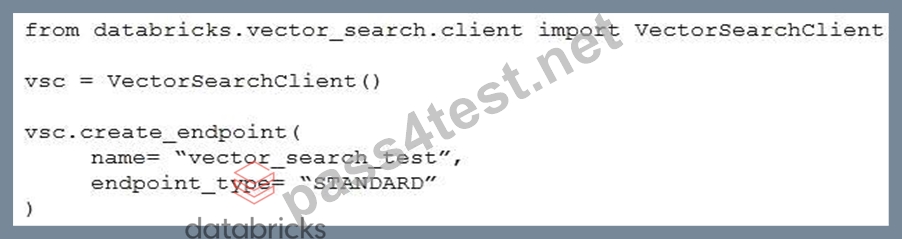
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
정답:C
설명:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
질문 # 35
A Generative AI Engineer is designing an LLM-powered live sports commentary platform. The platform provides real-time updates and LLM-generated analyses for any users who would like to have live summaries, rather than reading a series of potentially outdated news articles.
Which tool below will give the platform access to real-time data for generating game analyses based on the latest game scores?
정답:A
설명:
* Problem Context: The engineer is developing an LLM-powered live sports commentary platform that needs to provide real-time updates and analyses based on the latest game scores. The critical requirement here is the capability to access and integrate real-time data efficiently with the platform for immediate analysis and reporting.
* Explanation of Options:
* Option A: DatabricksIQ: While DatabricksIQ offers integration and data processing capabilities, it is more aligned with data analytics rather than real-time feature serving, which is crucial for immediate updates necessary in a live sports commentary context.
* Option B: Foundation Model APIs: These APIs facilitate interactions with pre-trained models and could be part of the solution, but on their own, they do not provide mechanisms to access real- time game scores.
* Option C: Feature Serving: This is the correct answer as feature serving specifically refers to the real-time provision of data (features) to models for prediction. This would be essential for an LLM that generates analyses based on live game data, ensuring that the commentary is current and based on the latest events in the sport.
* Option D: AutoML: This tool automates the process of applying machine learning models to real-world problems, but it does not directly provide real-time data access, which is a critical requirement for the platform.
Thus,Option C(Feature Serving) is the most suitable tool for the platform as it directly supports the real-time data needs of an LLM-powered sports commentary system, ensuring that the analyses and updates are based on the latest available information.
질문 # 36
A Generative Al Engineer is tasked with developing an application that is based on an open source large language model (LLM). They need a foundation LLM with a large context window.
Which model fits this need?
정답:B
설명:
* Problem Context: The engineer needs an open-source LLM with a large context window to develop an application.
* Explanation of Options:
* Option A: DistilBERT: While an efficient and smaller version of BERT, DistilBERT does not provide a particularly large context window.
* Option B: MPT-30B: This model, while large, is not specified as being particularly notable for its context window capabilities.
* Option C: Llama2-70B: Known for its large model size and extensive capabilities, including a large context window. It is also available as an open-source model, making it ideal for applications requiring extensive contextual understanding.
* Option D: DBRX: This is not a recognized standard model in the context of large language models with extensive context windows.
Thus,Option C(Llama2-70B) is the best fit as it meets the criteria of having a large context window and being available for open-source use, suitable for developing robust language understanding applications.
질문 # 37
......
Databricks-Generative-AI-Engineer-Associate시험합격: https://www.pass4test.net/Databricks-Generative-AI-Engineer-Associate.html
참고: Pass4Test에서 Google Drive로 공유하는 무료 2026 Databricks Databricks-Generative-AI-Engineer-Associate 시험 문제집이 있습니다: https://drive.google.com/open?id=1iW61mYqgsY--EDXYuSdPN6KlXfIJjHiU