2026年MogiExamの最新MLA-C01 PDFダンプおよびMLA-C01試験エンジンの無料共有:https://drive.google.com/open?id=1HqIPToD66ui4dVvfNjVB37SMG113WSxU
当社MogiExamの専門家は、MLA-C01テストクイズが毎日更新されるかどうかを確認しています。 MLA-C01試験トレントは、更新システムによってデジタル化された世界に対応できることを保証できます。私たちは、お客様が教材に関する最新情報を入手できるように最善を尽くします。弊社のMLA-C01試験トレントを購入する意思がある場合は、更新システムを楽しむ権利があることは間違いありません。 MLA-C01試験のダンプが更新されると、MLA-C01テストクイズの最新情報がすぐに届きます。すぐにMLA-C01試験準備をすぐに購入しましょう!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: ML Model Development | 26% | - Model selection and training
|
| Topic 2: Deployment and Orchestration of ML Workflows | 22% | - ML pipeline orchestration
|
| Topic 3: Data Preparation for Machine Learning (ML) | 28% | - Data preprocessing and transformation
|
| Topic 4: ML Solution Monitoring, Maintenance, and Security | 24% | - Security and governance
|
当社Amazonのソフトウェアバージョンには、実際のMLA-C01試験環境をシミュレートするという利点があります。 多くの受験者は、練習をするときにパフォーマンスが正しくなりすぎて緊張するため、MogiExam実際のMLA-C01試験に合格できません。 MLA-C01練習資料のこのソフトウェアバージョンは、心理的な恐怖を克服するのに役立ちます。 その上、練習を終えると得点が表示されるので、数回後には間違いなくどんどん良くなります。 MLA-C01試験の受験を完了したため、AWS Certified Machine Learning Engineer - Associate試験に合格する必要があります。
質問 # 195
A company uses a training job on Amazon SageMaker Al to train a neural network. The job first trains a model and then evaluates the model's performance ag test dataset. The company uses the results from the evaluation phase to decide if the trained model will go to production.
The training phase takes too long. The company needs solutions that can shorten training time without decreasing the model's final performance.
Select the correct solutions from the following list to meet the requirements for each description. Select each solution one time or not at all. (Select THREE.)
. Change the epoch count.
. Choose an Amazon EC2 Spot Fleet.
Change the batch size.
. Use early stopping on the training job.
Use the SageMaker Al distributed data parallelism (SMDDP) library.
. Stop the training job.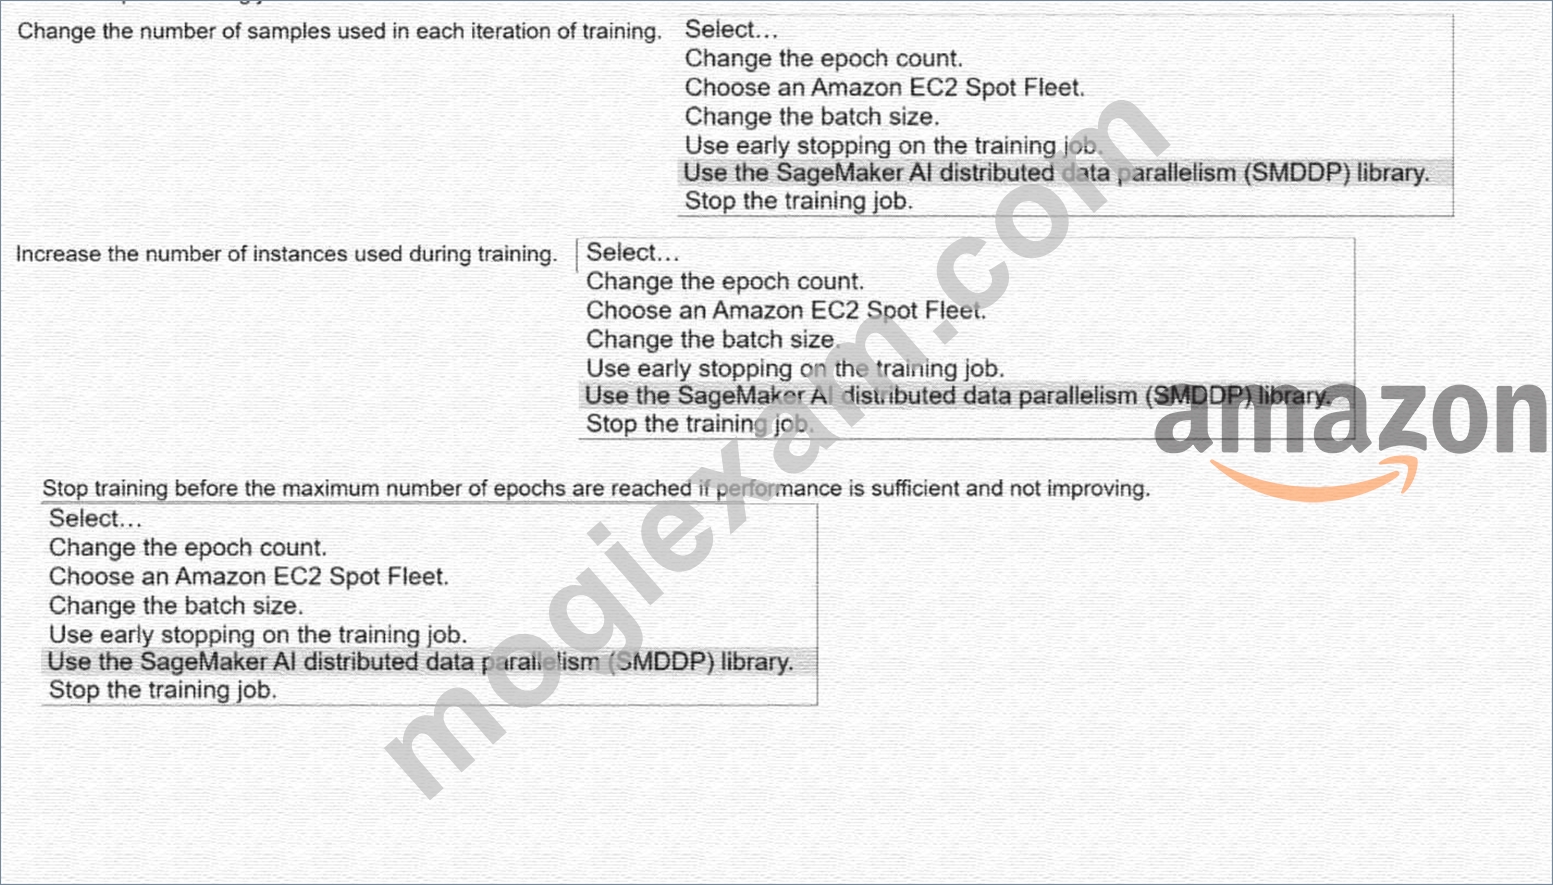
正解:
解説: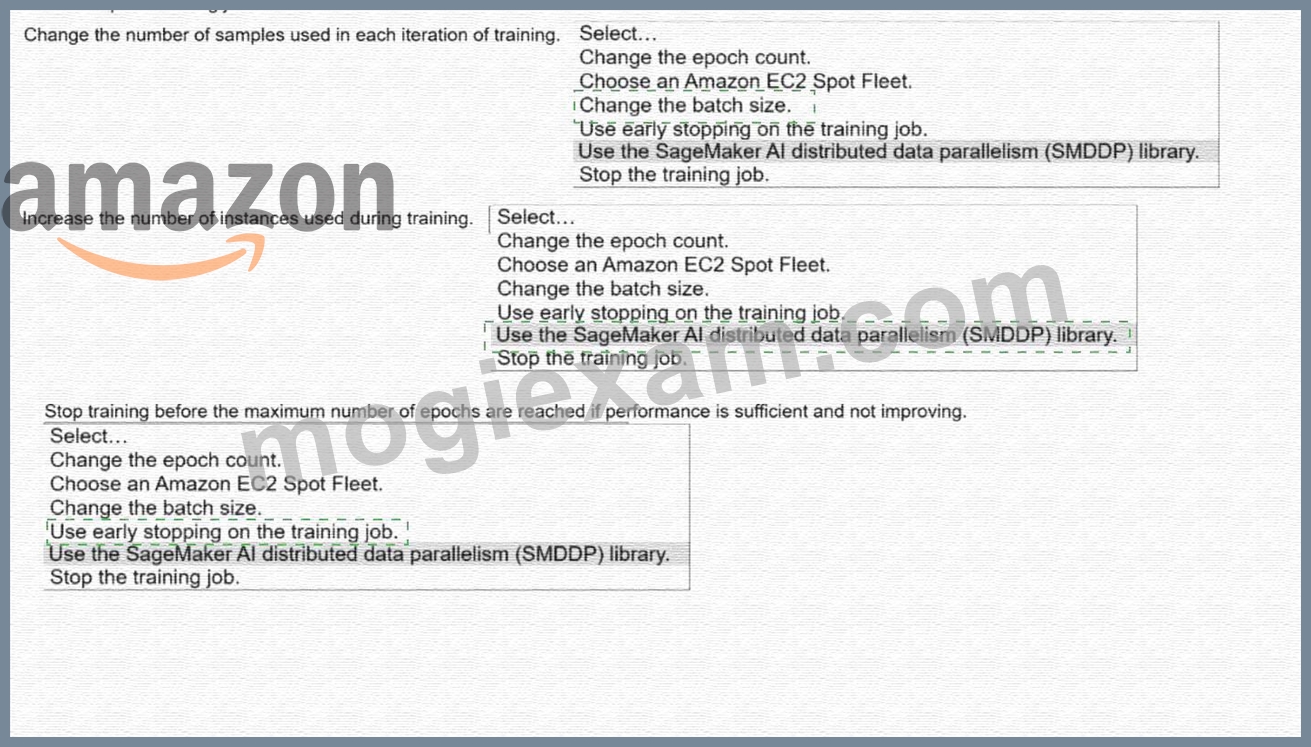
Explanation:
Change the number of samples used in each iteration of training
Correct selection:
Change the batch size
Why:
Increasing the batch size reduces the number of iterations per epoch, which can significantly shorten training time while maintaining model quality when tuned appropriately. AWS explicitly recommends batch size tuning as a primary performance optimization.
Increase the number of instances used during training
Correct selection:
Use the SageMaker AI distributed data parallelism (SMDDP) library
Why:
SMDDP is designed to efficiently distribute training data across multiple GPU instances with optimized gradient synchronization. This accelerates training without affecting model convergence or accuracy, unlike naive scaling approaches.
Stop training before the maximum number of epochs are reached if performance is sufficient and not improving Correct selection:
Use early stopping on the training job
Why:
Early stopping automatically terminates training when validation metrics stop improving. AWS recommends this to reduce wasted compute time while preserving optimal model performance.
質問 # 196
A company has developed a new ML model. The company requires online model validation on 10% of the traffic before the company fully releases the model in production. The company uses an Amazon SageMaker endpoint behind an Application Load Balancer (ALB) to serve the model.
Which solution will set up the required online validation with the LEAST operational overhead?
正解:B
解説:
Scenario:The company wants to perform online validation of a new ML model on 10% of the traffic before fully deploying the model in production. The setup must have minimal operational overhead.
Why Use SageMaker Production Variants?
* Built-In Traffic Splitting:Amazon SageMaker endpoints support production variants, allowing multiple models to run on a single endpoint. You can direct a percentage of incoming traffic to each variant by adjusting the variant weights.
* Ease of Management:Using production variants eliminates the need for additional infrastructure like separate endpoints or custom ALB configurations.
* Monitoring with CloudWatch:SageMaker automatically integrates with CloudWatch, enabling real- time monitoring of model performance and invocation metrics.
Steps to Implement:
* Deploy the New Model as a Production Variant:
* Update the existing SageMaker endpoint to include the new model as a production variant. This can be done via the SageMaker console, CLI, or SDK.
Example SDK Code:
import boto3
sm_client = boto3.client('sagemaker')
response = sm_client.update_endpoint_weights_and_capacities(
EndpointName='existing-endpoint-name',
DesiredWeightsAndCapacities=[
{'VariantName': 'current-model', 'DesiredWeight': 0.9},
{'VariantName': 'new-model', 'DesiredWeight': 0.1}
]
)
* Set the Variant Weight:
* Assign a weight of 0.1 to the new model and 0.9 to the existing model. This ensures 10% of traffic goes to the new model while the remaining 90% continues to use the current model.
* Monitor the Performance:
* Use Amazon CloudWatch metrics, such as InvocationCount and ModelLatency, to monitor the traffic and performance of each variant.
* Validate the Results:
* Analyze the performance of the new model based on metrics like accuracy, latency, and failure rates.
Why Not the Other Options?
* Option B:Setting the weight to 1 directs all traffic to the new model, which does not meet the requirement of splitting traffic for validation.
* Option C:Creating a new endpoint introduces additional operational overhead for traffic routing and monitoring, which is unnecessary given SageMaker's built-in production variant capability.
* Option D:Configuring the ALB to route traffic requires manual setup and lacks SageMaker's seamless variant monitoring and traffic splitting features.
Conclusion:Using production variants with a weight of 0.1 for the new model on the existing SageMaker endpoint provides the required traffic split for online validation with minimal operational overhead.
References:
* Amazon SageMaker Endpoints
* SageMaker Production Variants
* Monitoring SageMaker Endpoints with CloudWatch
質問 # 197
A company wants to deploy an Amazon SageMaker AI model that can queue requests. The model needs to handle payloads of up to 1 GB that take up to 1 hour to process. The model must return an inference for each request. The model also must scale down when no requests are available to process.
Which inference option will meet these requirements?
正解:C
解説:
Amazon SageMaker Asynchronous Inference is specifically designed for long-running inference requests and large payloads. It supports payload sizes up to 1 GB and processing times of up to 1 hour, while automatically queuing requests.
Asynchronous inference stores results in Amazon S3 and allows clients to retrieve inference outputs after processing completes. It also supports auto scaling down to zero when there are no incoming requests, reducing cost.
Batch transform is intended for offline, bulk inference and does not return per-request results in an asynchronous request-response pattern. Serverless and real-time inference have strict payload size and timeout limits that do not support 1-hour processing.
Therefore, asynchronous inference is the only SageMaker inference option that meets all stated requirements.
質問 # 198
An ML engineer is developing a fraud detection model by using the Amazon SageMaker XGBoost algorithm. The model classifies transactions as either fraudulent or legitimate.
During testing, the model excels at identifying fraud in the training dataset. However, the model is inefficient at identifying fraud in new and unseen transactions.
What should the ML engineer do to improve the fraud detection for new transactions?
正解:C
質問 # 199
An ML engineer is setting up an Amazon SageMaker AI pipeline for an ML model. The pipeline must automatically initiate a retraining job if any data drift is detected.
How should the ML engineer set up the pipeline to meet this requirement?
正解:A
解説:
AWS recommends Amazon SageMaker Model Monitor as the native service for detecting data drift, model drift, and bias drift in deployed ML models. Model Monitor continuously compares incoming inference data against a baseline dataset captured during training.
When Model Monitor detects drift beyond configured thresholds, it can emit Amazon CloudWatch events.
These events can trigger an AWS Lambda function, which is a common AWS-documented pattern for orchestrating automated workflows such as model retraining.
This Lambda function can then initiate a SageMaker Pipeline execution, starting a retraining job with updated data. This architecture aligns with AWS best practices for building automated, event-driven ML pipelines.
Option A is incorrect because AWS Glue is designed for data cataloging and ETL, not for ML-specific drift detection. Option B is unnecessary and overly complex for this use case. Option D is incorrect because Amazon QuickSight anomaly detection is intended for business intelligence analytics, not ML model monitoring.
AWS documentation explicitly positions SageMaker Model Monitor + Lambda automation as the recommended approach for continuous ML monitoring and retraining.
Therefore, Option C is the correct and AWS-verified answer.
質問 # 200
......
当社AmazonのMLA-C01ガイド急流は、過去の試験論文と業界での人気の傾向に基づいて、厳密な分析と要約を行っており、改訂および更新されています。 MLA-C01試験問題により、洗練された概念が簡素化されました。このソフトウェアは、さまざまな自己学習および自己評価機能を強化して、学習結果を確認します。 MLA-C01テストトレントのソフトウェアは、統計レポート機能を提供し、学生が脆弱なリンクを見つけて対処するのに役立ちます。 MLA-C01試験問題のこのバージョンを使用すると、試験に簡単に合格することができます。
MLA-C01模擬試験問題集: https://www.mogiexam.com/MLA-C01-exam.html
P.S.MogiExamがGoogle Driveで共有している無料の2026 Amazon MLA-C01ダンプ:https://drive.google.com/open?id=1HqIPToD66ui4dVvfNjVB37SMG113WSxU