P.S.JpexamがGoogle Driveで共有している無料の2026 Microsoft DP-700ダンプ:https://drive.google.com/open?id=1QXw3QJnTpSh4vagZIVQS97J93mPgVNL6
高い雇用圧力により、ますます多くの人々が雇用の緊張を和らげ、より良い仕事を得たいと考えています。 彼らが問題を解決する最善の方法は、JpexamのDP-700認定を取得することです。 認定資格は彼らの労働能力の主要なシンボルであるため、DP-700認定資格を所有できれば、仕事を探しているときに競争上の優位性を獲得できます。 短時間でDP-700試験問題を取得することが非常に重要であることを認識する人が増えています。 また、DP-700試験問題は、夢のような認定を取得するのに役立ちます。
| Section | Weight | Objectives |
|---|---|---|
| Implement and manage an analytics solution | 30–35% | - Manage data lifecycle and governance
|
| Ingest and transform data | 30–35% | - Ingest data
|
| Monitor and optimize an analytics solution | 30–35% | - Troubleshoot issues
|
Jpexamは、すべての受験者にDP-700試験の十分な知識を持つ専門家によってコンパイルされたDP-700テストトレントを提供し、DP-700学習教材のコンパイルに非常に専門的です。それだけでなく、テストトレントDP-700の最新情報を保持するために、チームは毎日更新を確認します。最新バージョンを入手したら、できるだけ早くメールボックスに送信します。試験に最適なDP-700学習教材を提供するのに最適なプラットフォームである必要があります。
質問 # 88
You have a Fabric workspace that contains a warehouse named Warehouse1. Warehouse1 contains a table named Customer. Customer contains the following data.

正解:
解説:
Explanation:
質問 # 89
You need to create the product dimension.
How should you complete the Apache Spark SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
正解:
解説:
Explanation:
A screenshot of a computer Description automatically generated
Join between Products and ProductSubCategories:
Use an INNER JOIN.
The goal is to include only products that are assigned to a subcategory. An INNER JOIN ensures that only matching records (i.e., products with a valid subcategory) are included.
Join between ProductSubCategories and ProductCategories:
Use an INNER JOIN.
Similar to the above logic, we want to include only subcategories assigned to a valid product category. An INNER JOIN ensures this condition is met.
WHERE Clause
Condition: IsActive = 1
Only active products (where IsActive equals 1) should be included in the gold layer. This filters out inactive products.
質問 # 90
You have a Fabric workspace named WS1 that contains several scheduled data pipelines. WS1 has workspace monitoring enabled, and the monitoring eventhouse contains a table named ItemJobEventLogs.
Users report that some downstream reports are missing newly ingested data.
You need to identify failed pipeline runs from the last nine minutes and return only the columns needed for troubleshooting.
How should you complete the KQL query?
正解:
解説:
Explanation:
First selection: JobType == ' Pipeline '
Second selection: SecondsAgo < = 540
Completed KQL query:
ItemJobEventLogs
| where JobType == ' Pipeline ' and JobStatus == ' Failed '
| extend SecondsAgo = datetime_diff( ' second ' , now(), ingestion_time())
| where SecondsAgo < = 540
| order by Timestamp desc
| project Timestamp, ItemName, WorkspaceName, JobStartTime, JobEndTime, JobStatus The correct selections are JobType == ' Pipeline ' and SecondsAgo < = 540 . Microsoft Fabric workspace monitoring writes item-level execution information to the ItemJobEventLogs table in the monitoring Eventhouse. Microsoft provides this specific KQL pattern for detecting recent pipeline failures , using JobType == ' Pipeline ' together with JobStatus == ' Failed ' .
The query then calculates:
datetime_diff( ' second ' , now(), ingestion_time())
This produces the approximate number of seconds elapsed since each monitoring record was ingested.
Because nine minutes = 540 seconds , the predicate SecondsAgo < = 540 retains records ingested during the preceding nine-minute window. SecondsAgo > = 540 would do the opposite by retaining records at least nine minutes old.
JobEndTime > = ago(9m) is not the correct selection because the query explicitly derives ingestion recency through ingestion_time(). Microsoft's documented workspace-monitoring example uses the same SecondsAgo < = 540 pattern.
Finally, project limits the result to the operational fields required for troubleshooting: timestamp, pipeline name, workspace, start/end times, and failure status.
Study Guide reference: Monitor and optimize an analytics solution # workspace monitoring # Eventhouse monitoring logs # KQL analysis of pipeline execution and failures.
質問 # 91
You have a Fabric workspace that contains an eventhouse named Eventhouse1.
In Eventhouse1, you plan to create a table named DeviceStreamData in a KQL database. The table will contain data based on the following sample.
正解:
解説:
Explanation:
質問 # 92
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric eventstream that loads data into a table named Bike_Location in a KQL database. The table contains the following columns:
BikepointID
Street
Neighbourhood
No_Bikes
No_Empty_Docks
Timestamp
You need to apply transformation and filter logic to prepare the data for consumption. The solution must return data for a neighbourhood named Sands End when No_Bikes is at least 15. The results must be ordered by No_Bikes in ascending order.
Solution: You use the following code segment:
Does this meet the goal?
正解:B
解説:
This code does not meet the goal because this is an SQL-like query and cannot be executed in KQL, which is required for the database.
Correct code should look like: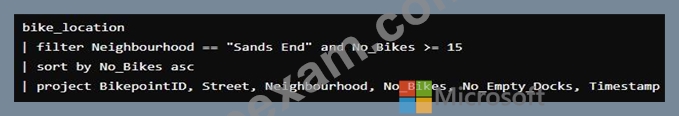
質問 # 93
......
お客様にDP-700試験ダンプをよりよく理解していただくために、当社はお客様に試用版を提供します。また、トレイルバージョンは無料です。トレイルバージョンはお客様にデモを提供します。つまり、お客様はDP-700試験トレントのデモを無料で学習できます。 DP-700テストクイズを使用する場合、当社の製品は優れた品質であり、他の製品と比較することはできないことを十分に知っていると思われます。 躊躇しないで、DP-700テストクイズを購入してください!
DP-700最新試験情報: https://www.jpexam.com/DP-700_exam.html
ちなみに、Jpexam DP-700の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1QXw3QJnTpSh4vagZIVQS97J93mPgVNL6