2026 Latest Real4dumps Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1dHxarYWx5QDn4IY7eCQHp46kIfvj6mbd
Do you want to pass Professional-Machine-Learning-Engineer exam certification at your first attempt to attend Professional-Machine-Learning-Engineer test? With Real4dumps, we will meet all of your needs, and make you pass Professional-Machine-Learning-Engineer certification exam at one time in a limited time. Because Real4dumps have Professional-Machine-Learning-Engineer Exam Certification training materials, which are summarized by experienced IT experts with many years' practice, and is a combination of Professional-Machine-Learning-Engineer exam dumps and answers, you can't regret to choose Real4dumps.
| Section | Objectives |
|---|---|
| Serving and scaling models | - Hardware accelerators (GPU/TPU) in serving - Online prediction (Vertex AI Prediction) - Batch prediction - Model optimization (Quantization, Distillation) |
| Automating and orchestrating ML pipelines | - Vertex AI Pipelines (Kubeflow Pipelines) - CI/CD for ML systems - Triggering and scheduling pipelines |
| Architecting low-code ML solutions | - AutoML capabilities and implementation - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - Implementing BigQuery ML for basic models |
| Monitoring ML solutions | - Model retraining strategies - Logging and alerting (Cloud Monitoring) - Performance monitoring and drift detection |
| Scaling prototypes into ML models | - Training at scale (Distributed training, TPUs) - Hyperparameter tuning - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Collaborating within and across teams to manage data and models | - Version control and reproducibility (e.g., DVC, MLOps) - Data management and governance - Collaboration between Data Scientists, Data Engineers, and ML Engineers |
>> Valid Professional-Machine-Learning-Engineer Exam Simulator <<
Maybe on other web sites or books, you can also see the related training materials. But as long as you compare Real4dumps's product with theirs, you will find that our product has a broader coverage of the certification exam's outline. You can free download part of exam practice questions and answers about Google certification Professional-Machine-Learning-Engineer exam from Real4dumps website as a try to detect the quality of our products. Why Real4dumps can provide the comprehensive and high-quality information uniquely? Because we have a professional team of IT experts. They continue to use their IT knowledge and rich experience to study the previous years exams of Google Professional-Machine-Learning-Engineer and have developed practice questions and answers about Google Professional-Machine-Learning-Engineer exam certification exam. So Real4dumps's newest exam practice questions and answers about Google certification Professional-Machine-Learning-Engineer exam are so popular among the candidates participating in the Google certification Professional-Machine-Learning-Engineer exam.
NEW QUESTION # 164
You work for a retail company. You have a managed tabular dataset in Vertex Al that contains sales data from three different stores. The dataset includes several features such as store name and sale timestamp. You want to use the data to train a model that makes sales predictions for a new store that will open soon You need to split the data between the training, validation, and test sets What approach should you use to split the data?
Answer: B
Explanation:
The best option for splitting the data between the training, validation, and test sets, using a managed tabular dataset in Vertex AI that contains sales data from three different stores, is to use Vertex AI default data split.
This option allows you to leverage the power and simplicity of Vertex AI to automatically and randomly split your data into the three sets by percentage. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can support various types of models, such as linear regression, logistic regression, k-means clustering, matrix factorization, and deep neural networks. Vertex AI can also provide various tools and services for data analysis, model development, model deployment, model monitoring, and model governance. A default data split is a data split method that is provided by Vertex AI, and does not require any user input or configuration. A default data split can help you split your data into the training, validation, and test sets by using a random sampling method, and assign a fixed percentage of the data to each set. A default data split can help you simplify the data split process, and works well in most cases.
A training set is a subset of the data that is used to train the model, and adjust the model parameters. A training set can help you learn the relationship between the input features and the target variable, and optimize the model performance. A validation set is a subset of the data that is used to validate the model, and tune the model hyperparameters. A validation set can help you evaluate the model performance on unseen data, and avoid overfitting or underfitting. A test set is a subset of the datathat is used to test the model, and provide the final evaluation metrics. A test set can help you assess the model performance on new data, and measure the generalization ability of the model. By using Vertex AI default data split, you can split your data into the training, validation, and test sets by using a random sampling method, and assign the following percentages of the data to each set1: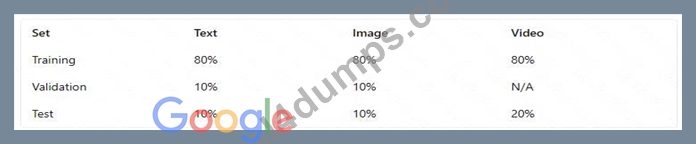
The other options are not as good as option B, for the following reasons:
* Option A: Using Vertex AI manual split, using the store name feature to assign one store for each set would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. A manual split is a data split method that allows you to control how your data is split into sets, by using the ml_use label or the data filter expression. A manual split can help you customize the data split logic, and handle complex or non-standard data formats. A store name feature is a feature that indicates the name of the store where the sales data was collected. A store name feature can help you identify the source of the data, and group the data by store. However, using Vertex AI manual split, using the store name feature to assign one store for each set would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. You would need to write code, create and configure the ml_use label or the data filter expression, and assign one store for each set. Moreover, this option would not ensure that the data in each set has the same distribution and characteristics as the data in the whole dataset, which could prevent you from learning the general pattern of the data, and cause bias or variance in the model2.
* Option C: Using Vertex AI chronological split and specifying the sales timestamp feature as the time variable would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. A chronological split is a data split method that allows you to split your data into sets based on the order of the data. A chronological split can help you preserve the temporal dependency and sequence of the data, and avoid data leakage. A sales timestamp feature is a feature that indicates the date and time when the sales data was collected. A sales timestamp feature can help you track the changes and trends of the data over time, and capture the seasonality and cyclicality of the data. However, using Vertex AI chronological split and specifying the sales timestamp feature as the time variable would not allow you to split your data into representative and balanced sets, and could cause errors or poor performance. You would need to write code, create and configure the time variable, and split the data by the order of the time variable. Moreover, this option would not ensure that the data in each set has the same distribution and characteristics as the data in the whole dataset, which could prevent you from learning the general pattern of the data, and cause bias or variance in the model3.
* Option D: Using Vertex AI random split, assigning 70% of the rows to the training set, 10% to the validation set, and 20% to the test set would not allow you to use the default data splitmethod that is provided by Vertex AI, and could increase the complexity and cost of the data split process. A random split is a data split method that allows you to split your data into sets by using a random sampling method, and assign a custom percentage of the data to each set. A random split can help you split your data into representative and balanced sets, and avoid data leakage. However, using Vertex AI random split, assigning 70% of the rows to the training set, 10% to the validation set, and 20% to the test set would not allow you to use the default data split method that is provided by Vertex AI, and could increase the complexity and cost of the data split process. You would need to write code, create and configure the random split method, and assign the custom percentages to each set. Moreover, this option would not use the default data split method that is provided by Vertex AI, which can simplify the data split process, and works well in most cases1.
References:
* About data splits for AutoML models | Vertex AI | Google Cloud
* Manual split for unstructured data
* Mathematical split
NEW QUESTION # 165
You are an ML engineer at a manufacturing company You are creating a classification model for a predictive maintenance use case You need to predict whether a crucial machine will fail in the next three days so that the repair crew has enough time to fix the machine before it breaks. Regular maintenance of the machine is relatively inexpensive, but a failure would be very costly You have trained several binary classifiers to predict whether the machine will fail. where a prediction of 1 means that the ML model predicts a failure.
You are now evaluating each model on an evaluation dataset. You want to choose a model that prioritizes detection while ensuring that more than 50% of the maintenance jobs triggered by your model address an imminent machine failure. Which model should you choose?
Answer: B
Explanation:
In predictive maintenance, the goal is to identify which machines are likely to fail soon, so that the repair crew can fix them before they break. In this context, it is important to prioritize detection, while also ensuring that more than 50% of the maintenance jobs triggered by your model address an imminent machine failure.
Recall is a metric that measures the proportion of actual positive observations that are correctly predicted as such by the model. In this case, recall is a good metric to use because it measures how well the model is able to identify the machines that are likely to fail soon.
Precision is a metric that measures the proportion of positive predictions that are actually true. In this case, precision is also important because it measures how many of the machines that the model predicts will fail soon, actually do fail soon.
By combining these two metrics, you can ensure that your model is able to identify the machines that are likely to fail soon with a high degree of accuracy. In this case, the model with the highest recall where precision is greater than 0.5 will be the best model, as it will have a high ability to identify the machines that are likely to fail soon and also it will have a high degree of accuracy.
Reference:
Recall and Precision
Predictive Maintenance
Metrics for classification
NEW QUESTION # 166
You are a lead ML engineer at a retail company. You want to track and manage ML metadata in a centralized way so that your team can have reproducible experiments by generating artifacts.
Which management solution should you recommend to your team?
Answer: B
Explanation:
https://cloud.google.com/vertex-ai/docs/ml-metadata/tracking
NEW QUESTION # 167
You need to develop a custom TensorRow model that will be used for online predictions. The training data is stored in BigQuery. You need to apply instance-level data transformations to the data for model training and serving. You want to use the same preprocessing routine during model training and serving. How should you configure the preprocessing routine?
Answer: D
NEW QUESTION # 168
Your team has been tasked with creating an ML solution in Google Cloud to classify support requests for one of your platforms. You analyzed the requirements and decided to use TensorFlow to build the classifier so that you have full control of the model ' s code, serving, and deployment. You will use Kubeflow pipelines for the ML platform. To save time, you want to build on existing resources and use managed services instead of building a completely new model. How should you build the classifier?
Answer: B
Explanation:
Transfer learning is a technique that leverages the knowledge and weights of a pre-trained model and adapts them to a new task or domain 1 . Transfer learning can save time and resources by avoiding training a model from scratch, and can also improve the performance and generalization of the model by using a larger and more diverse dataset 2 . AI Platform provides several established text classification models that can be used for transfer learning, such as BERT, ALBERT, or XLNet 3 . These models are based on state-of-the-art natural language p rocessing techniques and can handle various text classification tasks, such as sentiment analysis, topic classification, or spam detection 4 . By using one of these models on AI Platform, you can customize the model's code, serving, and deployment, and use Kubeflow pipelines for the ML platform.
Therefore, using an established text classification model on AI Platform to perform transfer learning is the best option for this use case.
References:
Transfer Learning - Machine Learning's Next Frontier
A Comprehensive Hands-on Guide to Transfer Learning with Real-World Applications in Deep Learning Text classification models Text Classification with Pre-trained Models in TensorFlow
NEW QUESTION # 169
......
In order to ensure the quality of our Professional-Machine-Learning-Engineer actual exam, we have made a lot of efforts. Our company spent a great deal of money on hiring hundreds of experts and they formed a team to write the work. The qualifications of these experts are very high. They have rich knowledge and rich experience on the Professional-Machine-Learning-Engineer Study Guide. So they know every detail about the Professional-Machine-Learning-Engineer exam questions and can make it better. With our Professional-Machine-Learning-Engineer learning guide, you will be bound to pass the exam.
New Exam Professional-Machine-Learning-Engineer Braindumps: https://www.real4dumps.com/Professional-Machine-Learning-Engineer_examcollection.html
What's more, part of that Real4dumps Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=1dHxarYWx5QDn4IY7eCQHp46kIfvj6mbd