Snowflake DAA-C01 Reliable Test Camp - Reliable DAA-C01 Study Guide
BTW, DOWNLOAD part of BraindumpStudy DAA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=12y8SCY5LfOeN6wA_naR5_X7x1jIfHSlb
After cracking the SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) exam you will receive the credential badge. It will pave your way toward well-paying jobs or promotions in any reputed tech company. At BraindumpStudy have customizable Snowflake DAA-C01 practice exams for the students to review and improve their preparation. The Snowflake DAA-C01 Practice Test material product of BraindumpStudy are created by experts with the dedication to help customers crack the Snowflake DAA-C01 exam on the first attempt.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Ingestion and Data Preparation | 15%-20% | - Prepare data and load into Snowflake
- 1. Load data from external/internal stages into a table
- 2. Load files using Snowsight
- Perform data discovery to identify what is needed from available datasets
- 1. Query tables to assess data elements and statistics maintained by Snowflake
- 2. Evaluate required transformations (table joins, set operations, ASOF JOINS)
- 3. Use commands to read metadata or alter context (DESCRIBE, SHOW, USE)
- 4. Identify elements required for business goals using BI reports or SQL analysis
- 5. Determine the level of data granularity required
- Use best practice considerations relating to data integrity structures
- 1. Perform table joins between parent/child tables
- 2. Define primary keys for tables
- 3. Implement constraints
- Enrich data by identifying and accessing relevant data from the Snowflake Marketplace
- 1. Use Secure Data Sharing (Marketplace, Internal Marketplace, Private Listings, Listings)
- 2. Find external data sets that correlate with available data
- 3. Create tables and views
- Implement data processing solutions
- 1. Use logging and monitoring solutions (auditing, data lineage)
- 2. Automate and implement data pipelines (scheduling)
- 3. Cleanse, conform, and enrich data
- 4. Respond to processing failures
- Use a collection system to retrieve data
- 1. Retrieve data from structured sources (CSV)
- 2. Retrieve data from unstructured sources
- 3. Retrieve data from semi-structured sources (Parquet, Avro, ORC, JSON, XML)
- 4. Synthetic Data Generation
|
| Topic 2: Data Transformation and Data Modeling | 22%-30% | - Transform data using SQL
- 1. Common Table Expressions (CTEs)
- 2. Window functions
- 3. QUALIFY clauses
- 4. PIVOT/UNPIVOT operations
- Design data models
- 1. Data vault models
- 2. Snowflake schema design
- 3. Star schema design
|
| Topic 3: Data Presentation and Data Visualization | 28%-29% | - Create dashboards
- 1. Snowsight dashboards
- 2. Present analytical results
- Integrate with BI tools
- 1. Other partner visualization tools
- 2. Power BI integration
- 3. Tableau integration
|
| Topic 4: Data Analysis | 30%-32% | - Perform advanced analytics using SQL
- 1. Aggregate functions
- 2. Snowflake-specific analytical features
- 3. Time-series analysis
|
>> Snowflake DAA-C01 Reliable Test Camp <<
Reliable DAA-C01 Study Guide | DAA-C01 Certification Exam Dumps
Can you imagine that ust a mobile phone can let you do DAA-C01 exam questions at any time? With our DAA-C01 learning guide, you will find studying for the exam can be so easy and intersting. If you are a student, you can lose a heavy bag with DAA-C01 Study Materials, and you can save more time for making friends, traveling, and broadening your horizons. Please believe that DAA-C01 guide materials will be the best booster for you to learn.
Snowflake SnowPro Advanced: Data Analyst Certification Exam Sample Questions (Q19-Q24):
NEW QUESTION # 19
What functions should a Data Analyst use to run descriptive analytics on a data set? (Select TWO).
- A. ROW_NUMBER
- B. AVG
- C. APPROX_COUNT_DISTINCT
- D. REGR_INTERCEPT
- E. REGR_SLOPE
Answer: B,C
Explanation:
Descriptive analytics is the process of using historical data to understand "what happened." This typically involves summarizing large datasets into interpretable chunks using central tendency, dispersion, and frequency measures.
AVG (Average) is a cornerstone of descriptive statistics. It provides the arithmetic mean of a numeric column, allowing an analyst to understand the "typical" value within a dataset (e.g., Average Order Value).
APPROX_COUNT_DISTINCT is a descriptive tool used to understand the volume of unique entities within a dataset (e.g., "How many unique customers visited the site?"). Similar to HLL mentioned earlier, this function provides a fast summary of data volume and variety, which is a primary goal of the descriptive phase of analysis.
Evaluating the Options:
* Options A and B (REGR_INTERCEPT and REGR_SLOPE) are used for linear regression. These fall under Predictive Analytics, as they are used to model relationships and predict future outcomes, rather than just describing current data.
* Option C (ROW_NUMBER) is a window function used for data ranking and ordering, but it does not provide a descriptive summary of the dataset's characteristics.
* Options D and E are correct because they provide summary statistics (mean and cardinality) that define the "state" of the data, which is the definition of descriptive analytics.
NEW QUESTION # 20
You are tasked with loading multiple CSV files from an external stage into a Snowflake table. The files have the following naming convention: HHMlSS.csv' (e.g., 'data_20240101 120000.csv'). You need to load all the files that were created on or after '2024-01-01' into the 'target_table'. Which of the following approaches can be used to load those data?
- A. Using a Snowflake task that runs daily, retrieves all the file names from the stage, filters the file names based on created date and loops through each filtered file name to load them
- B. Using a Snowpipe with a file notification integration, configuring the notification to trigger only for files created on or after '2024-01-01'.
- C. Using a single COPY INTO statement with a pattern match against METADATA$FILENAM The matching logic is done inline with the COPY INTO statement using regex.
- D. Using a single COPY INTO statement with a wildcard pattern in the file path and filtering in a subsequent INSERT INTO statement using a WHERE clause on the filename derived from METADATA$FILENAME.
- E. Using a loop with dynamic SQL to construct COPY INTO statements for each matching file based on the date substring.
Answer: C,D
Explanation:
Option B is a viable solution. COPY INTO can be combined with METADATA$FILENAME filtering to load files matching a criteria. Option E provides a better, more efficient solution that leverages the 'METADATA$FILENAME' pseudo-column to filter files directly within the 'COPY INTO' statement using regular expressions or string functions to extract and compare the date from the filename. Option A will work but is very inefficient. Option C will work, but complex to maintain. Option D is more complex to setup than option E. Snowpipe generally does not accept a single COPY command but rather an ongoing copy operation
NEW QUESTION # 21
You are responsible for maintaining a dashboard that visualizes sales data'. The dashboard relies on a Snowflake view named 'SALES SUMMARY. Users have reported slow refresh times, especially when filtering by date. The 'SALES SUMMARY view is defined as follows:
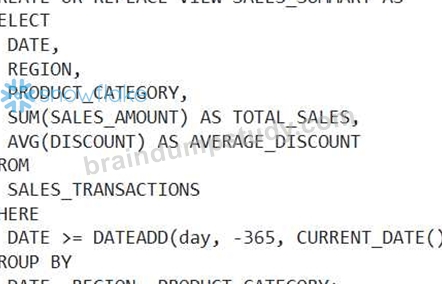
Which of the following actions could significantly improve the dashboard's performance when filtering by date, assuming 'SALES_TRANSACTIONS' table is large?
- A. Add a 'ORDER BY DATE clause to the 'SALES SUMMARY' view definition.
- B. Create a search optimization policy on the DATE column of the SALES_TRANSACTIONS table.
- C. Partition the 'SALES_TRANSACTIONS' table by the DATE column.
- D. Create a materialized view on top of
- E. create a clustering key on the DATE column in the 'SALES_TRANSACTIONS' table.
Answer: E
Explanation:
Clustering the 'SALES_TRANSACTIONS table by the DATE column is the most effective solution. Snowflake uses micro- partitioning, and clustering helps to logically group similar data together within micro-partitions. When filtering by DATE, Snowflake can then efficiently prune micro-partitions that do not contain relevant data, significantly reducing the amount of data scanned. Materialized views (A) can help but need to be maintained and add complexity. Search optimization on DATE can help but it's not the intended use case, as DATE is a range based column (B). Ordering the results (C) doesn't affect query performance significantly. Partitioning is not directly supported in Snowflake. Clustering is the correct approach.
NEW QUESTION # 22
A data analyst is tasked with creating a near-real-time dashboard using Streamlit and Snowflake to monitor website traffic. The website traffic data is continuously ingested into a Snowflake table named 'WEB TRAFFIC EVENTS' with columns 'EVENT TIME' (TIMESTAMP LTZ), 'PAGE URL' (VARCHAR), and 'USER ID' (VARCHAR). The analyst wants to ensure the Streamlit dashboard automatically reflects the latest data in Snowflake with minimal latency. Which of the following approaches would provide the MOST efficient and near-real-time data updates in the Streamlit dashboard?
- A. Use Streamlit's to directly edit data in the Snowflake table from the dashboard. This provides real-time updates by allowing users to modify the data directly.
- B. Configure Streamlit to use the Snowflake Connector for Python with auto-commit enabled. This ensures that any changes made to the data in Streamlit are immediately reflected in Snowflake.
- C. Leverage Snowflake's Change Data Capture (CDC) capabilities to track changes in the ' table. Streamlit can then query the CDC stream to retrieve only the changes since the last refresh, minimizing the amount of data transferred and processed. Utilize 'st.cache_data' with a short TTL.
- D. Use Streamlit's 'st.cache_data' decorator with a long TTL (time-to-live) on a function that queries Snowflake directly for each dashboard refresh. This will cache the query results for a longer period, reducing the load on Snowflake.
- E. Implement Snowflake's Snowpipe to continuously load data into a separate summary table containing pre-aggregated metrics (e.g., page views per minute). Streamlit can then query this summary table frequently without impacting Snowflake's performance. Use 'st.cache_data' with a short TTL to refresh the data quickly.
Answer: C
Explanation:
Leveraging Snowflake's CDC capabilities is the most efficient way to achieve near-real-time data updates in Streamlit. CDC allows you to retrieve only the changes made to the table since the last refresh, significantly reducing the amount of data transferred and processed compared to querying the entire table each time. Snowpipe is a good option, but is more oriented to data ingestion and not data changes. Option A caches results, which is opposite of real time. Option B is useful, but more complex than needed. Option C is not related to the problem. Option D is incorrect because 'auto-commit' applies only to data updates from the application to Snowflake. Streamlit can then query this CDC stream to get an updated set of data. Using 'st.cache_data' with a short TTL ensures the dashboard reflects recent data changes from the CDC Stream.
NEW QUESTION # 23
A Data Analyst is creating a Snowsight dashboard from a shared worksheet. What happens to the access and permissions of the users who initially had sharing privileges on the worksheet?
- A. The original users retain access and permissions on the worksheet.
- B. The original users temporarily lose access but regain it once the dashboard is created.
- C. The original users gain additional access to the worksheet.
- D. The original users lose access to the worksheet, their permissions on the worksheet are revoked.
Answer: D
Explanation:
When working within the Snowsight interface, the transition from a standalone worksheet to a dashboard component involves a change in how the underlying SQL and its associated metadata are managed. When a worksheet is converted or used to create a dashboard, the ownership and sharing model shifts to the dashboard level.
According to Snowflake's documentation on Snowsight collaboration, when a user creates a dashboard from a worksheet that was previously shared with others, the original worksheet's individual share settings are essentially superseded by the dashboard's own permissions. In many workflow scenarios within the UI, once the worksheet is finalized into a dashboard tile, the direct, independent access to that specific worksheet is severed for the original "sharees." Their permissions on that specific worksheet are revoked to prevent conflicting edits between the standalone version and the dashboard-integrated version.
Evaluating the Options:
* Option A is incorrect because Snowsight manages the lifecycle of worksheets used in dashboards as part of the dashboard object; independent sharing of the underlying worksheet is typically disabled or revoked.
* Option B and C are distractors; there is no mechanism in Snowsight that grants "additional" access or
"temporary" loss during the creation process.
* Option D is the 100% correct answer based on the SnowPro Data Analyst standard regarding Snowsight object ownership and sharing lifecycle. To allow others to see the work, the Analyst must now share the Dashboard itself, rather than relying on the previous worksheet-level permissions. This ensures a "single source of truth" for the visualization's logic.
NEW QUESTION # 24
......
Our DAA-C01 study materials are superior to other same kinds of study materials in many aspects. Our products’ test bank covers the entire syllabus of the test and all the possible questions which may appear in the test. Each question and answer has been verified by the industry experts. The research and production of our DAA-C01 Study Materials are undertaken by our first-tier expert team. The clients can have a free download and tryout of our DAA-C01 study materials before they decide to buy our products.
Reliable DAA-C01 Study Guide: https://www.braindumpstudy.com/DAA-C01_braindumps.html
- High Pass Rate DAA-C01 Exam Guide - DAA-C01 Latest Practice Dumps 📬 Easily obtain free download of ▶ DAA-C01 ◀ by searching on ⏩ www.dumpsmaterials.com ⏪ 📮Authorized DAA-C01 Exam Dumps
- Marvelous DAA-C01 Reliable Test Camp to Obtain Snowflake Certification 🔷 Search for ( DAA-C01 ) and download it for free immediately on 【 www.pdfvce.com 】 👍DAA-C01 Hot Spot Questions
- www.examdiscuss.com Snowflake DAA-C01 Dumps (2026) 😭 Easily obtain ➥ DAA-C01 🡄 for free download through ( www.examdiscuss.com ) 🦞Practical DAA-C01 Information
- Overcome Exam Challenges with Pdfvce DAA-C01 Exam Questions 🗾 Simply search for ▛ DAA-C01 ▟ for free download on ➠ www.pdfvce.com 🠰 🔛Authorized DAA-C01 Exam Dumps
- Snowflake First-grade DAA-C01 - SnowPro Advanced: Data Analyst Certification Exam Reliable Test Camp 💮 Search for ▷ DAA-C01 ◁ and download it for free immediately on ▛ www.testkingpass.com ▟ 🎥DAA-C01 Reliable Exam Bootcamp
- Pass Guaranteed Quiz Latest Snowflake - DAA-C01 Reliable Test Camp 🚦 Download ➥ DAA-C01 🡄 for free by simply searching on ➽ www.pdfvce.com 🢪 🥈Authorized DAA-C01 Exam Dumps
- DAA-C01 Reliable Exam Bootcamp 🕣 Exam DAA-C01 Passing Score 🎨 DAA-C01 Test Duration 🦹 Search for ➽ DAA-C01 🢪 and download it for free immediately on ➡ www.pdfdumps.com ️⬅️ ⛑Exam DAA-C01 Passing Score
- Authorized DAA-C01 Exam Dumps 🖋 Pdf DAA-C01 Torrent 🏂 DAA-C01 Accurate Test 🎭 Download ⮆ DAA-C01 ⮄ for free by simply searching on ( www.pdfvce.com ) ⬅DAA-C01 Cheap Dumps
- DAA-C01 Hot Spot Questions 🦈 DAA-C01 Accurate Test 🐸 Test DAA-C01 Questions Answers ↖ Simply search for ⇛ DAA-C01 ⇚ for free download on ➽ www.examcollectionpass.com 🢪 ⓂAuthorized DAA-C01 Exam Dumps
- DAA-C01 Reliable Exam Bootcamp 👻 Practical DAA-C01 Information 😭 New DAA-C01 Exam Bootcamp 🍒 Download ▷ DAA-C01 ◁ for free by simply entering ➡ www.pdfvce.com ️⬅️ website 🐦DAA-C01 Interactive Questions
- Marvelous DAA-C01 Reliable Test Camp to Obtain Snowflake Certification 🎮 Search for ➤ DAA-C01 ⮘ and easily obtain a free download on ☀ www.vce4dumps.com ️☀️ 🍊DAA-C01 Interactive Questions
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.grunnboek.nl, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of BraindumpStudy DAA-C01 dumps for free: https://drive.google.com/open?id=12y8SCY5LfOeN6wA_naR5_X7x1jIfHSlb