FreePdfDump is the best catalyst to help IT personage be successful. Many people who have passed some IT related certification exams used our FreePdfDump's training tool. Our FreePdfDump expert team use their experience for many people participating in Microsoft certification DP-750 exam to develope the latest effective training tools, which includes Microsoft DP-750 Certification simulation test, the current exam and answers. Our FreePdfDump's test questions and answers have 95% similarity with the real exam. With FreePdfDump's training tool your Microsoft certification DP-750 exams can be easy passed.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
>> Reliable DP-750 Test Guide <<
In order to facilitate the user's offline reading, the DP-750 study braindumps can better use the time of debris to learn. Our DP-750 study braindumps can be very good to meet user demand in this respect, allow the user to read and write in a good environment continuously consolidate what they learned. Our DP-750 prep guide has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit DP-750 Exam Questions. It points to the exam heart to solve your difficulty. So high quality materials can help you to pass your exam effectively, make you feel easy, to achieve your goal.
NEW QUESTION # 72
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.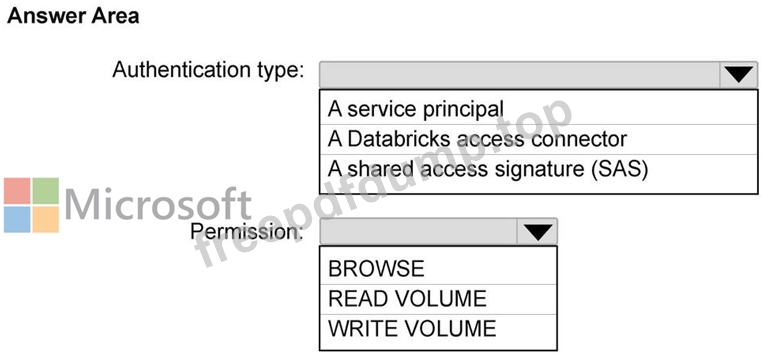
Answer:
Explanation: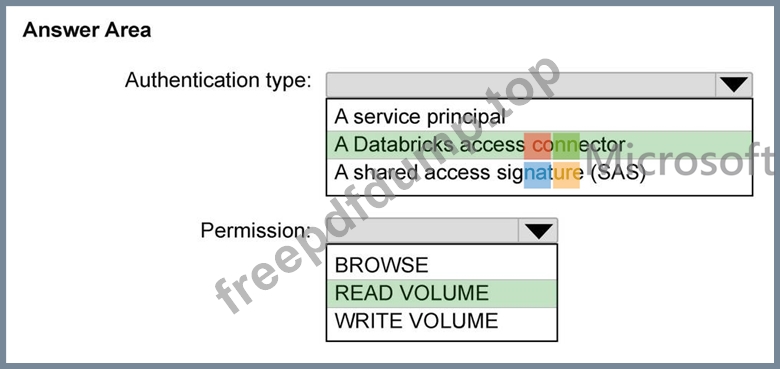
NEW QUESTION # 73
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.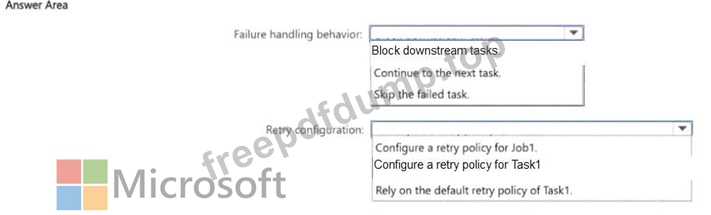
Answer:
Explanation: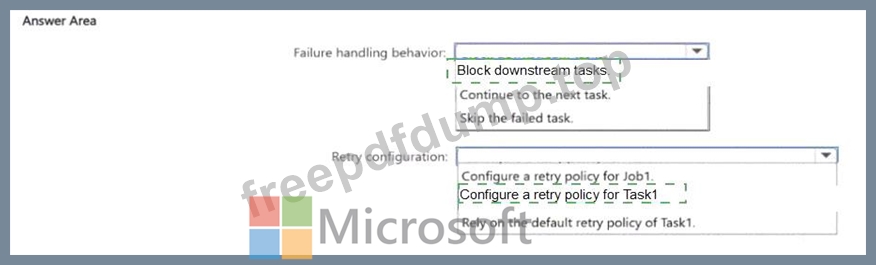
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
NEW QUESTION # 74
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline in Azure Databricks. The pipeline ingests transaction data into a table named Table1.
You need to ensure that in the event of an invalid record, the pipeline continues to run. The solution must meet the following requirements:
- Invalid records must NOT be written to Table1.
- Invalid records must be preserved for review.
- Minimize development effort.
What should you do?
Answer: D
Explanation:
To meet your pipeline requirements, use the expect_or_drop expectation constraint to ensure invalid records are not written to the table while allowing the pipeline to continue running. To preserve and review invalid records without custom development, capture the failed rows by isolating the inverse rule (expect_or_drop) in a quarantine flow.
Summary of the Behavior Matrix
Pipeline continues to run: Achieved via drop or warn behaviors (the fail policy is excluded because it halts execution).
Invalid records not written to the clean table: Achieved via the drop policy, which discards records from the downstream dataset.
Records preserved for review: Achieved by querying the automated, built-in Lakeflow Event Log Delta table, which automatically captures the details of any rejected or flagged rows without requiring custom code.
Minimized development: Eliminates the need to construct secondary "quarantine" storage tables manually.
Reference:
https://docs.databricks.com/aws/en/ldp/best-practices
NEW QUESTION # 75
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 76
You have an Azure Databricks account that contains workspaces enabled for Unity Catalog.
You need to implement audit logging to meet the following requirements:
* Capture audit logs for all the workspaces in the account.
* Retain the audit logs for 90 days.
* Minimize storage and ingestion costs.
The logs will be reviewed only during security investigations and will NOT be queried regularly.
To where should you send the audit logs?
Answer: C
Explanation:
An Azure Storage account provides durable, comparatively low-cost retention for diagnostic and audit logs that are accessed infrequently. A lifecycle or retention policy can preserve the logs for 90 days and then remove them automatically. This matches an investigation-only access pattern without paying the ingestion and indexing charges associated with Log Analytics. Azure Monitor metrics stores numerical monitoring measurements, not the complete audit-event records required here. Azure Event Hubs is a streaming transport intended to forward events to consumers and is not the final long-term retention destination. Log Analytics is appropriate when teams need frequent querying, dashboards, and alerting, but those capabilities introduce unnecessary cost for logs reviewed only during occasional investigations. Storage therefore best satisfies centralized retention and cost requirements.
NEW QUESTION # 77
......
For the office worker, they are both busy in the job or their family; for the students, they possibly have to learn or do other things. But if they use our DP-750 test prep, they won’t need so much time to prepare the exam and master exam content in a short time. What they need to do is just to spare 1-2 hours to learn and practice every day and then pass the exam with DP-750 Test Prep easily. It costs them little time and energy.
DP-750 Exam Flashcards: https://www.freepdfdump.top/DP-750-valid-torrent.html