Valid Certified-Data-Engineer-Professional Exam Review, Latest Certified-Data-Engineer-Professional Exam Discount

In this cut-throat competitive world of VCEEngine, the Databricks Certified-Data-Engineer-Professional certification is the most desired one. But what creates an obstacle in the way of the aspirants of the Databricks Certified-Data-Engineer-Professional certificate is their failure to find up-to-date, unique, and reliable Certified-Data-Engineer-Professional practice material to succeed in passing the Databricks Certified-Data-Engineer-Professional certification exam. If you are one of such frustrated candidates, don't get panic. VCEEngine declares its services in providing the real Certified-Data-Engineer-Professional PDF Questions.
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 2. Develop unit and integration tests for data processing code
- 3. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Compare streaming tables and materialized views
- 6. Use control flow operators in pipeline components
- 7. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 8. Use APPLY CHANGES APIs for change data capture
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Topic 2: Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Topic 3: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Topic 5: Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 7: Data Modelling | - Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Topic 8: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
|
| Topic 9: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 10: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure sharing with external platforms using the open sharing protocol
|
>> Valid Certified-Data-Engineer-Professional Exam Review <<
Latest Certified-Data-Engineer-Professional Exam Discount | Certified-Data-Engineer-Professional Discount
We boost the professional and dedicated online customer service team. They are working for the whole day, weak and year to reply the clients' question about our Certified-Data-Engineer-Professional study question and solve the clients' problem as quickly as possible. If the clients have any problem about the use of our Certified-Data-Engineer-Professional Exam Practice materials and the refund issue they can contact our online customer service at any time, our online customer service personnel will reply them quickly. So you needn’t worry about you will encounter the great difficulties when you use our Certified-Data-Engineer-Professional test pdf.
Databricks Certified Data Engineer Professional Sample Questions (Q31-Q36):
NEW QUESTION # 31
An upstream system is emitting change data capture (CDC) logs that are being written to a cloud object storage directory. Each record in the log indicates the change type (insert, update, or delete) and the values for each field after the change. The source table has a primary key identified by the field pk_id.
For auditing purposes, the data governance team wishes to maintain a full record of all values that have ever been valid in the source system. For analytical purposes, only the most recent value for each record needs to be recorded. The Databricks job to ingest these records occurs once per hour, but each individual record may have changed multiple times over the course of an hour.
Which solution meets these requirements?
- A. Use merge into to insert, update, or delete the most recent entry for each pk_id into a bronze table, then propagate all changes throughout the system.
- B. Iterate through an ordered set of changes to the table, applying each in turn; rely on Delta Lake's versioning ability to create an audit log.
- C. Use Delta Lake's change data feed to automatically process CDC data from an external system, propagating all changes to all dependent tables in the Lakehouse.
- D. Ingest all log information into a bronze table; use merge into to insert, update, or delete the most recent entry for each pk_id into a silver table to recreate the current table state.
- E. Create a separate history table for each pk_id resolve the current state of the table by running a union all filtering the history tables for the most recent state.
Answer: D
Explanation:
CDF captures changes only from a Delta table and is only forward-looking once enabled. The CDC logs are writing to object storage. So you would need to ingestion those and merge into downstream tables.
NEW QUESTION # 32
Which statement describes a key benefit of an end-to-end test?
- A. It pinpoint errors in the building blocks of your application.
- B. It makes it easier to automate your test suite
- C. It provides testing coverage for all code paths and branches.
- D. It closely simulates real world usage of your application.
Answer: D
Explanation:
End-to-end testing is a methodology used to test whether the flow of an application, from start to finish, behaves as expected. The key benefit of an end-to-end test is that it closely simulates real- world, user behavior, ensuring that the system as a whole operates correctly.
NEW QUESTION # 33
A Delta Lake table was created with the below query:
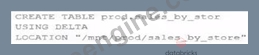
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
- A. A new Delta transaction log Is created for the renamed table.
- B. The table name change is recorded in the Delta transaction log.
- C. The table reference in the metastore is updated and all data files are moved.
- D. The table reference in the metastore is updated and no data is changed.
- E. All related files and metadata are dropped and recreated in a single ACID transaction.
Answer: D
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly.
NEW QUESTION # 34
The data governance team has instituted a requirement that all tables containing Personal Identifiable Information (PH) must be clearly annotated. This includes adding column comments, table comments, and setting the custom table property "contains_pii" = true.
The following SQL DDL statement is executed to create a new table:
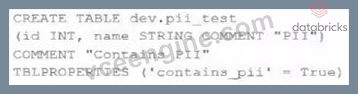
Which command allows manual confirmation that these three requirements have been met?
- A. DESCRIBE EXTENDED dev.pii test
- B. DESCRIBE DETAIL dev.pii test
- C. SHOW TBLPROPERTIES dev.pii test
- D. SHOW TABLES dev
- E. DESCRIBE HISTORY dev.pii test
Answer: A
Explanation:
This is the correct answer because it allows manual confirmation that these three requirements have been met. The requirements are that all tables containing Personal Identifiable Information (PII) must be clearly annotated, which includes adding column comments, table comments, and setting the custom table property "contains_pii" = true. The DESCRIBE EXTENDED command is used to display detailed information about a table, such as its schema, location, properties, and comments. By using this command on the dev.pii_test table, one can verify that the table has been created with the correct column comments, table comment, and custom table property as specified in the SQL DDL statement.
NEW QUESTION # 35
The following code has been migrated to a Databricks notebook from a legacy workload:
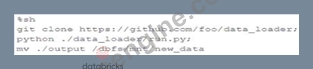
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- B. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- C. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- D. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- E. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
Answer: C
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 36
......
As for the Certified-Data-Engineer-Professional study materials themselves, they boost multiple functions to assist the learners to learn the study materials efficiently from different angles. For example, the function to stimulate the exam can help the exam candidates be familiar with the atmosphere and the pace of the Real Certified-Data-Engineer-Professional Exam and avoid some unexpected problem occur. Briefly speaking, our Certified-Data-Engineer-Professional training guide gives priority to the quality and service and will bring the clients the brand new experiences and comfortable feelings to pass the Certified-Data-Engineer-Professional exam.
Latest Certified-Data-Engineer-Professional Exam Discount: https://www.vceengine.com/Certified-Data-Engineer-Professional-vce-test-engine.html
- Most Certified-Data-Engineer-Professional Reliable Questions 🦡 Certified-Data-Engineer-Professional Exam Guide 👈 Certified-Data-Engineer-Professional Exam Guide 🔫 Search for ➠ Certified-Data-Engineer-Professional 🠰 and download it for free on ➠ www.practicevce.com 🠰 website 🏜Actual Certified-Data-Engineer-Professional Test
- Free PDF Quiz Databricks - Reliable Valid Certified-Data-Engineer-Professional Exam Review 🍯 Open 「 www.pdfvce.com 」 and search for ▛ Certified-Data-Engineer-Professional ▟ to download exam materials for free 🧕Most Certified-Data-Engineer-Professional Reliable Questions
- Actual Certified-Data-Engineer-Professional Test 🛂 Certified-Data-Engineer-Professional Real Torrent 🏋 Certified-Data-Engineer-Professional Simulations Pdf 🛣 Download [ Certified-Data-Engineer-Professional ] for free by simply searching on 「 www.prepawayete.com 」 🔟Certified-Data-Engineer-Professional Real Torrent
- Free PDF 2026 Valid Databricks Valid Certified-Data-Engineer-Professional Exam Review 🤝 Download ☀ Certified-Data-Engineer-Professional ️☀️ for free by simply entering ▶ www.pdfvce.com ◀ website 🥪Test Certified-Data-Engineer-Professional Free
- www.exam4labs.com: Your Reliable Databricks Certified-Data-Engineer-Professional Exam Companion 🥡 The page for free download of ✔ Certified-Data-Engineer-Professional ️✔️ on ⏩ www.exam4labs.com ⏪ will open immediately 📌Certified-Data-Engineer-Professional Exam Guide
- Certified-Data-Engineer-Professional Trustworthy Exam Torrent 🤙 Test Certification Certified-Data-Engineer-Professional Cost ⏯ Certified-Data-Engineer-Professional Trustworthy Exam Torrent 👆 Search for ( Certified-Data-Engineer-Professional ) on “ www.pdfvce.com ” immediately to obtain a free download 🆗Certified-Data-Engineer-Professional Exam Objectives Pdf
- www.examdiscuss.com: Your Reliable Databricks Certified-Data-Engineer-Professional Exam Companion 📺 Download ▛ Certified-Data-Engineer-Professional ▟ for free by simply searching on ( www.examdiscuss.com ) 🦇Certified-Data-Engineer-Professional Test Dumps Demo
- Free PDF 2026 Valid Databricks Valid Certified-Data-Engineer-Professional Exam Review 🌷 Search for 【 Certified-Data-Engineer-Professional 】 and download it for free on “ www.pdfvce.com ” website 🌜Reliable Certified-Data-Engineer-Professional Exam Sims
- Certified-Data-Engineer-Professional Test Guide 🩳 Test Certified-Data-Engineer-Professional Free ‼ Certified-Data-Engineer-Professional Exam Guide 😟 Search for “ Certified-Data-Engineer-Professional ” and download exam materials for free through ⮆ www.validtorrent.com ⮄ 🍛Test Certification Certified-Data-Engineer-Professional Cost
- Free PDF Quiz 2026 Databricks Certified-Data-Engineer-Professional: Pass-Sure Valid Databricks Certified Data Engineer Professional Exam Review 🧁 Easily obtain ⇛ Certified-Data-Engineer-Professional ⇚ for free download through ➤ www.pdfvce.com ⮘ 🎱Certified-Data-Engineer-Professional Exam Objectives Pdf
- Certified-Data-Engineer-Professional Test Dumps Demo 🧎 Certified-Data-Engineer-Professional Simulations Pdf 🔲 Valid Certified-Data-Engineer-Professional Test Cost 😊 ⇛ www.vce4dumps.com ⇚ is best website to obtain ☀ Certified-Data-Engineer-Professional ️☀️ for free download 🦂Certified-Data-Engineer-Professional Reliable Exam Topics
- connect.garmin.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes