Practice materials are typically seen as the tools of reviving, practicing and remembering necessary exam questions for the exam, spending much time on them you may improve the chance of winning. However, our AI-200 training materials can offer better condition than traditional practice materials and can be used effectively. We treat it as our major responsibility to offer help so our AI-200 Practice Guide can provide so much help, the most typical one is the efficiency of our AI-200 exam questions, which can help you pass the AI-200 exam only after studying for 20 to 30 hours.
| Section | Objectives |
|---|---|
| Topic 1: Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Topic 2: Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search - Implement computer vision solutions |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
>> Certification AI-200 Exam Cost <<
To be successful in a professional exam like the Microsoft AI-200 exam, you must know the criteria to pass it. You should know the type of Developing AI Cloud Solutions on Azure questions, the pattern of the Developing AI Cloud Solutions on Azure exam, and the time limit to complete the AI-200 Exam. All these factors help you pass the Microsoft AI-200 exam. Getcertkey is your reliable partner in getting your AI-200 certification. The Microsoft AI-200 exam dumps help you achieve your professional goals.
NEW QUESTION # 116
Your application must classify uploaded product images into one of 40 custom categories specific to your business (e.g., proprietary part numbers). What should you use?
Answer: D
Explanation:
Prebuilt Vision models recognize general objects/scenes but not business-specific categories.
Custom Vision allows you to train a classifier on your own labeled images for domain-specific categories such as proprietary part numbers.
NEW QUESTION # 117
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to implement a secret management solution for the Recommendation API to satisfy the security and identity requirements of Fabrikam Inc.
Which service should you use?
Answer: B
Explanation:
Scenario, technical requirements: Secret management: All secrets must be stored centrally.
Secrets must be rotated automatically by using a centralized lifecycle policy.
Azure Key Vault is the correct and recommended service to store secrets in this scenario. It fulfills all the requirements for centralized management, Python SDK integration, and automated rotation.
Reference:
https://www.cloudthat.com/resources/blog/securing-sensitive-information-with-azure-key-vault
NEW QUESTION # 118
Drag and Drop Question
You have an existing AKS cluster and a container image stored in Azure Container Registry.
You must deploy a new version without interrupting traffic.
You need to perform a rolling update by using a manifest file.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.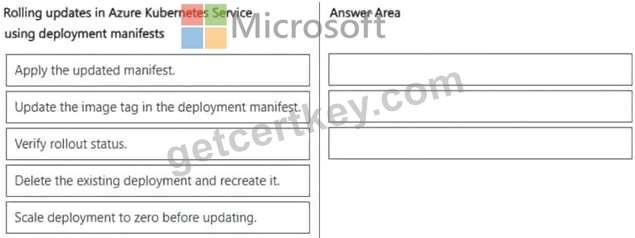
Answer:
Explanation: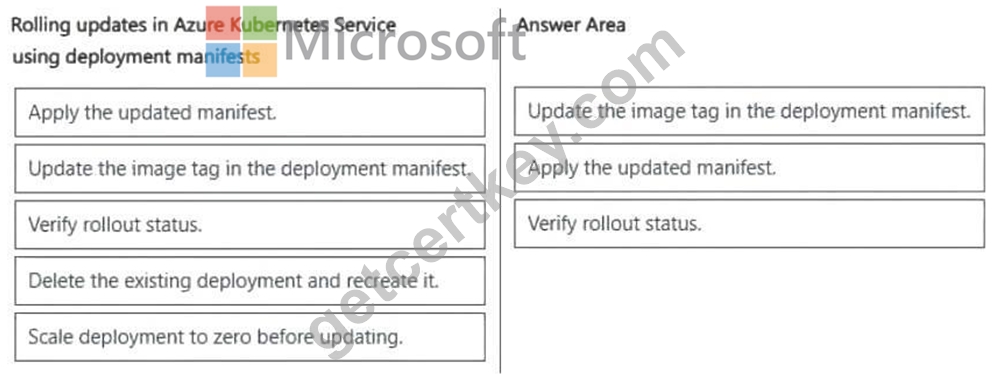
Explanation:
Step 1: Update the image tag in the deployment manifest
This changes the definition file to point to your new version image stored in the Azure Container Registry.
Step 2: Apply the updated manifest
Running kubectl apply -f <manifest.yaml> triggers Kubernetes to natively initiate a zero-downtime rolling update strategy, incrementally replacing old pods with new ones.
Step 3: Verify rollout status
Running kubectl rollout status deployment/<deployment-name> allows you to track and ensure the new version deploys successfully without failure.
Reference:
https://learn.microsoft.com/en-us/azure/aks/tutorial-kubernetes-deploy-application
NEW QUESTION # 119
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to improve throughput for concurrent application requests to PostgreSQL. What should you implement?
Answer: C
Explanation:
To improve throughput for highly concurrent application requests in this architecture, you should implement connection pooling.
PostgreSQL follows a process-based architecture where each client connection spawns a separate backend process. This consumes significant memory and CPU overhead during high concurrency. Connection pooling (using tools like PgBouncer or Azure's built-in pooler) allows containerized microservices to reuse a fixed set of database connections. This drastically reduces connection overhead, prevents database exhaustion, and maximizes throughput for short, rapid API queries like vector similarity searches.
Reference:
https://medium.com/@srajanpathak45/a-principal-engineers-guide-to-postgresql-and-modern-alternatives-e8920fd6269a
NEW QUESTION # 120
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Drag and Drop Question
You need to implement the semantic retrieval workflow for the recommendation engine to meet the technical and performance requirements of Fabrikam Inc.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
Explanation:
Scenario:
Current: The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Step 1: Define Table Schema with vector and metadata columns
Schema configuration: Establish the PostgreSQL table structure using the pgvector extension to store both the product metadata and the high-dimensional embedding vectors.
Step 2: Configure a Hierachical Navigable Small World (HNSW) index on the embedding vector columns Configure Vector Index HNSW indexing: Implement a Hierarchical Navigable Small World (HNSW) index rather than a B- tree index, as standard B-tree indexing cannot index multi-dimensional vector embeddings for similarity searches.
An HNSW (Hierarchical Navigable Small World) index is the correct choice for the embedding vector columns in this scenario, while a B-tree index is entirely unsuited for vector similarity search.
Step 3: Load embedding vectors and associated product metadata
Populate Database
Data ingestion: Load the pre-computed embedding vectors along with their corresponding product metadata into the newly indexed table.
Step 4: Perform a similarity search using a WHERE clause and the <=> operator Query Similar Items Similarity search: Execute vector similarity queries using the <=> operator (which denotes cosine distance in pgvector) to find and return the closest product recommendations.
Reference:
https://mobisoftinfotech.com/resources/blog/enhancing-rag-generative-ai-postgresql-hnsw-indexes
NEW QUESTION # 121
......
In order to survive in the society and realize our own values, learning our AI-200 practice engine is the best way. Never top improving yourself. The society warmly welcomes struggling people. You will really benefit from your correct choice. Our AI-200 Study Materials are ready to help you pass the exam and get the certification. You can certainly get a better life with the certification. Please make a decision quickly. We are waiting for you to purchase our AI-200 exam questions.
AI-200 Sample Questions Answers: https://www.getcertkey.com/AI-200_braindumps.html