What's more, part of that RealVCE DAA-C01 dumps now are free: https://drive.google.com/open?id=1E0pRq8SKMKpbJmMLCPdCegZ6gBcL6uG8
Generally speaking, every candidate wants to pass the exam just one time. DAA-C01 learning materials of us can do that for you. Since we have a professional team to collect and research the latest information for the exam, and therefore the quality can be guaranteed. We offer you free demo for DAA-C01 Exam Materials to have a try, so that you can know what the complete version is like. Besides, we also pass guarantee and money back guarantee, and if you fail to pass the exam after using DAA-C01 exam materials of us, we will give you refund.
| Section | Objectives |
|---|---|
| Snowflake Architecture and Data Platform Fundamentals | - Snowflake architecture concepts
|
| Data Loading and Unloading | - Data ingestion methods
|
| Security, Governance, and Data Sharing | - Access control and security
|
| Data Modeling and Performance Optimization | - Modeling approaches in Snowflake
|
| Data Transformation and Analysis | - Analytical workloads
|
>> Reliable DAA-C01 Exam Test <<
To make sure that our DAA-C01 training braindumps are the best on matter on the content or on the displays, we invite volunteers to experience our DAA-C01 real exam before selling to customers. They will carefully tell their thoughts about our DAA-C01 Study Guide. Sometimes, their useful suggestions will also be adopted. That is the important reason why our DAA-C01 exam materials are always popular in the market.
NEW QUESTION # 64
You are tasked with preparing a large dataset of website clickstream data stored in a Snowflake table named This table contains a 'timestamp' column (TIMESTAMP NTZ), a column (VARCHAR), and a 'page_urr column (VARCHAR). You need to identify the most popular pages visited by users during specific hours of the day, but only for users who have visited at least 5 unique pages in the dataset. Which sequence of SQL operations, potentially including temporary tables or CTEs, would efficiently achieve this goal in Snowflake?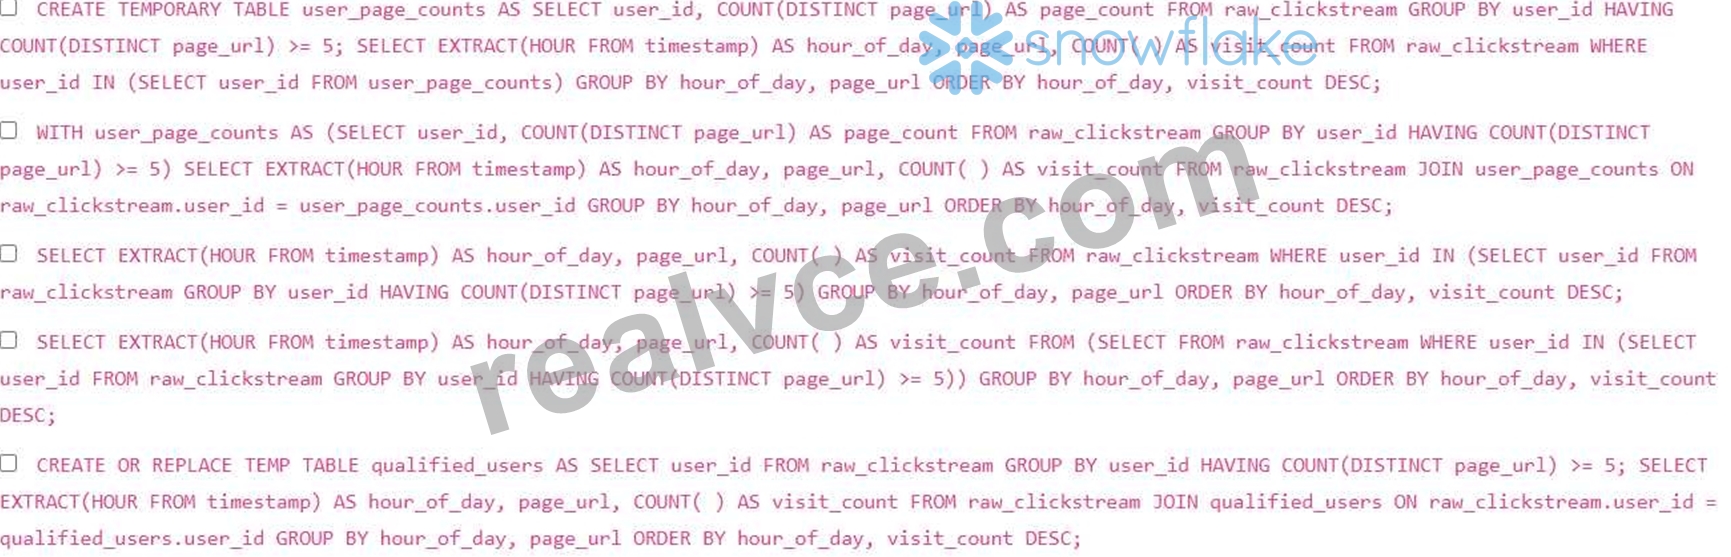
Answer: B,E
Explanation:
Option B and E are the most efficient solutions. Option B uses a CTE (Common Table Expression) to filter users who have visited at least 5 unique pages and then joins this result with the original table to calculate visit counts by hour and page. Option E creates a TEMP table for qualified users then joins against it to create a final aggregated set. A is functionally correct but may not be as optimized as using a CTE and uses two queries. C has an unnecessary subquery in the WHERE clause, which can degrade performance. D uses inline view which is less readable and less efficient than CTE. Both CTEs (B) and temporary tables (E) are common techniques in Snowflake for breaking down complex queries and can improve readability and maintainability. Snowflake's query optimizer is generally very good, and the CTE approach (B) is often preferred for its clarity.
NEW QUESTION # 65
You are designing a data warehouse for a retail company. The company needs to analyze sales data based on product category, customer demographics, and store location. The sales data is initially stored in a semi-structured JSON format with nested arrays for product details and customer information. The BI team requires optimized query performance for aggregations across these dimensions. Which approach is most suitable for this scenario?
Answer: D
Explanation:
Option B is the most suitable approach. A flattened relational data model with separate tables and foreign keys allows for efficient querying and aggregations across different dimensions, which is a key requirement for BI reporting. Flattening the data reduces the overhead of parsing JSON during query execution and enables the use of standard SQL aggregation functions. Option A can lead to performance issues with complex JSON structures. Option D can lead to data redundancy and update anomalies. Option C offers a hybrid approach but can still be inefficient for certain queries. Option E relies too heavily on Snowflake's automatic optimization and will likely underperform compared to a properly designed data model.
NEW QUESTION # 66
You are analyzing website traffic data in Snowflake using Snowsight. The data is stored in a table 'WEB TRAFFIC' with columns 'VISIT DATE (DATE), 'PAGE URL' (VARCHAR), 'VISITOR_ID (VARCHAR), and (INT - in seconds). You need to create a Snowsight dashboard to answer the following questions: 1. What is the average session duration per page URL? 2. What is the distribution of session durations (histogram)? 3. How many unique visitors are there per day? Which of the following approaches is the MOST efficient and appropriate for creating this Snowsight dashboard?
Answer: B
Explanation:
Option A is the most efficient and appropriate. Snowsight's direct SQL query functionality, coupled with the 'WIDTH_BUCKET' function, provides a straightforward and performant way to create the required visualizations. Using views (Option E) adds an unnecessary layer of abstraction. Trying to combine all visualizations into a single tile (Options B and D) is not suitable for the different visualization types. Using Snowsight Notebook (Option C) introduces unnecessary overhead for this relatively simple descriptive analysis task. While Notebooks are powerful, they're best used for more complex data transformations and analysis that SQL cannot easily handle.
NEW QUESTION # 67
A data pipeline is failing intermittently, with the error logs indicating 'Insufficient compute resources'. You are tasked with collecting data to diagnose the root cause. What combination of Snowflake features and data collection strategies would be MOST effective in identifying if warehouse auto-scaling or query performance is the primary contributor to the issue?
Answer: B,E
Explanation:
Options A and C provide a targeted approach. A allows tracking warehouse resource usage during the pipeline failures, identifying if the warehouse is reaching its limits. C helps identify slow-running queries contributing to resource exhaustion and detects queries using excessive local disk, indicating potential optimization opportunities. Increasing the warehouse size without analysis (B & D) is not cost-effective. Collecting only error logs (E) is not sufficient for a comprehensive diagnostic approach. It is too narrow and may not expose warehouse load issues and bottlenecks.
NEW QUESTION # 68
You have a Snowpipe configured to load CSV files from an AWS S3 bucket into a Snowflake table. The CSV files are compressed using GZIP. You've noticed that Snowpipe is occasionally failing with the error 'Incorrect number of columns in file'. This issue is intermittent and affects different files. Your team has confirmed that the source data schema should be consistent. What combination of actions provides the most likely and efficient solution to address this intermittent column count mismatch issue?
Answer: C,E
Explanation:
Setting *ERROR ON COLUMN COUNT MISMATCH' to FALSE allows the pipe to continue without halting on such errors. However, this approach will leave behind bad records. Carriage return issues can occur, which affect the column count when ingesting data. If there are carriage return characters inside the CSV fields, this will be misinterpreted as delimiters. Option A might help if headers are present and consistent, but is less likely the root cause of an intermittent column count mismatch. Option C is unlikely to be a primary cause of column count issues as GZIP decompression is generally reliable. Option E is a workaround, but less efficient than correctly configuring the CSV parsing.
NEW QUESTION # 69
......
The clients can try out and download our DAA-C01 study materials before their purchase. They can immediately use our DAA-C01 training guide after they pay successfully. And our expert team will update the DAA-C01 study materials periodically after their purchase and if the clients encounter the problems in the course of using our DAA-C01 Learning Engine our online customer service staff will enthusiastically solve their problems.
DAA-C01 Latest Test Simulator: https://www.realvce.com/DAA-C01_free-dumps.html
What's more, part of that RealVCE DAA-C01 dumps now are free: https://drive.google.com/open?id=1E0pRq8SKMKpbJmMLCPdCegZ6gBcL6uG8