2026 Die neuesten EchteFrage Data-Engineer-Associate PDF-Versionen Prüfungsfragen und Data-Engineer-Associate Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1l-NtdeEuGxEZma5K16Vi8zp3m1dbslQu
Heutztage hat ein Fachqualifizieter große Vorteile in der heute konkurrenzfähigen Gesellschaft, besonders im IT-Bereich. Einige IT-Zertifikate zu bekommen ist sehr nützlich. Die Amazon Data-Engineer-Associate Zertifizierungsprüfung ist eine Prüfung, die das Niveau der fachlichen Kenntnissen überprüft und stellt ein großes Gewicht in der IT-Branche dar. Wegen der Schwierigkeit der Amazon Data-Engineer-Associate (AWS Certified Data Engineer - Associate (DEA-C01)) Zertifizierungsprüfung hat man viel Zeit und Energie für die Prüfung benutzt. Jedoch sind sie am Ende doch in der Prüfung durchgefallen. Die Gründe dafür liegt darin, dass Sie nicht an der speziellen Kursen teilnehmen. Nun haben Experten die zielgerichteten Prüfungen entwickelt, die Ihnen helden, viel Zeit und Energie zu ersparen und trotzdem die Prüfung 100% zu bestehen.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Ingest and transform data using AWS services - Build and manage data pipelines |
| Topic 2: Data Security and Governance | 18% | - Implement data security controls - Apply governance and compliance best practices |
| Topic 3: Data Store Management | 26% | - Select appropriate data storage solutions - Optimize storage performance and cost |
| Topic 4: Data Operations and Support | 22% | - Monitor and maintain data pipelines - Troubleshoot data workflow issues |
>> Data-Engineer-Associate Exam Fragen <<
Bestehen Ihre Freude die Amazon Data-Engineer-Associate Zertifizierungsprüfung? Wie können Sie das Ziel erreichen? Wir EchteFrage können Ihnen die Methode zeigen. Die Amazon Data-Engineer-Associate Dumps von EchteFrage sind die neuesten und umfassendsten Prüfungsunterlagen und wir bieten Ihnen auch sehr guten Service. Wir EchteFrage sind die einzige Wahl für Sie Amazon Data-Engineer-Associate Zertifizierungsprüfung zu bestehen. Informieren Sie sich bitte an EchteFrage Website. Lassen Wir Ihnen helfen.
240. Frage
A company wants to implement real-time analytics capabilities. The company wants to use Amazon Kinesis Data Streams and Amazon Redshift to ingest and process streaming data at the rate of several gigabytes per second. The company wants to derive near real-time insights by using existing business intelligence (BI) and analytics tools.
Which solution will meet these requirements with the LEAST operational overhead?
Antwort: A
Begründung:
This solution meets the requirements of implementing real-time analytics capabilities with the least operational overhead. By creating an external schema in Amazon Redshift, you can access the data from Kinesis Data Streams using SQL queries without having to load the data into the cluster. By creating a materialized view on top of the stream, you can store the results of the query in the cluster and make them available for analysis. By setting the materialized view to auto refresh, you can ensure that the view is updated with the latest data from the stream at regular intervals. This way, you can derive near real-time insights by using existing BI and analytics tools. References:
Amazon Redshift streaming ingestion
Creating an external schema for Amazon Kinesis Data Streams
Creating a materialized view for Amazon Kinesis Data Streams
241. Frage
A data engineer is using Amazon QuickSight to build a dashboard to report a company's revenue in multiple AWS Regions. The data engineer wants the dashboard to display the total revenue for a Region, regardless of the drill-down levels shown in the visual.
Which solution will meet these requirements?
Antwort: C
Begründung:
Option C (LAC-A) is the correct choice because the requirement is to always show the Region-level total even when the visual is drilled down into lower levels (for example, country # city # store). A simple calculated field (Option B) is computed at the row level and then aggregated by the visual, so it will change as the drill-down changes the grain. A table calculation (Option A) is evaluated based on the current visual layout and can vary with the fields placed in the visual, which makes it unreliable for enforcing a fixed
"Region total regardless of drill-down."
A level-aware calculation (aggregate) is specifically intended to "lock" an aggregation to a chosen dimensional level (here: Region). That means you can compute revenue aggregated at the Region level and reuse that value across lower drill levels without it recalculating at city/store granularity. A window LAC (LAC-W) is primarily for windowed analytics (running totals, period-over-period, rank, moving averages) over a partition/order, not for enforcing a fixed dimensional aggregation level.
Therefore, LAC-A best matches the requirement.
242. Frage
A company stores employee data in Amazon Redshift A table named Employee uses columns named Region ID, Department ID, and Role ID as a compound sort key. Which queries will MOST increase the speed of a query by using a compound sort key of the table? (Select TWO.)
Antwort: B,D
Begründung:
In Amazon Redshift, a compound sort key is designed to optimize the performance of queries that use filtering and join conditions on the columns in the sort key. A compound sort key orders the data based on the first column, followed by the second, and so on. In the scenario given, the compound sort key consists of Region ID, Department ID, and Role ID. Therefore, queries that filter on the leading columns of the sort key are more likely to benefit from this order.
Option B: "Select * from Employee where Region ID='North America' and Department ID=20;" This query will perform well because it uses both the Region ID and Department ID, which are the first two columns of the compound sort key. The order of the columns in the WHERE clause matches the order in the sort key, thus allowing the query to scan fewer rows and improve performance.
Option C: "Select * from Employee where Department ID=20 and Region ID='North America';" This query also benefits from the compound sort key because it includes both Region ID and Department ID, which are the first two columns in the sort key. Although the order in the WHERE clause does not match exactly, Amazon Redshift will still leverage the sort key to reduce the amount of data scanned, improving query speed.
Options A, D, and E are less optimal because they do not utilize the sort key as effectively:
Option A only filters by the Region ID, which may still use the sort key but does not take full advantage of the compound nature.
Option D uses only Role ID, the last column in the compound sort key, which will not benefit much from sorting since it is the third key in the sort order.
Option E filters on Region ID and Role ID but skips the Department ID column, making it less efficient for the compound sort key.
Reference:
Amazon Redshift Documentation - Sorting Data
AWS Certified Data Analytics Study Guide
AWS Certification - Data Engineer Associate Exam Guide
243. Frage
A company has multiple applications that use datasets that are stored in an Amazon S3 bucket. The company has an ecommerce application that generates a dataset that contains personally identifiable information (PII).
The company has an internal analytics application that does not require access to the PII.
To comply with regulations, the company must not share PII unnecessarily. A data engineer needs to implement a solution that with redact PII dynamically, based on the needs of each application that accesses the dataset.
Which solution will meet the requirements with the LEAST operational overhead?
Antwort: B
Begründung:
Option B is the best solution to meet the requirements with the least operational overhead because S3 Object Lambda is a feature that allows you to add your own code to process data retrieved from S3 before returning it to an application. S3 Object Lambda works with S3 GET requests and can modify both the object metadata and the object data. By using S3 Object Lambda, you can implement redaction logic within an S3 Object Lambda function to dynamically redact PII based on the needs of each application that accesses the data. This way, you can avoid creating and maintaining multiple copies of the dataset with different levels of redaction.
Option A is not a good solution because it involves creating and managing multiple copies of the dataset with different levels of redaction for each application. This option adds complexity and storage cost to the data protection process and requires additional resources and configuration. Moreover, S3 bucket policies cannot enforce fine-grained data access control at the row and column level, so they are not sufficient to redact PII.
Option C is not a good solution because it involves using AWS Glue to transform the data for each application. AWS Glue is a fully managed service that can extract, transform, and load (ETL) data from various sources to various destinations, including S3. AWS Glue can also convert data to different formats, such as Parquet, which is a columnar storage format that is optimized for analytics. However, in this scenario, using AWS Glue to redact PII is not the best option because it requires creating and maintaining multiple copies of the dataset with different levels of redaction for each application. This option also adds extra time and cost to the data protection process and requires additional resources and configuration.
Option D is not a good solution because it involves creating and configuring an API Gateway endpoint that has custom authorizers. API Gateway is a service that allows you to create, publish, maintain, monitor, and secure APIs at any scale. API Gateway can also integrate with other AWS services, such as Lambda, to provide custom logic for processing requests. However, in this scenario, using API Gateway to redact PII is not the best option because it requires writing and maintaining custom code and configuration for the API endpoint, the custom authorizers, and the REST API call. This option also adds complexity and latency to the data protection process and requires additional resources and configuration.
References:
* AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide
* Introducing Amazon S3 Object Lambda - Use Your Code to Process Data as It Is Being Retrieved from S3
* Using Bucket Policies and User Policies - Amazon Simple Storage Service
* AWS Glue Documentation
* What is Amazon API Gateway? - Amazon API Gateway
244. Frage
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?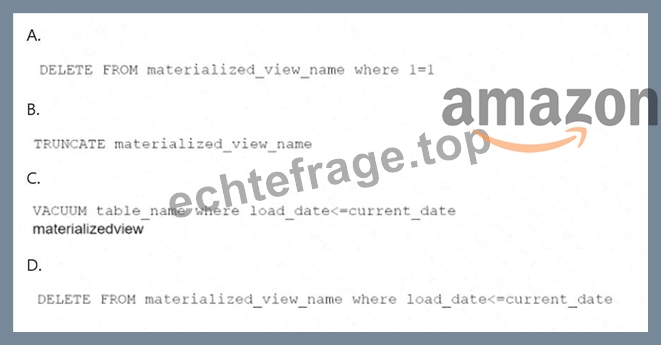
Antwort: C
Begründung:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
245. Frage
......
Unsere Schulungsunterlagen können Ihre Kenntnisse vor der Amazon Data-Engineer-Associate Prüfung testen und auch Ihr Verhalten in einer bestimmten Zeit bewerten. Wir geben Ihnen Anleitung zu Ihrer Note und Schwachpunkt, so dass Sie Ihre Schwäche nachholen können. Die Lernhilfe zur Amazon Data-Engineer-Associate Zertifizierungsprüfung von EchteFrage stellen Ihnen unterschiedliche logische Themen vor. So können Sie nicht nur lernen, sondern auch andere Techiniken und Subjekte kennen lernen. Wir versprechen, dass unsere Amazon Data-Engineer-Associate Schlungsunterlagen von der Praxis bewährt werden. EchteFrage hat genügende Vorbereitung für Ihre Prüfung getroffen. Unsere Fragen sind umfassend und der Preis ist rational.
Data-Engineer-Associate Probesfragen: https://www.echtefrage.top/Data-Engineer-Associate-deutsch-pruefungen.html
Übrigens, Sie können die vollständige Version der EchteFrage Data-Engineer-Associate Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1l-NtdeEuGxEZma5K16Vi8zp3m1dbslQu