P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by NewPassLeader: https://drive.google.com/open?id=1cJawtREkHoQTCXfTuYGMIXD8DGTELL5O
Preparing for the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) test can be challenging, especially when you are busy with other responsibilities. Candidates who don't use Professional-Machine-Learning-Engineer dumps fail in the Professional-Machine-Learning-Engineer examination and waste their resources. Using updated and valid Professional-Machine-Learning-Engineer Questions; can help you develop skills essential to achieve success in the Professional-Machine-Learning-Engineer certification exam.
| Section | Objectives |
|---|---|
| Topic 1: Architecting low-code ML solutions | - Leveraging pre-built ML models as a service (e.g., Vision AI, Speech-to-Text, Recommendations AI) - AutoML capabilities and implementation - Implementing BigQuery ML for basic models |
| Topic 2: Scaling prototypes into ML models | - Hyperparameter tuning - Training at scale (Distributed training, TPUs) - Frameworks (TensorFlow, PyTorch, JAX, Scikit-learn) |
| Topic 3: Serving and scaling models | - Online prediction (Vertex AI Prediction) - Batch prediction - Model optimization (Quantization, Distillation) - Hardware accelerators (GPU/TPU) in serving |
| Topic 4: Collaborating within and across teams to manage data and models | - Collaboration between Data Scientists, Data Engineers, and ML Engineers - Version control and reproducibility (e.g., DVC, MLOps) - Data management and governance |
| Topic 5: Monitoring ML solutions | - Performance monitoring and drift detection - Logging and alerting (Cloud Monitoring) - Model retraining strategies |
| Topic 6: Automating and orchestrating ML pipelines | - Vertex AI Pipelines (Kubeflow Pipelines) - CI/CD for ML systems - Triggering and scheduling pipelines |
>> Premium Professional-Machine-Learning-Engineer Files <<
Our company NewPassLeader has been putting emphasis on the development and improvement of our Professional-Machine-Learning-Engineer test prep over ten year without archaic content at all. So we are bravely breaking the stereotype of similar content materials of the Professional-Machine-Learning-Engineer Exam, but add what the exam truly tests into our Professional-Machine-Learning-Engineer exam guide. So we have adamant attitude to offer help rather than perfunctory attitude. It will help you pass your Professional-Machine-Learning-Engineer exam in shortest time.
NEW QUESTION # 394
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: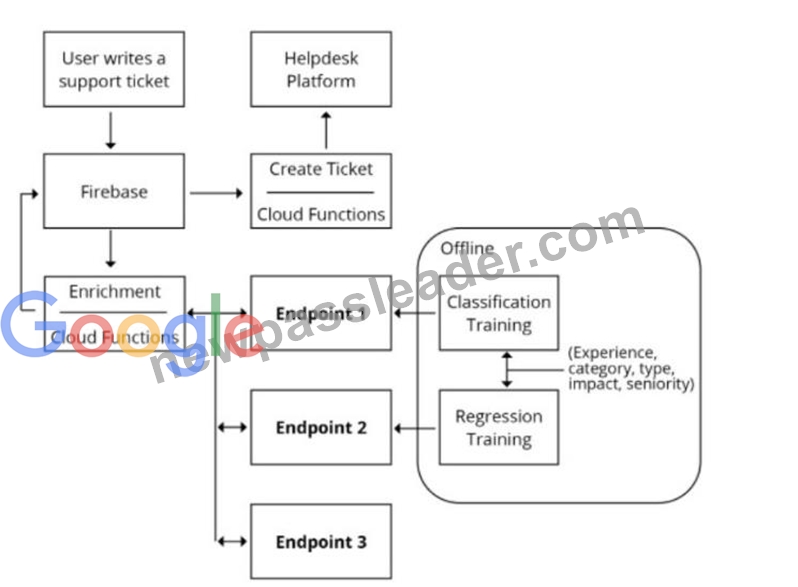
Which endpoints should the Enrichment Cloud Functions call?
Answer: D
Explanation:
https://cloud.google.com/architecture/architecture-of-a-serverless-ml-model#architecture The architecture has the following flow:
A user writes a ticket to Firebase, which triggers a Cloud Function.
-The Cloud Function calls 3 different endpoints to enrich the ticket:
-An AI Platform endpoint, where the function can predict the priority.
-An AI Platform endpoint, where the function can predict the resolution time.
-The Natural Language API to do sentiment analysis and word salience.
-For each reply, the Cloud Function updates the Firebase real-time database.
-The Cloud Function then creates a ticket into the helpdesk platform using the RESTful API.
NEW QUESTION # 395
While performing exploratory data analysis on a dataset, you find that an important categorical feature has 5% null values. You want to minimize the bias that could result from the missing values. How should you handle the missing values?
Answer: D
NEW QUESTION # 396
You work at a subscription-based company. You have trained an ensemble of trees and neural networks to predict customer churn, which is the likelihood that customers will not renew their yearly subscription. The average prediction is a 15% churn rate, but for a particular customer the model predicts that they are 70% likely to churn. The customer has a product usage history of 30%, is located in New York City, and became a customer in 1997. You need to explain the difference between the actual prediction, a 70% churn rate, and the average prediction. You want to use Vertex Explainable AI. What should you do?
Answer: A
Explanation:
* Option A is incorrect because training local surrogate models to explain individual predictions is not a feature of Vertex Explainable AI, but rather a general technique for interpreting black-box models. Local surrogate models are simpler models that approximate the behavior of the original model around a specific input1.
* Option B is correct because configuring sampled Shapley explanations on Vertex Explainable AI is a way to explain the difference between the actual prediction and the average prediction for a given input. Sampled Shapley explanations are based on the Shapley value, which is a game-theoretic concept that measures how much each feature contributes to the prediction2. Vertex Explainable AI supports sampled Shapley explanations for tabular data, such as customer churn3.
* Option C is incorrect because configuring integrated gradients explanations on Vertex Explainable AI is not suitable for explaining the difference between the actual prediction and the average prediction for a given input. Integrated gradients explanations are based on the idea of computing the gradients of the prediction with respect to the input features along a path from a baseline input to the actual input4. Vertex Explainable AI supports integrated gradients explanations for image and text data, but not for tabular data3.
* Option D is incorrect because measuring the effect of each feature as the weight of the feature multiplied by the feature value is not a valid way to explain the difference between the actual prediction and the average prediction for a given input. This method assumes that the model is linear and additive, which is not the case for an ensemble of trees and neural networks. Moreover, this method does not account for the interactions between features or the non-linearity of the model5.
References:
* Local surrogate models
* Shapley value
* Vertex Explainable AI overview
* Integrated gradients
* Feature importance
NEW QUESTION # 397
You were asked to investigate failures of a production line component based on sensor readings. After receiving the dataset, you discover that less than 1% of the readings are positive examples representing failure incidents. You have tried to train several classification models, but none of them converge. How should you resolve the class imbalance problem?
Answer: A
Explanation:
https://developers.google.com/machine-learning/data-prep/construct/sampling-splitting/imbalanced-data#downsampling-and-upweighting
https://developers.google.com/machine-learning/data-prep/construct/sampling-splitting/imbalanced-data
NEW QUESTION # 398
You are an ML engineer at a large retail company. You have a BigQuery table containing five years of daily sales data for 50,000 distinct product SKUs. You need to generate a daily demand forecast for the next 30 days for each individual SKU. The solution must automatically account for holidays and weekly seasonality. You want to minimize data egress costs and operational complexity by keeping the data and model within the data warehouse. What should you do?
Answer: D
Explanation:
BigQuery ML ARIMA_PLUS trains and forecasts directly within BigQuery, avoiding data movement and separate serving infrastructure. By specifying the SKU as the time-series identifier, one model can generate independent 30-day forecasts for all 50,000 products while automatically detecting seasonal patterns and modeling holiday effects.
Reference:
https://docs.cloud.google.com/bigquery/docs/reference/standard-sql/bigqueryml-syntax-create-time-series
https://docs.cloud.google.com/bigquery/docs/arima-multiple-time-series-forecasting-tutorial
https://docs.cloud.google.com/bigquery/docs/time-series-forecasting-holidays-tutorial
NEW QUESTION # 399
......
Take advantage of this golden opportunity, and download our Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) updated exam questions to grab the most prestigious credential in one go. NewPassLeader has formulated the Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam dumps in these three user-friendly formats: Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) Web-Based Practice Test, Desktop Practice Exam Software, and Professional-Machine-Learning-Engineer questions PDF file. You will find the specifications of these formats below to understand them properly.
Professional-Machine-Learning-Engineer Exams Dumps: https://www.newpassleader.com/Google/Professional-Machine-Learning-Engineer-exam-preparation-materials.html
P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by NewPassLeader: https://drive.google.com/open?id=1cJawtREkHoQTCXfTuYGMIXD8DGTELL5O