Free PDF Accurate Databricks - Printable Certified-Data-Engineer-Professional PDF

BONUS!!! Download part of PDF4Test Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1DPVDo0ZeMBU74leVbSm_MxUfCcKZlxlU
Using the Certified-Data-Engineer-Professional Study Materials, you will find that you can grasp the knowledge what you need in the exam in a short time. Because users only need to spend little hours on the Certified-Data-Engineer-Professional study materials, our learning materials will help users to learn all the difficulties of the test site, to help users pass the qualifying examination and obtain the qualification certificate. If you think that time is important to you, try our learning materials and it will save you a lot of time.
| Section | Objectives |
|---|
| Topic 1: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Topic 2: Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 5: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Topic 6: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 7: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Topic 8: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Topic 9: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Topic 10: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Apply Change Data Feed to address streaming table limitations and improve latency
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
>> Printable Certified-Data-Engineer-Professional PDF <<
Real and Updated Certified-Data-Engineer-Professional Exam Questions
Our Certified-Data-Engineer-Professional practice questions are specialized in providing our customers with the most reliable and accurate exam guide and help them pass their exams by achieve their satisfied scores. With our Certified-Data-Engineer-Professional study materials, your exam will be a piece of cake. We have a lasting and sustainable cooperation with customers who are willing to purchase our actual exam. We try our best to renovate and update our Certified-Data-Engineer-Professional learning guide in order to help you fill the knowledge gap during your learning process, thus increasing your confidence and success rate.
Databricks Certified Data Engineer Professional Sample Questions (Q15-Q20):
NEW QUESTION # 15
A workspace admin has created a new catalog called finance_data and wants to delegate permission management to a finance team lead without giving them full admin rights. Which privilege should be granted to the finance team lead?
- A. GRANT OPTION privilege on the finance_data catalog.
- B. ALL PRIVILEGES on the finance_data catalog.
- C. MANAGE privilege on the finance_data catalog.
- D. Make the finance team lead a metastore admin.
Answer: C
Explanation:
The MANAGE privilege in Unity Catalog provides the ability to grant and revoke privileges on the specified object (in this case, a catalog) without giving full administrative access or ownership.
This is the Databricks-recommended approach for delegating governance responsibilities while preserving the principle of least privilege.
By contrast, the ALL PRIVILEGES option grants excessive access (including read and write permissions), and metastore admin status provides global control over all catalogs--far exceeding the requirement. The MANAGE privilege enables the finance team lead to control access to objects within finance_data responsibly while limiting overall administrative exposure.
NEW QUESTION # 16
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
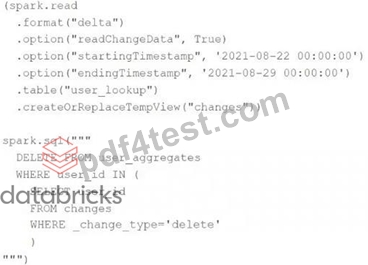
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
- B. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
- C. No; the change data feed only tracks inserts and updates not deleted records.
- D. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
- E. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
Answer: A
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 17
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.
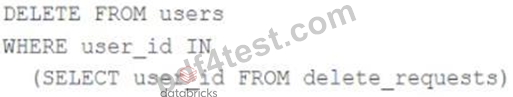
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- B. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- C. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- D. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
- E. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
Answer: D
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
NEW QUESTION # 18
A data engineer is building a streaming data pipeline to ingest JSON files from cloud storage into a Delta Lake table. The pipeline must process files incrementally, handle schema evolution automatically, ensure exactly-once processing, and minimize manual infrastructure management.
How should the data engineer fulfill these requirements?
- A. Use Lakeflow Spark Declarative Pipelines with a static DataFrame read, merge schema with spark.conf.set ("spark.databricks.delta.schema.autoMerge.enabled", "true")
- B. Use traditional Spark Structured Streaming with Auto Loader, manually configuring checkpoints location and enabling schema inference with "mergeSchema"= "true"
- C. Use Lakeflow Spart Declarative Pipelines with Auto Loader and enabling schema inference with
"cloudFiles.schemaEvolutionMode"= "addNewColumns" - D. Use Auto Loader in batch mode with a daily job to overwrite the Delta table.
Answer: C
Explanation:
Lakeflow Spark Declarative Pipelines combined with Auto Loader provide fully managed incremental file ingestion with exactly-once guarantees and minimal operational overhead.
Enabling schema inference and evolution allows new columns in incoming JSON files to be incorporated automatically, satisfying the requirements for streaming ingestion, schema evolution, and reduced manual infrastructure management.
NEW QUESTION # 19
A distributed team of data analysts share computing resources on an interactive cluster with autoscaling configured. In order to better manage costs and query throughput, the workspace administrator is hoping to evaluate whether cluster upscaling is caused by many concurrent users or resource-intensive queries.
In which location can one review the timeline for cluster resizing events?
- A. Driver's log file
- B. Ganglia
- C. Workspace audit logs
- D. Cluster Event Log
- E. Executor's log file
Answer: D
Explanation:
The Cluster Event Log in Databricks will show the timeline for cluster resizing events, including details about when and why a cluster was resized (scaled up or down). This log would help the workspace administrator determine the causes of cluster scaling, whether due to many concurrent users submitting jobs or a few users running resource-intensive queries.
NEW QUESTION # 20
......
Practice tests are also a core part of the PDF4Test product. We recognize that retention of information is crucial, and interactive learning tools, such as practice exams are provided to help students retain the information they have learned. These Certified-Data-Engineer-Professional Practice Tests simulate the actual exam conditions and provide applicants with an accurate assessment of their readiness for the test.
Certified-Data-Engineer-Professional Verified Answers: https://www.pdf4test.com/Certified-Data-Engineer-Professional-dump-torrent.html
- Databricks Printable Certified-Data-Engineer-Professional PDF: Databricks Certified Data Engineer Professional - www.testkingpass.com Official Pass Certify 🎎 Search for ⇛ Certified-Data-Engineer-Professional ⇚ on 「 www.testkingpass.com 」 immediately to obtain a free download 🍨Certified-Data-Engineer-Professional Cert Exam
- Elevate Your Preparation By Using Databricks Certified-Data-Engineer-Professional Exam Questions ❣ 「 www.pdfvce.com 」 is best website to obtain “ Certified-Data-Engineer-Professional ” for free download 📜Valid Certified-Data-Engineer-Professional Exam Questions
- Exam Certified-Data-Engineer-Professional Guide 🈺 Real Certified-Data-Engineer-Professional Dumps 🗽 Relevant Certified-Data-Engineer-Professional Answers 😗 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and download exam materials for free through ➽ www.prep4away.com 🢪 🦱Certified-Data-Engineer-Professional Valid Study Materials
- Elevate Your Preparation By Using Databricks Certified-Data-Engineer-Professional Exam Questions ☢ Search for “ Certified-Data-Engineer-Professional ” and download exam materials for free through “ www.pdfvce.com ” 🪓Valid Certified-Data-Engineer-Professional Exam Questions
- Perfect Printable Certified-Data-Engineer-Professional PDF | 100% Free Certified-Data-Engineer-Professional Verified Answers 🚂 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download it for free on ➤ www.dumpsmaterials.com ⮘ website 🦼Valid Certified-Data-Engineer-Professional Exam Questions
- Databricks Printable Certified-Data-Engineer-Professional PDF: Databricks Certified Data Engineer Professional - Pdfvce Official Pass Certify 🐺 Simply search for “ Certified-Data-Engineer-Professional ” for free download on [ www.pdfvce.com ] 🎈Certified-Data-Engineer-Professional Real Braindumps
- Certified-Data-Engineer-Professional Real Braindumps 😤 Relevant Certified-Data-Engineer-Professional Answers 🥣 Certified-Data-Engineer-Professional Free Dumps 📁 Search for “ Certified-Data-Engineer-Professional ” and download exam materials for free through ✔ www.vce4dumps.com ️✔️ 😾Certified-Data-Engineer-Professional Real Braindumps
- Valid Certified-Data-Engineer-Professional Exam Objectives 🧝 Certified-Data-Engineer-Professional Latest Exam Cost 🩺 Relevant Certified-Data-Engineer-Professional Answers ✉ Search for ⇛ Certified-Data-Engineer-Professional ⇚ and download exam materials for free through ⇛ www.pdfvce.com ⇚ 🔤Certified-Data-Engineer-Professional Latest Exam Cost
- Valid Exam Certified-Data-Engineer-Professional Registration ✅ Certified-Data-Engineer-Professional Cert Exam 🔍 Popular Certified-Data-Engineer-Professional Exams 🙎 Open ⏩ www.torrentvce.com ⏪ and search for { Certified-Data-Engineer-Professional } to download exam materials for free 🏛Printable Certified-Data-Engineer-Professional PDF
- Printable Certified-Data-Engineer-Professional PDF 📫 Certified-Data-Engineer-Professional Cert Exam 🖋 Certified-Data-Engineer-Professional Real Braindumps 🍠 Search for ▶ Certified-Data-Engineer-Professional ◀ and easily obtain a free download on ▷ www.pdfvce.com ◁ 🗨Exam Certified-Data-Engineer-Professional Guide
- Databricks Printable Certified-Data-Engineer-Professional PDF: Databricks Certified Data Engineer Professional - www.validtorrent.com Official Pass Certify 🏚 Open ▶ www.validtorrent.com ◀ and search for ▷ Certified-Data-Engineer-Professional ◁ to download exam materials for free 😹Relevant Certified-Data-Engineer-Professional Answers
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
DOWNLOAD the newest PDF4Test Certified-Data-Engineer-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1DPVDo0ZeMBU74leVbSm_MxUfCcKZlxlU