Microsoftお客様との持続可能な関係に高い価値を置いているため、AI-300準備ガイドのヘルプの下で最高の証明書学習体験をお楽しみいただけます。まず、5〜10分でお支払いが完了すると、短納期で、オンラインでAI-300ガイドトレントをお送りします。加えて、当社のAI-300試験トレントの使用中に技術的および運用上の問題に対処するのに問題がある場合は、すぐにご連絡ください。24時間のオンラインサービスは、Operationalizing Machine Learning and Generative AI Solutions問題をすぐに解決するための努力です。
| Section | Objectives |
|---|---|
| Implement secure and scalable AI systems | - Security and governance
|
| Design and implement generative AI solutions | - Large language model integration
|
| Operationalizing machine learning solutions | - ML lifecycle management
|
| Plan and design AI solutions using Azure AI services | - Requirements gathering and solution architecture
|
ここで説明したいのはCertJukenにあるコアバリューです。全てのMicrosoftのAI-300「Operationalizing Machine Learning and Generative AI Solutions」試験は非常に大切ですが、この情報技術が急速に発展している時代に、CertJukenはただその中の一つだけです。ではなぜほとんどの人々はCertJukenを選んだのですか。それはCertJukenが提供する問題資料は絶対あなたが試験に受かることを助けられるからです。CertJukenが提供する資料は最新のトレーニングツールが常にアップデートして認証試験の目標を変換するの結果です。CertJuken はあなたに最新の試験研究資料を提供しますから、CertJuken MicrosoftのAI-300問題集を持っていたら、試験に直面する自信に満ちることができ、合格しないなんて全然心配することはなく気楽に試験に受かることができます。
質問 # 180
A team is validating a generative AI assistant for a company. The assistant generates responses by using internal knowledge sources.
The company requires assurance that responses are accurate, supported by sources, and related to the user prompts before enabling production access.
You need to implement quality metrics that confirm the assistant produces reliable and meaningful responses.
Which two evaluation metrics should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:B、D
解説:
To ensure your Azure Machine Learning generative AI assistant (which utilizes a Retrieval- Augmented Generation or RAG architecture) produces reliable and meaningful responses before going live, you should use the RAG Triad of built-in quality evaluation metrics.
These primary automated metrics-Groundedness, Relevance, and Response Completeness- directly measure accuracy, connection to internal knowledge sources, and alignment with user prompts.
The Primary Metrics (The RAG Triad)
These metrics are evaluated on a 1-to-5 scale using Azure Machine Learning's built-in, AI- assisted "LLM-as-a-judge" evaluators:
Groundedness: Measures how well the assistant's generated answer aligns only with the information retrieved from your internal knowledge sources. Even if a response is factually correct in the real world, it is penalized if the information cannot be verified inside the retrieved context document. This is your primary defense against hallucinations.
Relevance: Assesses how pertinently the model's generated response directly addresses the user's specific prompt. This checks whether the system understood the user's intent or if it provided an off-topic or distracted response.
Response Completeness: Focuses on the "recall" aspect of the assistant. It measures whether the generated text effectively answers all parts of the user prompt using the ground truth data, ensuring no critical insights or data points are omitted.
Reference:
https://medium.com/thedeephub/a-deep-dive-into-evaluation-in-azure-prompt-flow-dd898ebb158c
質問 # 181
Hotspot Question
You manage a Retrieval-Augmented Generation (RAG) system that retrieves internal policy documents from a vector index.
Recent analysis shows that:
- Retrieved results frequently include duplicated content from the same document.
- Retrieved chunks sometimes span unrelated policy sections.
You review the following retrieval and ingestion configurations: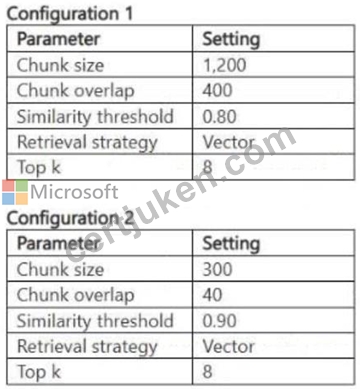
You need to reduce duplicated retrieval results and improve chunk relevance across policy sections. For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.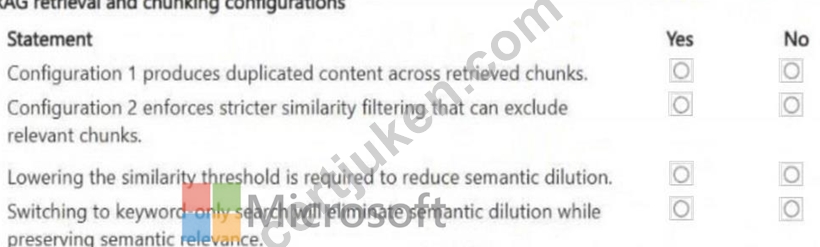
正解:
解説: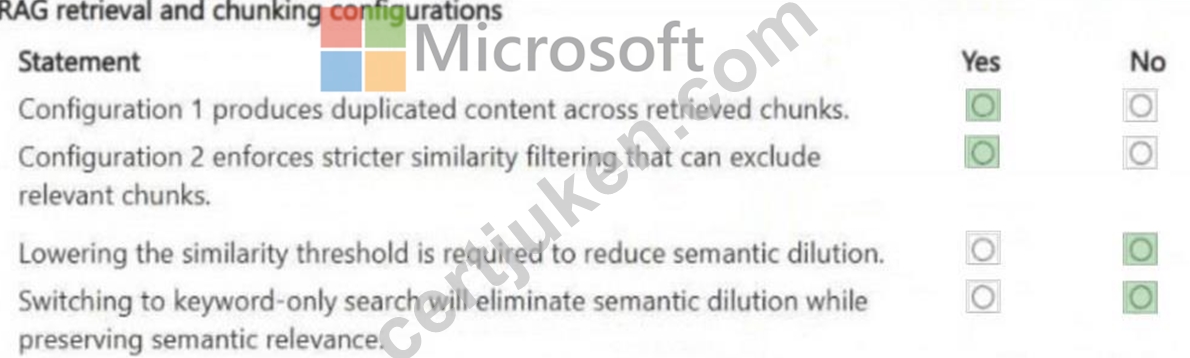
質問 # 182
A team develops multiple AI applications in Microsoft Foundry that rely on shared prompt templates.
The team requires a centralized way to track, version, and reuse prompt content across projects.
You need to recommend a solution to track and reuse prompt content.
Which approach should you recommend?
正解:D
解説:
A Git repository provides all three capabilities required: version history for every change with author attribution and timestamp, branching for experimentation, tagging for stable releases, and a single source of truth accessible to all projects via clone or submodule reference. Azure ML datasets (option B) are designed for training data, not text configuration artifacts, and lack per-line diff tracking and review workflows.
Embedding prompts in application configuration files (option C) scatters prompt content across multiple applications with no unified view, no shared versioning, and no cross-project reuse. Unstructured Blob Storage with folder organization (option D) provides no version history, no diff tracking, no review workflow, and no native tooling for comparing prompt variants. Git is the definitive answer for centralized tracking, versioning, and reuse of prompt content across Microsoft Foundry projects.
Microsoft Learn Reference Topic: Prompt engineering and version control - Managing prompts in AI applications with Git
質問 # 183
A data science team completes multiple training runs within an experiment by using MLflow.
The team wants to store a selected model in Azure Machine Learning so that it can be versioned and deployed later.
The model must be versioned centrally for reuse across environments.
You need to version the trained model.
Which two actions should you perform? Each correct answer presents part of the solution.
Choose two.
NOTE: Each correct selection is worth one point.
正解:B、D
解説:
To set up versioning for a trained model in an Azure Machine Learning (Azure ML) workspace using MLflow, you must capture the model artifacts during the training run and then register the model into the centralized registry.
[A]
1. Capture Model Artifacts
During each training run, use the MLflow SDK to log the model. This ensures that all necessary files (the model binary, environment dependencies, and the MLmodel metadata) are stored as run outputs in the workspace.
Manual Logging: Use a flavor-specific method like mlflow.sklearn.log_model(model,
"model_path") within an active run.
Automatic Logging: Call mlflow.autolog() before starting your training. This automatically captures metrics, parameters, and the model artifacts for supported frameworks.
Artifact Location: Once logged, artifacts are typically found in the outputs/ folder of the specific run, accessible via the Azure Machine Learning Studio.
[B]
2. Register the Model
After identifying the best-performing run, you register it to the Model Registry. This creates a named, versioned entity that can be accessed across different environments for deployment.
To set up versioning for an MLflow model in Azure Machine Learning (Azure ML) that is accessible across different environments, you should use a centralized Azure ML Registry. While a standard Azure ML Workspace acts as an MLflow server for individual experiments, an Azure ML Registry is the specifically designed feature for sharing models, environments, and components across multiple workspaces and environments within an Azure tenant.
3. Centralized Reuse
By registering the model in the workspace's registry, you establish a single source of truth. You can then load this specific version in any environment (e.g., staging or production) using its registry URI: models:/<model_name>/<version_or_alias>.
Incorrect:
[Not D]
Must use an Azure ML Registry (Central).
Reference:
https://mlflow.org/docs/latest/ml/model-registry/
質問 # 184
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to recommend an experiment-tracking strategy that ensures consistent experiment results. What should you recommend?
正解:D
解説:
Scenario:
The current challenges faced by the data science team include the following: Experiment tracking is inconsistent To support the business goals, Fabrikam Inc. identifies these technical requirements: Implement experiment tracking and model versioning for all training jobs.
In Azure-based AI operations, integrating MLflow with Azure Machine Learning (Azure ML) provides a unified interface to track experiments, version models, and manage the lifecycle of both traditional ML and Generative AI workloads.
Direct Implementation Strategy
To ensure consistent experiment results and comparison of prompt strategies versus fine-tuned models, use the following architectural approach:
Centralized Tracking: Configure the MLflow tracking URI to point to your Azure ML Workspace.
This allows all logs (from local notebooks, remote training jobs, or Prompt Flow) to aggregate in a single "Experiments" dashboard.
Prompt Strategy Comparison: Use Azure ML Prompt Flow to develop and test prompt variants.
Prompt Flow automatically logs metrics (like groundedness and relevance) which can be viewed alongside fine-tuned model metrics in the Azure ML Studio.
Model Versioning: Use the MLflow Model Registry hosted within Azure ML. Each successful training or fine-tuning run should be registered as a new version of a named model, providing a clear lineage from data to deployment.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-mlflow-cli-runs
質問 # 185
......
ほとんどの人は勉強中にコンピューターを使用することを好むかもしれませんが、Microsoftコンピューターで勉強することは目に害を及ぼすと考えているため、多くの人が紙の購入を学びたいと認めている必要があります。CertJuken AI-300テスト問題には、顧客のニーズを満たすために印刷をサポートする機能があります。 正常にダウンロードしたら、AI-300試験問題をOperationalizing Machine Learning and Generative AI Solutions論文に印刷できます。 目を保護するだけでなく、メモをとるのに非常に便利です。 AI-300試験準備を気に入っていただけると信じています。
AI-300ファンデーション: https://www.certjuken.com/AI-300-exam.html