P.S. Free & New AI-200 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=1_NxYZL9MNdIrIYPV1KNcvGn0aTg1vpox
If you are preparing for AI-200 exam and upset without accurate exam torrent and practice materials, Prep4King guarantees you to pass exam at first attempt absolutely. Our AI-200 exam torrent is edited by latest official examination knowledge. Once official department change questions we will release new version of AI-200 Exam Torrent accordingly. We provide one year free update and service warranty for all products. You will have sufficient time to take part in exams.
| Section | Weight | Objectives |
|---|---|---|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
All these three Prep4King Developing AI Cloud Solutions on Azure (AI-200) exam questions formats are easy to use and perfectly work with all devices, operating systems, and the latest web browsers. So rest assured that with the Prep4King AI-200 Exam Dumps you will get everything that you need to learn, prepare and pass the challenging Developing AI Cloud Solutions on Azure (AI-200) exam with good scores.
NEW QUESTION # 85
You are investigating high latency in an AI search application that processes millions of requests daily.
Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
* Include only data from the last 24 hours.
* Filter for failed requests only.
* Calculate the average duration of dependencies, grouped by operation.
The query must follow best practice to optimize the performance by minimizing the initial data scan.
You need to create the query.
In which order should perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.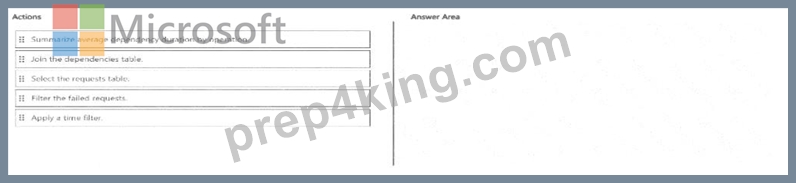
Answer:
Explanation: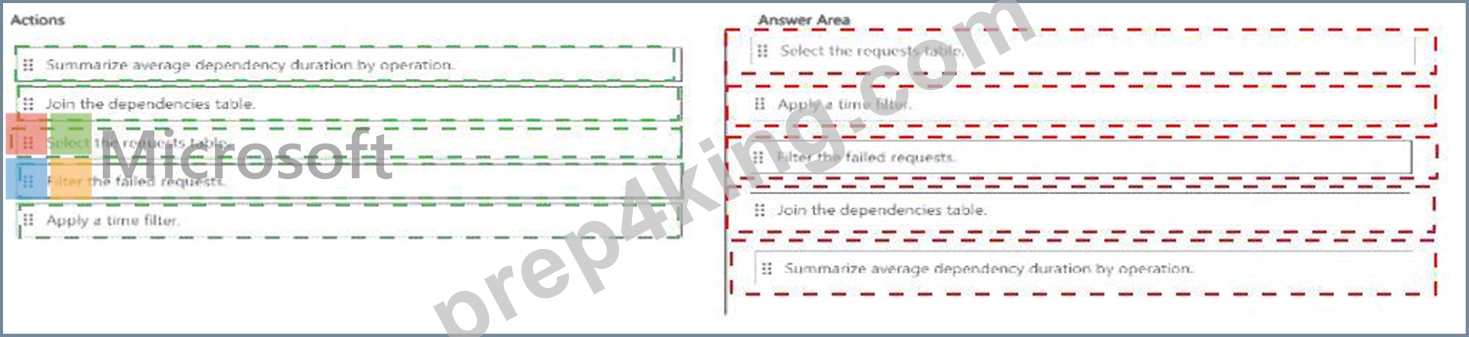
Explanation: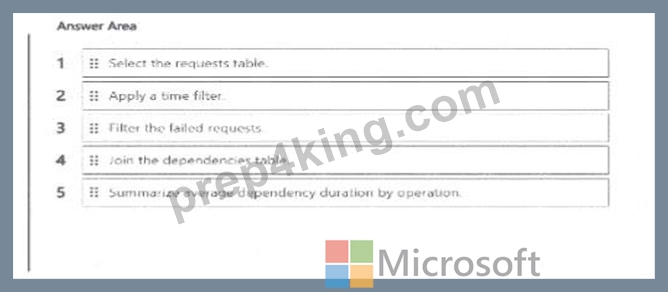
Verified answer: 1) Select the requests table; 2) apply the 24-hour time filter; 3) filter failed requests; 4) join the dependencies table; 5) summarize average dependency duration by operation.
Detailed Explanation: KQL performs best when high-selectivity filters are applied as early as possible, especially the time predicate that limits the amount of data scanned. Starting from AppRequests, restricting to the last 24 hours, and then filtering failures reduces the left-side dataset before the join. The dependency table is then correlated with those requests, and aggregation is performed last to calculate average dependency duration by operation. Joining or summarizing before the time and failure filters would process more data than necessary.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Optimize log queries in Azure Monitor
NEW QUESTION # 86
You are developing a .NET application that uses Azure Cosmos DB for NoSQL to store application data The application uses the Azure Cosmos DB for NoSQL SDK to interact with the database account. The application must perform the following tasks
* Initialize the connection by using the account endpoint and key.
* Define shared throughput.
* Perform create, read, update, and delete (CRUD) operations on items stored in a container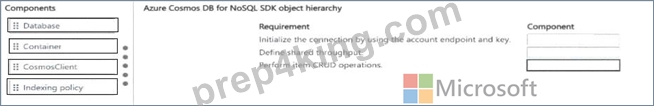
Answer:
Explanation: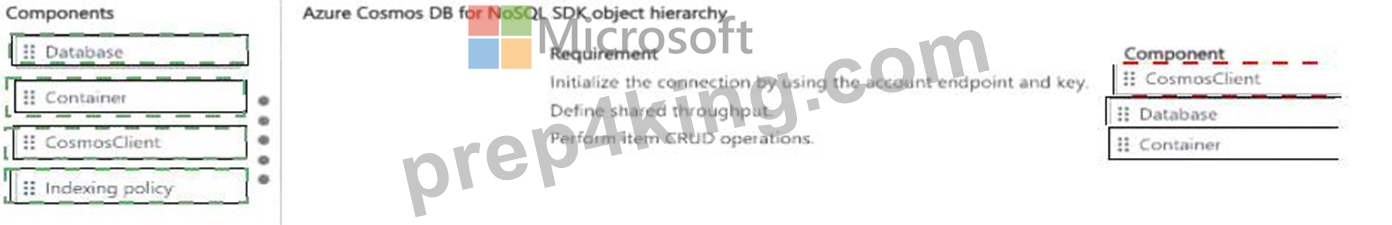
Explanation: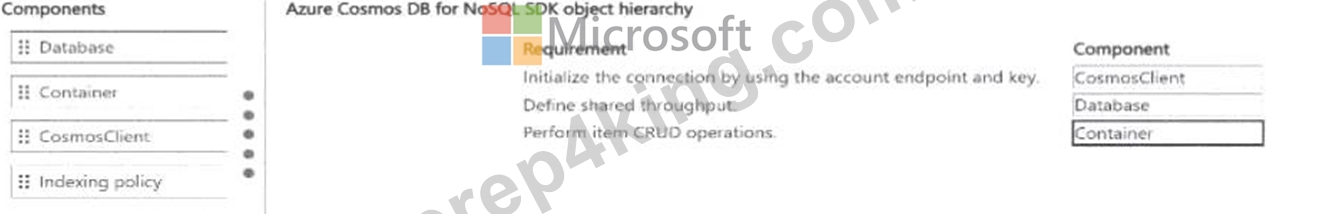
Verified Answer: Initialize connection: CosmosClient. Define shared throughput: Database. Perform item CRUD: Container.
Detailed Explanation: The Cosmos DB SDK follows the service resource hierarchy. CosmosClient represents the account connection and is initialized with the account endpoint and credential. Shared throughput is configured at the database level when multiple containers share database throughput. Item create, read, update, and delete operations are performed through a container object because containers hold items and define partitioning/indexing behavior. An indexing policy is configuration attached to a container, not the SDK object used for CRUD.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Cosmos DB databases, containers, and items
NEW QUESTION # 87
You need to implement trace correlation according to the business requirements.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you se lect.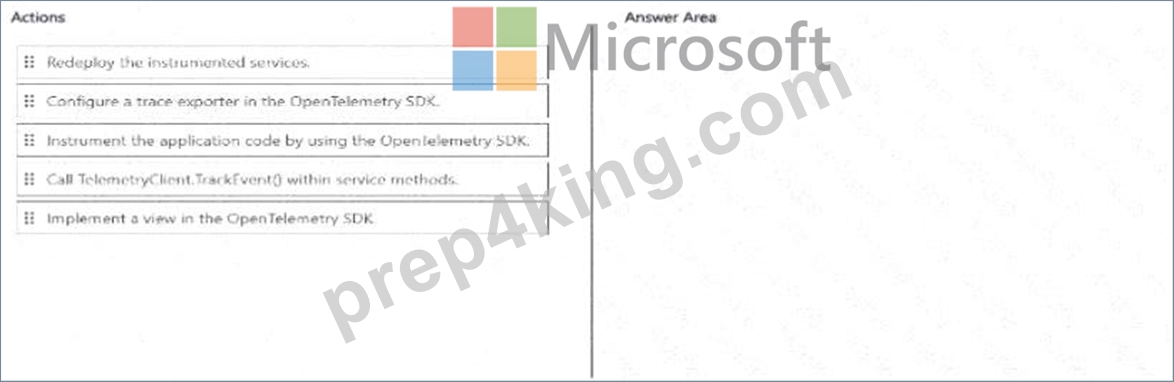
Answer:
Explanation: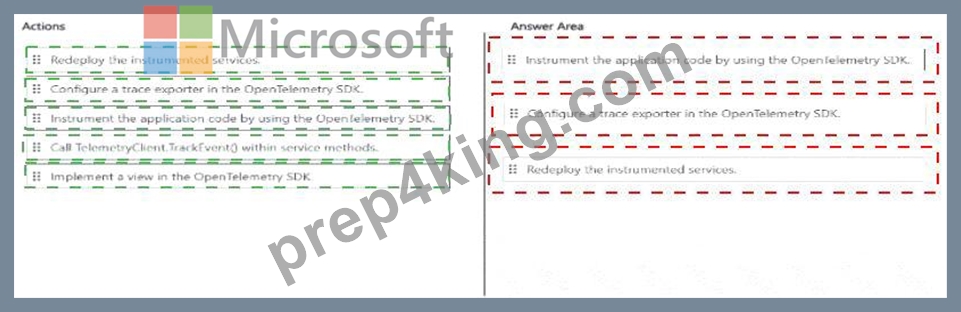
Explanation: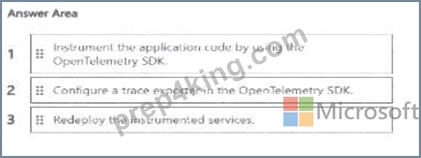
Verified answer: 1) Instrument the application code with the OpenTelemetry SDK; 2) configure an Azure Monitor trace exporter in the OpenTelemetry SDK; 3) redeploy the instrumented services.
Detailed Explanation: Trace correlation requires the application to create OpenTelemetry spans and an exporter to send those spans to Azure Monitor. Instrumentation must therefore be present before the updated service is deployed. The previous Application Insights SDK instrumentation does not satisfy the case-study requirement that all tracing use OpenTelemetry. Configuring an OpenTelemetry view is unrelated to basic distributed-trace export, and calling TrackEvent is an Application Insights SDK pattern rather than the required OpenTelemetry approach.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 88
Drag and Drop Question
A Python API retrieves a document from Azure Database for PostgreSQL by using a SQL statement. The API accepts the document ID from user input. The current implementation inserts the document ID directly into the SQL statement.
You need to secure the SQL statement execution by minimizing the possibility of SQL injection.
How should you modify the current implementation? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.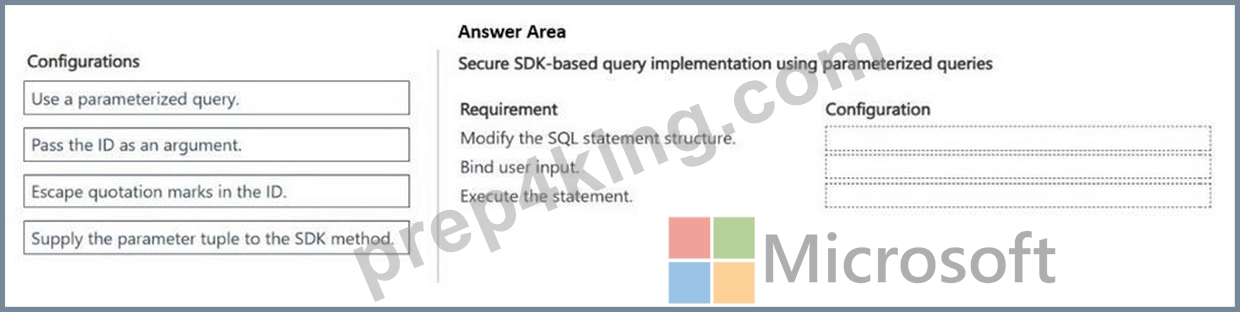
Answer:
Explanation: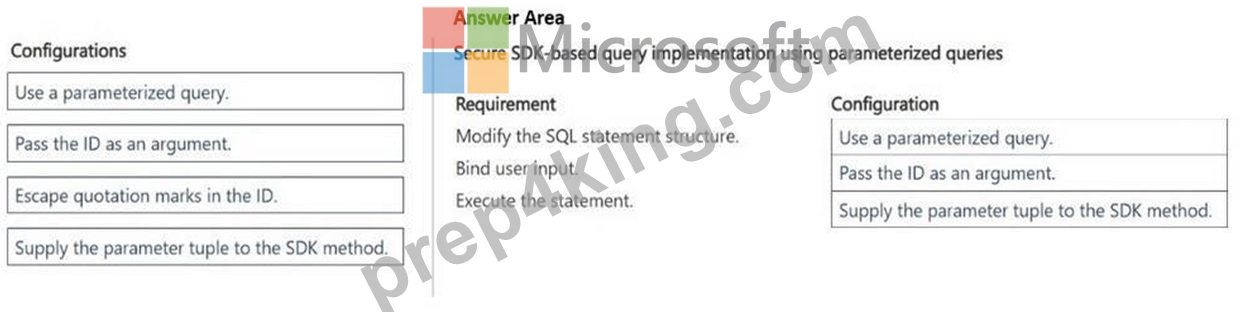
Explanation:
Box 1: Use a parameterized query
To secure your SQL statement against SQL injection, you must replace direct string insertion with parameterized queries (also known as prepared statements).
Box 2: Pass the ID as an argument
The current implementation inserts the document ID directly into the SQL statement.
Box 3: Supply the parameter tuple to the SDK method
Supply parameter tuples: Pass the user input as a separate tuple or list argument into your database driver's execution method (e.g., cursor.execute(query, (document_id,))).
Reference:
https://www.stackhawk.com/blog/finding-and-fixing-sql-injection-vulnerabilities-in-flask-python/
NEW QUESTION # 89
You need to configure vector embedding updates according to the business and technical requirements.
Which information should you use? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.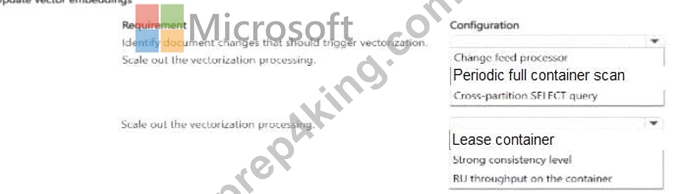
Answer:
Explanation: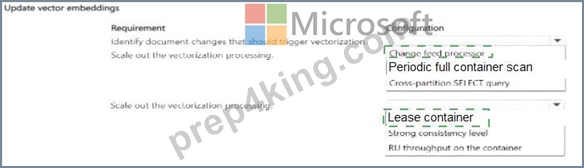
Explanation: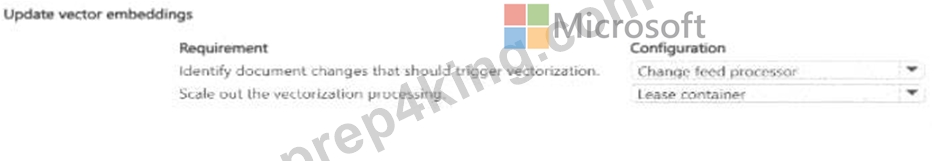
Verified Answer: Identify document changes: Change feed processor. Scale out vectorization processing:
Lease container.
Detailed Explanation: The change feed processor is designed to react to inserts and updates in a monitored Cosmos DB container, which directly matches the requirement to generate embeddings for new or changed documents. Its lease container stores processing state and coordinates work across multiple workers, allowing the processing workload to scale out without duplicating ownership of change-feed ranges. A periodic full scan would consume unnecessary RUs, and neither strong consistency nor container RU throughput is the coordination mechanism for distributed change-feed workers.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Cosmos DB change feed processor
NEW QUESTION # 90
......
It is known to us that the AI-200 exam has been increasingly significant for modern people in this highly competitive word, because the AI-200 test certification can certify whether you have the competitive advantage in the global labor market or have the ability to handle the job in a certain area, especial when we enter into a newly computer era. Therefore our AI-200 practice torrent is tailor-designed for these learning groups, thus helping them pass the AI-200 exam in a more productive and efficient way and achieve success in their workplace.
AI-200 Latest Exam Camp: https://www.prep4king.com/AI-200-exam-prep-material.html
BONUS!!! Download part of Prep4King AI-200 dumps for free: https://drive.google.com/open?id=1_NxYZL9MNdIrIYPV1KNcvGn0aTg1vpox