2026年Fast2testの最新DAA-C01 PDFダンプおよびDAA-C01試験エンジンの無料共有:https://drive.google.com/open?id=1peaeO45M5ImfolIkrKvZUj5EJ9RQETft
どのようにして短時間で試験に合格し、証明書を取得できますか? DAA-C01試験トレントは、目標を達成するための最良の選択です。お客様のニーズに応じて、当社の製品は多くの専門家によって改訂されました。 DAA-C01試験問題集のほとんどの機能は、お客様がより多くの時間を節約し、お客様をリラックスさせるのに役立ちます。 DAA-C01テストクイズを使用することを選択した場合、短時間でDAA-C01試験に合格することは非常に簡単です。 DAA-C01試験問題の勉強に20〜30時間費やすだけです。他のことをする自由時間が増えます。
| Section | Weight | Objectives |
|---|---|---|
| Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
| Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs) - Scalar, aggregate, table, system functions |
| Build and Troubleshoot Advanced SQL Queries | 20–25% | - Semi-structured data processing - Complex joins, subqueries, window functions - Query optimization and troubleshooting |
| Perform Descriptive and Diagnostic Analysis | 10–15% | - Anomaly detection and root cause analysis - Exploratory and ad-hoc analysis - Statistical summarization and trend analysis |
| Prepare and Present Data | 10–15% | - Align outputs with business requirements - Snowsight dashboards and sharing results - Data visualization and reporting |
| Prepare and Load Data | 15–20% | - Data ingestion methods: COPY INTO, stages, Snowpipe - File formats: CSV, JSON, Parquet, Avro - External tables and data validation |
| Perform Simple Data Transformations for Analysis | 15–20% | - Views, materialized views, CTEs - Data cleansing, standardization, type conversion - Handling NULLs and structuring datasets |
すべての人が当社Fast2testのDAA-C01学習教材を使用することは非常に便利です。私たちの学習教材は、多くの人々が私たちの製品を購入した場合、多くの問題を解決するのに役立ちます。当社のDAA-C01学習教材のオンライン版は機器に限定されません。つまり、学習教材を電話、コンピューターなどを含むすべての電子機器に適用できます。そのため、当社のオンライン版DAA-C01学習教材は、試験の準備に非常に役立ちます。私たちは、DAA-C01学習教材が良い選択になると信じています。
質問 # 19
A data analyst is investigating a decline in the conversion rate on an e-commerce website. They have access to the following tables in Snowflake: 'sessions': 'session id', 'user id', 'start time', 'end_time' 'page views': 'session id', 'page_urr, 'view time' 'transactions': 'session_id', 'transaction id', 'amount', 'transaction_time' Which of the following approaches, using Snowflake features, would be MOST effective for identifying potential bottlenecks or drop-off points in the user journey?
正解:A、B
解説:
Options B and C provide useful diagnostic insights. B offers direct information about conversion at each stage of the funnel. Option C enables discovery of unusual drops over time. Option A might be a difficult, resource intensive solution for complex user journeys. Option D is a poor approach as it identifies the rate of change in tables instead of the main objective - bottlenecks or drop-off points. Option E, while helpful for data governance, doesn't directly pinpoint user journey issues.
質問 # 20
You need to load data from a set of CSV files located in an AWS S3 bucket into a Snowflake table called 'SALES DATA. The CSV files have a header row, and you want to automatically detect the data types of the columns. However, some files might have inconsistent data types (e.g., a column that is usually an integer might occasionally contain a string). Furthermore the file are compressed using GZIP. Which of the following COPY INTO command options can you use to achieve this goal while handling potential data type mismatches?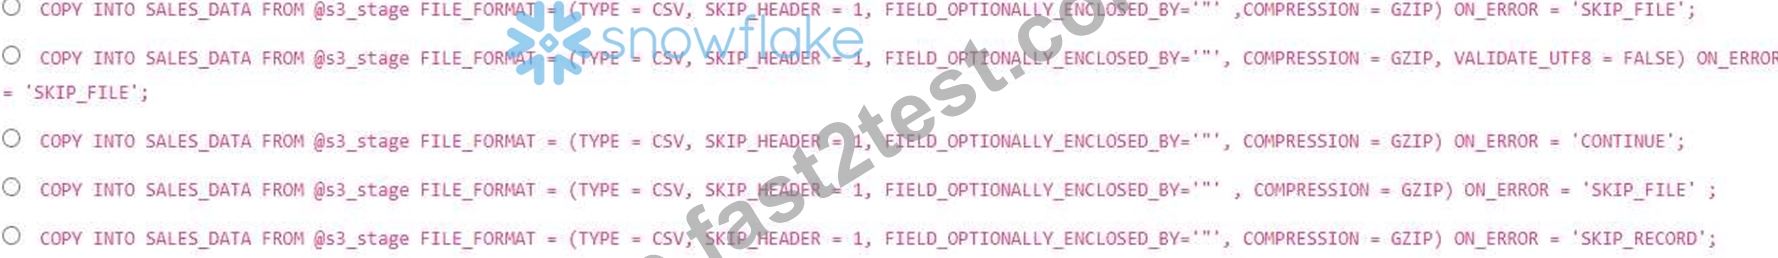
正解:B
解説:
The 'ON_ERROR = 'SKIP_RECORD" option allows the COPY INTO command to skip individual records that have data type mismatches or other errors during the load process. This ensures that the load process continues even if some records fail validation. 'SKIP_FILE' would skip entire file, 'CONTINUE' will only continue the process with the given data, and 'SKIP_FILE' skips the file. The VALIDATE UTF8 isn't directly relevant to data type issues
質問 # 21
When optimizing query performance in Snowflake, what benefits does result caching provide?
正解:C
解説:
Result caching accelerates query execution by storing intermediate results, reducing processing time for repetitive or commonly accessed queries.
質問 # 22
A data analyst is experiencing slow query performance when joining two large tables, 'SALES' (1 billion rows) and 'CUSTOMERS' (10 million rows), on 'CUSTOMER ID. The 'SALES' table is frequently updated. The following query is used: SELECT s. , c. FROM SALES s JOIN CUSTOMERS c ON s.CUSTOMER_lD = c.CUSTOMER_lD WHERE s.SALE_DATE DATEADD(day, -30, CURRENT DATE()); Which of the following strategies would MOST effectively improve the query performance, assuming you have appropriate privileges to alter objects and cost is a concern?
正解:E
解説:
Creating 'SALES LAST 30 DAYS' table and joining is the most effective strategy because it reduces the size of the SALES table significantly before the join operation. Materialized views (A) are generally effective, but the high update frequency of the SALES table could lead to significant overhead in materialized view maintenance. Standard indexes (B) are not supported in Snowflake. Search optimization (C) may not be suitable as the could have high cardinality. Clustering (D) could improve performance, but the benefits might not outweigh the cost of reclustering after frequent data loading, and it does not limit the initial size of the join.
質問 # 23
While loading data into Snowflake using named file formats, a file format defined in which location has precedence?
正解:D
解説:
In the Snowflake data loading hierarchy, understanding the order of precedence for file format options is critical for troubleshooting and automation. Snowflake allows you to define file format options (such as CSV delimiter, header settings, or compression type) at multiple levels: as a standalone named File Format object, within a Stage definition, or directly inside a COPY INTO statement.
When data is loaded, Snowflake evaluates these definitions based on a specific override logic. The COPY INTO statement sits at the top of this hierarchy. This means that any file format options or named file formats explicitly called out in the COPY INTO command will override any conflicting settings defined at the stage or table level. For example, if a stage is defined to expect comma-separated files, but the COPY INTO command specifies a pipe delimiter, Snowflake will use the pipe delimiter for that specific load operation.
Evaluating the Options:
* Options A, B, and C are incorrect because while they provide default behaviors for specific objects or namespaces, they are considered "lower-level" configurations.
* Option D is the 100% correct answer. The COPY INTO statement provides the final, explicit instruction to the query engine. This design allows Data Analysts to use general-purpose stages for various file types by simply specifying the unique format requirements at the time of the execution, providing maximum flexibility in the Data Ingestion workflow.
質問 # 24
......
DAA-C01試験のブレーンダンプは、より大きな会社に注目させる能力を証明できます。 DAA-C01試験ガイドは、良い仕事を得るのに役立ちます。 DAA-C01のテスト準備は、ごく短時間で完全かつ効率的に自分自身を証明するのに役立ちます。 何万人ものお客様が、DAA-C01試験の質問で20〜30時間勉強すれば、DAA-C01試験に合格し、それに応じて資格を取得できることを証明しました。
DAA-C01参考書勉強: https://jp.fast2test.com/DAA-C01-premium-file.html
2026年Fast2testの最新DAA-C01 PDFダンプおよびDAA-C01試験エンジンの無料共有:https://drive.google.com/open?id=1peaeO45M5ImfolIkrKvZUj5EJ9RQETft