Valid Databricks-Certified-Data-Engineer-Professional Test Preparation - Valid Databricks-Certified-Data-Engineer-Professional Study Guide
We know deeply that a reliable Databricks-Certified-Data-Engineer-Professional exam material is our company's foothold in this competitive market. High accuracy and high quality are the most important things we always looking for. Compared with the other products in the market, our Databricks-Certified-Data-Engineer-Professional latest questions grasp of the core knowledge and key point of the real exam, the targeted and efficient Databricks Certified Data Engineer Professional Exam study training dumps guarantee our candidates to pass the test easily. Passing exam won’t be a problem anymore as long as you are familiar with our Databricks-Certified-Data-Engineer-Professional Exam Material (only about 20 to 30 hours practice). High accuracy and high quality are the reasons why you should choose us.
| Section | Weight | Objectives |
|---|
| Cost & Performance Optimisation | 13% | - Optimize compute and storage resources
- Apply cost management best practices
- Improve query and pipeline performance
|
| Debugging and Deploying | 10% | - Troubleshoot and debug pipelines
- Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
|
| Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads
- Use Auto Loader and structured streaming
- Ingest data from diverse sources
|
| Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards
- Apply data cleansing and validation rules
- Implement schema evolution and management
|
| Developing Code for Data Processing using Python and SQL | 22% | - Use Databricks-specific libraries and APIs
- Write efficient and maintainable code
- Implement complex data processing logic
|
| Monitoring and Alerting | 10% | - Track data lineage and metrics
- Monitor pipeline performance and health
- Set up alerts and notifications
|
| Data Modelling | 6% | - Optimize table design and partitioning
- Implement dimensional and relational models
- Design Medallion Architecture
|
| Data Governance | 7% | - Use Unity Catalog for governance
- Manage data assets and metadata
- Enforce data policies and standards
|
| Ensuring Data Security and Compliance | 10% | - Secure data at rest and in transit
- Ensure data privacy and compliance
- Implement access control and permissions
|
| Data Sharing and Federation | 5% | - Manage cross-platform data access
- Implement Lakehouse Federation
- Use Delta Sharing for secure data sharing
|
>> Valid Databricks-Certified-Data-Engineer-Professional Test Preparation <<
Valid Databricks-Certified-Data-Engineer-Professional Study Guide - Latest Databricks-Certified-Data-Engineer-Professional Exam Vce
What do you know about DumpTorrent? Have you ever used DumpTorrent exam dumps or heard DumpTorrent dumps from the people around you? As professional exam material providers in Databricks certification exam, DumpTorrent is certain the best website you've seen. Why am I so sure? No website like DumpTorrent can not only provide you with the Best Databricks-Certified-Data-Engineer-Professional Practice test materials to pass the test, also can provide you with the most quality services to let you 100% satisfaction.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q32-Q37):
NEW QUESTION # 32
The data engineering team maintains the following code:
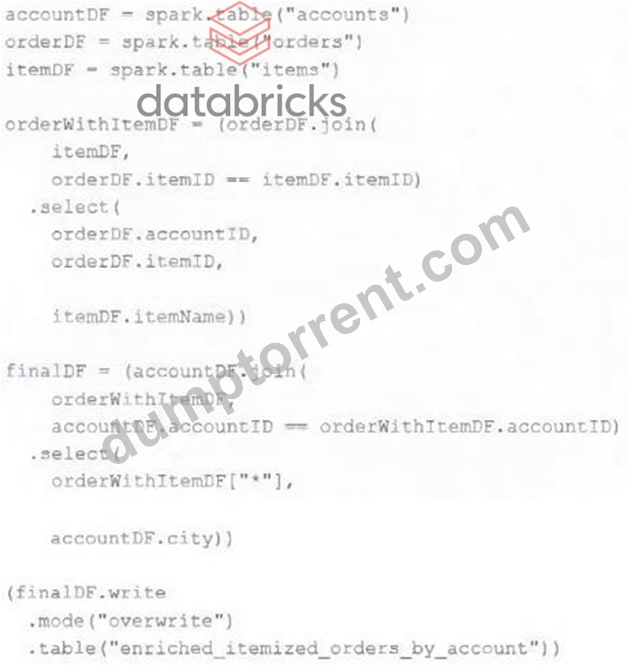
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- B. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- C. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- D. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- E. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
Answer: C
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 33
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Use apply_changes without CDF and filter rows where _soft_deleted is true.
- B. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
- C. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
- D. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
Answer: C
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 34
A data engineering workspace was automatically enabled for Unity Catalog, creating a workspace catalog. New team members report they can create tables in the default schema but cannot access table in other schemas within the same workspace catalog. Why are the new team members unable to access tables in other schemas?
- A. Workspace catalog permissions are not subject to inheritance rules.
- B. Tables in other schemas require additional BROWSEprivileges that new users don't receive automatically
- C. Workspace users receive USE CATALOG and specific privileges on default schema only.
- D. New users only receive CREATE TABLE privileges on the default schema.
Answer: C
Explanation:
When a workspace catalog is automatically created, new users are granted USE CATALOG and limited privileges on the default schema only. Access to other schemas requires explicit grants, so users cannot see or query tables in those schemas without additional permissions.
NEW QUESTION # 35
A data engineer is using the AUTO CDC API in Lakeflow Spark Declarative Pipeline to propagate deletions from a source table (orders_source) to a target table (orders_target). The source has Change Data Feed (CDF) enabled, but some delete events arrive out of order due to upstream delays. How does the AUTO CDC API internally ensure deletions are applied correctly despite out-of-order events?
- A. It ignores deletions if they arrive after updates for the same key.
- B. It uses sequence_by to order events and retains tombstones for deleted rows until older sequences are processed.
- C. It manually sorts incoming events by timestamp before applying changes.
- D. It runs VACUUM on the target table to purge conflicting records.
Answer: B
Explanation:
AUTO CDC uses the sequence_by column to deterministically order change events for each key.
Delete operations create tombstones that are retained until all earlier sequence values have been processed, ensuring that out-of-order delete events are still applied correctly and consistently in the target table.
NEW QUESTION # 36
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays.
Which limitation will the team face while diagnosing this problem?
- A. New fields not be computed for historic records.
- B. Spark cannot capture the topic partition fields from the kafka source.
- C. Updating the table schema will invalidate the Delta transaction log metadata.
- D. New fields cannot be added to a production Delta table.
- E. Updating the table schema requires a default value provided for each file added.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
Answer: A
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
NEW QUESTION # 37
......
Our Databricks-Certified-Data-Engineer-Professional exam dumps strive for providing you a comfortable study platform and continuously explore more functions to meet every customer’s requirements. We may foresee the prosperous talent market with more and more workers attempting to reach a high level through the Databricks certification. To deliver on the commitments of our Databricks-Certified-Data-Engineer-Professional Test Prep that we have made for the majority of candidates, we prioritize the research and development of our Databricks-Certified-Data-Engineer-Professional test braindumps, establishing action plans with clear goals of helping them get the Databricks certification.
Valid Databricks-Certified-Data-Engineer-Professional Study Guide: https://www.dumptorrent.com/Databricks-Certified-Data-Engineer-Professional-braindumps-torrent.html
- First-grade Valid Databricks-Certified-Data-Engineer-Professional Test Preparation - Trustable Source of Databricks-Certified-Data-Engineer-Professional Exam 🌸 Simply search for 《 Databricks-Certified-Data-Engineer-Professional 》 for free download on 「 www.examcollectionpass.com 」 🅰Databricks-Certified-Data-Engineer-Professional Updated Testkings
- Databricks-Certified-Data-Engineer-Professional Latest Braindumps Ebook 🖼 Practice Databricks-Certified-Data-Engineer-Professional Exams 💃 Exam Databricks-Certified-Data-Engineer-Professional Training 🗻 The page for free download of ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ on ➽ www.pdfvce.com 🢪 will open immediately 🔃Databricks-Certified-Data-Engineer-Professional Practice Exam
- Famous Databricks-Certified-Data-Engineer-Professional Test Learning Guide: Databricks Certified Data Engineer Professional Exam has high pass rate - www.torrentvce.com 🤠 Open { www.torrentvce.com } enter ▷ Databricks-Certified-Data-Engineer-Professional ◁ and obtain a free download 🩺Databricks-Certified-Data-Engineer-Professional Exam Cram
- Databricks Databricks-Certified-Data-Engineer-Professional Exam | Valid Databricks-Certified-Data-Engineer-Professional Test Preparation - Pass-leading Provider for your Databricks-Certified-Data-Engineer-Professional Exam 🙈 Open ⏩ www.pdfvce.com ⏪ and search for [ Databricks-Certified-Data-Engineer-Professional ] to download exam materials for free 🕤Databricks-Certified-Data-Engineer-Professional Exam Online
- Practice Databricks-Certified-Data-Engineer-Professional Exams 🐆 Reliable Databricks-Certified-Data-Engineer-Professional Study Notes 🌯 Databricks-Certified-Data-Engineer-Professional Practice Exam 🪀 ➠ www.easy4engine.com 🠰 is best website to obtain [ Databricks-Certified-Data-Engineer-Professional ] for free download 😷Databricks-Certified-Data-Engineer-Professional Test Dumps Demo
- Databricks-Certified-Data-Engineer-Professional Reliable Test Dumps 👇 Databricks-Certified-Data-Engineer-Professional Exam Cram 🐇 Databricks-Certified-Data-Engineer-Professional New Exam Bootcamp 🔑 Search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ on ➡ www.pdfvce.com ️⬅️ immediately to obtain a free download 💖Databricks-Certified-Data-Engineer-Professional New Exam Bootcamp
- Databricks-Certified-Data-Engineer-Professional Exam Cram 🗺 Databricks-Certified-Data-Engineer-Professional Latest Test Prep 🚌 Practice Databricks-Certified-Data-Engineer-Professional Exams 🕠 Open ▷ www.troytecdumps.com ◁ enter ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and obtain a free download 🔖Databricks-Certified-Data-Engineer-Professional Updated Testkings
- First-grade Valid Databricks-Certified-Data-Engineer-Professional Test Preparation - Trustable Source of Databricks-Certified-Data-Engineer-Professional Exam 🎀 Search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ and download it for free immediately on [ www.pdfvce.com ] 🐅Databricks-Certified-Data-Engineer-Professional Practice Exam
- Valid Databricks-Certified-Data-Engineer-Professional Test Preparation | 100% Free Accurate Valid Databricks Certified Data Engineer Professional Exam Study Guide 😋 Download ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ for free by simply searching on ✔ www.examcollectionpass.com ️✔️ 🔏Databricks-Certified-Data-Engineer-Professional Test Dumps Demo
- 100% Pass 2026 The Best Databricks Databricks-Certified-Data-Engineer-Professional: Valid Databricks Certified Data Engineer Professional Exam Test Preparation 〰 Search for { Databricks-Certified-Data-Engineer-Professional } and download it for free on ➥ www.pdfvce.com 🡄 website 🦂Exam Databricks-Certified-Data-Engineer-Professional Passing Score
- Practice Databricks-Certified-Data-Engineer-Professional Exams Ⓜ Databricks-Certified-Data-Engineer-Professional Reliable Test Dumps 🥿 Databricks-Certified-Data-Engineer-Professional Related Exams 😥 Open ➠ www.prepawayete.com 🠰 and search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ to download exam materials for free 👪Databricks-Certified-Data-Engineer-Professional Test Dumps Demo
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, learn.csisafety.com.au, Disposable vapes