BTW, DOWNLOAD part of Exam4Tests AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=10n-CN4Juqxr7WDBwfpGj_QQaW63P997f
Using these Microsoft AI-300 practice test software you will identify your mistakes, gain confidence and learn time-management skills. It will help you to prepare better for the final AI-300 exam. Exam4Tests Microsoft AI-300 Valid Dumps - Free Demo Download & Refund Guarantee Microsoft AI-300 exam dumps are the best option if you really want to pass the Operationalizing Machine Learning and Generative AI Solutions exam on your first attempt.
| Section | Weight | Objectives |
|---|---|---|
| Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
| Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
>> Latest Test AI-300 Experience <<
Our company always put the quality of the AI-300 practice materials on top priority. In the past ten years, we have made many efforts to perfect our AI-300 study materials. Our AI-300 study questions cannot tolerate any small mistake. All staff has made great dedication to developing the AI-300 Exam simulation. Our professional experts are devoting themselves on the compiling and updating the exam materials and our services are ready to guide you 24/7 when you have any question.
NEW QUESTION # 131
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupyter notebook in the workspace. The experiment must log a list of numerical metrics.
You need to implement a method to log a list of numerical metrics.
Which method should you use?
Answer: C
Explanation:
To log a list of numerical metrics using the Azure Machine Learning Python SDK v2, you should use the mlflow.log_metric() method within a loop, or mlflow.log_metrics() to log them simultaneously as a dictionary.
Reference:
https://learn.microsoft.com/en-us/answers/questions/1456554/downloading-azureml-experiment-metrics-logged-with
NEW QUESTION # 132
Hotspot Question
A team retrains a machine learning model on a weekly basis by using updated training data.
The team must be able to rerun any previous experiment by using the exact data that was available at the time it was originally run. The solution must preserve historical versions of the data without duplicating training scripts.
You need to manage the data so that experiments can be reproduced reliably.
Which workspace actions should you perform? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.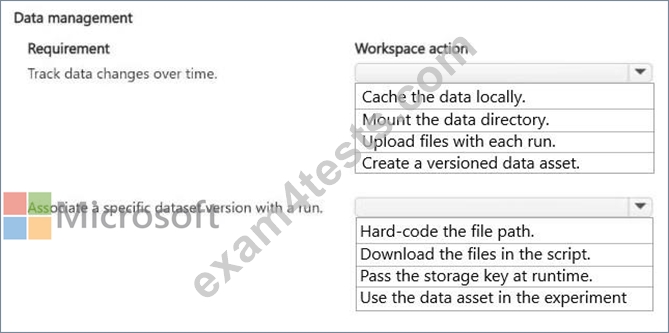
Answer:
Explanation:
Explanation:
Box 1: Create a versioned dataset
Track data changes over time.
Creating a versioned dataset in your machine learning workspace configuration is the correct and industry-standard way to solve this.
Versioned datasets allow you to decouple your training scripts from your data state. This approach satisfies all your constraints without duplicating code or creating messy infrastructure.
Enables Reproducibility: Every time you run a training job, you log the specific dataset version used (e.g., v1, v2, v3). To rerun a historical experiment, you simply call that specific version identifier.
Prevents Code Duplication: Your training scripts remain identical. They accept a dataset version as an input parameter rather than pointing to hardcoded file paths.
Tracks Weekly Updates: When the weekly data refresh occurs, you register the new data as v+1 in the workspace registry, keeping a clean chronological ledger.
Box 2: Use the data asset in the experiment
Associate a specific dataset version with a run.
To best associate a specific dataset version with a run in the workspace, you should use the data asset in the experiment.
Automatic Lineage: Registering data as a versioned data asset automatically tracks which exact version was used in which specific run.
Exact Reproducibility: You can look back at any historical run and instantly identify or retrieve the precise data state used at that moment.
No Script Duplication: Your training scripts remain decoupled from the data, satisfying your requirement to preserve history without changing code.
Incorrect:
[Pass the storage key at runtime]
Passing a storage key at runtime only connects the run to a storage location, not a specific, immutable version of the data at a frozen point in time.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-version-track-datasets
NEW QUESTION # 133
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States.
Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions.
Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support. Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
* Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets
* Azure AI Search indexing curated analytical documents and reference materials
* A small set of Python-based training scripts maintained by data scientists
* Azure OpenAI Service with deployed foundational models
* A Microsoft Foundry resource for building a RAG-based solution
Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
* Model training jobs are run manually from notebooks.
* Experiment tracking is inconsistent
* Model versions are registered without standardized metadata.
* Deployment is performed manually by data scientists, with limited rollback capability.
* The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities. Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
* Provide a conversational interface that answers analytics questions by using internal documents and datasets.
* Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
* Enable repeatable and auditable model training and deployment processes.
* Support experimentation to compare prompt strategies and fine-tuned models.
* Align the model with the ranked preferences and optimize behavior for the long term.
* Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
* Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
* Implement experiment tracking and model versioning for all training jobs.
* Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
* Deploy traditional machine learning models with support for staged rollout and rollback.
* Improve RAG-based solution output quality.
* Use the existing evaluation datasets that are based on real data with input-output pairs.
* Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
You need to isolate training workloads while remaining cost-aware to address Fabrikam Inc.'s issues, constraints, and technical requirements. What should you implement?
Answer: D
Explanation:
Scenario: Issues and Constraints: Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Managed compute targets with autoscaling are the best choice for Azure Machine Learning training workloads when serverless or managed options are preferred and cost predictability is critical.
Best Implementation: Managed Compute with Autoscaling
This option, specifically using Azure Machine Learning compute clusters (AmlCompute), aligns with all your requirements:
Managed Infrastructure: Azure handles the creation, patching, and lifecycle of the virtual machines, reducing management overhead.
Cost Predictability & Efficiency: Autoscaling allows you to set a minimum of zero nodes. This ensures you only pay for compute while a job is running, preventing costs from idle resources.
Scalability: It can automatically scale up to a multi-node cluster to handle large datasets or distributed training jobs.
Enterprise Governance: Administrators can enforce cost control by setting quotas at the subscription or workspace level.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/how-to-use-serverless-compute
NEW QUESTION # 134
You create a binary classification model. You use the Fairlearn package to assess model fairness.
You must eliminate the need to retrain the model.
You need to implement the Fairlearn package.
Which algorithm should you use?
Answer: A
Explanation:
The question ' s constraint is explicit: no retraining. This immediately eliminates ExponentiatedGradient (option A), which is a reduction-based in-processing algorithm that requires retraining as part of the fairness- aware optimization process. GridSearch (option C) systematically trains multiple models across a grid of fairness constraints, again requiring training. CorrelationRemover (option B) is a pre-processing technique that transforms training features before training, also requiring a new training run. ThresholdOptimizer (option D) is a post-processing algorithm: it takes an already-trained model and optimizes its classification thresholds independently for different sensitive-attribute groups to achieve a fairness constraint such as equalized odds or demographic parity, without touching the model weights. This is the only Fairlearn approach that operates purely at inference time on an existing model.
Microsoft Learn Reference Topic: Mitigate unfairness in machine learning models with Fairlearn - Post- processing with ThresholdOptimizer
NEW QUESTION # 135
Hotspot Question
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data. The folder structure contains the following content: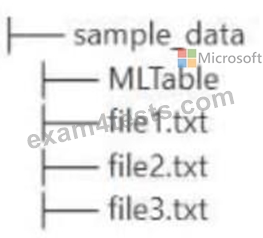
You write Python SDK v2 code to materialize the data from the files in the sample_data folder into a Pandas data frame.
You need to complete the Python SDK v2 code to use the MLTable folder as the materialization blueprint.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point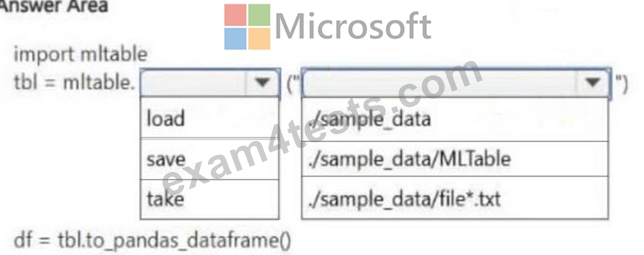
Answer:
Explanation: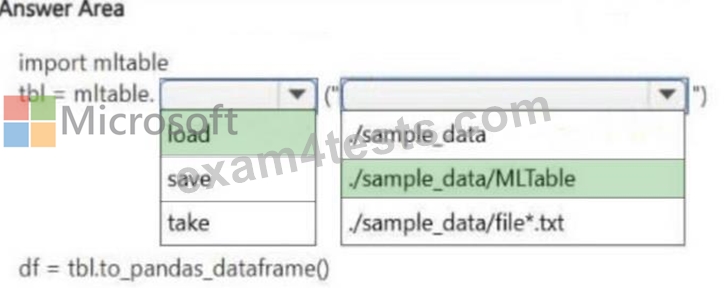
NEW QUESTION # 136
......
Our AI-300 test guide has become more and more popular in the world. Of course, if you decide to buy our AI-300 latest question, we can make sure that it will be very easy for you to pass your exam and get the certification in a short time, first, you just need 5-10 minutes can receive AI-300 Exam Torrent that you can learn and practice it. Then you just need 20-30 hours to practice our AI-300 study materials that you can attend your AI-300 exam. It is really spend your little time and energy.
AI-300 Test Simulator: https://www.exam4tests.com/AI-300-valid-braindumps.html
P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by Exam4Tests: https://drive.google.com/open?id=10n-CN4Juqxr7WDBwfpGj_QQaW63P997f