What's more, part of that PDFDumps SPS-C01 dumps now are free: https://drive.google.com/open?id=1rnJcnY0B-nd2eOAtlZY8VJMaQTyk0nys
These real and updated Snowflake SPS-C01 dumps are essential to pass the SPS-C01 exam on the first try. Don't waste further time and money, get real Snowflake SPS-C01 pdf questions and practice test software, and start SPS-C01 Test Preparation today. PDFDumps will also provide you with up to 365 days of free exam questions updates.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Performance and Best Practices | 10% | - Security and governance
|
| Topic 2: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Topic 3: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 4: Data Transformations and Operations | 35% | - DataFrame manipulation
|
Owing to our high-quality SPS-C01 real test and high passing rate, our company has been developing faster and faster and gain good reputation in the world. Our education experts are adept at designing and researching exam questions and answers of SPS-C01 study torrent. What's more, we can always get latest SPS-C01 exam information resource. We have unique advantages on study guide materials. Our high passing rate is the leading position in this field. We are the best choice for candidates who are eager to pass exams and acquire the certifications. Our SPS-C01 Actual Exam will be definitely conducive to realizing the dream of obtaining the certificate.
NEW QUESTION # 306
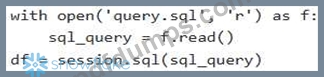
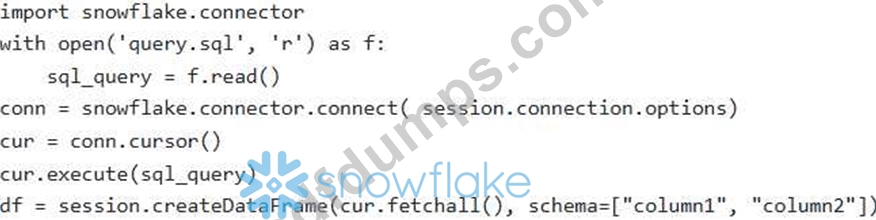
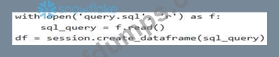
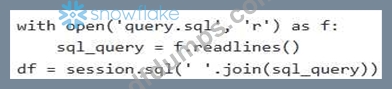
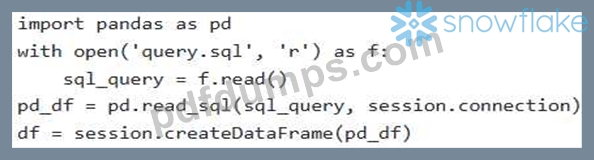
You have a SQL query stored in a file named 'query.sqr which contains several complex analytical calculations. The query depends on a Snowpark 'session' object already established. You want to create a Snowpark DataFrame from the result of this query. Which of the following code snippets achieves this with optimal performance and readability, assuming correct file access permissions?
Answer: A
Explanation:
Option A provides the most straightfomard and efficient approach. It reads the SQL query from the file and directly creates a Snowpark DataFrame using 'session.sql(sql_query)'. Option B introduces Pandas, which is unnecessary and less efficient. Option C uses the Snowflake Connector outside of Snowpark's API, which is generally not the preferred approach. Option D has a non-existent function create_dataframe' , and Option E reads lines separately requiring a join which might be erroneous.
NEW QUESTION # 307
You have a Snowpark Python application that performs complex data transformations and machine learning model training. The data is stored in Snowflake tables. You notice that model training jobs, specifically those involving large feature sets and iterative algorithms, are consistently slow. The warehouse is already scaled to a LARGE size. Which of the following techniques, when applied individually or in combination, would MOST likely improve the performance of model training in Snowpark?
Answer: B,D
Explanation:
Caching intermediate DataFrames (Option B) avoids redundant computations, significantly speeding up iterative algorithms. Filtering and data skipping (Option E) reduce the amount of data processed, which is especially beneficial with large feature sets. While sprocs (Option A) offer performance benefits for certain IJDFs, the impact on overall model training performance might be less significant compared to caching and data reduction. External functions (Option C) may introduce network latency, outweighing the potential benefits, unless carefully optimized for data transfer. Scaling up (Option D) might help, but is not the most likely to improve performance, given that the warehouse is already at a LARGE size. Focusing on more efficient data handling is better in most cases.
NEW QUESTION # 308
A data engineer is tasked with creating a Snowpark session using JWT authentication. They have a private key 'rsa_key.pff, a user name 'snowpark_user' , and an account identifier 'my_account'. The goal is to create a session object suitable for submitting Snowpark jobs. Which code snippet correctly demonstrates the instantiation of a session object using JWT?





Answer: E
Explanation:
Option B correctly reads the private key file, converts it to the required PEM format, and then uses it within the connection parameters to establish a Snowpark session. It handles the private key securely by loading and formatting it properly before passing it to the connection parameters. Option A, C and D attempts to directly provide the path to the private key or read the content with incorrect formatting which is incorrect. Option E doesn't address reading the private key in correct form and only address warehouse selection after the session is create.
NEW QUESTION # 309
You are working with a Snowpark DataFrame 'sales_data' containing sales transactions. The DataFrame includes columns 'transaction_id' (STRING), 'product_id' (IN T), 'sale_date' (DATE), and 'sale_amount' (DOUBLE). You need to calculate the total sales amount for each product on a daily basis. Furthermore, you want to filter out any days where the total sales amount for a specific product is less than $50. Which of the following code snippets correctly achieves this using Snowpark Python?





Answer: A,E
Explanation:
Options A and B are correct. Both first group the data by 'product_id' and 'sale_date' and calculate the sum of 'sale_amount' for each group. They then filter the results to include only those rows where 'total_sales' is greater than 50. 'filter' and 'where' are interchangable. C would be invalid snowpark as you use 'having' after group_by. Option D and E would also be valid if the prompt asked for all days with a sale amount equal to greater than $50 not greater.
NEW QUESTION # 310
You are developing a Snowpark application that utilizes a UDF. You need to ensure that the UDF runs with the privileges of the caller (the user executing the query). Which of the following steps are necessary to accomplish this while creating the Snowpark session?
Answer: C
Explanation:
To ensure a UDF runs with the privileges of the caller, you need to explicitly specify the 'api_caller_identity=sf.Caller.CALLER when defining the UDF using Snowpark. This instructs Snowflake to execute the UDF with the caller's permissions. No special session configurations are needed. Option A is irrelevant for caller's identity. Option B is incorrect as it's not automatic. Option D does not exist. Option E is a valid SQL command but needs to be implemented in Python using 'session.sqr function
NEW QUESTION # 311
......
With the pass rate reaching 98.75%, our SPS-C01 test materials have gained popularity in the international market. Many candidates have recommended our products to their friends. In addition, SPS-C01 exam materials are edited by skilled professionals, and they possess the professional knowledge for the exam, therefore you can use the exam materials at ease. Free demo for SPS-C01 Exam Dumps are available, and you can have a try before buying , so that you can have a better understanding of what you are going to buy.
SPS-C01 Reliable Exam Price: https://www.pdfdumps.com/SPS-C01-valid-exam.html
DOWNLOAD the newest PDFDumps SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1rnJcnY0B-nd2eOAtlZY8VJMaQTyk0nys