DOWNLOAD the newest DumpsTests DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1U59BsWA5Lb-e83WpWZyyQ_1U_w6JNcrV
In order to help you save more time, we will transfer DY0-001 test guide to you within 10 minutes online after your payment and guarantee that you can study these materials as soon as possible to avoid time waste. We believe that time is the most valuable things in the world. This is why we are dedicated to improve your study efficiency and production. Moreover if you have a taste ahead of schedule, you can consider whether our DY0-001 Exam Torrent is suitable to you or not, thus making the best choice. What’s more, if you become our regular customers, you can enjoy more membership discount and preferential services.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam |
| Exam Number: | DY0-001 |
| Exam Price: | $529 USD |
| Exam Format: | Performance-Based, Multiple Choice |
| Certificate Validity Period: | Usually 3 years |
| Available Languages: | Japanese, English |
| Passing Score: | Pass/Fail (No scaled score) |
| Real Exam Qty: | Up to 90 |
| Exam Duration: | 165 minutes |
| Related Certifications: | CompTIA DataAI (formerly DataX) |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Available at Pearson VUE testing centers or via online proctoring (OnVUE). |
| Pre Condition: | 5+ years of experience in data science or a similar role recommended. |
| Official Syllabus URL: | https://www.comptia.org/en-us/certifications/dataai |
>> Guaranteed CompTIA DY0-001 Passing <<
There is a succession of anecdotes, and there are specialized courses. Experts call them experts, and they must have their advantages. They are professionals in every particular field. The DY0-001 test material, in order to enhance the scientific nature of the learning platform, specifically hired a large number of qualification exam experts, composed of product high IQ team, these experts by combining his many years teaching experience of DY0-001 quiz guide and research achievements in the field of the test, to exam the popularization was very complicated content of CompTIA DataAI Certification Exam exam dumps, better meet the needs of users of various kinds of cultural level. Expert team not only provides the high quality for the DY0-001 Quiz guide consulting, also help users solve problems at the same time, leak fill a vacancy, and finally to deepen the user's impression, to solve the problem of DY0-001 test material and no longer make the same mistake.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
NEW QUESTION # 61
Which of the following is a key difference between KNN and k-means machine-learning techniques?
Answer: A
Explanation:
# K-Nearest Neighbors (KNN) is a supervised machine learning algorithm used primarily for classification and regression. It labels a new instance by majority vote (or averaging, in regression) of its k-nearest labeled neighbors.
# k-Means is an unsupervised learning algorithm used for clustering. It partitions unlabeled data into k groups based on feature similarity, using centroids.
Thus, the key difference is in their purpose:
* KNN # Classification (Supervised)
* K-Means # Clustering (Unsupervised)
Why the other options are incorrect:
* A: Both can technically operate on continuous or categorical data (with preprocessing).
* B: This is not a meaningful or standardized distinction.
* C: This reverses the actual roles. k-means finds centroids; KNN finds nearest neighbors.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 4.1 (Classification vs. Clustering):"KNN is a supervised learning algorithm for classification tasks. K-means is an unsupervised clustering technique that groups data by proximity to centroids."
* Data Science Handbook, Chapter 5:"One key distinction: KNN uses labeled data to classify or regress; k-means uses unlabeled data to identify groupings."
-
NEW QUESTION # 62
Which of the following best describes the minimization of the residual term in a LASSO linear regression?
Answer: B
Explanation:
# LASSO (Least Absolute Shrinkage and Selection Operator) regression minimizes the squared residuals (e²), just like OLS, but adds an L1 penalty to encourage sparsity in the coefficients. Thus, the residual component minimized is still the sum of squared errors.
Why the other options are incorrect:
* A: |e| is absolute error, not used in standard LASSO objective.
* B: e is the error term, but minimization applies to its squared version.
* C: Minimizing to exactly 0 is idealistic but not realistic.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.3:"LASSO minimizes squared errors with an additional L1 regularization term."
* Elements of Statistical Learning, Chapter 6:"LASSO regression uses the same residual sum of squares (e²) as OLS for error measurement, with an added constraint."
-
NEW QUESTION # 63
A company created a very popular collectible card set. Collectors attempt to collect the entire set, but the availability of each card varies, with because some cards have higher production volumes than others. The set contains a total of 12 cards. The attributes of the cards are below: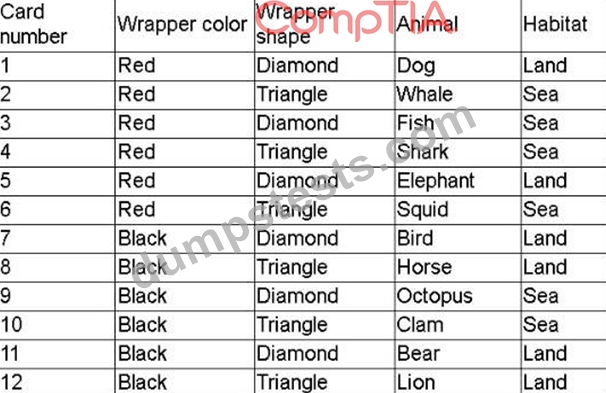
A data scientist is provided a historical record of cards purchased, which was acquired by a local collectors' association. The data scientist needs to design an initial model iteration to predict whether or not the animal on the card lives in the sea or on land given the provided attributes. Which of the following is the best way to accomplish this task?
Answer: B
Explanation:
You have categorical inputs (wrapper color, shape, animal) and a binary target (sea vs. land). A decision tree natively handles categorical features and yields clear, rule-based splits that predict habitat, making it the most appropriate choice.
NEW QUESTION # 64
Which of the following distributions would be best to use for hypothesis testing on a data set with 20 observations?
Answer: C
Explanation:
# For small sample sizes (typically n < 30), the Student's t-distribution is preferred over the normal distribution for hypothesis testing because it accounts for the added uncertainty in the estimate of the standard deviation. With 20 observations, the t-distribution is more appropriate and reliable.
Why the other options are incorrect:
* A: Power law is used in modeling rare events or heavy-tailed distributions, not hypothesis testing.
* B: The normal distribution is more appropriate when the sample size is large.
* C: Uniform distribution assumes equal probability - not used in inferential statistics.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 1.3:"The t-distribution is used for small sample hypothesis testing where the population standard deviation is unknown."
-
NEW QUESTION # 65
A data analyst is examining the correlation matrix of a new data set to identify issues that could adversely impact model performance. Which of the following is the analyst most likely checking for?
Answer: D
Explanation:
# Multicollinearity occurs when independent variables are highly correlated with each other. This can distort coefficient estimates and reduce model interpretability. A correlation matrix is the primary tool used to detect it.
Why the other options are incorrect:
* A & C: Under/oversampling relate to class imbalance, not variable correlation.
* D: Overfitting is related to model complexity, not directly observable via a correlation matrix.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Correlation matrices are used to detect multicollinearity - high correlations among predictors that may destabilize models."
NEW QUESTION # 66
......
Cert DY0-001 Guide: https://www.dumpstests.com/DY0-001-latest-test-dumps.html
What's more, part of that DumpsTests DY0-001 dumps now are free: https://drive.google.com/open?id=1U59BsWA5Lb-e83WpWZyyQ_1U_w6JNcrV