一番優秀なSPS-C01日本語練習問題試験-試験の準備方法-高品質なSPS-C01資格復習テキスト

無料でクラウドストレージから最新のPass4Test SPS-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1RvBgJIHOpPA5_gAD0FTG_ujqQJC7QUlS
SPS-C01パススルートレントの設計に多くの変更があります。 最も印象的なバージョンは、APPオンラインバージョンです。 通常、あらゆる種類のデジタルデバイスで使用できます。 しかし、オンラインではないときにオンラインバージョンを使用できるという特別な利点もあります。ネットワーク環境で初めて使用する場合は、どこからでもPass4TestのSPS-C01学習ガイドのオンラインバージョンを使用できます。 ネットワーク接続なし。 オンライン版のSPS-C01試験問題はあなたに適した選択肢だと思います
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Transformations and Operations | 35% | - User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
- Advanced operations
- 1. Window functions and analytics
- 2. Pivot and unpivot transformations
- 3. Semi-structured data processing
- DataFrame manipulation
- 1. Filtering, sorting, grouping, aggregation
- 2. Selection, projection, renaming, casting
- 3. Joins, unions, set operations
|
| Snowpark API and Development | 30% | - Python API fundamentals
- 1. DataFrame creation from tables, views, SQL
- 2. Data persistence and writing results
- 3. Column operations and functions
- Multi-language support
- 1. Java and Scala API basics
- 2. Environment setup and dependencies
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
- Snowpark architecture and execution model
- 1. Client-side vs server-side processing
- 2. Lazy evaluation and DAG execution
- 3. Transformations vs actions
|
| Performance and Best Practices | 10% | - Security and governance
- 1. Access control and permissions
- 2. Data protection and compliance
- Optimization techniques
- 1. Minimizing data movement
- 2. Caching and warehouse sizing
- 3. Query pushdown and execution plans
|
>> SPS-C01日本語練習問題 <<
SPS-C01資格復習テキスト & SPS-C01ダウンロード
SnowflakeのSPS-C01クイズトレントは無料の試用版を提供します。したがって、SPS-C01テスト準備についてより深く理解し、この種の学習教材が購入に適しているかどうかを推定するのに役立ちます。 Pass4Test試用版を使用すると、テストプラットフォームで利用可能な3つの異なるバージョンの選択からアフターサービスまで、さまざまな側面からのSPS-C01試験トレントについてより深く理解できます。 SPS-C01試験問題を試してみたら、Snowflake Certified SnowPro Specialty - Snowpark購入するのが大好きです。
Snowflake Certified SnowPro Specialty - Snowpark 認定 SPS-C01 試験問題 (Q360-Q365):
質問 # 360
You are developing a Snowpark application that processes high-volume event data stored in a Snowflake table named 'raw events'. The application aggregates data by session ID. You observe significant performance degradation during peak hours. Analyzing Snowflake query history reveals that the 'session_id' column has high cardinality and data skew. Which of the following strategies, or combination of strategies, would be MOST effective in optimizing the aggregation performance?
- A. Use a 'GROUP BY' clause in the Snowpark DataFrame combined with a 'hint' to specify the ' for optimized parallel processing.
- B. Increase the warehouse size to a larger tier (e.g., from X-Small to Small).
- C. Implement a custom UDF (User-Defined Function) in Python to perform the aggregation and then apply the 'GROUP clause in the Snowpark DataFrame.
- D. Pre-aggregate the raw event data into smaller batches using a scheduled task before the main Snowpark application runs, and then aggregate the pre- aggregated data in the Snowpark application.
- E. Use a 'GROUP clause in the Snowpark DataFrame to perform the aggregation.
正解:A、D
解説:
Using BUCKET_ID hint improves parallel processing and mitigates data skew in Snowpark. Pre-aggregation reduces the amount of data processed by the Snowpark application, thus improving performance. Increasing the warehouse size (A) might help but doesn't address data skew. UDFs (D) can introduce overhead if not optimized. GROUP BY alone (B) will not address the data skew problem
質問 # 361
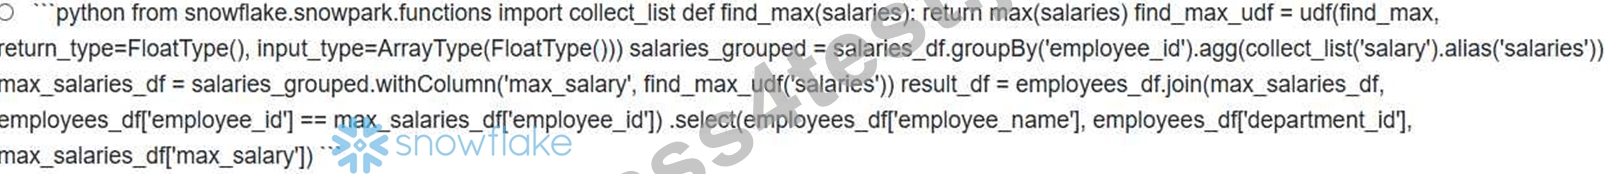
You have two Snowpark DataFrames: 'employees_df with columns 'employee_id' (INTEGER), 'employee_name' (STRING), 'department_id' (INTEGER), and 'salaries_df' with columns 'employee_id' (INTEGER), "salary' (FLOAT), 'effective_date' (DATE). You need to create a new DataFrame that contains the employee's name, department, and the highest salary they have ever received. Assuming there can be multiple salary entries for the same employee with different 'effective date' values, which of the following Snowpark code snippets would correctly and efficiently solve this problem?
正解:A
解説:
Option B is the most efficient solution. It first calculates the maximum salary for each employee in the DataFrame using 'groupBy' and 'max' , then joins this aggregated result with the 'employees_df to retrieve the employee's name and department. This approach avoids unnecessary data shuffling and minimizes the amount of data processed in the join. Option A performs the join before the aggregation, which can be less efficient. Options C and E use window functions, which are more complex and may not be as efficient for this simple aggregation. Option D uses a UDF and 'collect_list' , which can be very inefficient due to data transfer and UDF overhead.
質問 # 362
A Snowpark application needs to authenticate to Snowflake using OAuth. The application is running on an Azure Function and uses a client ID, client secret, and refresh token obtained previously. Which of the following connection parameter dictionaries is correctly configured for OAuth authentication?
正解:E
解説:
Option E correctly specifies 'oauth' as the authenticator and uses the access token to establish the connection. Using the access token directly after obtaining it is the common practice for OAuth in Snowpark. Options A, B, C and D are incorrect because for Snowpark, you typically use the access token, not the refresh token, directly in the connection parameters after you've initially exchanged the refresh token for an access token outside of this specific session establishment.
質問 # 363
You are working with a Snowpark DataFrame 'transactions df that contains customer transaction data'. This data includes a 'transaction amount' column and a 'transaction date' column. You need to create a new feature called 'is weekend transaction' that indicates whether a transaction occurred on a weekend (Saturday or Sunday). Furthermore, some 'transaction_date' values are missing. You want to impute the missing dates with the mode (most frequent date) before determining if the transaction occurred on a weekend. Which of the following steps, when combined, provide the correct and most efficient approach to achieve this?
- A. 1. Calculate the mode of the 'transaction_date' column. 2. Filter all rows where 'transaction_date' is null and load that data into a temporary table. 3. Update all rows in original 'transactions_df from temporary table. 4. Create a UDF that takes a date as input and returns True if it's a weekend (Saturday or Sunday), False otherwise. 5. Apply the UDF to the 'transaction_date' column to create the column.
- B. 1. Calculate the mode of the 'transaction_date' column using Snowpark functions. 2. Fill the missing values in the 'transaction_date' column with the calculated mode using 'fillna()'. 3. Use the 'dayofweek' function to determine the day of the week and create using a 'when' condition.
- C. 1. Replace the null values in 'transaction_date' column with a constant string like '1900-01-01'.2. Create a UDF that takes a date as input and returns True if it's a weekend (Saturday or Sunday), False otherwise. 3. Apply the UDF to the 'transaction_dates column to create the column. 4. After applying the UDF convert back the replaced values in transaction_date to null.
- D. 1. Calculate the mode of the 'transaction_date' column using Snowpark functions. 2. Fill the missing values in the 'transaction_date' column with the calculated mode using 3. Create a UDF using datetime library that takes a date as input and returns True if it's a weekend (Saturday or Sunday), False otherwise. 4. Apply the UDF to the 'transaction_date' column to create the column.
- E. 1. Calculate the mode of the 'transaction_date' column. 2. Fill the missing values in the 'transaction_date' column with the calculated mode. 3. Create a UDF that takes a date as input and returns True if it's a weekend (Saturday or Sunday), False otherwise. 4. Apply the UDF to the 'transaction_date' column to create the 'is weekend transaction' column.
正解:B
解説:
Option B is the most efficient and utilizes Snowpark's built-in capabilities. It calculates the mode using Snowpark's aggregation functions, fills missing values using and leverages the function to determine weekend status without the need for a UDF. Option A creates a UDF which is less efficient than using a built-in function. Option C replaces with an arbitary string which is bad as its hardcoding and not efficient, after filling the value a UDF is made which is not efficient as well, Also after that the data has to converted back, thus option C is not correct. Options D is more complex as it utilizes temporary table which is not efficient. Option E create a UDF when snowpark provides readily available functions. so its less efficient.
質問 # 364
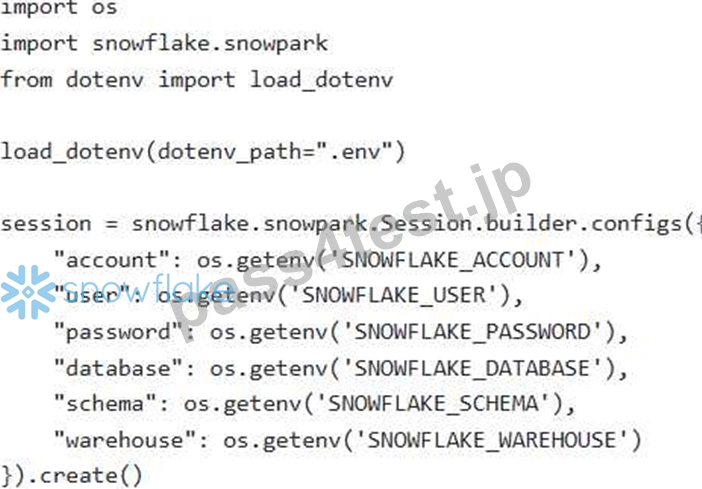
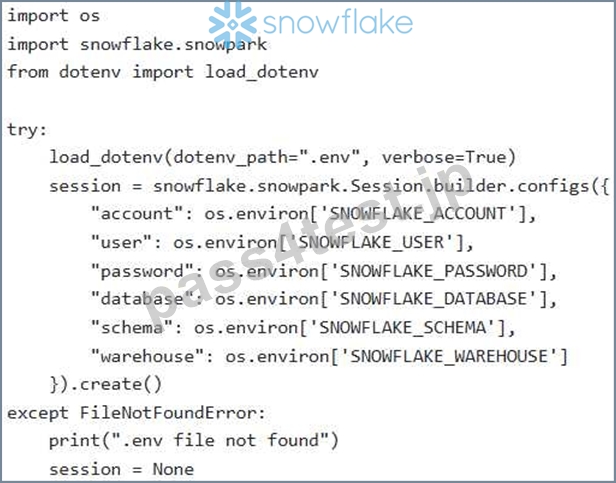
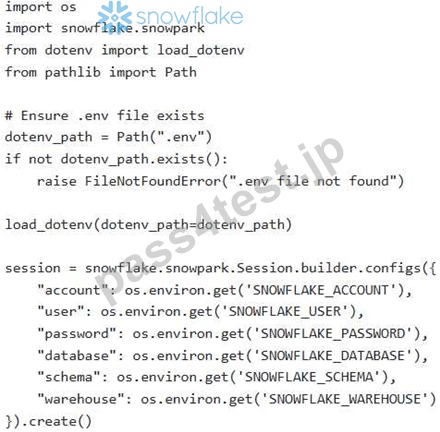
You have configured your Snowpark application to use a '.env' file for storing connection parameters. The ' .env' file contains the following:
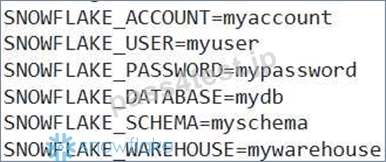
Which of the following code snippets demonstrates the most secure and recommended method for creating a Snowpark session using these environment variables and also ensuring the file exists?
正解:C
解説:
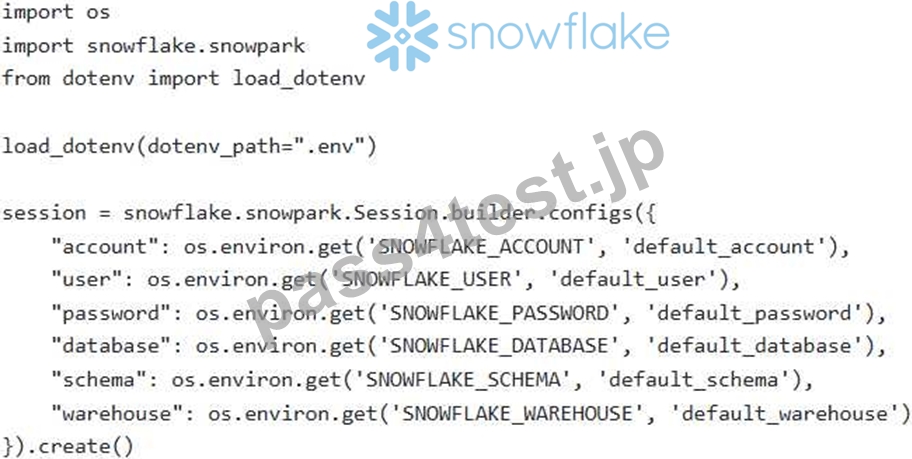
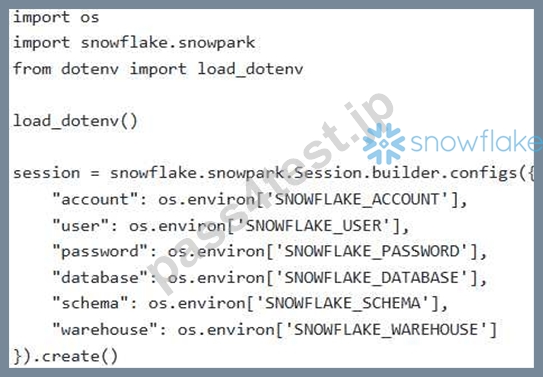
Option D is the most robust because it explicitly checks for the existence of the .env' file using 'pathlib' before attempting to load it, raising a FileNotFoundError' if it's missing, AND it utilizes 'os.environ.get()' which is safer than directly accessing 'os.environ[]" because it returns if the environment variable doesn't exist, preventing 'KeyError' exceptions, although in this case the .env' file not being present is detected. Options A, B, C and E don't proactively check for file existence prior to opening, and could thus potentially fail or crash the Snowpark session, or could inadvertently utilize invalid default values, which could lead to unexpected or incorrect behavior. Providing default values (Option E) might mask configuration errors.
質問 # 365
......
あなたより優れる人は存在している理由は彼らはあなたの遊び時間を効率的に使用できることです。どのようにすばらしい人になれますか?ここで、あなたに我々のSnowflake SPS-C01試験問題集をお勧めください。弊社Pass4TestのSPS-C01試験問題集を介して、速く試験に合格してSPS-C01試験資格認定書を受け入れる一方で、他の人が知らない知識を勉強して優れる人になることに近くなります。
SPS-C01資格復習テキスト: https://www.pass4test.jp/SPS-C01.html
- SPS-C01最新受験攻略 🧹 SPS-C01問題集無料 📽 SPS-C01勉強の資料 🌃 ☀ www.it-passports.com ️☀️で➠ SPS-C01 🠰を検索して、無料でダウンロードしてくださいSPS-C01模擬対策問題
- SPS-C01日本語認定対策 🌅 SPS-C01勉強の資料 🤧 SPS-C01合格率書籍 😷 《 www.goshiken.com 》には無料の⏩ SPS-C01 ⏪問題集がありますSPS-C01認定資格
- SPS-C01認定内容 ✍ SPS-C01資格認証攻略 🤗 SPS-C01学習教材 🚻 最新➽ SPS-C01 🢪問題集ファイルは☀ www.japancert.com ️☀️にて検索SPS-C01模試エンジン
- 効率的なSPS-C01日本語練習問題と実際的なSPS-C01資格復習テキスト 🔽 ⏩ www.goshiken.com ⏪サイトにて☀ SPS-C01 ️☀️問題集を無料で使おうSPS-C01模擬対策問題
- SPS-C01試験の準備方法|有難いSPS-C01日本語練習問題試験|一番優秀なSnowflake Certified SnowPro Specialty - Snowpark資格復習テキスト 🏚 今すぐ➡ www.xhs1991.com ️⬅️を開き、➥ SPS-C01 🡄を検索して無料でダウンロードしてくださいSPS-C01実際試験
- SPS-C01認定資格 🦩 SPS-C01シュミレーション問題集 💑 SPS-C01受験資料更新版 🍸 Open Webサイト▷ www.goshiken.com ◁検索[ SPS-C01 ]無料ダウンロードSPS-C01問題集無料
- SPS-C01認定内容 😛 SPS-C01実際試験 🎿 SPS-C01模擬対策問題 🚬 ☀ www.japancert.com ️☀️には無料の{ SPS-C01 }問題集がありますSPS-C01日本語認定対策
- SPS-C01 Snowflake Certified SnowPro Specialty - Snowparkトレーニング資料、SPS-C01問題集、SPS-C01試験ガイド 🐮 ➽ www.goshiken.com 🢪を開いて⮆ SPS-C01 ⮄を検索し、試験資料を無料でダウンロードしてくださいSPS-C01模擬対策問題
- 試験SPS-C01日本語練習問題 - 一生懸命にSPS-C01資格復習テキスト | ユニークなSPS-C01ダウンロード 🌖 URL ⏩ www.goshiken.com ⏪をコピーして開き、▷ SPS-C01 ◁を検索して無料でダウンロードしてくださいSPS-C01日本語認定対策
- SPS-C01 Snowflake Certified SnowPro Specialty - Snowparkトレーニング資料、SPS-C01問題集、SPS-C01試験ガイド 🧪 ⇛ www.goshiken.com ⇚を開き、「 SPS-C01 」を入力して、無料でダウンロードしてくださいSPS-C01勉強の資料
- 試験SPS-C01日本語練習問題 - 一生懸命にSPS-C01資格復習テキスト | ユニークなSPS-C01ダウンロード 📨 サイト☀ www.it-passports.com ️☀️で( SPS-C01 )問題集をダウンロードSPS-C01問題例
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
無料でクラウドストレージから最新のPass4Test SPS-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1RvBgJIHOpPA5_gAD0FTG_ujqQJC7QUlS