It can be said that all the content of the DP-800 study materials are from the experts in the field of masterpieces, and these are understandable and easy to remember, so users do not have to spend a lot of time to remember and learn. It takes only a little practice on a daily basis to get the desired results. Especially in the face of some difficult problems, the user does not need to worry too much, just learn the DP-800 Study Materials provide questions and answers, you can simply pass the exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Our company boosts top-ranking expert team, professional personnel and specialized online customer service personnel. Our experts refer to the popular trend among the industry and the real exam papers and they research and produce the detailed information about the DP-800 study materials. They constantly use their industry experiences to provide the precise logic verification. The DP-800 Study Materials are compiled with the highest standard of technology accuracy and developed by the certified experts and the published authors only.
NEW QUESTION # 31
You need to meet the development requirements for the FeedbackJson column How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.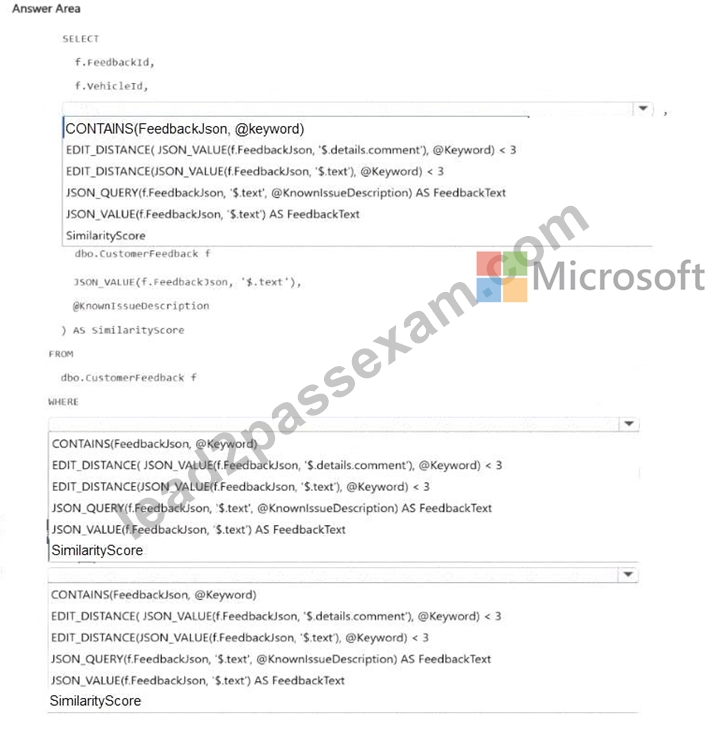
Answer:
Explanation: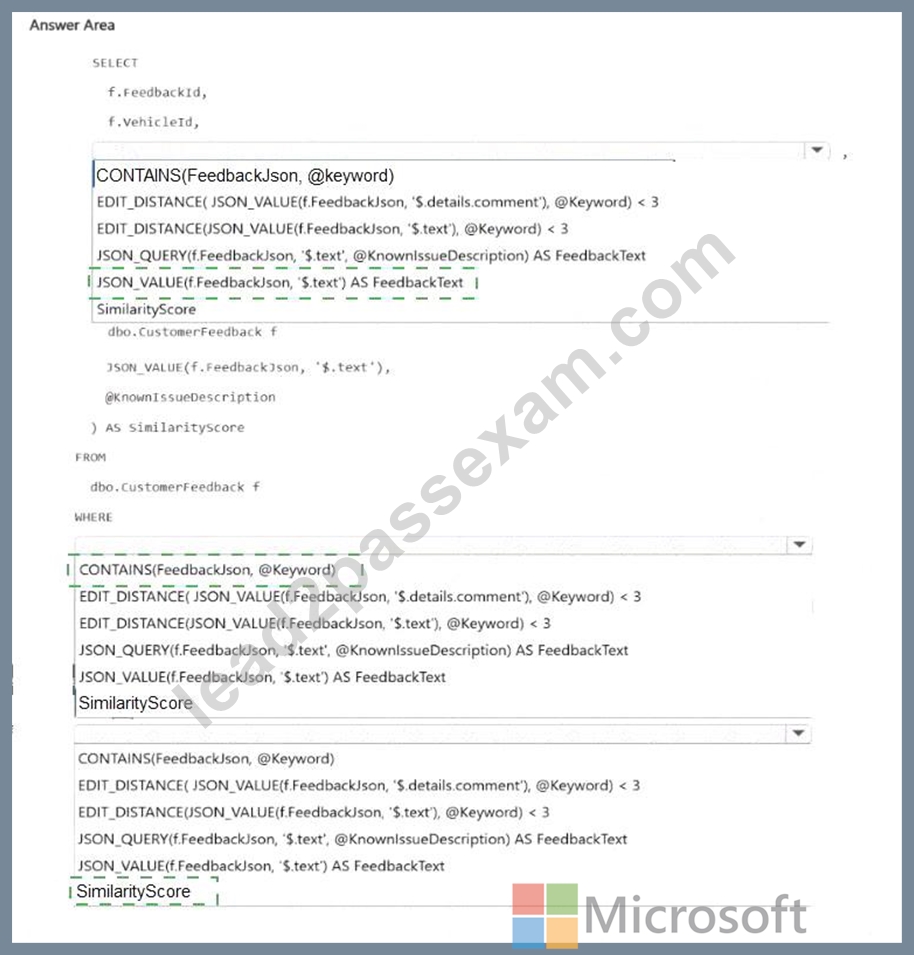
Explanation:
JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText
CONTAINS(FeedbackJson, @Keyword)
SimilarityScore
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column.
First, to extract the customer feedback text from the JSON document , the correct expression is JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText . Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array .
Since $.text is the textual feedback string, JSON_VALUE is the correct function.
Second, to filter rows where the JSON text contains a keyword , the best choice is CONTAINS (FeedbackJson, @Keyword) . The scenario explicitly states that FeedbackJson already has a full-text index
, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering.
Third, to order the results by similarity score, highest first , the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query.
NEW QUESTION # 32
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.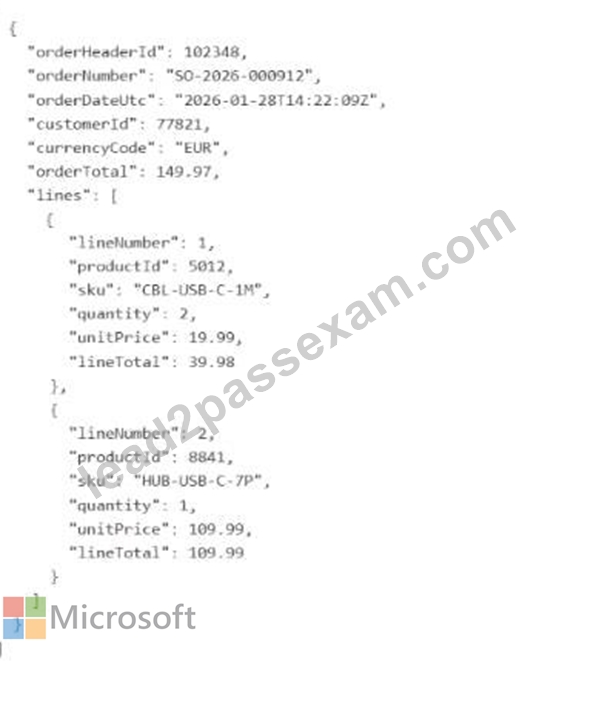
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.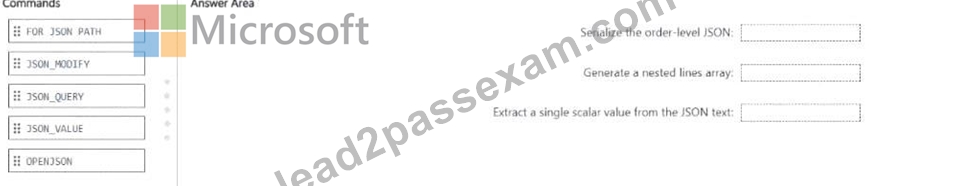
Answer:
Explanation: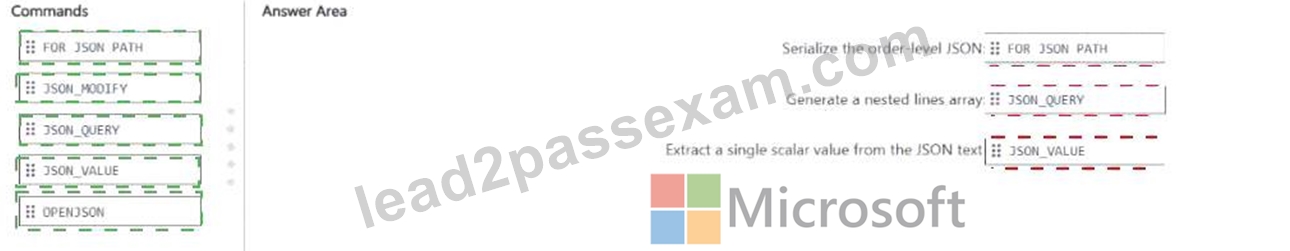
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 33
You have an Azure SQL database that contains a table named dbo.SupportTickets. dbo.SupportTickets contains a JSON column named Payload and a datetime column CreatedAt.
You need to generate a report for the last seven days that meets the following requirements:
* Returns exactly one row per customer per day
* For each customer and day, returns the earliest ticket
* Includes the customer ID stored in Payload
How should you complete the Transact-SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.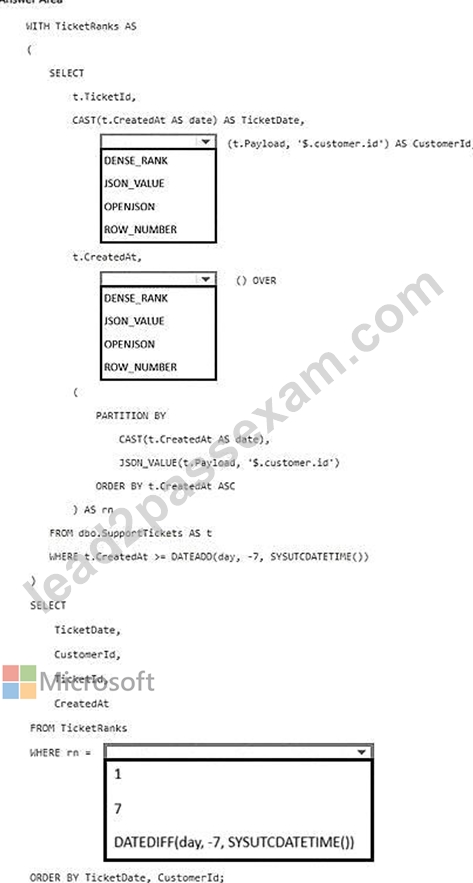
Answer:
Explanation: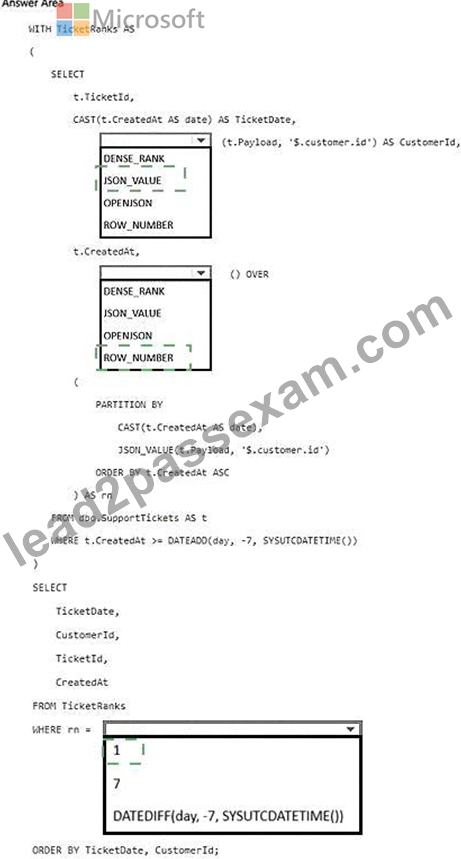
Explanation:
* CustomerId extraction # JSON_VALUE
* Ranking function # ROW_NUMBER
* Final filter # 1
The first selection is JSON_VALUE because CustomerId is stored as a scalar property in the JSON payload at
$.customer.id . Microsoft documents that JSON_VALUE extracts a scalar value from JSON text, whereas OPENJSON is used to shred JSON into relational rows/columns.
The second selection is ROW_NUMBER . The query partitions the data by:
CAST(t.CreatedAt AS date),
JSON_VALUE(t.Payload, ' $.customer.id ' )
and orders each partition by:
t.CreatedAt ASC
Microsoft documents that ROW_NUMBER() assigns sequential numbers starting at 1 within each partition .
Therefore, the earliest ticket for each customer on each day receives rn = 1 .
The third selection is therefore 1 , because filtering with:
WHERE rn = 1
returns exactly one row per customer per calendar day-the earliest ticket in that partition.
So the completed logic is:
WITH TicketRanks AS
(
SELECT
t.TicketId,
CAST(t.CreatedAt AS date) AS TicketDate,
JSON_VALUE(t.Payload, ' $.customer.id ' ) AS CustomerId,
t.CreatedAt,
ROW_NUMBER() OVER
(
PARTITION BY
CAST(t.CreatedAt AS date),
JSON_VALUE(t.Payload, ' $.customer.id ' )
ORDER BY t.CreatedAt ASC
) AS rn
FROM dbo.SupportTickets AS t
WHERE t.CreatedAt > = DATEADD(day, -7, SYSUTCDATETIME())
)
SELECT
TicketDate,
CustomerId,
TicketId,
CreatedAt
FROM TicketRanks
WHERE rn = 1
ORDER BY TicketDate, CustomerId;
Final hotspot selections:
* First dropdown: JSON_VALUE
* Second dropdown: ROW_NUMBER
* Third dropdown: 1
NEW QUESTION # 34
You have an Azure SQL database that contains a table named stores, stores contains a column named description and a vector column named embedding.
You need to implement a hybrid search query that meets the following requirements:
* Uses full-text search on description for the keyword portion
* Returns the top 20 results based on a combined score that uses a weighted formula of 60% vector distance and 40% full-text rank How should you configure the query components? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.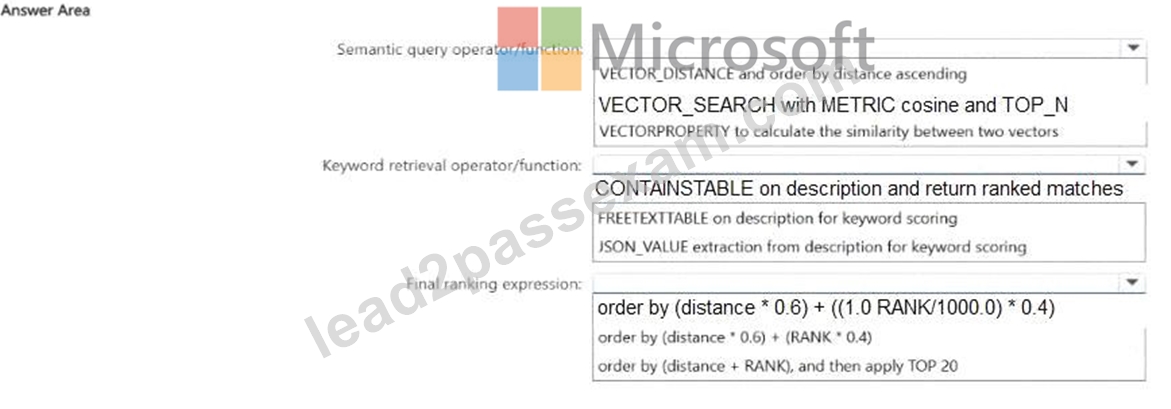
Answer:
Explanation: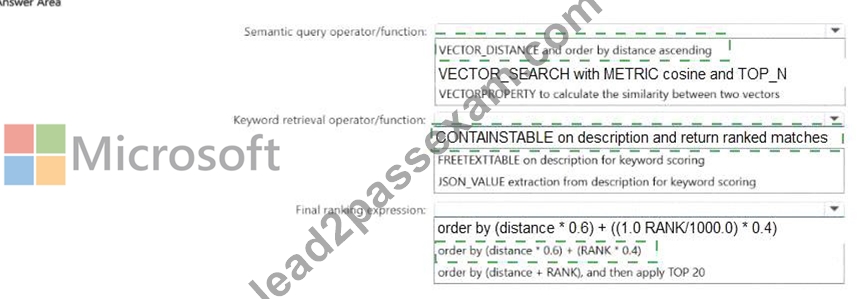
Explanation: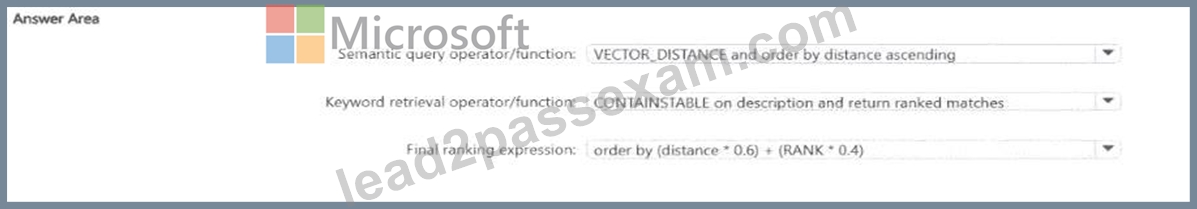
For the vector portion, the correct choice is VECTOR_DISTANCE and order by distance ascending . The requirement is to build a combined weighted formula using the actual vector distance. Microsoft documents that VECTOR_DISTANCE returns the exact distance between two vectors. Since lower distance means greater similarity, ascending distance is the right direction for ranking. VECTOR_SEARCH is for ANN retrieval, but this hotspot specifically asks for a weighted formula based on distance , so VECTOR_DISTANCE is the appropriate operator.
For the keyword portion, the correct choice is CONTAINSTABLE on description and return ranked matches . Microsoft documents that CONTAINSTABLE returns a RANK column from 0 through 1000 , which is exactly what is needed for weighted scoring in a hybrid formula.
For the final ranking expression, the best choice is order by (distance * 0.6) + ((1.0 - RANK/1000.0) * 0.4) .
This works because vector distance is a lower-is-better metric, while full-text RANK is a higher-is-better metric. Dividing RANK by 1000 normalizes it to the documented range, and subtracting from 1.0 converts it into a lower-is-better term so both components can be combined consistently in one ascending score. This final step is a sound inference based on Microsoft's documented distance semantics and full-text rank range.
NEW QUESTION # 35
You have an Azure SQL database that supports an AI-driven product search API.
You need to identify the top CPU-consuming queries from the last two hours by using Query Store data. The solution must aggregate CPU consumption across executions and return only the top 15 query hashes.
How should you complete the Transact-SQL code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all.
NOTE: Each correct selection is worth one point.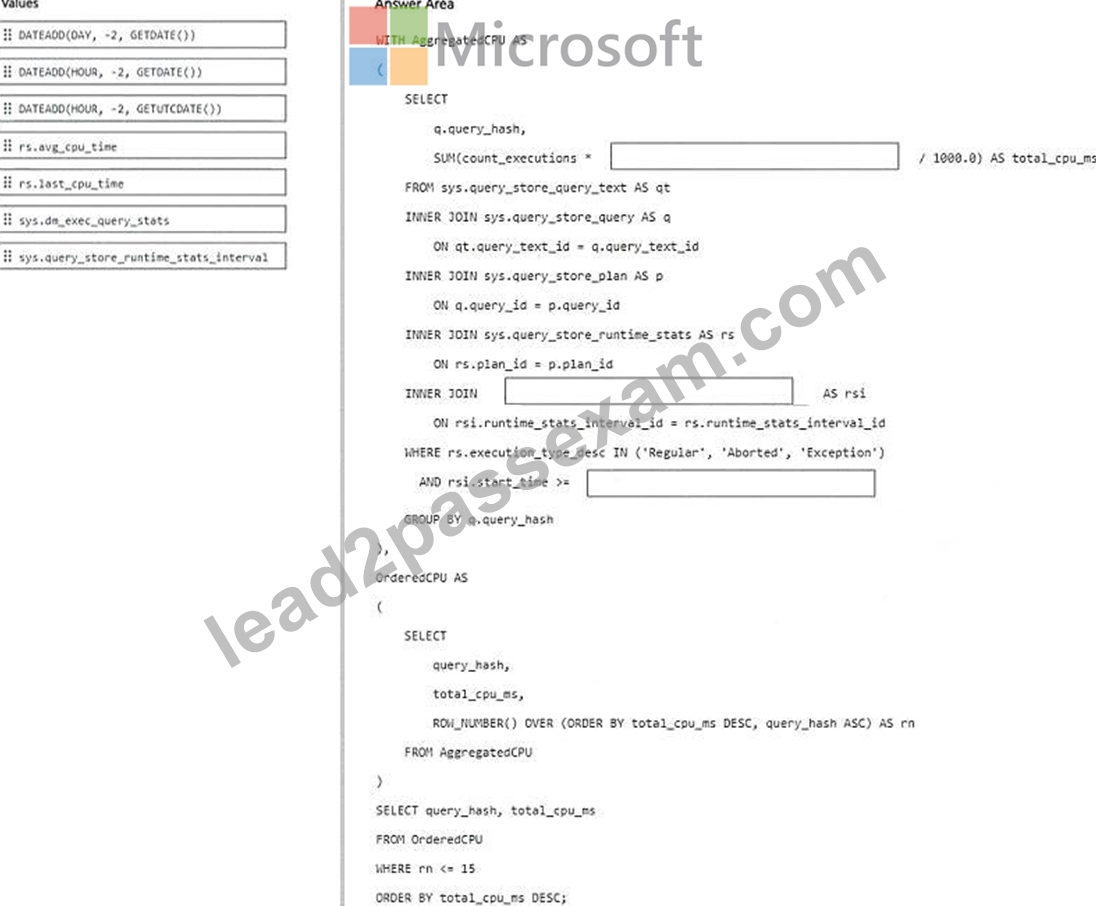
Answer:
Explanation: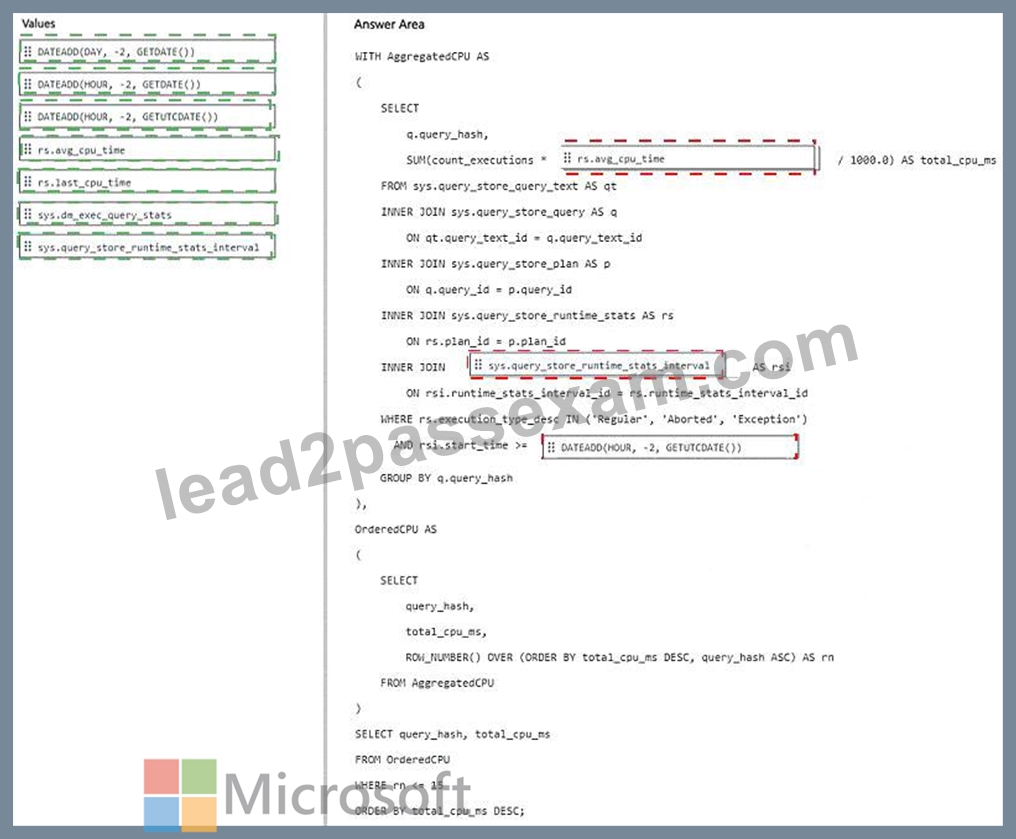
Explanation:
Verified Answer : =
* CPU aggregation expression # rs.avg_cpu_time
* Runtime interval source # sys.query_store_runtime_stats_interval
* Last two hours filter # DATEADD(HOUR, -2, GETUTCDATE())
Comprehensive and Detailed Explanation with all Developing AI-Enabled Database Solutions documents : = The first correct selection is rs.avg_cpu_time . Query Store stores CPU statistics per aggregation interval, and Microsoft documents avg_cpu_time as the average CPU time per execution, in microseconds . To calculate total CPU consumption across all executions, multiply count_executions by avg_cpu_time , then divide by
1000.0 to convert microseconds to milliseconds:
SUM(count_executions * rs.avg_cpu_time / 1000.0)
This is the exact pattern Microsoft uses in its documented query for identifying the top 15 CPU-consuming queries by query hash .
The second selection is sys.query_store_runtime_stats_interval because sys.query_store_runtime_stats.
runtime_stats_interval_id is a foreign key to this view. The interval view provides start_time and end_time , allowing Query Store data to be limited to the required time window.
The third selection is DATEADD(HOUR, -2, GETUTCDATE()) . Microsoft's own Azure SQL performance- monitoring example for the last two hours uses exactly:
rsi.start_time > = DATEADD(HOUR, -2, GETUTCDATE())
and then ranks by total CPU descending to return the top 15 query hashes.
Final drag-and-drop selections:
* First target: rs.avg_cpu_time
* Second target: sys.query_store_runtime_stats_interval
* Third target: DATEADD(HOUR, -2, GETUTCDATE())
NEW QUESTION # 36
......
Actual Microsoft DP-800 exam questions in our PDF format are ideal for restrictions-free quick preparation for the test. Microsoft DP-800 Real exam questions which are available for download in PDF format can be printed and studied in a hard copy format. Our Developing AI-Enabled Database Solutions (DP-800) PDF file of updated exam questions is compatible with smartphones, laptops, and tablets. Therefore, you can use this Developing AI-Enabled Database Solutions PDF to prepare for the test without limits of time and place.
Reliable DP-800 Exam Answers: https://www.lead2passexam.com/Microsoft/valid-DP-800-exam-dumps.html