Certified-Data-Engineer-Professional Exam Questions & Certified-Data-Engineer-Professional New Dumps Free

With our outstanding Certified-Data-Engineer-Professional exam questions, we can assure you a 99% percent pass rate. Due to continuous efforts of our experts, we have exactly targeted the content of the Certified-Data-Engineer-Professional exam. You will pass the exam after 20 to 30 hours' learning with our Certified-Data-Engineer-Professional Study Material. Many users have witnessed the effectiveness of our Certified-Data-Engineer-Professional guide exam you surely will become one of them. Try it right now!
| Section | Objectives |
|---|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Apply Change Data Feed to address streaming table limitations and improve latency
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 7. Create pipeline components using control flow operators such as if/else and foreach
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
>> Certified-Data-Engineer-Professional Exam Questions <<
Top Certified-Data-Engineer-Professional Exam Questions | High Pass-Rate Certified-Data-Engineer-Professional New Dumps Free: Databricks Certified Data Engineer Professional
Get the test Certified-Data-Engineer-Professional certification requires the user to have extremely high concentration will all test sites in mind, and this is definitely a very difficult. Our Certified-Data-Engineer-Professional learning questions can successfully solve this question for you for the content are exactly close to the changes of the Certified-Data-Engineer-Professional Real Exam. When you grasp the key points, nothing will be difficult for you anymore. Our professional experts are good at compiling the Certified-Data-Engineer-Professional training guide with the most important information. Believe in us, and your success is 100% guaranteed!
Databricks Certified Data Engineer Professional Sample Questions (Q175-Q180):
NEW QUESTION # 175
A table named user_ltv is being used to create a view that will be used by data analysts on various teams. Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed:
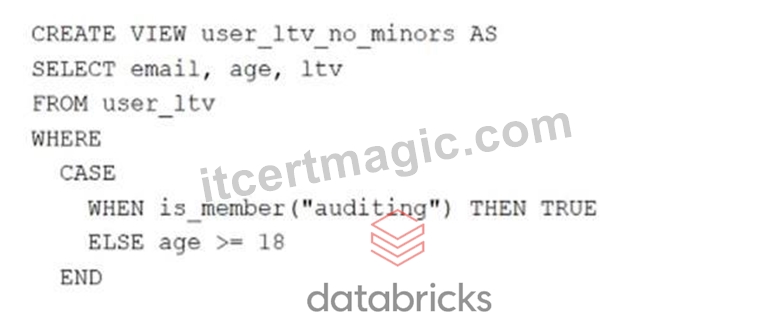
An analyst who is not a member of the auditing group executes the following query:
SELECT * FROM user_ltv_no_minors
Which statement describes the results returned by this query?
- A. All age values less than 18 will be returned as null values all other columns will be returned with the values in user_ltv.
- B. All columns will be displayed normally for those records that have an age greater than 17; records not meeting this condition will be omitted.
- C. All columns will be displayed normally for those records that have an age greater than 18; records not meeting this condition will be omitted.
- D. All records from all columns will be displayed with the values in user_ltv.
- E. All values for the age column will be returned as null values, all other columns will be returned with the values in user_ltv.
Answer: C
Explanation:
Given the CASE statement in the view definition, the result set for a user not in the auditing group would be constrained by the ELSE condition, which filters out records based on age. Therefore, the view will return all columns normally for records with an age greater than 18, as users who are not in the auditing group will not satisfy the is_member('auditing') condition. Records not meeting the age > 18 condition will not be displayed.
NEW QUESTION # 176
A data engineer is performing a join operation to combine values from a static userlookup table with a streaming DataFrame streamingDF.
Which code block attempts to perform an invalid stream-static join?
- A. streamingDF.join(userLookup, ["user_id"], how="outer")
- B. streamingDF.join(userLookup, ["userid"], how="inner")
- C. streamingDF.join(userLookup, ["user_id"], how="left")
- D. userLookup.join(streamingDF, ["userid"], how="inner")
- E. userLookup.join(streamingDF, ["user_id"], how="right")
Answer: A
Explanation:
https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html#support-matrix-for-joins-in-streaming-queries
NEW QUESTION # 177
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date. Which operation lacks support for cluster on write?
- A. spark.write.format('delta').mode('append')
- B. INSERT INTO operations
- C. spark.writestream.format('delta').mode('append')
- D. CTAS and RTAS statements
Answer: C
Explanation:
Delta Lake's Liquid Clustering is an advanced feature that improves query performance by dynamically clustering data without requiring costly compaction steps like traditional Z-ordering.
When performing writes to a Liquid Clustered table, some write operations automatically maintain clustering, while others do not.
NEW QUESTION # 178
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs UI. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can Read
- B. Can Manage
- C. No permissions
- D. Can Run
- E. Can Edit
Answer: A
NEW QUESTION # 179
A data engineering team needs to create a SQL Alert that monitors data quality across multiple columns in their customer table. They want to trigger an alert when both the percentage of customers with missing email addresses exceeds 15% AND the percentage of customers with invalid phone number formats exceeds 10%. Which SQL query pattern is appropriate for implementing this multi-column alert condition?
- A. SELECT CASE WHEN email_null_pct >15 AND phone_invalid_pct> 10 THEN 1 ELSE 0 END FROM (SELECT (COUNT (CASE WHEN email IS NULL THEN 1 END) * 100.0 / COUNT (*)) as phone_invalid_pct FROM customers) metrics
- B. SELECT email_null_pct, phone_invalid_pct FROM (SELECT (COUNT(CASE WHEN email IS NULL THEN 1 END) *
100.0/COUNT (*)) as email_null_pct, (COUNT(CASE WHEN phone NOT RLIKE 'ˆ[0-9-+()\\s]+$' THEN 1 END)*
100.0/COUNT (*)) as phone_invalid_pct FROM customers) - C. SELECT COUNT (*) FROM customers WHERE email IS NULL OR phone_format_invalid = true
- D. SELECT email, phone FROM customers WHERE email IS NULL AND phone NOT RLIKE 'ˆ[0-9-
+()\\s]+$'
Answer: B
Explanation:
This pattern computes independent percentage metrics for each data quality condition in a single aggregated query. By calculating the percentage of missing emails and invalid phone formats as separate columns, it enables the SQL Alert to evaluate a compound condition where both thresholds must be exceeded before triggering.
NEW QUESTION # 180
......
With "reliable credit" as the soul of our Certified-Data-Engineer-Professional study tool, "utmost service consciousness" as the management philosophy, we endeavor to provide customers with high quality service. Our service staff, who are willing to be your little helper and answer your any questions about our Certified-Data-Engineer-Professional qualification test, aim at comprehensive, coordinated and sustainable cooperation relationship with every users. Any puzzle about our Certified-Data-Engineer-Professional Test Torrent will receive timely and effective response, just leave a message on our official website or send us an e-mail at your convenience.
Certified-Data-Engineer-Professional New Dumps Free: https://www.itcertmagic.com/Databricks/real-Certified-Data-Engineer-Professional-exam-prep-dumps.html
- Take Your Databricks Certified-Data-Engineer-Professional Practice Exam In Different Formats 🏑 Easily obtain ➡ Certified-Data-Engineer-Professional ️⬅️ for free download through ✔ www.validtorrent.com ️✔️ 👐Certified-Data-Engineer-Professional Detail Explanation
- Latest Certified-Data-Engineer-Professional Dumps Ebook 😥 Certified-Data-Engineer-Professional Latest Real Exam 🍽 Certified-Data-Engineer-Professional New Exam Materials 🧡 Enter ( www.pdfvce.com ) and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download for free 🛂Latest Certified-Data-Engineer-Professional Dumps Ebook
- Question Certified-Data-Engineer-Professional Explanations 💏 New Certified-Data-Engineer-Professional Practice Questions 😹 Certified-Data-Engineer-Professional New Exam Materials 🧞 Simply search for ☀ Certified-Data-Engineer-Professional ️☀️ for free download on 《 www.validtorrent.com 》 🍢Certified-Data-Engineer-Professional New Exam Materials
- Certified-Data-Engineer-Professional Sure-Pass Learning Materials: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Pass-Sure Torrent - Certified-Data-Engineer-Professional Exam Braindumps 😭 Easily obtain “ Certified-Data-Engineer-Professional ” for free download through ⏩ www.pdfvce.com ⏪ 💞Pdf Certified-Data-Engineer-Professional Files
- Best Databricks Certified-Data-Engineer-Professional Exam Questions Professionally Researched by Databricks Certified Trainers 🛢 Easily obtain ( Certified-Data-Engineer-Professional ) for free download through ▛ www.torrentvce.com ▟ 🌶New Certified-Data-Engineer-Professional Braindumps Free
- Pass Guaranteed Quiz 2026 Newest Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Questions 🏴 Download { Certified-Data-Engineer-Professional } for free by simply searching on ▷ www.pdfvce.com ◁ ⬅Latest Certified-Data-Engineer-Professional Test Pass4sure
- Pdf Certified-Data-Engineer-Professional Files 🚻 Test Certified-Data-Engineer-Professional Pass4sure 🆖 Test Certified-Data-Engineer-Professional Simulator Online 🕷 ➠ www.examcollectionpass.com 🠰 is best website to obtain ▷ Certified-Data-Engineer-Professional ◁ for free download 🍙Test Certified-Data-Engineer-Professional Online
- Test Certified-Data-Engineer-Professional Simulator Online 👣 New Certified-Data-Engineer-Professional Test Preparation 📢 Question Certified-Data-Engineer-Professional Explanations 🧎 Search for ▷ Certified-Data-Engineer-Professional ◁ and obtain a free download on “ www.pdfvce.com ” 📐Test Certified-Data-Engineer-Professional Online
- Get Databricks Certified-Data-Engineer-Professional Practice Test For Quick Preparation (2026) 🍡 Enter ➽ www.testkingpass.com 🢪 and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 💘Certified-Data-Engineer-Professional New Exam Materials
- Certified-Data-Engineer-Professional Test Collection Pdf 👳 Latest Certified-Data-Engineer-Professional Dumps Ebook 👟 Certified-Data-Engineer-Professional Associate Level Exam 📈 Search for ➥ Certified-Data-Engineer-Professional 🡄 and obtain a free download on ➤ www.pdfvce.com ⮘ 💔New Certified-Data-Engineer-Professional Braindumps Free
- Pdf Certified-Data-Engineer-Professional Files 😼 New Certified-Data-Engineer-Professional Braindumps Free 😇 Test Certified-Data-Engineer-Professional Online 🎏 Go to website ➥ www.practicevce.com 🡄 open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 👇Certified-Data-Engineer-Professional New Exam Materials
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes