As the employment situation becoming more and more rigorous, it’s necessary for people to acquire more DP-750 skills and knowledge when they are looking for a job. Enterprises and institutions often raise high acquirement for massive candidates, and aim to get the best quality talents. Thus a high-quality DP-750 Certification will be an outstanding advantage, especially for the employees, which may double your salary, get you a promotion. So choose us, choose a brighter future.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
Our DP-750 learning materials are carefully compiled by industry experts based on the examination questions and industry trends. You don't have to worry about our learning from DP-750 exam question. We assure you that our DP-750 learning materials are easy to understand and use the fewest questions to convey the most important information. As long as you follow the steps of our DP-750 Quiz torrent, your mastery of knowledge will be very comprehensive and you will be very familiar with the knowledge points. This will help you pass the exam more smoothly.
NEW QUESTION # 11
You have an Azure Databricks workspace named Workspace1 that contains a takehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a new native catalog in Unity Catalog. Does this meet the goal?
Answer: B
Explanation:
The correct answer is B - No.
A native catalog in Unity Catalog is a standard Databricks-managed catalog. Creating one provisions a metadata namespace inside Unity Catalog, but it has no connection whatsoever to DB1 or any external SQL Server database. There is no mechanism to point a native catalog at an external database - it simply doesn't serve that purpose.
The requirement is to expose an external SQL Server's schemas and tables inside Unity Catalog without copying the data. That requires a foreign catalog, which is created through Lakehouse Federation using a registered connection to the external database. A foreign catalog acts as a read-only, virtual mirror of the external database - queries run against the live external data in place.
Creating a native catalog and then trying to manually recreate DB1's structure inside it would involve copying all the data, violating the 'data is NOT copied' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 12
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster! You need to configure Cluster1 to meet the following requirements;
* The cluster must scale up automatically when workloads increase.
* The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: D,E
Explanation:
The correct answers are C and D. Together they deliver cost-efficient autoscaling:
D (Enable autoscaling) allows the cluster to grow when workloads increase and shrink when they ease off.
This satisfies both scale-up and scale-down requirements without manual intervention.
C (Auto-termination after 30 minutes of inactivity) ensures the cluster stops entirely when no work is running, eliminating the cost of an idle cluster. This is the cheapest possible state.
Option A (disable Photon) reduces compute acceleration - that's a performance regression with no meaningful cost benefit for autoscaling. Option B (compute policy that lets users manage settings) adds governance overhead and doesn't address scaling behaviour. Option E (fixed number of workers) is the opposite of autoscaling - a static worker count that either over-provisions during quiet periods or under- provisions during peaks.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
NEW QUESTION # 13
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
Drag and Drop Question
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.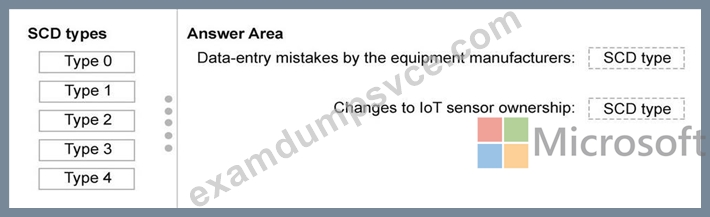
Answer:
Explanation: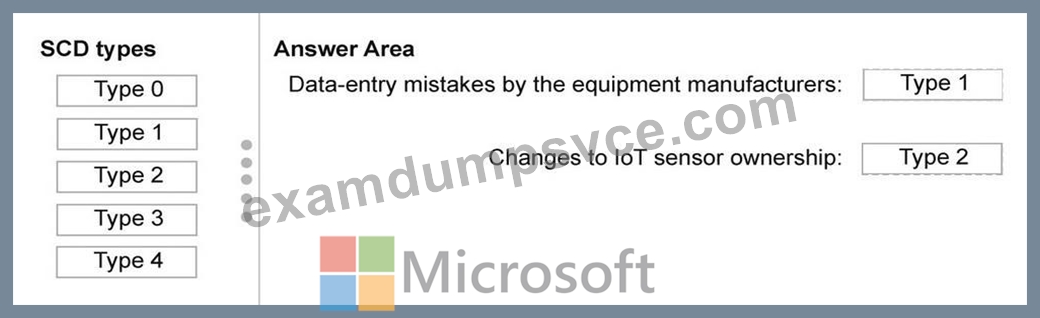
NEW QUESTION # 14
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
Ensure that amount is always greater than 0.
Prevent an update to Table1 from being committed when data that violates rule1 is detected.
Which statement should you execute?
Answer: C
Explanation:
The correct answer is C - @dlt.expect_or_fail.
Lakeflow Spark Declarative Pipelines (SDP) offers three expectation decorators, each with a different violation response:
@dlt.expect - logs the violation as a metric but writes all records, including bad ones, to the table. Suitable for monitoring only.
@dlt.expect_or_drop - drops violating records and continues the pipeline. The table receives only clean rows, but the pipeline update commits successfully.
@dlt.expect_or_fail - fails the entire pipeline update when a violation is detected. The table update is never committed. This is the correct choice when data integrity is non-negotiable: 'Prevent an update to Table1 from being committed when data that violates rule1 is detected.'
@dlt.expect_all_or_drop takes a dictionary of rules and drops violating rows but still commits - it doesn't halt the pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 15
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed.
You need to configure the job alerting behavior.
What should trigger a notification?
Answer: B
Explanation:
To achieve this, you should set a "Failure" notification at the individual task level for critical tasks only, rather than relying on a job-level notification.
Task-Level Notifications (Critical Tasks): By configuring notifications exclusively on the critical tasks for the "Failure" event status, any failure of these specific tasks will immediately send an alert. Because tasks execute within the job lifecycle, this notification inherently triggers while the job is in progress or completing its critical paths.
No Job-Level Notifications: You must not set a job-level "Failure" notification. If a non-critical task fails, it can cause the overall job status to register as a failure or "Succeeded with failures", which would erroneously trigger a job-level alert.
Handling Non-Critical Tasks: Non-critical tasks should be left without task-level failure notifications. To ensure they don't break downstream flows, you can configure downstream dependent tasks to use the "Run if: All done" or "Run if: None failed" (depending on your dependency architecture) conditional rules so the job execution continues and logs the failures automatically to the matrix view.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/jobs/notifications
NEW QUESTION # 16
......
In the information era, IT industry is catching more and more attention. In the society which has a galaxy of talents, there is still lack of IT talents. Many companies need IT talents, and generally, they investigate IT talents's ability in according to what IT related authentication certificate they have. So having some IT related authentication certificate is welcomed by many companies. But these authentication certificate are not very easy to get. Microsoft DP-750 is a quite difficult certification exams. Although a lot of people participate in Microsoft DP-750 exam, the pass rate is not very high.
Pdf DP-750 Files: https://www.examdumpsvce.com/DP-750-valid-exam-dumps.html