Braindumps Certified-Data-Engineer-Professional Downloads - Latest Certified-Data-Engineer-Professional Test Fee

Databricks Certified-Data-Engineer-Professional Exam Questions, applicants may study for and pass their desired certification exam. You may use PremiumVCEDump's top Certified-Data-Engineer-Professional study resources to prepare for the Databricks Certified Data Engineer Professional exam. The Databricks Certified-Data-Engineer-Professional Exam Questions offered by PremiumVCEDump are dependable and trustworthy sources of preparation. PremiumVCEDump provides valid exam questions and answers for customers, and free updates for 365 days.
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- Building and Testing ETL Pipelines
- 1. Develop unit and integration tests for data processing code
- 2. Use control flow operators in pipeline components
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Compare streaming tables and materialized views
- 6. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Use APPLY CHANGES APIs for change data capture
|
| Topic 2: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 3: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Topic 4: Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Topic 5: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Design and implement scalable data models using Delta Lake
- 3. Optimize data layout using Liquid Clustering
|
| Topic 6: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 7: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 8: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
- Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
|
| Topic 9: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 10: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
|
>> Braindumps Certified-Data-Engineer-Professional Downloads <<
Latest Certified-Data-Engineer-Professional Test Fee | Study Certified-Data-Engineer-Professional Dumps
Certified-Data-Engineer-Professional exam dumps allow free trial downloads. You can get the information you want to know through the trial version. After downloading our study materials trial version, you can also easily select the version you like, as well as your favorite Certified-Data-Engineer-Professional Exam Prep, based on which you can make targeted choices. Our study materials want every user to understand the product and be able to really get what they need.
Databricks Certified Data Engineer Professional Sample Questions (Q45-Q50):
NEW QUESTION # 45
The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.
A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production data. Because all users have Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.
Which statement captures best practices for this situation?
- A. In environments where interactive code will be executed, production data should only be accessible with read permissions; creating isolated databases for each environment further reduces risks.
- B. All developer, testing and production code and data should exist in a single unified workspace; creating separate environments for testing and development further reduces risks.
- C. Because delta Lake versions all data and supports time travel, it is not possible for user error or malicious actors to permanently delete production data, as such it is generally safe to mount production data anywhere.
- D. Because access to production data will always be verified using passthrough credentials it is safe to mount data to any Databricks development environment.
Answer: A
Explanation:
The best practice in such scenarios is to ensure that production data is handled securely and with proper access controls. By granting only read access to production data in development and testing environments, it mitigates the risk of unintended data modification. Additionally, maintaining isolated databases for different environments helps to avoid accidental impacts on production data and systems.
NEW QUESTION # 46
The data governance team has instituted a requirement that the "user" table containing Personal Identifiable Information (PII) must have the appropriate masking on the SSN column. This means that anyone outside of the HRAdminGroup should see masked social security numbers as ***-**-
****.
The team created a masking function:

What does the data governance team need to do next to achieve this goal?
- A. CREATE TABLE users
(name STRING, int STRING);
ALTER TABLE users ALTER COLUMN ssn CREATE MASK if is_member('HRAdminGroup'); - B. CREATE TABLE users
(name STRING, ssn STRING);
ALTER TABLE users ALTER COLUMN ssn SET MASK ssn_mask; - C. CREATE TABLE users
(name STRING, ssn INT MASKED ssn_mask); - D. CREATE TABLE users
(name STRING);
ALTER TABLE users CREATE COLUMN ssn CREATE MASK ssn_mask;
Answer: B
Explanation:
In Databricks, after creating a masking function, you apply it to a column using ALTER TABLE
<table> ALTER COLUMN <column> SET MASK <mask_function>. The table must already include the column (here, ssn as STRING). This ensures that only users in the HRAdminGroup see the unmasked SSN, while all others see the masked value.
NEW QUESTION # 47
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
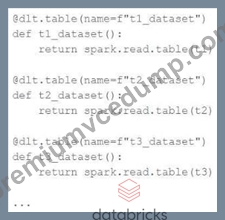
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
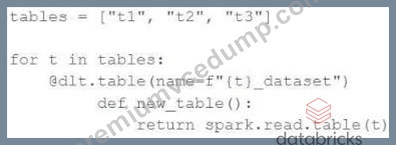
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
Answer: C
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 48
A data engineer needs to create an application that will collect information about the latest job run including the repair history. How should the data engineer format the request?
- A. Call/api/2.1/jobs/runs/list with the run_id and include_history parameters
- B. Call/api/2.1/jobs/runs/get with the run_id and include_history parameters
- C. Call/api/2.1/jobs/runs/list with the job_id and include_history parameters
- D. Call/api/2.1/jobs/runs/get with the job_id and include_history parameters
Answer: C
Explanation:
To retrieve information about the latest job runs along with their repair history, you use the jobs/runs/list endpoint with the job_id and include_history=true. This endpoint returns a list of runs for a specific job, including details about retries and repair attempts, which is not available via runs/get that retrieves a single run by run_id.
NEW QUESTION # 49
A data engineering team is setting up deployment automation. To deploy workspace assets remotely using the Databricks CLI command, they must configure it with proper authentication.
Which authentication approach will provide the highest level of security?
- A. Use a service principal ID and its OAuth client secret.
- B. Use a shared user account and its OAuth client secret.
- C. Use a service principal and its Personal Access Token.
- D. Use a service principal with OAuth token federation.
Answer: D
Explanation:
The most secure and enterprise-recommended authentication method for Databricks automation is OAuth token federation with service principals.
This configuration allows service principals (non-human identities) to authenticate using temporary OAuth access tokens from a trusted identity provider (such as Azure AD or AWS IAM federation). These tokens are short-lived and scoped, significantly reducing credential exposure risks.
By contrast, static client secrets (B) or PATs (C) are long-lived and require periodic manual rotation, increasing security vulnerability. Shared user accounts (D) violate least-privilege and auditability principles. Therefore, A provides the strongest, most compliant authentication model for automated CLI and CI/CD workflows.
NEW QUESTION # 50
......
You will receive an email attached with Certified-Data-Engineer-Professional exam study guide within 5-10 min after you pay. It means that you do not need to wait too long to get the dumps you want. Besides, you will have free access to the updated Databricks Certified-Data-Engineer-Professional study material for one year. If there is any update, our system will send the update Certified-Data-Engineer-Professional Test Torrent to your payment email automatically. Please pay attention to your payment email for the latest Databricks Certified-Data-Engineer-Professional exam dumps. If there is no any email about the update, please check your spam.
Latest Certified-Data-Engineer-Professional Test Fee: https://www.premiumvcedump.com/Databricks/valid-Certified-Data-Engineer-Professional-premium-vce-exam-dumps.html
- Pass Guaranteed Quiz 2026 Updated Databricks Certified-Data-Engineer-Professional: Braindumps Databricks Certified Data Engineer Professional Downloads 🐄 Copy URL 【 www.pdfdumps.com 】 open and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download for free 🌼Certified-Data-Engineer-Professional Valid Exam Camp Pdf
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional –High Pass-Rate Braindumps Downloads 🐔 Download 「 Certified-Data-Engineer-Professional 」 for free by simply searching on 《 www.pdfvce.com 》 🛤New Certified-Data-Engineer-Professional Exam Discount
- Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Dumps Torrent - Certified-Data-Engineer-Professional Exam Materials 🎆 Open ▛ www.troytecdumps.com ▟ enter ➽ Certified-Data-Engineer-Professional 🢪 and obtain a free download 🏎Training Certified-Data-Engineer-Professional For Exam
- Latest Certified-Data-Engineer-Professional Exam Testking 🦜 Latest Certified-Data-Engineer-Professional Exam Testking 🤸 Certified-Data-Engineer-Professional Download 💁 Copy URL ➡ www.pdfvce.com ️⬅️ open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🌕Valid Certified-Data-Engineer-Professional Exam Sims
- Ace exam on your first attempt with actual Databricks Certified-Data-Engineer-Professional questions 🤘 Download ( Certified-Data-Engineer-Professional ) for free by simply searching on ➽ www.vce4dumps.com 🢪 ⚒New Certified-Data-Engineer-Professional Exam Discount
- Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Dumps Torrent - Certified-Data-Engineer-Professional Exam Materials 📍 Search for ▷ Certified-Data-Engineer-Professional ◁ on 《 www.pdfvce.com 》 immediately to obtain a free download 🔵Latest Certified-Data-Engineer-Professional Exam Testking
- Latest Certified-Data-Engineer-Professional Exam Fee 🎥 Certified-Data-Engineer-Professional Reliable Test Labs 💯 Certified-Data-Engineer-Professional Download 🌛 Search for ( Certified-Data-Engineer-Professional ) and download exam materials for free through 【 www.pdfdumps.com 】 🎋Latest Certified-Data-Engineer-Professional Test Dumps
- Updated Databricks Certified-Data-Engineer-Professional Practice Material In 1 year 🔥 Search for 「 Certified-Data-Engineer-Professional 」 and easily obtain a free download on ☀ www.pdfvce.com ️☀️ ⬆Training Certified-Data-Engineer-Professional For Exam
- 100% Pass 2026 The Best Certified-Data-Engineer-Professional: Braindumps Databricks Certified Data Engineer Professional Downloads 🛀 Open website ⏩ www.exam4labs.com ⏪ and search for ➤ Certified-Data-Engineer-Professional ⮘ for free download 🕧Certified-Data-Engineer-Professional Reliable Guide Files
- Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Dumps Torrent - Certified-Data-Engineer-Professional Exam Materials 🏡 Immediately open ➤ www.pdfvce.com ⮘ and search for 「 Certified-Data-Engineer-Professional 」 to obtain a free download 🕑Test Certified-Data-Engineer-Professional Passing Score
- 100% Pass 2026 The Best Certified-Data-Engineer-Professional: Braindumps Databricks Certified Data Engineer Professional Downloads 🥀 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and download it for free on ⇛ www.prepawaypdf.com ⇚ website 💧Certified-Data-Engineer-Professional Test Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes