The dynamic society prods us to make better. Our services on our Microsoft AI-200 exam questions are also dependable in after-sales part with employees full of favor and genial attitude towards job. So our services around the Microsoft AI-200 Training Materials are perfect considering the needs of exam candidates all-out.
| Section | Objectives |
|---|---|
| Topic 1: Implement Azure AI solutions | - Implement knowledge mining with Azure AI Search - Implement computer vision solutions - Implement natural language processing solutions - Implement generative AI solutions using Azure OpenAI |
| Topic 2: Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Topic 3: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Plan security and compliance requirements - Monitor and optimize AI solutions |
>> Valid AI-200 Test Simulator <<
You can even print the study material and save it in your smart devices to study anywhere and pass the Developing AI Cloud Solutions on Azure (AI-200) certification exam. The second format, by Actual4test, is a web-based Developing AI Cloud Solutions on Azure (AI-200) practice exam that can be accessed online through browsers like Firefox, Google Chrome, Safari, and Microsoft Edge. You don't need to download or install any excessive plugins or Software to use the web-based software.
NEW QUESTION # 132
Drag and Drop Question
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.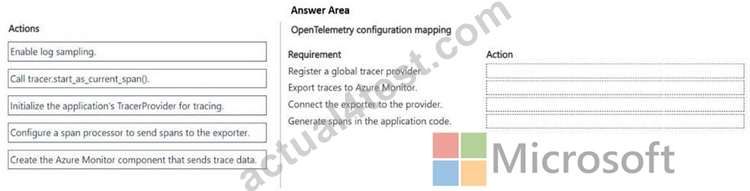
Answer:
Explanation: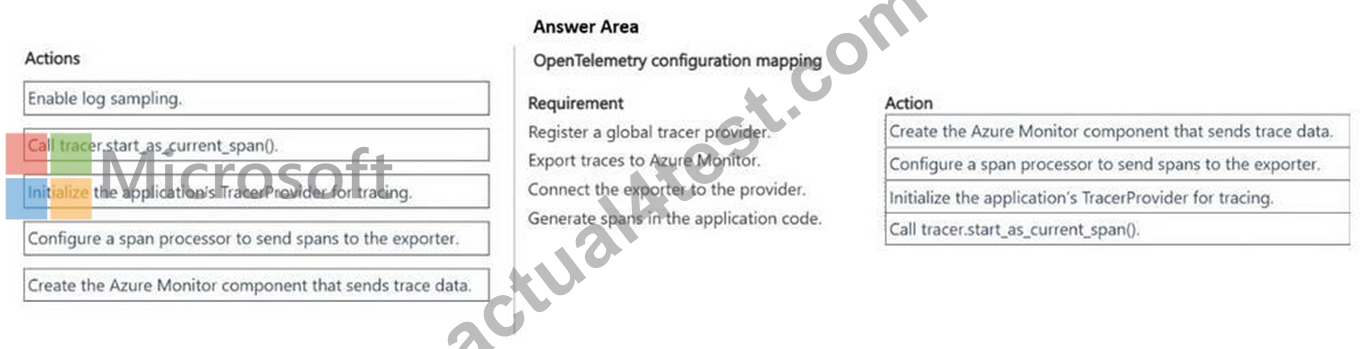
Explanation:
Box 1: Create the Azure Monitor component that sends trace data
To register a global TracerProvider in OpenTelemetry, you must call the SetTracerProvider method on the global tracer provider object, passing in your fully configured TracerProvider instance.
Box 2: Configure a span processor to send spans to the exporter
To export OpenTelemetry traces to Azure Monitor using the Python SDK, you must configure a span processor (such as BatchExportSpanProcessor), pass your initialized Azure Monitor trace exporter to it, and register that span processor with your global tracer provider.
Box 3: Initialize the application's TracerProvider for tracing
Box 4: Call tracer.start_as_current_span()
Acquire your tracer and create spans. Example code (continued from box 2 above):
tracer = trace.get_tracer(__name__)
with tracer.start_as_current_span("hello-aca-span")
Reference:
https://learn.microsoft.com/en-us/azure/durable-task/sdks/durable-task-scheduler-opentelemetry-tracing
https://learn.microsoft.com/en-us/python/api/overview/azure/monitor-opentelemetry-exporter-readme
NEW QUESTION # 133
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to configure image builds for a new service to meet the technical requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,F
Explanation:
Technical requirements, CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
The two best actions to meet the requirements are to create and configure an ACR Task with a source repository context and then push updated code to the source repository.
The core constraint explicitly dictates using ACR Tasks to automate image builds triggered by source code commits.
[D] Create and configure an ACR Task with a source repository context: This step directly establishes the automation hook. By defining the repository context (such as GitHub or Azure Repos) during task creation, Azure Container Registry is instructed exactly where to watch for code modifications.
[F] Push updated code to the source repository: Once the ACR Task is configured with the source repository context, pushing new commits acts as the native trigger. ACR automatically intercepts the commit webhook, spins up a transient cloud agent, builds the Python container image via the Dockerfile, and pushes it directly into your registry.
Reference:
https://learn.microsoft.com/en-us/azure/container-registry/container-registry-tasks-overview
NEW QUESTION # 134
You plan to deploy a web app to App Service on Linux. You create an App Service plan. You create and push a custom Docker image that contains the web app to Azure Container Registry.
You need to access the console logs generated from inside the container in real-time.
How should you complete the Azure CLI command? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.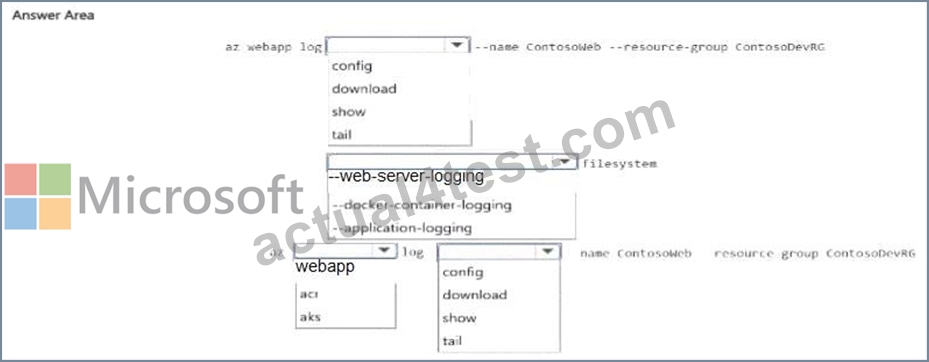
Answer:
Explanation: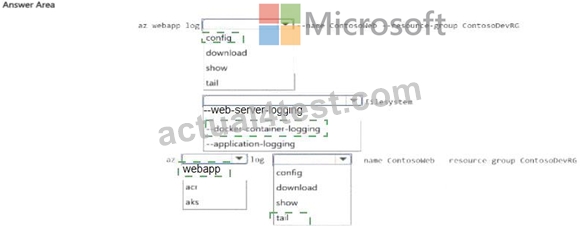
Explanation: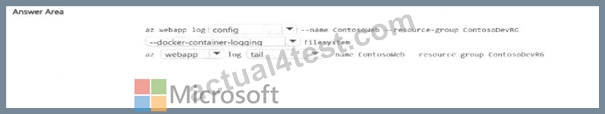
nable container logging with `az webapp log config --docker-container-logging filesystem`, then stream it with `az webapp log tail`.
Detailed Explanation: The Azure CLI exposes separate operations for enabling App Service container logging and viewing the live stream. For a custom Linux container, docker/container logging must first be written to the App Service filesystem. The `az webapp log tail` command then starts real-time log tracing.
Commands such as `show` or `download` inspect configuration or retrieve historical files; they do not provide the requested live stream from the running container.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure CLI: az webapp log
NEW QUESTION # 135
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.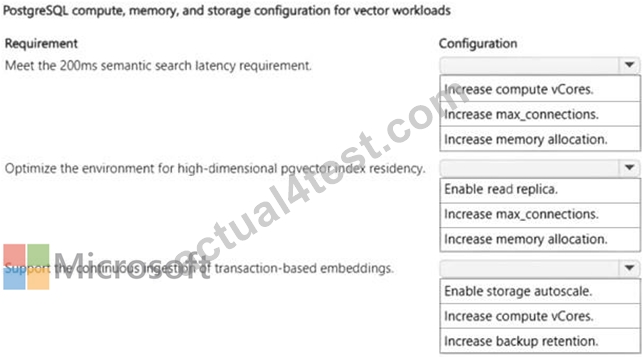
Answer:
Explanation:
Explanation:
Box 1: Increase compute vCores
Technical requirements, Performance: Semantic search latency must remain under 200 milliseconds at peak load.
To reduce semantic search latency under 200 milliseconds at peak load, the best action is to Increase compute vCores.
Vector similarity search and semantic retrieval are highly CPU-intensive operations. The math behind vector distance calculations (such as Cosine similarity, Dot Product, or Euclidean distance) relies heavily on mathematical operations executed per query. When a system experiences peak load, compute vCores easily become the primary bottleneck. Adding more vCores directly increases parallel processing capacity, dramatically shortening the execution time of similarity calculations and keeping retrieval latency within the required 200 ms SLA.
Box 2: Increase memory allocation
The best action is to increase memory allocation.
High-dimensional vector indexes (such as HNSW or IVFFlat managed by the pgvector extension) are highly resource-intensive and rely heavily on RAM. To maintain fast vector similarity searches and avoid high-latency disk operations, the entire vector index must fit into memory (RAM residency). Scaling up the database instance's memory directly expands the PostgreSQL shared buffers and cache, ensuring the high-dimensional index remains resident in RAM for rapid semantic retrieval.
Box 3: Enable storage autoscale
Enable storage autoscale is the best action to support the continuous ingestion of transaction- based embeddings.
Continuous Ingestion Demands Dynamic Space: Continuous transaction processing causes vector databases (such as Azure Database for PostgreSQL with pgvector or Azure SQL Database) to expand constantly over time.
Preventing Ingestion Failures: If storage reaches capacity limits, the database switches into a read-only state. This immediately fails and halts all incoming real-time embedding write operations. Enabling storage autoscale allows the environment to dynamically provision storage on the fly without downtime.
Reference:
https://dl.acm.org/doi/10.1145/3695053.3731013
https://learn.microsoft.com/en-us/training/paths/develop-ai-solutions-azure-database-postgresql/
https://learn.microsoft.com/en-us/azure/architecture/guide/technology-choices/vector-search
NEW QUESTION # 136
You provisioned an Azure Cosmos DB for NoSQL account named account1 with the default consistency level.
You plan to configure the consistency level on a per request basis. You plan to request Consistent Prefix consistency on a per-request basis.
You need to identify the resulting consistency level for read and write operations.
Which levels result from this configuration? To answer, select the appropriate options in the answer a rea.
NOTE: Each correct selection is worth one point.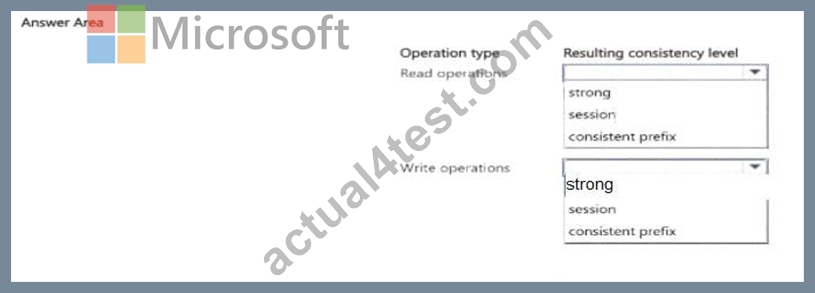
Answer:
Explanation: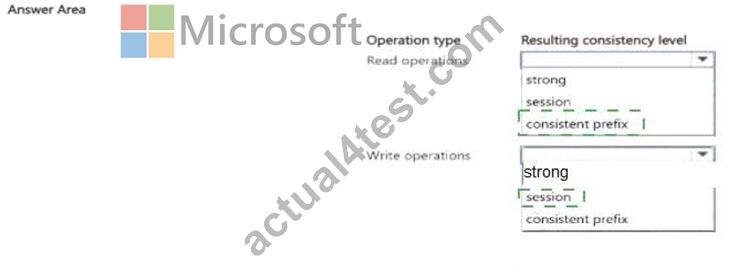
Explanation: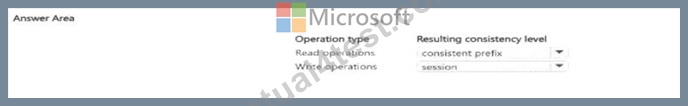
Verified answer: Read operations: Consistent Prefix. Write operations: Session (the account default remains effective for writes).
Detailed Explanation: Azure Cosmos DB allows a client or request to override consistency for reads.
Microsoft explicitly notes that such an override applies only to reads; it does not change how writes are committed and replicated under the account's configured consistency. Because a new account uses Session consistency by default, requesting Consistent Prefix affects the reads while the account continues to use its Session consistency behavior for writes. This distinction is the key point tested by the hotspot.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Manage Cosmos DB consistency levels | Cosmos DB consistency level choices
NEW QUESTION # 137
......
If you want to know our AI-200 exam questions before your coming exam, you can just visit our website. And it is easy and convenient to free download the demos of our AI-200 study guide, you just need to click on it. Then you wil find that all points of the AI-200 Learning Materials are predominantly related with the exam ahead of you. Every page is full of well-turned words for your reference related wholly with the AI-200 training prep.
Reliable AI-200 Exam Cost: https://www.actual4test.com/AI-200_examcollection.html