P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1v1vEgSVROmymBUrFOeWpGOgl_2uGcjop
Many candidates who are ready to participate in the Snowflake certification SPS-C01 exam may see many websites available online to provide resources about Snowflake certification SPS-C01 exam. However, Pass4suresVCE is the only website whose exam practice questions and answers are developed by a study of the leading IT experts's reference materials. The information of Pass4suresVCE can ensure you pass your first time to participate in the Snowflake Certification SPS-C01 Exam.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and Operations | 35% | - Advanced operations
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Performance and Best Practices | 10% | - Security and governance
|
| Snowpark API and Development | 30% | - Multi-language support
|
Our SPS-C01 exam questions are supposed to help you pass the exam smoothly. Don't worry about channels to the best SPS-C01 study materials so many exam candidates admire our generosity of offering help for them. Up to now, no one has ever challenged our leading position of this area. The existence of our SPS-C01 learning guide is regarded as in favor of your efficiency of passing the exam. And the pass rate of our SPS-C01 training braindumps is high as 98% to 100%.
NEW QUESTION # 287
You have a Python UDTF that calculates a running average from a stream of numerical data'. The UDTF's 'process' method maintains state (the running sum and count) between calls. You need to ensure that the UDTF's state is properly initialized for each new group of data processed within a Snowpark DataFrame. What are the requirements?
Answer: A,B
Explanation:
The correct answers are A and B. To ensure proper initialization, the UDTF class needs both an '__init___' method to initialize the state variables when a new instance of the UDTF is created, and a 'reset' method. The 'reset' method is crucial because it's called by Snowpark at the beginning of processing each new group of rows, allowing the UDTF to re-initialize its state for each group. Option C and D are incorrect. While end_partition' is used it's not related to state initialization. Del is for object deletion.
NEW QUESTION # 288
You've transformed a large Snowpark DataFrame and want to persist it to a Snowflake stage for downstream applications. Your requirements are: 1. The data must be written in CSV format. 2. The files must be GZIP compressed. 3. A header row should be included in each file. 4. The files should be stored in a stage named 'customer_stage' in your Snowflake database. Which of the following code snippets correctly implements this, ensuring optimal performance and resource utilization?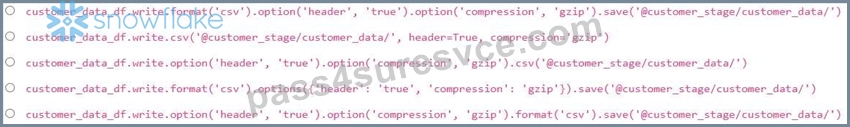
Answer: D
Explanation:
Option B provides the most concise and readable way to achieve the desired outcome using the dedicated writer method. It directly specifies the header and compression options as parameters. Options A, D, and E require specifying the file format separately using 'format('csv')' and configuring header and compression through options, which is less direct. Option C has incorrect order - it need to set format first before setting options, so its less readable.
NEW QUESTION # 289
You are developing a Snowpark application in Python to perform sentiment analysis on customer reviews stored in a Snowflake table named 'CUSTOMER_REVIEWS. The table has columns 'REVIEW ONT), 'REVIEW TEXT (VARCHAR), and 'SENTIMENT SCORE (FLOAT). You want to define a UDF using Snowpark that leverages a pre-trained sentiment analysis model from the 'nltk' library (already uploaded to a stage). The UDF should take 'REVIEW TEXT' as input and return the sentiment score. Which of the following code snippets will correctly define and register the UDF, ensuring it's accessible for use in Snowpark DataFrames, taking into account potential serialization issues with 'nltk' models?





Answer: C
Explanation:
Option E is correct because it utilizes the '@udf decorator combined with to ensure the 'nltk' library is available within the UDF's execution environment. Importantly, the analyzer is initialized within the function to avoid serialization issues, and all necessary imports are present, including specifying the data types. The nltk import is included inside the function due to the nature of the UDF and the package import. Option A is incorrect because it does not address the dependency on 'nltk' within the Snowflake environment. Option B is incorrect since the @udf decorator is not used correctly and doesn't load the dependencies correctly, and does not explicitly state the Snowflake data types. Option C is incorrect as it uses 'session.add_import' which is deprecated and not the recommended way to add packages to the session, packages option is the recommended method. Option D is incorrect since it does not explicitly state the Snowflake data types, and has the udf.register which is not a decorator, and also not a good approach.
NEW QUESTION # 290
You have a Snowpark DataFrame 'df sales' containing sales data with columns like 'order id', 'product id', 'quantity', and 'sale_price' You want to persist this data into a Snowflake table named "SALES DATA'. You also want to create a dynamic table on top of this base table for faster analytics. You need to choose the appropriate persistence strategy and consider the implications of using a dynamic table. Which of the following options represents the BEST approach?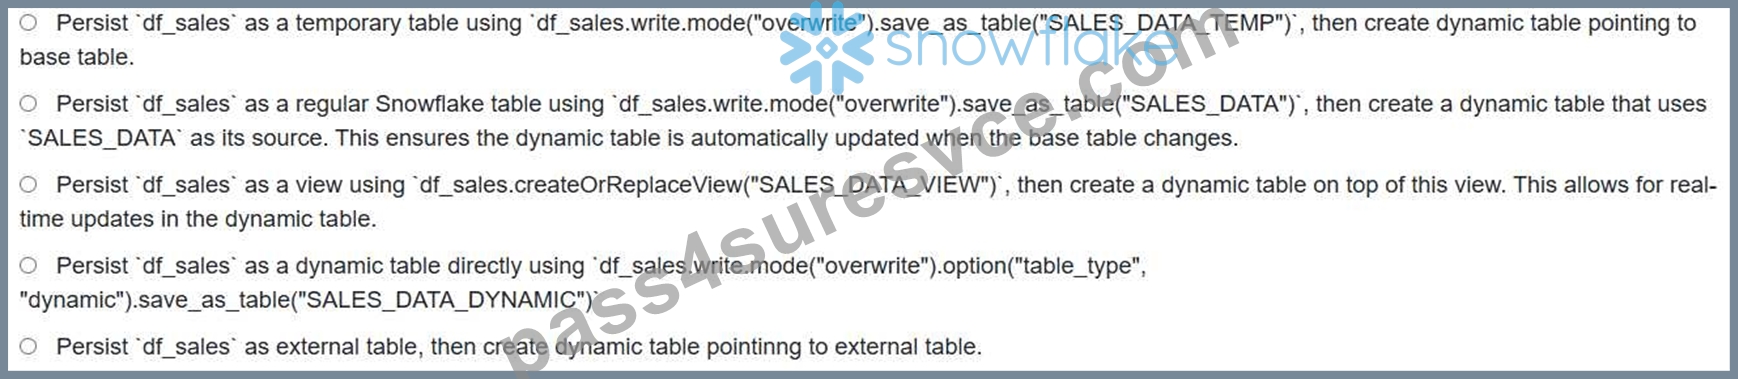
Answer: D
Explanation:
Option B is the best approach because it combines the advantages of persistence with the benefits of dynamic tables. Regular Table Persistence: Persisting as a regular table using DATA") ensures the data is stored durably in Snowflake. This serves as the foundation for the dynamic table. Dynamic Table Creation: Creating a dynamic table that uses 'SALES DATA' as its source provides a materialized view that automatically updates when the base table changes. This allows for faster analytics as the data is pre-computed and optimized for querying. Avoidance of Temporary Tables: Option A uses a temporary table, which is not suitable for long-term storage or scenarios where the data needs to persist beyond the session. Views vs. Dynamic Tables: Option C uses a view, which is not materialized. While views provide real-time access to the data, they can be slower for complex queries compared to dynamic tables. Option D isn't correct as 'table_type' is not a valid option for in Snowpark. Option E isnt valid scenario
NEW QUESTION # 291
You are developing a Snowpark Python application that reads a large dataset (1 TB) from a Snowflake table 'TRANSACTIONS and performs complex aggregations. The application is experiencing significant performance issues, with query execution taking several hours. You have already verified that the warehouse size is appropriate and caching is enabled. You suspect the issue might be related to data skew and incorrect partitioning. Which of the following strategies would be MOST effective in identifying and mitigating this performance bottleneck?
Answer: D
Explanation:
Option C is the most effective. Data skew is a common performance bottleneck. Analyzing the data distribution and using 'repartition' with the skewed column helps redistribute the data evenly across partitions. and histograms assist in identifying skewed columns. Option A might work if aggregation reduces the data size significantly, but it's not guaranteed and could lead to memory issues. Option B might not address the skew effectively if the random partitioning doesn't align with the data distribution. Option D caches the entire DataFrame, which might not fit in memory and doesn't address the skew. Option E is a brute-force approach and doesn't solve the underlying problem of data skew.
NEW QUESTION # 292
......
With our SPS-C01 exam questions, you can adjust yourself to the exam speed and stay alert according to the time-keeper that we set on our SPS-C01 training materials. Therefore, you can trust on our products for this effective simulation function will eventually improve your efficiency and assist you to succeed in the SPS-C01 Exam. If you are ready, the SPS-C01 exam will just be a piece of cake in front of you. And our SPS-C01 exam questions are the right tool to help you get ready.
Download SPS-C01 Demo: https://www.pass4suresvce.com/SPS-C01-pass4sure-vce-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Pass4suresVCE: https://drive.google.com/open?id=1v1vEgSVROmymBUrFOeWpGOgl_2uGcjop