高通過率的Databricks Certified-Data-Engineer-Professional題庫下載是行業領先材料&可靠的Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional

Certified-Data-Engineer-Professional認證考試是現今很受歡迎的考試。還沒有取得這個考試的認證資的你,肯定也想參加這個考試了吧。確實,這是一個困難的考試,但是這也並不是說不能 取得高分輕鬆通過考試。那麼,還不知道通過考試的捷徑的你,想知道技巧嗎?我現在告訴你,那就是NewDumps的Certified-Data-Engineer-Professional考古題。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Ingest data from message buses and cloud storage
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Analyze errors and remediate failed job runs
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
|
| Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Develop User-Defined Functions using Pandas/Python UDFs
- Building and Testing ETL Pipelines
- 1. Configure environments, dependencies, memory, and retry behavior
- 2. Compare streaming tables and materialized views
- 3. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Use control flow operators in pipeline components
- 7. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 8. Develop unit and integration tests for data processing code
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
>> Certified-Data-Engineer-Professional題庫下載 <<
完整包括的Certified-Data-Engineer-Professional題庫下載 |第一次嘗試輕鬆學習並通過考試和一流的Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional
NewDumps的專家團隊為了滿足以大部分IT人士的需求,他們利用自己的經驗和知識努力地研究過去的幾年的Databricks Certified-Data-Engineer-Professional 認證考試題目,如此,NewDumps的最新的Databricks Certified-Data-Engineer-Professional 的模擬測試題和答案就問世了。 我們的Databricks Certified-Data-Engineer-Professional 模擬測試題及答案和真實考試的題目及答案有95%的相似性,通過NewDumps提供的測試題你可以100%通過考試。如果你沒有通過考試,NewDumps會全額退款給你。你也可以先在網上免費下載NewDumps提供的部分關於Databricks Certified-Data-Engineer-Professional 認證考試的練習題和答案作為嘗試,在你瞭解了我們的可靠性後,快將我們NewDumps提供的產品加入您的購物車吧。NewDumps將成就你的夢想。
最新的 Databricks Certification Certified-Data-Engineer-Professional 免費考試真題 (Q205-Q210):
問題 #205
A departing platform owner currently holds ownership of multiple catalogs and controls storage credentials and external locations. A data engineer has been asked to ensure continuity: transfer catalog ownership to the platform team group, delegate ongoing privilege management, and retain the ability to receive and share data via Delta Sharing. Which role must be in place to perform these actions across the metastore?
- A. Workspace Admin, because workspace admins can transfer ownership of any Unity Catalog object.
- B. Account Admin, because account admins can only create metastores but cannot change ownership of catalogs.
- C. Metastore Admin, because metastore admins can transfer ownership and manage privileges across all metastore objects, including shares and recipients.
- D. Catalog Owner, because catalog owners can transfer any object in any catalog in the metastore.
答案:C
解題說明:
Metastore Admins have the highest administrative privileges within a Unity Catalog metastore.
They can transfer ownership of any Unity Catalog object, including catalogs, schemas, tables, storage credentials, and external locations. Metastore Admins are also required to manage Delta Sharing configurations such as creating or transferring shares and recipients.
Account Admins, by contrast, only create metastores and cannot change ownership or manage Delta Sharing objects. Workspace Admins have privileges limited to workspace-level management, not cross-metastore access.
問題 #206
A data engineering team is setting up deployment automation. To deploy workspace assets remotely using the Databricks CLI command, they must configure it with proper authentication.
Which authentication approach will provide the highest level of security?
- A. Use a service principal with OAuth token federation.
- B. Use a service principal ID and its OAuth client secret.
- C. Use a service principal and its Personal Access Token.
- D. Use a shared user account and its OAuth client secret.
答案:A
解題說明:
The most secure and enterprise-recommended authentication method for Databricks automation is OAuth token federation with service principals.
This configuration allows service principals (non-human identities) to authenticate using temporary OAuth access tokens from a trusted identity provider (such as Azure AD or AWS IAM federation). These tokens are short-lived and scoped, significantly reducing credential exposure risks.
By contrast, static client secrets (B) or PATs (C) are long-lived and require periodic manual rotation, increasing security vulnerability. Shared user accounts (D) violate least-privilege and auditability principles. Therefore, A provides the strongest, most compliant authentication model for automated CLI and CI/CD workflows.
問題 #207
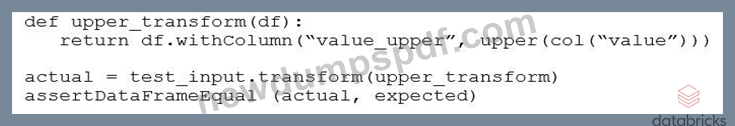
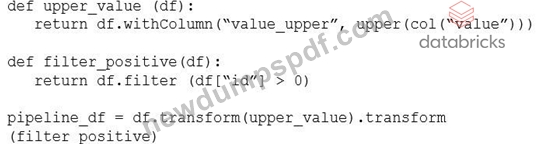
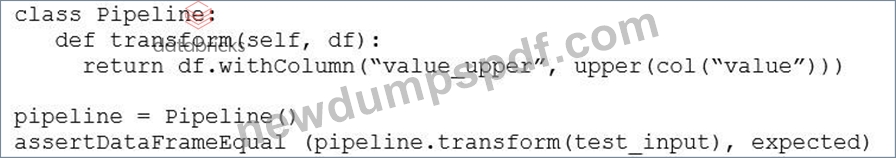
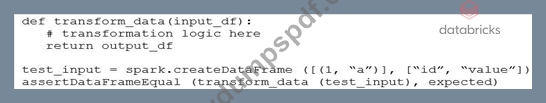
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
答案:A
解題說明:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
問題 #208
A data organization has adopted Delta Sharing to securely distribute curated datasets from a Unity Catalog-enabled workspace. The data engineering team shares large Delta tables internally via Databricks-to-Databricks and externally via Open Sharing for aggregated reports. While testing, they encounter challenges related to access control, data update visibility, and shareable object types. What is a limitation of the Delta Sharing protocol or implementation when used with Databricks-to-Databricks or Open Sharing?
- A. With Open Sharing, recipients cannot access Volumes, Models, or notebooks -- only static Delta tables are supported.
- B. With Databricks-to-Databricks sharing, Unity Catalog recipients must re-ingest data manually using COPY INTO or REST APIs.
- C. Delta Sharing (both Databricks-to-Databricks and Open Sharing) allows recipients to modify the source data if they have select privileges.
- D. Delta Sharing does not support Unity Catalog-enabled tables; only legacy Hive Metastore tables are shareable.
答案:A
解題說明:
According to Databricks' documentation, Open Sharing allows secure sharing of Delta tables to any recipient via a REST-based protocol without requiring a Databricks account. However, the Open Sharing protocol is limited to static Delta tables--it does not support sharing of Unity Catalog objects like Volumes, Machine Learning models, or notebooks. Only Databricks-to- Databricks sharing supports dynamic data sharing with update visibility and streaming reads.
Thus, the inability to share non-table objects in Open Sharing represents a known limitation of the protocol. Option A accurately reflects this constraint as described in Delta Sharing design principles and documentation.
問題 #209
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats. After converting a subset of data to Delta Lake, they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join, whereas queries on legacy formats used Sort Merge Joins. The queries reading Delta Lake data also scanned less data. Which reason could be attributed to the difference in query performance?
- A. Delta Lake enables data skipping and file pruning using a vectorized Parquet reader.
- B. Shuffle Hash Joins are always more efficient than Sort Merge Joins.
- C. The queries against the Delta Lake tables were able to leverage the dynamic file pruning optimization.
- D. The queries against the ORC tables leveraged the dynamic data skipping optimization but not the dynamic file pruning optimization.
答案:A
解題說明:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage, data skipping, and file pruning. According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters, a process called data skipping and file pruning. Additionally, Delta uses a vectorized Parquet reader, which reduces I/O and CPU overhead. Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
問題 #210
......
我們NewDumps的IT認證考題擁有多年的培訓經驗,NewDumps Databricks的Certified-Data-Engineer-Professional考試培訓資料是個值得信賴的產品,我們的IT精英團隊不斷為廣大考生提供最新版的Certified-Data-Engineer-Professional考試培訓資料,我們的工作人員作出了巨大努力,以確保你們在考試中總是取得好成績,可以肯定的是,NewDumps Databricks的Certified-Data-Engineer-Professional考試材料是為你提供最實際的IT認證材料。
Certified-Data-Engineer-Professional下載: https://www.newdumpspdf.com/Certified-Data-Engineer-Professional-exam-new-dumps.html
- 最新的Certified-Data-Engineer-Professional題庫下載 |第一次嘗試輕鬆學習並通過考試和全面覆蓋的Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional ⛳ 免費下載➠ Certified-Data-Engineer-Professional 🠰只需進入➠ www.newdumpspdf.com 🠰網站Certified-Data-Engineer-Professional考試指南
- Certified-Data-Engineer-Professional考古题推薦 🥨 Certified-Data-Engineer-Professional考試指南 😟 Certified-Data-Engineer-Professional認證指南 🧬 進入➤ www.newdumpspdf.com ⮘搜尋▷ Certified-Data-Engineer-Professional ◁免費下載Certified-Data-Engineer-Professional考試指南
- 100%合格率Certified-Data-Engineer-Professional題庫下載&認證考試的領導者材料和真實的Certified-Data-Engineer-Professional下載 📟 來自網站⇛ tw.fast2test.com ⇚打開並搜索「 Certified-Data-Engineer-Professional 」免費下載Certified-Data-Engineer-Professional考試指南
- Certified-Data-Engineer-Professional熱門證照 🏌 Certified-Data-Engineer-Professional考古题推薦 🍜 Certified-Data-Engineer-Professional考試重點 🌞 在➠ www.newdumpspdf.com 🠰網站上查找➠ Certified-Data-Engineer-Professional 🠰的最新題庫Certified-Data-Engineer-Professional更新
- 最新的Certified-Data-Engineer-Professional題庫下載 |第一次嘗試輕鬆學習並通過考試和全面覆蓋的Certified-Data-Engineer-Professional:Databricks Certified Data Engineer Professional 🔦 透過[ www.pdfexamdumps.com ]輕鬆獲取( Certified-Data-Engineer-Professional )免費下載Certified-Data-Engineer-Professional考試指南
- Certified-Data-Engineer-Professional考古题推薦 ⚓ 最新Certified-Data-Engineer-Professional題庫 🦓 最新Certified-Data-Engineer-Professional考古題 😽 進入[ www.newdumpspdf.com ]搜尋▛ Certified-Data-Engineer-Professional ▟免費下載Certified-Data-Engineer-Professional測試
- Certified-Data-Engineer-Professional題庫下載和資格考試中的領先材料供應商&Certified-Data-Engineer-Professional下載 ⚗ 來自網站【 tw.fast2test.com 】打開並搜索⇛ Certified-Data-Engineer-Professional ⇚免費下載Certified-Data-Engineer-Professional考試指南
- Certified-Data-Engineer-Professional考題資源 🍱 最新Certified-Data-Engineer-Professional題庫 🦩 Certified-Data-Engineer-Professional熱門證照 👧 複製網址⇛ www.newdumpspdf.com ⇚打開並搜索[ Certified-Data-Engineer-Professional ]免費下載Certified-Data-Engineer-Professional通過考試
- 使用Certified-Data-Engineer-Professional題庫下載 - 告別Databricks Certified Data Engineer Professional考試煩惱 😹 到【 www.newdumpspdf.com 】搜索《 Certified-Data-Engineer-Professional 》輕鬆取得免費下載Certified-Data-Engineer-Professional通過考試
- 真實的Certified-Data-Engineer-Professional題庫下載 |第一次嘗試易於學習和通過考試和權威的Databricks Databricks Certified Data Engineer Professional 📰 ⇛ www.newdumpspdf.com ⇚網站搜索⇛ Certified-Data-Engineer-Professional ⇚並免費下載Certified-Data-Engineer-Professional考試重點
- 準備充分的Databricks Certified-Data-Engineer-Professional題庫下載是行業領先材料&正確的Certified-Data-Engineer-Professional下載 🏺 ( www.kaoguti.com )提供免費⏩ Certified-Data-Engineer-Professional ⏪問題收集Certified-Data-Engineer-Professional考古題介紹
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes