Hot Official Databricks-Certified-Professional-Data-Engineer Practice Test 100% Pass | Pass-Sure Databricks-Certified-Professional-Data-Engineer Latest Test Answers: Databricks Certified Professional Data Engineer Exam

You can adjust the speed and keep vigilant by setting a timer for the simulation test. At the same time online version of Databricks-Certified-Professional-Data-Engineer test preps also provides online error correction— through the statistical reporting function, it will help you find the weak links and deal with them. Of course, you can also choose two other versions. The contents of the three different versions of Databricks-Certified-Professional-Data-Engineer learn torrent is the same and all of them are not limited to the number of people/devices used at the same time.
| Section | Weight | Objectives |
|---|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Differences between data lake, data warehouse, and lakehouse
- 2. Bronze, silver, gold data layers
- 3. Data governance fundamentals
|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Task dependencies and orchestration
- 3. Jobs and job scheduling
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. ACID transactions
- 3. Time travel and data versioning
- Delta Lake operations
- 1. Delta Live Tables
- 2. Schema evolution and enforcement
- 3. Merge, update, delete operations
|
| Data Ingestion | 15-20% | - Streaming ingestion
- 1. Structured streaming fundamentals
- 2. Kafka integration
- Batch ingestion methods
- 1. Spark APIs for ingestion
- 2. Integration with external systems
- 3. DBR autoloader
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
- Spark DataFrames and Spark SQL
- 1. Window functions
- 2. Spark SQL queries and functions
- 3. DataFrame operations and transformations
|
>> Official Databricks-Certified-Professional-Data-Engineer Practice Test <<
Databricks Databricks-Certified-Professional-Data-Engineer Latest Test Answers - Updated Databricks-Certified-Professional-Data-Engineer Demo
The passing rate of our Databricks-Certified-Professional-Data-Engineer exam materials are very high and about 99% and so usually the client will pass the exam successfully. But in case the client fails in the exam unfortunately we will refund the client immediately in full at one time. The refund procedures are very simple if you provide the Databricks-Certified-Professional-Data-Engineer exam proof of the failure marks we will refund you immediately. Clients always wish that they can get immediate use after they buy our Databricks-Certified-Professional-Data-Engineer Test Questions because their time to get prepared for the exam is limited. Our Databricks-Certified-Professional-Data-Engineer test torrent won’t let the client wait for too much time and the client will receive the mails in 5-10 minutes sent by our system. Then the client can log in and use our software to learn immediately. It saves the client’s time.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q195-Q200):
NEW QUESTION # 195
When building a DLT s pipeline you have two options to create a live tables, what is the main dif-ference between CREATE STREAMING LIVE TABLE vs CREATE LIVE TABLE?
- A. CREATE LIVE TABLE is used when working with Streaming data sources and Incremental data
- B. CREATE LIVE TABLE is used in DELTA LIVE TABLES, CREATE STREAMING LIVE can only used in Structured Streaming applications
- C. CREATE STREAMING LIVE table is used in MULTI HOP Architecture
- D. There is no difference both are the same, CREATE STRAMING LIVE will be deprecated soon
- E. CREATE STREAMING LIVE TABLE is used when working with Streaming data sources and Incremental data
Answer: E
Explanation:
Explanation
The answer is, CREATE STREAMING LIVE TABLE is used when working with Streaming data sources and Incremental data
NEW QUESTION # 196
A data engineering team has a time-consuming data ingestion job with three data sources. Each notebook takes about one hour to load new data. One day, the job fails because a notebook update introduced a new required configuration parameter. The team must quickly fix the issue and load the latest data from the failing source.
Which action should the team take?
- A. Repair the run with the new parameter.
- B. Repair the run with the new parameter, and update the task by adding the missing task parameter.
- C. Update the task by adding the missing task parameter, and manually run the job.
- D. Share the analysis with the failing notebook owner so that they can fix it quickly.
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The repair run capability in Databricks Jobs allows re-execution of failed tasks without re-running successful ones. When a parameterized job fails due to missing or incorrect task configuration, engineers can perform a repair run to fix inputs or parameters and resume from the failed state.
This approach saves time, reduces cost, and ensures workflow continuity by avoiding unnecessary recomputation. Additionally, updating the task definition with the missing parameter prevents future runs from failing.
Running the job manually (B) loses run context; (C) alone does not prevent recurrence; (D) delays resolution. Thus, A follows the correct operational and recovery practice.
NEW QUESTION # 197
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- B. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
- C. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- D. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- E. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
Answer: A
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
Thepyspark.sql.functions.broadcastfunction in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation.
In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
References:
* Databricks Documentation on Broadcast Joins: Databricks Broadcast Join Guide
* PySpark API Reference: pyspark.sql.functions.broadcast
NEW QUESTION # 198
A DLT pipeline includes the following streaming tables:
Raw_lot ingest raw device measurement data from a heart rate tracking device.
Bgm_stats incrementally computes user statistics based on BPM measurements from raw_lot.
How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?
- A. Set the SkipChangeCommits flag to true raw_lot
- B. Set the pipelines, reset, allowed property to false on raw_iot
- C. Set the skipChangeCommits flag to true on bpm_stats
- D. Set the pipelines, reset, allowed property to false on bpm_stats
Answer: B
Explanation:
In Databricks Lakehouse, to retain manually deleted or updated records in theraw_iottable while recomputing downstream tables when a pipeline update is run, the propertypipelines.reset.allowedshould be set tofalse.
This property prevents the system from resetting the state of the table, which includes the removal of the history of changes, during a pipeline update. By keeping this property as false, any changes to theraw_iot table, including manual deletes or updates, are retained, and recomputation of downstream tables, such as bpm_stats, can occur with the full history of data changes intact.
References:
* Databricks documentation on DLT pipelines: https://docs.databricks.com/data-engineering/delta-live- tables/delta-live-tables-overview.html
NEW QUESTION # 199
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
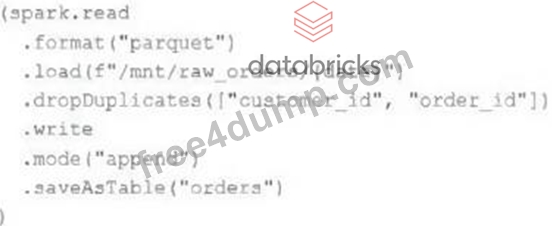
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
- B. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- C. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
- D. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- E. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
Answer: E
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "DROP DUPLICATES" section.
NEW QUESTION # 200
......
There are totally three versions of Databricks-Certified-Professional-Data-Engineer practice materials which are the most suitable versions for you: PDF, Software and APP online versions. We promise ourselves and exam candidates to make these Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Learning Materials top notch. So if you are in a dark space, our Databricks Databricks-Certified-Professional-Data-Engineer exam questions can inspire you make great improvements.
Databricks-Certified-Professional-Data-Engineer Latest Test Answers: https://www.free4dump.com/Databricks-Certified-Professional-Data-Engineer-braindumps-torrent.html
- Test Databricks-Certified-Professional-Data-Engineer Prep 🍀 Advanced Databricks-Certified-Professional-Data-Engineer Testing Engine 🤍 Databricks-Certified-Professional-Data-Engineer Reliable Test Forum 📶 Open ▷ www.prepawayete.com ◁ and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to download exam materials for free 👫Advanced Databricks-Certified-Professional-Data-Engineer Testing Engine
- Pass Guaranteed Quiz 2026 Databricks-Certified-Professional-Data-Engineer: Perfect Official Databricks Certified Professional Data Engineer Exam Practice Test 🏉 Simply search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free download on ✔ www.pdfvce.com ️✔️ 🐭Databricks-Certified-Professional-Data-Engineer Reliable Test Forum
- Databricks-Certified-Professional-Data-Engineer Latest Test Fee 💕 Databricks-Certified-Professional-Data-Engineer Pdf Version ⛪ Practice Databricks-Certified-Professional-Data-Engineer Exam Fee 🧊 Download ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free by simply entering 【 www.troytecdumps.com 】 website 🍆Valid Databricks-Certified-Professional-Data-Engineer Test Guide
- Quiz Databricks Databricks-Certified-Professional-Data-Engineer - First-grade Official Databricks Certified Professional Data Engineer Exam Practice Test 📦 Search for ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ and obtain a free download on ⇛ www.pdfvce.com ⇚ 🚆Databricks-Certified-Professional-Data-Engineer Reliable Test Forum
- Quiz Databricks Databricks-Certified-Professional-Data-Engineer - First-grade Official Databricks Certified Professional Data Engineer Exam Practice Test 🏛 Enter 《 www.testkingpass.com 》 and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 to download for free 🛂Practice Databricks-Certified-Professional-Data-Engineer Exam Fee
- Test Databricks-Certified-Professional-Data-Engineer Prep 🥼 Databricks-Certified-Professional-Data-Engineer Pdf Version 🦰 Databricks-Certified-Professional-Data-Engineer Valid Exam Sample 🎉 Download [ Databricks-Certified-Professional-Data-Engineer ] for free by simply entering [ www.pdfvce.com ] website 🥶Study Databricks-Certified-Professional-Data-Engineer Reference
- Databricks-Certified-Professional-Data-Engineer Best Vce 🤭 Test Databricks-Certified-Professional-Data-Engineer Prep 🧚 Valid Databricks-Certified-Professional-Data-Engineer Test Guide 📓 Download ▷ Databricks-Certified-Professional-Data-Engineer ◁ for free by simply searching on ⇛ www.torrentvce.com ⇚ 🧟Databricks-Certified-Professional-Data-Engineer Certificate Exam
- Advanced Databricks-Certified-Professional-Data-Engineer Testing Engine 🎒 New Guide Databricks-Certified-Professional-Data-Engineer Files 😛 Study Databricks-Certified-Professional-Data-Engineer Reference 💿 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ on ⇛ www.pdfvce.com ⇚ immediately to obtain a free download 🤐Databricks-Certified-Professional-Data-Engineer Pdf Version
- Actual Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps – Pass Exam With Good Scores 💸 Search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 and download exam materials for free through ▶ www.practicevce.com ◀ 🧼Advanced Databricks-Certified-Professional-Data-Engineer Testing Engine
- Databricks-Certified-Professional-Data-Engineer Reliable Test Forum 🌿 Databricks-Certified-Professional-Data-Engineer Reliable Test Forum 💋 Databricks-Certified-Professional-Data-Engineer Valid Test Pdf 🤶 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and easily obtain a free download on ▛ www.pdfvce.com ▟ ⬅Databricks-Certified-Professional-Data-Engineer Valid Exam Sample
- Valid Databricks-Certified-Professional-Data-Engineer Test Guide ⚖ New Databricks-Certified-Professional-Data-Engineer Test Objectives 🌠 Valid Databricks-Certified-Professional-Data-Engineer Test Guide 👷 Immediately open ▛ www.vce4dumps.com ▟ and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 to obtain a free download 🍼Databricks-Certified-Professional-Data-Engineer Certificate Exam
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes