P.S. Free & New MLA-C01 dumps are available on Google Drive shared by ActualTestsIT: https://drive.google.com/open?id=13BZrTCrR0BrXUq9MiCnzqyJL87sG-zNP
Our MLA-C01 learning torrent helps you pass the exam in the shortest time and with the least amount of effort. And MLA-C01 guide aaterials have different versions. Besides, MLA-C01 actual exam can strengthen the weaknesses of your study habit in your practicing period. Whether you are an office worker or a student or even a housewife, time is your most important resource. We are a comprehensive service platform aiming at help you to pass MLA-C01 Exams in the shortest time and with the least amount of effort.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Processing | 22% | - Data validation and quality assessment - Handling imbalanced data - Data ingestion and transformation - Data preprocessing and feature engineering - Data pipelining with AWS services ( Glue, Data Brew, etc.) |
| Topic 2: Model Deployment and Inference | 20% | - Inference optimization (latency, throughput) - Model deployment strategies (real-time, batch) - Model versioning and rollback - A/B testing and shadow mode deployment - SageMaker endpoints configuration |
| Topic 3: MLOps and Monitoring | 28% | - CI/CD pipelines for ML - Incident response and remediation - Model lineage and reproducibility - Cost optimization for ML workloads - Model monitoring and drift detection - Security and access management for ML |
| Topic 4: Model Development | 30% | - Distributed training - Algorithm selection and model architecture - Training and validation strategies - Hyperparameter optimization - Transfer learning and fine-tuning - ML frameworks (SageMaker, built-in algorithms) |
>> MLA-C01 Reliable Dumps Ebook <<
The learning material is open in three excellent formats, PDF, a desktop practice test, and a web-based practice test. Amazon MLA-C01 Dumps is organized by experts while saving the furthest down-the-line plan to them for the Amazon MLA-C01 Exam. The sans bug plans have been given to you all to drift through the Amazon MLA-C01 certification exam.
NEW QUESTION # 62
An ML engineer is setting up a CI/CD pipeline for an ML workflow in Amazon SageMaker AI. The pipeline must automatically retrain, test, and deploy a model whenever new data is uploaded to an Amazon S3 bucket.
New data files are approximately 10 GB in size. The ML engineer also needs to track model versions for auditing.
Which solution will meet these requirements?
Answer: A
Explanation:
AWS documentation identifies SageMaker Pipelines as the native CI/CD service for ML workflows. Pipelines allow engineers to define automated steps for data processing, training, evaluation, and deployment, making them ideal for retraining models when new data arrives in Amazon S3.
For version tracking and auditing, SageMaker Model Registry is explicitly designed to manage model versions, metadata, approval status, and deployment history. This satisfies regulatory and audit requirements without custom tooling.
AWS Lambda is not suitable for handling large datasets (10 GB), and CodeBuild is not ML-aware and lacks built-in model governance. Manual notebook workflows do not meet CI/CD or automation requirements.
AWS best practices strongly recommend SageMaker Pipelines combined with the Model Registry for scalable, auditable, and production-grade ML CI/CD pipelines.
Therefore, Option B is the correct and AWS-verified solution.
NEW QUESTION # 63
An ML engineer uses one ML framework to train multiple ML models. The ML engineer needs to optimize inference costs and host the models on Amazon SageMaker AI.
Which solution will meet these requirements MOST cost-effectively?
Answer: D
Explanation:
Amazon SageMaker multi-model endpoints (MME) are designed to host multiple models behind a single endpoint, dynamically loading models into memory on demand. AWS documentation explicitly recommends MME as the most cost-effective solution when multiple models share the same ML framework and inference container.
With MME, SageMaker loads models from Amazon S3 only when they are invoked and unloads idle models automatically. This dramatically reduces the number of instances required and avoids paying for always-on resources for infrequently used models.
Multi-container endpoints are intended for inference pipelines or ensembles and require all containers to be loaded at startup, which increases cost. Deploying separate endpoints for each model results in the highest cost due to duplicated infrastructure.
AWS best practices clearly position multi-model endpoints as the optimal choice for reducing inference costs when hosting many models with similar runtime requirements.
Therefore, Option B is the correct and AWS-verified solution.
NEW QUESTION # 64
A company uses a hybrid cloud environment. A model that is deployed on premises uses data in Amazon 53 to provide customers with a live conversational engine.
The model is using sensitive data. An ML engineer needs to implement a solution to identify and remove the sensitive data.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
Amazon Macie is a fully managed data security and privacy service that uses machine learning to discover and classify sensitive data in Amazon S3. It is purpose-built to identify sensitive data with minimal operational overhead. After identifying the sensitive data, you can use AWS Lambda functions to automate the process of removing or redacting the sensitive data, ensuring efficiency and integration with the hybrid cloud environment. This solution requires the least development effort and aligns with the requirement to handle sensitive data effectively.
NEW QUESTION # 65
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.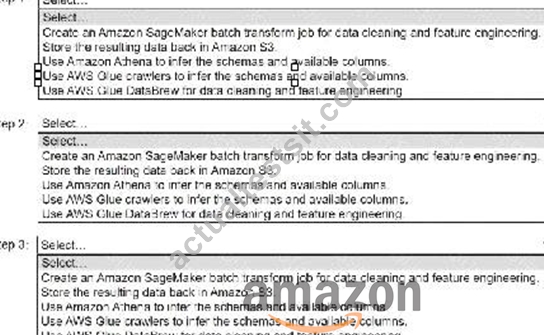
Answer:
Explanation: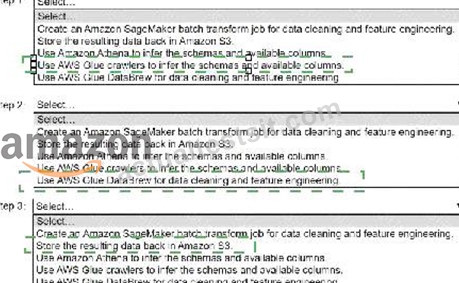
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.Step 3: Store the resulting data back in Amazon S3.
* Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
* Why?The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
* How?Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
* Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering
* Why?Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
* How?Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
* Step 3: Store the Resulting Data Back in Amazon S3
* Why?After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
* How?Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
* Use AWS Glue crawlers to infer schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 66
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token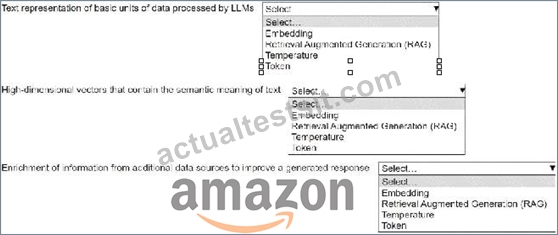
Answer:
Explanation: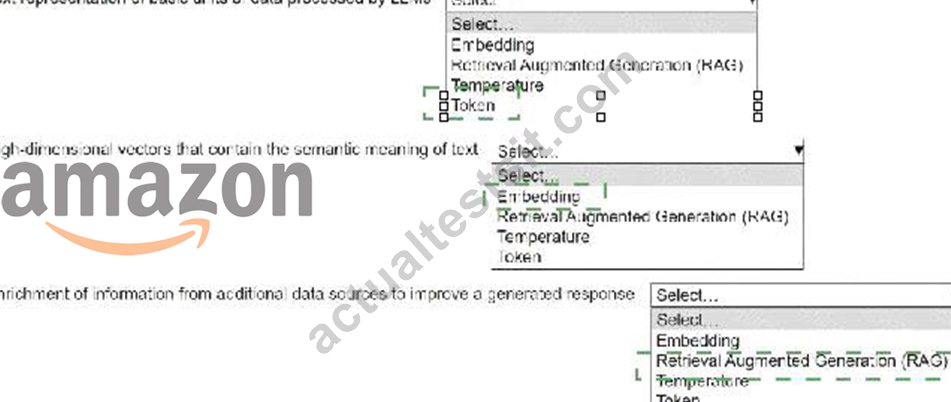
Explanation: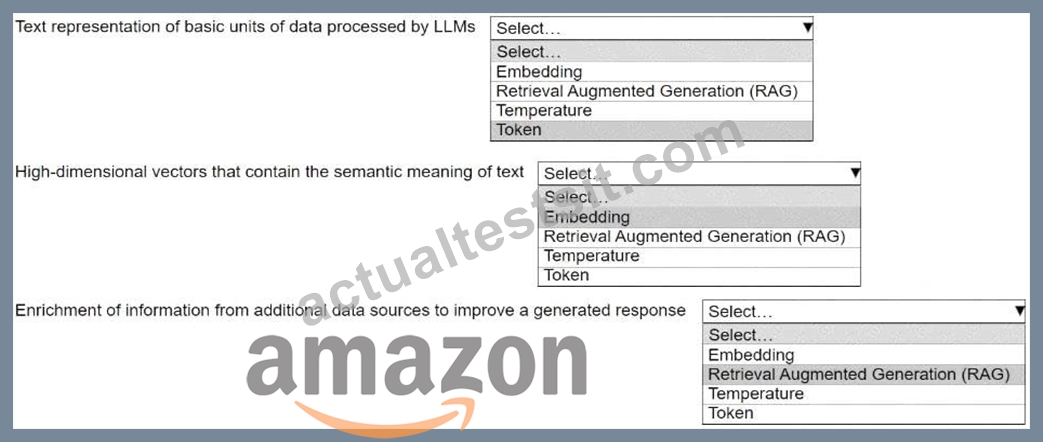
* Text representation of basic units of data processed by LLMs:Token
* High-dimensional vectors that contain the semantic meaning of text:Embedding
* Enrichment of information from additional data sources to improve a generated response:
Retrieval Augmented Generation (RAG)
Comprehensive Detailed Explanation
* Token:
* Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, "running" might be split into two tokens: "run" and "ing."
* Why?Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
* Embedding:
* Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
* Why?Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to "understand" text contextually.
* Retrieval Augmented Generation (RAG):
* Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model's generated responses.
* Why?RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to-date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 67
......
ActualTestsIT follows its motto to facilitate its consumer by providing them the material to qualify for the Amazon MLA-C01 certification exam with excellence. Therefore, it materializes its mission by giving them free of cost Amazon MLA-C01 demo of the dumps. This practical step taken by the ActualTestsIT will enable its users to assess the quality of the Amazon MLA-C01 dumps.
Valid Test MLA-C01 Tutorial: https://www.actualtestsit.com/Amazon/MLA-C01-exam-prep-dumps.html
BONUS!!! Download part of ActualTestsIT MLA-C01 dumps for free: https://drive.google.com/open?id=13BZrTCrR0BrXUq9MiCnzqyJL87sG-zNP