最新-高品質なCertified-Data-Engineer-Professional学習資料試験-試験の準備方法Certified-Data-Engineer-Professional学習教材

Certified-Data-Engineer-Professional学習テストは、シラバスの変更と、Databricks歴史的な質問や業界の動向に基づいた理論と実践の最新の進展に応じて、何百人もの専門家によって改訂された高品質の製品でした。 あなたが学生であろうとオフィスワーカーであろうと、ルーキーであろうと長年の経験を積んだベテランであろうと、Certified-Data-Engineer-Professionalガイドトレントが最適です。 Certified-Data-Engineer-Professional学習教材の主な利点は、98%以上のDatabricks Certified Data Engineer Professional高い合格率であり、Certified-Data-Engineer-Professional試験に合格するには十分です。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Configure environments, dependencies, memory, and retry behavior
- 2. Use control flow operators in pipeline components
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Compare streaming tables and materialized views
- 7. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 8. Develop unit and integration tests for data processing code
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Query Profiler and Spark UI to monitor workloads
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Data Sharing and Federation | - Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
>> Certified-Data-Engineer-Professional学習資料 <<
Certified-Data-Engineer-Professional学習教材、Certified-Data-Engineer-Professional関連資料
あなたが学生であるか、すでに仕事に参加した専門家であるかどうか、あなたは今競争の圧力を感じなければなりません。しかし、どんなに激しい競争であっても、あなたが力を持っている限り、あなたは確かに目立つことができます。良くなるのは簡単ではありません。 Certified-Data-Engineer-Professional試験の質問はあなたに助けを与えることができます。 Certified-Data-Engineer-Professional学習教材を使用した後、Certified-Data-Engineer-Professional試験にすばやく合格し、自分の強さを証明することもできます。もちろん、Certified-Data-Engineer-Professional学習教材はそれ以上のものをもたらします。 Certified-Data-Engineer-Professional試験問題の助けを借りて、より明るい未来を手に入れてください。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q80-Q85):
質問 # 80
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")
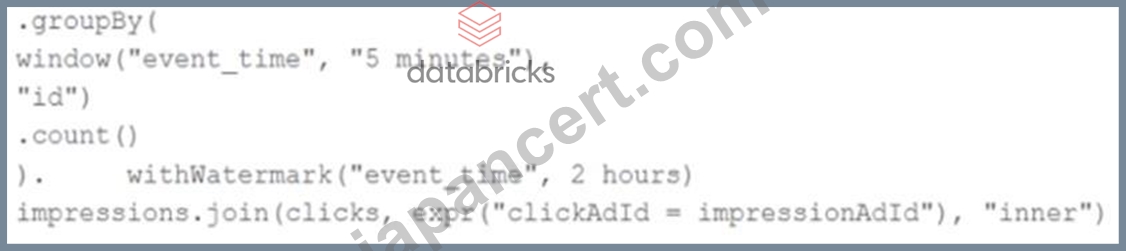
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
- A. Joining on event time constraint: clickTime >= impressionTime AND clickTime <= impressionTime interval 1 hour
- B. Joining on event time constraint: clickTime >= impressionTime - interval 3 hours and removing watermarks
- C. Joining on event time constraint: clickTime + 3 hours < impressionTime - 2 hours
- D. Joining on event time constraint: clickTime == impressionTime using a leftOuter join
正解:A
質問 # 81
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. Whenever a table is being created, make sure that the location keyword is used.
- B. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- C. When configuring an external data warehouse for all table storage. leverage Databricks for all ELT.
- D. Whenever a database is being created, make sure that the location keyword is used
- E. When tables are created, make sure that the external keyword is used in the create table statement.
正解:A
解説:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
質問 # 82
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
MERGE INTO customers
USING (
SELECT updates.customer_id as merge_ey, updates .*
FROM updates
UNION ALL
SELECT NULL as merge_key, updates .*
FROM updates JOIN customers
ON updates.customer_id = customers.customer_id
WHERE customers.current = true AND updates.address <> customers.address ) staged_updates ON customers.customer_id = mergekey WHEN MATCHED AND customers. current = true AND customers.address <> staged_updates.address THEN UPDATE SET current = false, end_date = staged_updates.effective_date WHEN NOT MATCHED THEN INSERT (customer_id, address, current, effective_date, end_date) VALUES (staged_updates.customer_id, staged_updates.address, true, staged_updates.effective_date, null) Which statement describes this implementation?
- A. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- B. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- C. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- D. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
正解:C
解説:
The provided MERGE statement is a classic implementation of a Type 2 SCD in a data warehousing context. In this approach, historical data is preserved by keeping old records (marking them as not current) and adding new records for changes. Specifically, when a match is found and there's a change in the address, the existing record in the customers table is updated to mark it as no longer current (current = false), and an end date is assigned (end_date = staged_updates.effective_date). A new record for the customer is then inserted with the updated information, marked as current. This method ensures that the full history of changes to customer information is maintained in the table, allowing for time-based analysis of customer data.
質問 # 83
A data engineer needs to design an efficient pipeline that automatically processes new CSV files as they arrive in S3 storage. Which Databricks feature should the data engineer use to meet these requirements?
- A. Streaming from cloud storage using standard Spark readStream with format ("csv") and format ("json")
- B. Auto Loader with schema inference and evolution enabled
- C. Traditional batch processing with scheduled Databricks Jobs
- D. COPY INTO SQL command with parameters to track processed files
正解:B
解説:
Auto Loader is designed to efficiently and incrementally process new files as they arrive in cloud object storage. It provides scalable file discovery, supports schema inference and evolution, and minimizes overhead compared to traditional batch or manual streaming approaches.
質問 # 84
A large company seeks to implement a near real-time solution involving hundreds of pipelines with parallel updates of many tables with extremely high volume and high velocity data.
Which of the following solutions would you implement to achieve this requirement?
- A. Configure Databricks to save all data to attached SSD volumes instead of object storage, increasing file I/O significantly.
- B. Isolate Delta Lake tables in their own storage containers to avoid API limits imposed by cloud vendors.
- C. Use Databricks High Concurrency clusters, which leverage optimized cloud storage connections to maximize data throughput.
- D. Partition ingestion tables by a small time duration to allow for many data files to be written in parallel.
- E. Store all tables in a single database to ensure that the Databricks Catalyst Metastore can load balance overall throughput.
正解:C
解説:
High Concurrency clusters in Databricks are designed for multiple concurrent users and workloads. They provide fine-grained sharing of cluster resources and are optimized for operations such as running multiple parallel queries and updates. This would be suitable for a solution that involves many pipelines with parallel updates, especially with high volume and high velocity data.
質問 # 85
......
親愛なるお客様、当社のウェブサイトにある優れた学習教材の助けを借りて試験を受ける準備ができている場合、選択は素晴らしいものになります。 Certified-Data-Engineer-Professionalトレーニング資料:Databricks Certified Data Engineer Professionalは優れた選択肢であり、特に時間をかけずに試験に合格し、成功することに熱心な方に役立ちます。 次のように、すばらしい製品を詳細に紹介する自由を考えてみましょう。
Certified-Data-Engineer-Professional学習教材: https://www.japancert.com/Certified-Data-Engineer-Professional.html
- Certified-Data-Engineer-Professional試験の準備方法|正確的なCertified-Data-Engineer-Professional学習資料試験|真実的なDatabricks Certified Data Engineer Professional学習教材 🛬 ▷ www.jpexam.com ◁で{ Certified-Data-Engineer-Professional }を検索して、無料で簡単にダウンロードできますCertified-Data-Engineer-Professional学習関連題
- Certified-Data-Engineer-Professional試験感想 👝 Certified-Data-Engineer-Professional無料試験 👖 Certified-Data-Engineer-Professional更新版 🚔 ➤ Certified-Data-Engineer-Professional ⮘を無料でダウンロード⇛ www.goshiken.com ⇚で検索するだけCertified-Data-Engineer-Professional関連資格試験対応
- Certified-Data-Engineer-Professionalソフトウエア 💦 Certified-Data-Engineer-Professional模擬対策 🤜 Certified-Data-Engineer-Professional受験準備 🙌 ▛ www.mogiexam.com ▟サイトにて☀ Certified-Data-Engineer-Professional ️☀️問題集を無料で使おうCertified-Data-Engineer-Professional技術問題
- Certified-Data-Engineer-Professional資格復習テキスト 🐋 Certified-Data-Engineer-Professional資格復習テキスト ⛅ Certified-Data-Engineer-Professional資格取得 🐔 ➠ www.goshiken.com 🠰には無料の【 Certified-Data-Engineer-Professional 】問題集がありますCertified-Data-Engineer-Professional試験感想
- 最新-素晴らしいCertified-Data-Engineer-Professional学習資料試験-試験の準備方法Certified-Data-Engineer-Professional学習教材 🧘 ⇛ www.mogiexam.com ⇚にて限定無料の⮆ Certified-Data-Engineer-Professional ⮄問題集をダウンロードせよCertified-Data-Engineer-Professional資格復習テキスト
- Certified-Data-Engineer-Professional勉強の資料 🦳 Certified-Data-Engineer-Professional受験準備 🏇 Certified-Data-Engineer-Professional資格取得 🤶 ウェブサイト➥ www.goshiken.com 🡄から⏩ Certified-Data-Engineer-Professional ⏪を開いて検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional試験感想
- Certified-Data-Engineer-Professionalソフトウエア 🧶 Certified-Data-Engineer-Professional独学書籍 🍜 Certified-Data-Engineer-Professional試験関連赤本 🍲 ウェブサイト⮆ www.goshiken.com ⮄から“ Certified-Data-Engineer-Professional ”を開いて検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional学習関連題
- Certified-Data-Engineer-Professional独学書籍 🏝 Certified-Data-Engineer-Professional資格復習テキスト Ⓜ Certified-Data-Engineer-Professional資格準備 💓 ➽ www.goshiken.com 🢪に移動し、➠ Certified-Data-Engineer-Professional 🠰を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional関連資格試験対応
- Certified-Data-Engineer-Professional更新版 🎁 Certified-Data-Engineer-Professional資格取得 🚂 Certified-Data-Engineer-Professional学習指導 🚛 ➽ www.mogiexam.com 🢪を開き、➠ Certified-Data-Engineer-Professional 🠰を入力して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional更新版
- Certified-Data-Engineer-Professional更新版 ⚖ Certified-Data-Engineer-Professionalソフトウエア 🔙 Certified-Data-Engineer-Professional更新版 ⬅ ウェブサイト➽ www.goshiken.com 🢪から▛ Certified-Data-Engineer-Professional ▟を開いて検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional更新版
- Certified-Data-Engineer-Professional資格準備 🩺 Certified-Data-Engineer-Professionalソフトウエア 🐁 Certified-Data-Engineer-Professional試験感想 ☕ 今すぐ“ www.passtest.jp ”で☀ Certified-Data-Engineer-Professional ️☀️を検索し、無料でダウンロードしてくださいCertified-Data-Engineer-Professional模擬対策
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, mayagriffiths253.blogspot.com, link.woomy.me, findaspring.org, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.zazzle.com, Disposable vapes