Highly Rated Databricks Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional PDF Dumps

You many attend many certificate exams but you unfortunately always fail in or the certificates you get can’t play the rules you wants and help you a lot. So what certificate exam should you attend and what method should you use to let the certificate play its due rule? You should choose the test Certified-Data-Engineer-Professionalcertification and buys our Certified-Data-Engineer-Professional study materials to solve the problem. Passing the test Certified-Data-Engineer-Professionalcertification can help you increase your wage and be promoted easily and buying our Certified-Data-Engineer-Professional study materials can help you pass the test smoothly.
| Section | Objectives |
|---|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 3. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 4. Create pipeline components using control flow operators such as if/else and foreach
- 5. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
>> Reliable Certified-Data-Engineer-Professional Test Topics <<
Certified-Data-Engineer-Professional Best Vce & Certified-Data-Engineer-Professional Reliable Test Syllabus
We are never complacent about our achievements, so all content are strictly researched by proficient experts who absolutely in compliance with syllabus of this exam. Accompanied by tremendous and popular compliments around the world, to make your feel more comprehensible about the Certified-Data-Engineer-Professional practice materials, all necessary questions of knowledge concerned with the exam are included into our Certified-Data-Engineer-Professional practice materials. They are conductive to your future as a fairly reasonable investment.
Databricks Certified Data Engineer Professional Sample Questions (Q129-Q134):
NEW QUESTION # 129
The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.
A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production data. Because all users have Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.
Which statement captures best practices for this situation?
- A. In environments where interactive code will be executed, production data should only be accessible with read permissions; creating isolated databases for each environment further reduces risks.
- B. All developer, testing and production code and data should exist in a single unified workspace; creating separate environments for testing and development further reduces risks.
- C. Because access to production data will always be verified using passthrough credentials it is safe to mount data to any Databricks development environment.
- D. Because delta Lake versions all data and supports time travel, it is not possible for user error or malicious actors to permanently delete production data, as such it is generally safe to mount production data anywhere.
Answer: A
Explanation:
The best practice in such scenarios is to ensure that production data is handled securely and with proper access controls. By granting only read access to production data in development and testing environments, it mitigates the risk of unintended data modification. Additionally, maintaining isolated databases for different environments helps to avoid accidental impacts on production data and systems.
NEW QUESTION # 130
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When a database is being created, make sure that the LOCATION keyword is used.
- B. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
- C. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
- D. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- E. When the workspace is being configured, make sure that external cloud object storage has been mounted.
Answer: B
Explanation:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
NEW QUESTION # 131
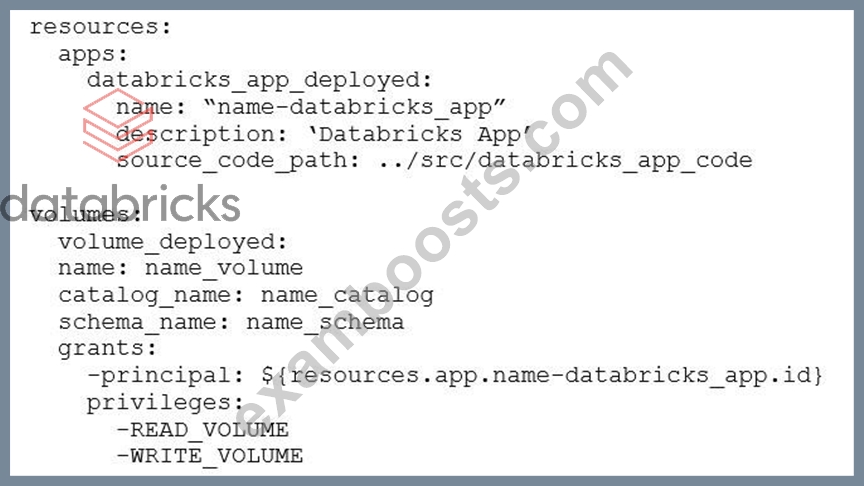
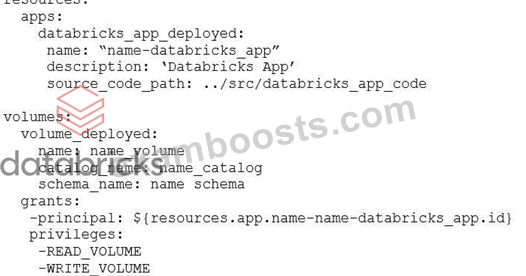
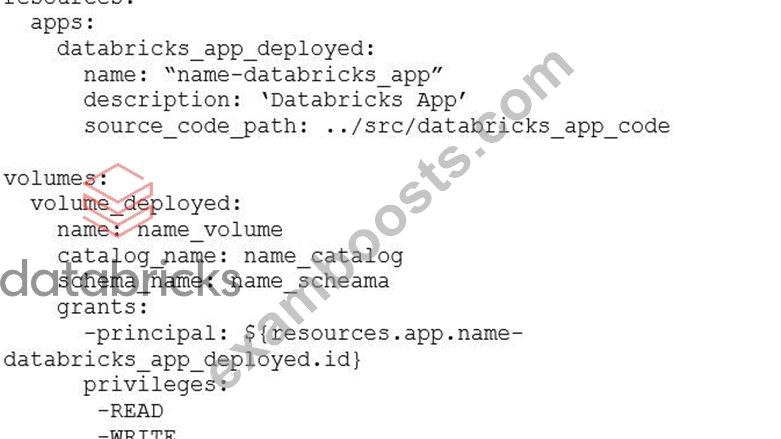
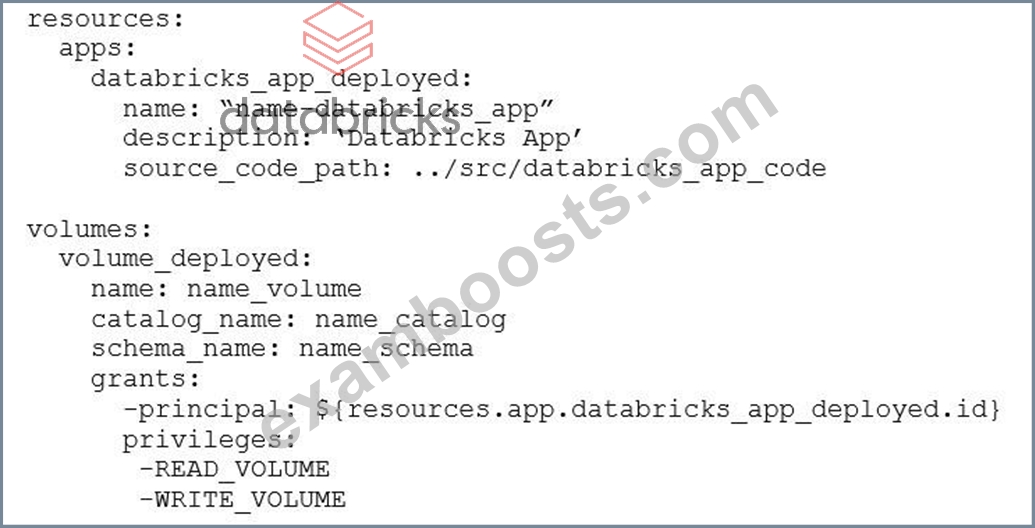
In a Databricks Asset Bundle project, in the file resources/app.yml, the data engineer would like to deploy a Databricks Apps databricks_app_deployed and Volume volume_deployed and grant the Service Principal behind Databricks Apps permissions to READ and WRITE to the Volume.
How should the data engineer achieve the deployment?
Answer: D
Explanation:
This configuration correctly references the service principal created for the Databricks App using the deployed app resource identifier, and it grants the required READ and WRITE privileges at the Volume level. The privileges are specified using the correct Volume-specific permissions, ensuring the Databricks App can securely access the Volume after deployment.
NEW QUESTION # 132
A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each microbatch of data is processed in less than 3s; at least 12 times per minute, a microbatch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution.
Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?
- A. Increase the number of shuffle partitions to maximize parallelism, since the trigger interval cannot be modified without modifying the checkpoint directory.
- B. Set the trigger interval to 3 seconds; the default trigger interval is consuming too many records per batch, resulting in spill to disk that can increase volume costs.
- C. Use the trigger once option and configure a Databricks job to execute the query every 10 minutes; this approach minimizes costs for both compute and storage.
- D. Set the trigger interval to 10 minutes; each batch calls APIs in the source storage account, so decreasing trigger frequency to maximum allowable threshold should minimize this cost.
- E. Set the trigger interval to 500 milliseconds; setting a small but non-zero trigger interval ensures that the source is not queried too frequently.
Answer: D
NEW QUESTION # 133
The data engineering team maintains the following code:
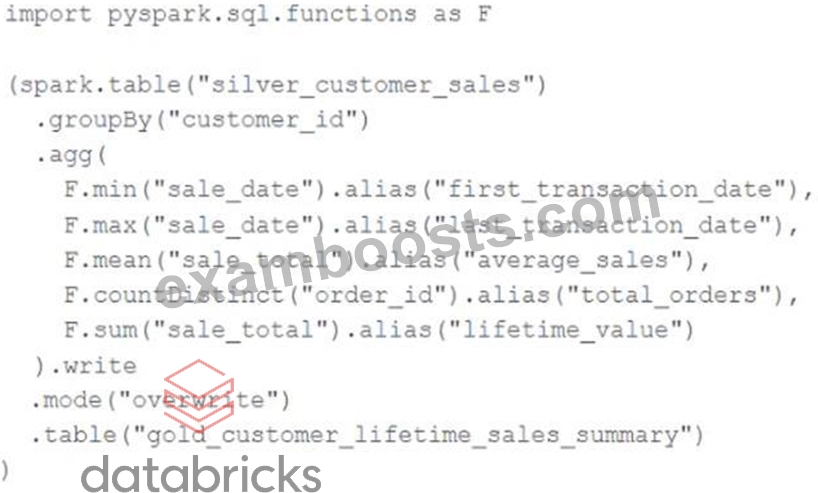
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.
- B. A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.
- C. An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.
- D. The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.
- E. An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.
Answer: D
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.
NEW QUESTION # 134
......
We have three formats of study materials for your leaning as convenient as possible. Our Databricks Certification question torrent can simulate the real operation test environment to help you pass this test. You just need to choose suitable version of our Certified-Data-Engineer-Professional guide question you want, fill right email then pay by credit card. It only needs several minutes later that you will receive products via email. After your purchase, 7*24*365 Day Online Intimate Service of Certified-Data-Engineer-Professional question torrent is waiting for you. We believe that you don’t encounter failures anytime you want to learn our Certified-Data-Engineer-Professional guide torrent.
Certified-Data-Engineer-Professional Best Vce: https://www.examboosts.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html
- Certified-Data-Engineer-Professional Reliable Test Tips 👐 Certified-Data-Engineer-Professional Latest Exam Pattern 💱 Certified-Data-Engineer-Professional Exam Questions Pdf 🚘 Download { Certified-Data-Engineer-Professional } for free by simply entering ☀ www.easy4engine.com ️☀️ website 💔Certified-Data-Engineer-Professional Reliable Learning Materials
- Certified-Data-Engineer-Professional Exam Actual Questions 🐭 Certified-Data-Engineer-Professional Latest Exam Pattern 🧎 Certified-Data-Engineer-Professional New Braindumps Free 🥮 Download ➥ Certified-Data-Engineer-Professional 🡄 for free by simply entering ➽ www.pdfvce.com 🢪 website ⭐Latest Certified-Data-Engineer-Professional Test Simulator
- 2026 Reliable Certified-Data-Engineer-Professional Test Topics 100% Pass | Professional Certified-Data-Engineer-Professional Best Vce: Databricks Certified Data Engineer Professional 📫 Copy URL ▶ www.practicevce.com ◀ open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 😋Certified-Data-Engineer-Professional Latest Exam Pattern
- Latest Certified-Data-Engineer-Professional Test Fee 😩 Certified-Data-Engineer-Professional Exam Actual Questions 🏔 Certified-Data-Engineer-Professional New Braindumps Sheet 🥄 Search for “ Certified-Data-Engineer-Professional ” on ⇛ www.pdfvce.com ⇚ immediately to obtain a free download 📝Certified-Data-Engineer-Professional Latest Version
- Perfect 100% Free Certified-Data-Engineer-Professional – 100% Free Reliable Test Topics | Certified-Data-Engineer-Professional Best Vce 🕵 Search for [ Certified-Data-Engineer-Professional ] and download exam materials for free through ✔ www.prep4sures.top ️✔️ 🛣Certified-Data-Engineer-Professional Top Questions
- Certified-Data-Engineer-Professional Latest Exam Pattern 😻 Certified-Data-Engineer-Professional Top Questions 😣 Certified-Data-Engineer-Professional Reliable Test Tips 😎 Easily obtain ✔ Certified-Data-Engineer-Professional ️✔️ for free download through ⏩ www.pdfvce.com ⏪ ⏺Certified-Data-Engineer-Professional Exam Actual Questions
- Pass Guaranteed Quiz Certified-Data-Engineer-Professional - Trustable Reliable Databricks Certified Data Engineer Professional Test Topics 🏚 Easily obtain free download of ▶ Certified-Data-Engineer-Professional ◀ by searching on [ www.examdiscuss.com ] 🚵Exam Certified-Data-Engineer-Professional Fees
- Databricks Reliable Certified-Data-Engineer-Professional Test Topics | Useful Databricks Certified-Data-Engineer-Professional Best Vce: Databricks Certified Data Engineer Professional 🔛 The page for free download of ▶ Certified-Data-Engineer-Professional ◀ on ➠ www.pdfvce.com 🠰 will open immediately 🚘Certified-Data-Engineer-Professional Latest Dumps Ppt
- Easy to Use www.testkingpass.com Databricks Certified-Data-Engineer-Professional Practice Questions Formats 👩 Download { Certified-Data-Engineer-Professional } for free by simply entering ⇛ www.testkingpass.com ⇚ website 🍎Certified-Data-Engineer-Professional Top Questions
- Databricks Certified-Data-Engineer-Professional PDF Format 🪑 Open ⏩ www.pdfvce.com ⏪ enter ⮆ Certified-Data-Engineer-Professional ⮄ and obtain a free download 🥧New Certified-Data-Engineer-Professional Exam Cram
- Certified-Data-Engineer-Professional Exam Questions Pdf 🦓 Latest Certified-Data-Engineer-Professional Test Simulator 🍢 Certified-Data-Engineer-Professional Exam Questions Pdf 😤 Search for ▶ Certified-Data-Engineer-Professional ◀ and download it for free immediately on ⮆ www.prepawaypdf.com ⮄ ⏭Latest Certified-Data-Engineer-Professional Test Fee
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, www.stes.tyc.edu.tw, Disposable vapes