What's more, part of that ActualCollection SPS-C01 dumps now are free: https://drive.google.com/open?id=1neNrcha8MJHzdfa9-Bf3nQjAE1uPLO69
While making revisions and modifications to the Snowflake SPS-C01 practice exam, our team takes reports from over 90,000 professionals worldwide to make the Snowflake SPS-C01 Exam Questions foolproof. To make you capable of preparing for the SPS-C01 exam smoothly, we provide actual Snowflake SPS-C01 exam dumps.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Topic 2: Performance and Best Practices | 10% | - Optimization techniques
|
| Topic 3: Snowpark API and Development | 30% | - Multi-language support
|
| Topic 4: Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
>> SPS-C01 Simulation Questions <<
ActualCollection gives a guarantee to our customers that they can pass the Snowflake SPS-C01 Certification Exam on the first try by preparing from the ActualCollection and if they fail to pass it despite their efforts they can claim their payment back as per terms and conditions. ActualCollection facilitates customers with a 24/7 support system which means whenever they get stuck somewhere they don't struggle and contact the support system which will assist them in the right way. A lot of students have prepared from practice material and rated it positively.
NEW QUESTION # 36
You have a Snowpark DataFrame 'df with a column 'transaction_date' of STRING type, containing dates in 'YYYY-MM-DD' format, and a 'transaction_amount' column of STRING type, containing currency values like '$1 ,234.56'. You need to create a new DataFrame 'df_transformed' that contains the 'transaction_date' as a DATE type and 'transaction_amount' as a DOUBLE type. What Snowpark Python code snippet will accomplish this transformation most efficiently and handle potential errors during the cast?
Answer: A
Explanation:
Option C is the most robust because it uses and , which handle potential conversion errors by returning NULL instead of throwing exceptions. It also correctly uses 'regexp_replace' to remove both '$ and ',' from the 'transaction_amount' string before casting. Option A doesn't handle the format string for 'to_date' or special characters in amount. Option B doesnt remove special charcaters from transaction amount.Option D will not return other existing Columns, and also it doesn't handle the format string for 'to_date' or special characters in amount. Option E will not handle errors gracefully and redundantly imports 'snowflake.snowpark.functions as sf, and it also requires providing a format string for 'to_date' .
NEW QUESTION # 37
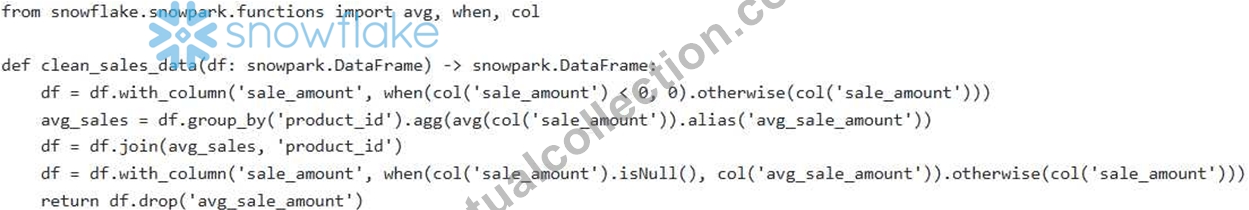
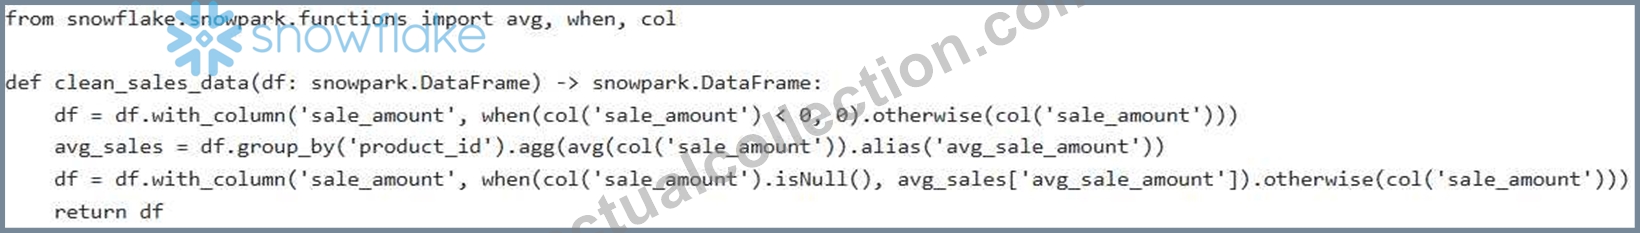
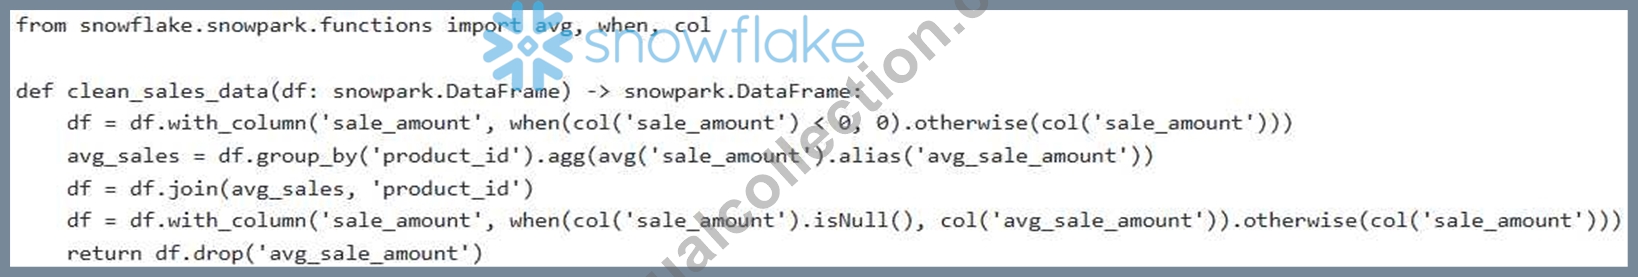
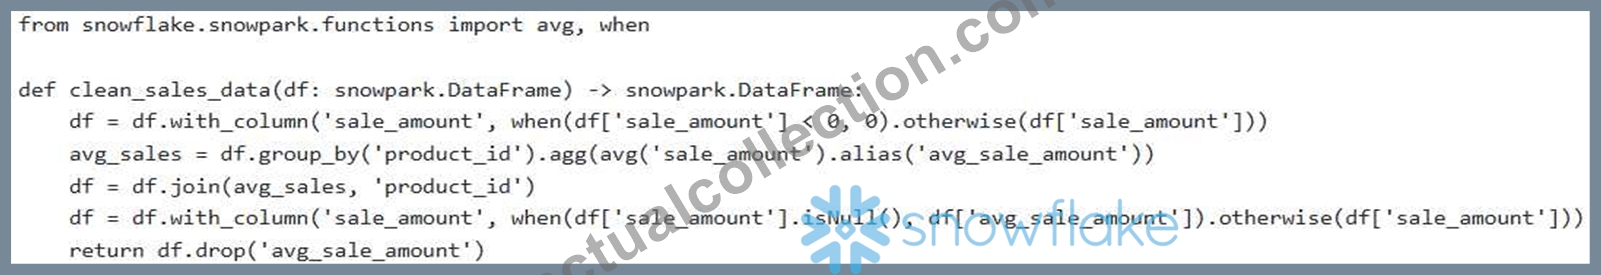
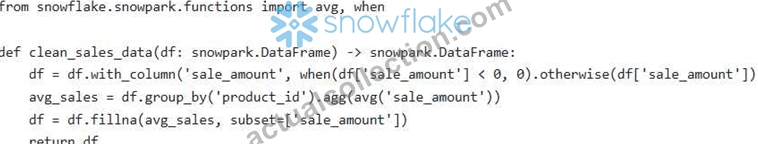
You have a Snowpark DataFrame with columns 'product_id', 'customer_id', and 'sale_amount'. Some values are negative, indicating returns, and others are null. You need to replace negative values with 0 and fill null values with the average 'sale_amount' for each 'product_id'. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark?
Answer: A
Explanation:
Option E first replaces negative values with 0. Then, it calculates the average sales amount per product and joins it back to the original DataFrame. Finally, it fills null values with the calculated average sales amount and drops the temporary column. This is efficient because it utilizes Snowpark's DataFrame operations. other options does not handle nulls or gives errors.
NEW QUESTION # 38
You are developing a Snowpark application that utilizes a DataFrame named 'transactions df containing transactional data. You need to apply a series of complex transformations, including window functions and joins with other DataFrames. To optimize performance and manage resources effectively, you want to control how Snowpark executes these operations within Snowflake. Which of the following actions or configurations would have the MOST significant impact on controlling the execution plan and resource utilization of your Snowpark application?
Answer: C
Explanation:
Option C, using to analyze the query plan and then manually optimizing the Snowpark code, would have the MOST significant impact. Understanding the query plan allows you to identify bottlenecks, skew issues, and inefficient operations. Based on the plan, you can rewrite your Snowpark code to guide Snowflake toward a more efficient execution strategy. Caching (A) can sometimes help, but it's not always beneficial and can consume resources unnecessarily if not used carefully. Enabling native execution (B) generally improves performance, but it doesn't give you direct control over the execution plan. Partitioning (D) can be helpful, but the optimal number of partitions depends on the data and the transformations being performed. Using imperative loops (E) generally defeats the purpose of using Snowpark's declarative DataFrame API, which is designed to leverage Snowflake's query optimizer and parallel processing capabilities. It will most likely be very ineficient. Therefore, analyzing the query plan is crucial for optimizing resource utilization and controlling execution.
NEW QUESTION # 39
A UDTF (User-Defined Table Function) named 'split_sentences" takes a text string as input and returns a table with each row containing a single sentence from the input. You need to grant SELECT privilege on this UDTF to a specific role, 'DATA ANALYST'. Which of the following SQL statements will achieve this?
Answer: A
Explanation:
Since UDTFs return a table, you need to grant the 'SELECT privilege on the table function to allow the role to query the results produced by the UDTF. The syntax is 'GRANT SELECT ON TABLE FUNCTION'. option A is wrong it's for UDE Options C and E provide too many privileges, potentially allowing unintended modifications. Option D is not the correct Privilege.
NEW QUESTION # 40
You are tasked with processing a Snowpark DataFrame named 'orders df that contains order information. The DataFrame includes the following columns: 'order _ id' (INTEGER), 'customer_id' (INTEGER), 'order_date' (DATE), 'order_total' (STRING), and 'discount_code' (STRING). The 'order_total' column contains values with leading dollar signs and commas (e.g., '$1 ,234.56'). The column can contain codes like 'SAVEIO', 'SAVE20', or be NULL. Your goal is to create a new DataFrame 'transformed_df that includes the following transformations: 1 . Convert the 'order_total' column to a numeric value (DOUBLE) after removing the dollar signs and commas. 2. Apply a discount based on the 'discount_code'. If the 'discount_code' is 'SAVEIO', apply a 10% discount; if it's 'SAVE20', apply a 20% discount. If the 'discount_code' is NULL or any other value, apply no discount (0%). 3. Calculate the 'final_total' after applying the discount. Which of the following code snippets correctly and efficiently implements these transformations using Snowpark?





Answer: B
Explanation:
Option A correctly implements all transformations efficiently using Snowpark functions. It converts 'order_totar to a numeric value, applies the discount based on the using 'when' , and calculates the 'final_totar. It avoids using IJDFs or 'collect' operations, which can be less efficient. Using 'lit' with numeric values isn't necessary or best practice, so option B is less preferable. Option C attempts to use a IJDF, which is less efficient than using built-in Snowpark functions. Also 'to_number' and for IJDF is not required. Option D calculates the discount amount directly instead of the discount rate. Option E attempts to use 'rdd.map' which is not available and it's generally advised against as it removes parallelism.
NEW QUESTION # 41
......
As one of the hot exam of our website, Snowflake dumps pdf has a high pass rate which reach to 85%. According to our customer's feedback, our SPS-C01 vce braindumps covers mostly the same topics as included in the real exam. So if you practice our SPS-C01 Test Questions seriously and review test answers, pass exam will be absolute.
SPS-C01 Exam Brain Dumps: https://www.actualcollection.com/SPS-C01-exam-questions.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=1neNrcha8MJHzdfa9-Bf3nQjAE1uPLO69