P.S. Free & New SPS-C01 dumps are available on Google Drive shared by BraindumpsPrep: https://drive.google.com/open?id=18MZHhL5iu-xRQli-xvJTAjJ68Dq9mrM7
All SPS-C01 exam questions are available at an affordable cost and fulfill all your training needs. BraindumpsPrep knows that applicants of the Snowflake SPS-C01 examination are different from each other. Each candidate has different study styles and that's why we offer our Snowflake SPS-C01 product in three formats. These formats are SPS-C01 PDF, desktop practice test software, and web-based practice exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts | 15% | - Snowpark architecture and core concepts - Client-side vs. Server-side execution - Stored procedures and conditional logic - Snowpark Sessions and connection management - Transformations vs. Actions - Snowpark DataFrames and query plans |
| Topic 2: Performance Optimization and Best Practices | 20% | - Warehouse sizing for Snowpark - Debugging and explain plans - Minimizing data transfer - Caching strategies - Query pushdown and optimization - Vectorized UDFs |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Using built-in functions - Window functions - Filtering, Aggregating, and Joining DataFrames - Persisting transformed data - Complex data pipelines |
| Topic 4: Snowpark API for Python | 30% | - Working with Semi-structured data - User-Defined Functions (UDFs) and Stored Procedures - Establishing connections and session management - DataFrame creation and manipulation - Reading and writing data |
To meet the needs of users, and to keep up with the trend of the examination outline, our SPS-C01 exam questions will provide customers with latest version of our products. Our company's experts are daily testing our SPS-C01 study guide for timely updates. So we solemnly promise the users, our products make every effort to provide our users with the Latest SPS-C01 Learning Materials. As long as the users choose to purchase our SPS-C01 exam preparation materials, there is no doubt that he will enjoy the advantages of the most powerful update.
NEW QUESTION # 102
You have a Snowpark DataFrame 'df containing customer data with columns 'customer_id', 'signup_date' (TIMESTAMP NTZ), and 'country'. You need to create a new DataFrame that calculates the number of days since each customer signed up, but only for customers in 'USA' and 'Canada'. Furthermore, you want to filter out records where the signup was more than 365 days ago. Which of the following Snowpark code snippets will achieve this most efficiently?





Answer: D
Explanation:
Option E is the most efficient. It first filters the DataFrame by country using 'isin' , which is optimized for multiple values. Then, it calculates 'days_since_signup' using 'datediff and finally filters based on the number of days. Option A is correct but not as efficient as using 'isin-. Option B calculates 'days_since_signup' before filtering, which is less efficient. Option C uses 'to_number' which would result in the difference being represented in milliseconds and would require further conversion. Also using 'to_number' may lead to data loss. Option D has incorrect operator precedence in the 'where' clause, making it functionally wrong.
NEW QUESTION # 103
You have a Snowpark application that processes sensor data from a large number of devices. You've implemented a scalar UDF in Python to calculate a complex statistical metric for each sensor reading. Initial tests show poor performance. Which of the following strategies would be MOST effective in improving the performance of this application, considering the nature of the computation and the data volume?
Answer: E
Explanation:
Vectorized UDFs process data in batches (vectors), significantly reducing the overhead associated with individual row processing, which is the primary bottleneck of scalar UDFs. While increasing warehouse size (C) might provide some improvement, it doesn't address the fundamental inefficiency of scalar processing. Java might be faster (A), but the biggest gain comes from vectorization. Caching (D) is useful for repeated calculations, but doesn't address the inherent UDF overhead if computations are unique. SQL (E) is good, but might not be possible due to the complexity.
NEW QUESTION # 104
You have created a Snowpark UDF that uses a custom Python module 'my_module.py', containing a function 'process data'. This module is not available through Anaconda'. You've packaged the module into a zip file named 'my module.zip'. What steps are necessary to deploy this UDF in Snowflake so that it can correctly use the 'my_module'?
Answer: A
Explanation:
Option B is correct. You need to upload the zip file to an internal stage. The 'imports' argument during UDF creation tells Snowflake to unpack the zip and make the module available. Snowflake handles adding the necessary path to 'sys.path', so no manual modification is needed within the UDF. Specifying external stages is possible, but internal stages are preferred for security and performance. Option A is incomplete (doesn't specify how the import relates to the UDF), Option C is technically feasible with external stages but is less preferable. Option D is incorrect as it unnecessary to modify sys.path. Option E specifies 'packages' argument where you would normally include packages available through Anaconda.
NEW QUESTION # 105
Consider the following Snowpark Python code snippet that defines and applies a UDF:
Which of the following modifications would MOST likely improve the performance of this code, assuming the DataFrame 'df contains a large number of rows?
Answer: C,D
Explanation:
Setting tells Snowpark to treat the UDF as a vectorized UDE However, simply setting the flag is not sufficient. E is also required because Vectorized UDF requires functions that accept and process arrays as inputs, not single scalar values. The function needs to be modified to handle arrays using NumPy or similar libraries. The code also need to be rewritten to work with arrays. B has nothing to do with performance. Increasing Warehouse size might help but not on the scale of vectorization.
NEW QUESTION # 106
A financial firm is using Snowpark Python to analyze stock trading data'. They have a DataFrame named 'trades' with columns 'trade_id', 'stock_symbol', 'trade_price', and 'trade_timestamp'. They want to identify potentially fraudulent trades based on the following criteria: 1. Trades where the 'trade_price' deviates significantly from the average price of that 'stock_symbol' over the past hour. 2. Trades originating from user accounts where the price is above $1000.3. Trades which has stock symbol 'XYZ'. The firm wants to apply multiple filters to the DataFrame to extract only the fraudulent trades and needs an efficient and concise approach using Snowpark. Which of the following code snippets, using 'trade_price' > 1000 as user identifier, MOST accurately and efficiently implements this filtering logic? Assume that a Snowflake user has a maximum amount they can spend on a trade, and therefore, the user ID is associated with 'trade_price'.
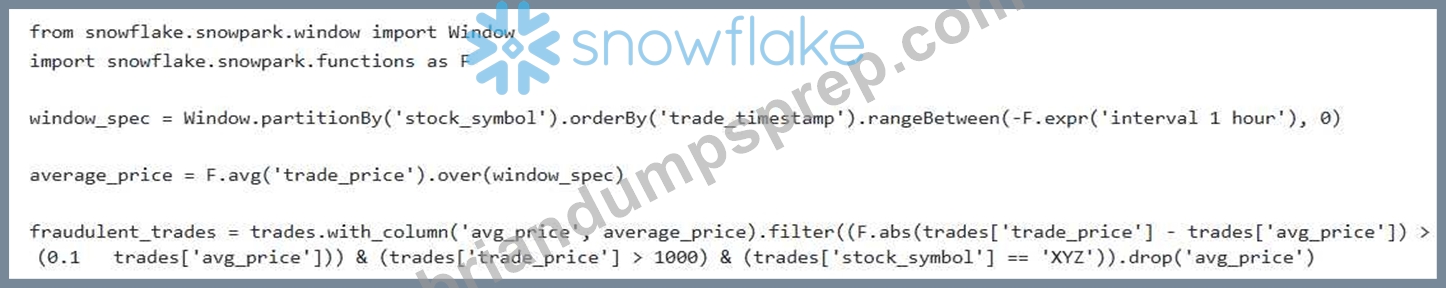
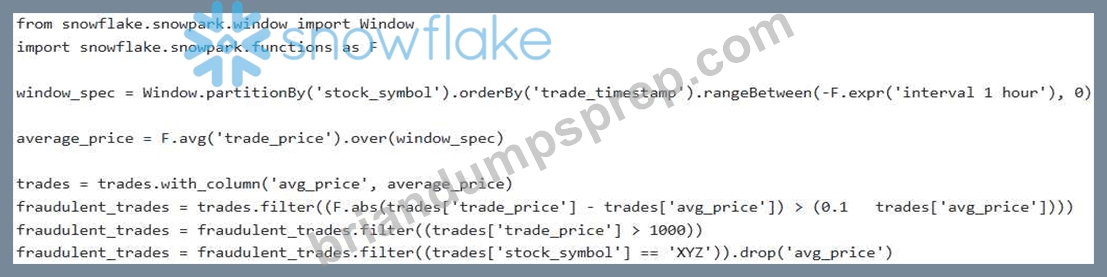
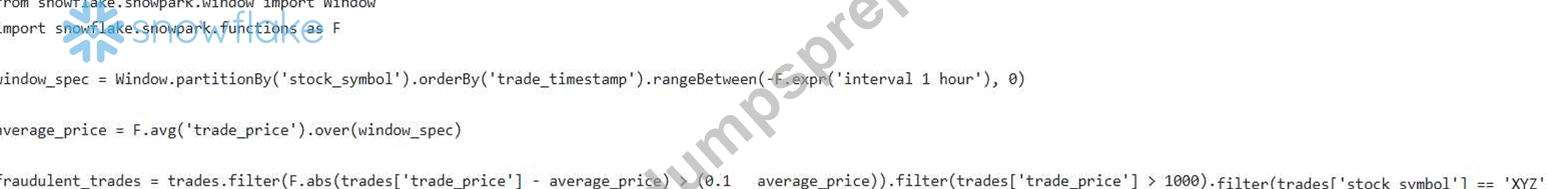


Answer: A
Explanation:
The most efficient and accurate solution is Option B. Here's why: Efficiency: It calculates the average price within the window using and the 'over' clause only once, storing this in a new column called 'avg_price' . The initial calculation uses a window function and does not take place until the query is executed. Accuracy: After adding the new 'avg_price' column, it can filter on multiple conditions. All conditions are evaluated at once. This is efficient as it combines all three conditions for filtering into one filter expression which reduces the number of passes made on the data. After using the 'avg_price' column in the filter step, it immediately drops this column to avoid polluting the 'fraudulent_trades' result. Correctness: After adding the new 'avg_price' column, it can filter on multiple conditions using window functions. Also, the price and the stock symbol are also part of the same filter criteria, ensuring the data is filtered as desired. Other Options: Option A : Does not reuse the calculated average price which decreases readability. Option C : Applies filters one after another. Each filter call will perform a full pass on the data, which is inefficient. Also needs to store the new average price in a new column, which will pollute the resulting dataframe. So, it is worse than Option B. Option D : Applies filters one after another and does not reuse the average price, and the filter steps require window function to be evaluated on separate filter operation. It is less efficient than Option B. Option E : Averages price on previously filtered data, which is not according to the requirements.
NEW QUESTION # 107
......
Passing the test SPS-C01 certification can prove you are that kind of talents and help you find a good job with high pay and if you buy our SPS-C01 guide torrent you will pass the exam successfully. Our product boosts many merits and useful functions to make you to learn efficiently and easily. Our SPS-C01 guide questions are compiled and approved elaborately by experienced professionals and experts. The download and tryout of our SPS-C01 Torrent question before the purchase are free and we provide free update and the discounts to the old client. Our customer service personnel are working on the whole day and can solve your doubts and questions at any time.
New SPS-C01 Braindumps Ebook: https://www.briandumpsprep.com/SPS-C01-prep-exam-braindumps.html
2026 Latest BraindumpsPrep SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=18MZHhL5iu-xRQli-xvJTAjJ68Dq9mrM7