Nutanix인증 NCP-MCI-7.5시험은 인기있는 IT자격증을 취득하는데 필요한 국제적으로 인정받는 시험과목입니다. Nutanix인증 NCP-MCI-7.5시험을 패스하려면 Itexamdump의Nutanix인증 NCP-MCI-7.5덤프로 시험준비공부를 하는게 제일 좋은 방법입니다. Itexamdump덤프는 IT전문가들이 최선을 다해 연구해낸 멋진 작품입니다. Nutanix인증 NCP-MCI-7.5덤프구매후 업데이트될시 업데이트버전을 무료서비스료 제공해드립니다.
| Section | Objectives |
|---|---|
| Topic 1: Prism Administration and Management | - Prism Element and Prism Central - Reporting and analytics - Monitoring and alerts |
| Topic 2: Networking and Security | - Virtual networking concepts - Microsegmentation and security policies - Network configuration in AHV |
| Topic 3: Storage and Data Services | - Data resiliency and replication - Storage containers and policies - Snapshots and backups |
| Topic 4: Cluster Operations and Lifecycle Management | - Upgrades and lifecycle management - Health monitoring and troubleshooting - Capacity planning and optimization |
| Topic 5: Nutanix Architecture and Core Concepts | - Cluster design fundamentals - Nutanix AOS components and architecture - Hyperconverged Infrastructure (HCI) principles |
| Topic 6: Virtualization and AHV | - AHV architecture and features - VM lifecycle management - Image service and VM deployment |
Nutanix인증 NCP-MCI-7.5시험을 준비하기 위해 잠도 설쳐가면서 많이 힘들죠? Itexamdump덤프가 고객님의 곁을 지켜드립니다. Itexamdump에서 제공해드리는Nutanix인증 NCP-MCI-7.5덤프는 실제Nutanix인증 NCP-MCI-7.5시험문제를 연구하여 만든 공부자료이기에 최고의 품질을 자랑합니다. Itexamdump덤프를 열심히 공부하여 멋진 IT전문가의 꿈을 이루세요.
질문 # 28
An administrator wants to run a workload at site A, but replicate it to two clusters with different RPOs. Which replication option fits the needs?
정답:A
설명:
The requirement is straightforward: there is one source site (Site A) and the workload must be replicated to two destination clusters, each with potentially different RPO settings. In Nutanix DR design terminology, that is a one-to-many replication pattern. Nutanix documentation for multisite disaster recovery explains that a single protection policy can include replication schedules to multiple recovery clusters, which is how a source can protect workloads to more than one target with different schedule definitions. That makes D the correct answer.
The other choices describe different topologies. Many-to-One means multiple sources targeting one destination. Many-to-Many is broader bidirectional or multiple-source/multiple-target logic than the question requires. Two-Way-Mirroring is not the correct pattern for one source sending copies outward to two other sites. Nutanix's protection-policy model is specifically flexible enough to define different replication schedules toward separate destinations, which is why this exact scenario is best labeled One-to-Many. So for an exam-aligned and documentation-consistent answer, D is the right choice.
질문 # 29
A new cluster is being deployed for the accounting department with the following characteristics:
* There is a lot of infrequently used data.
* The data is critical for the company.
* Fault Tolerance 2 is required.
* The budget is tight.
In addition to compression, which storage efficiency mechanism and minimum required number of nodes should the administrator configure?
정답:C
설명:
The question is asking for the best balance of capacity efficiency, fault tolerance, and cost control. Nutanix documentation explains that erasure coding is the storage-efficiency mechanism that increases usable capacity by using parity instead of full-copy replication overhead, making it a strong fit when data is relatively cold or infrequently modified. Nutanix also documents that erasure coding requires a minimum of six nodes when using replication factor 3, which corresponds to Fault Tolerance 2 designs. That makes Erasure Coding with six nodes the correct answer.
Deduplication is valuable for certain duplicate-heavy data sets such as VDI or repeated blocks, but the question emphasizes business-critical cold data and a tight budget. In that context, erasure coding provides the more directly documented capacity-efficiency benefit. The five-node options are eliminated by Nutanix's minimum-node requirement for RF3 erasure coding. Since FT2 implies the higher fault-tolerance design and Nutanix requires six nodes for EC with RF3, A is the correct answer.
질문 # 30
An administrator needs to protect a set of workloads across three sites (Site A, Site B, Site C) managed by different Prism Central instances. Which is the most efficient way to protect such VMs?
정답:C
설명:
Nutanix documentation for multisite disaster recovery states that a protection policy can include multiple replication schedules across up to three different recovery clusters, and Nutanix also documents the ability to configure multisite replication schedules for up to three recovery clusters with different schedules. That means a source site can protect workloads to multiple destinations without requiring separate, duplicated protection policies for each site. Given the options, the most efficient approach is therefore one protection policy from the source cluster covering all three sites, which is option D.
The answer choices that create multiple separate protection policies are less efficient and introduce avoidable administrative duplication. Cloning policies across sites also misses the point of Nutanix's native multisite capability. Even though the sites are managed by different Prism Central instances, Nutanix documents DR support between clusters registered to different Prism Central instances as well. So the most scalable and documentation-aligned answer is D.
질문 # 31
Faced with prolonged times for hardware delivery, an administrator is looking for a way to be informed on time when cluster storage capacity is running low. In order for new hard disks to be delivered on time, the administrator needs to get a warning earlier than it is set currently.
Which action should the administrator take to receive a warning about cluster storage capacity running low earlier?
정답:C
설명:
To receive an alert earlier, the administrator must lower the threshold at which the alert's warning state is triggered. Nutanix alerting works by comparing utilization against configured warning and critical thresholds.
If the threshold is lowered, the system reaches it sooner, which gives the administrator more lead time before the environment becomes capacity-constrained. Among the given options, the one that directly performs that function is decreasing the Storage Container Space Usage Exceeded alert Warning threshold, which is option C.
The other choices are weaker or misaligned. There is no meaningful "increase frequency" adjustment that changes when capacity is considered low; it would only change how often checks occur, not the trigger point.
Changing the critical threshold does not provide earlier warning notice, which is what the question asks for.
The wording also points more naturally to a threshold-based action rather than enabling a different alert family. In Nutanix monitoring, earlier warnings come from making the warning trigger more conservative.
Therefore C is the best answer because it causes the alert to fire at a lower usage percentage and provides earlier operational notice.
질문 # 32
Refer to Exhibit: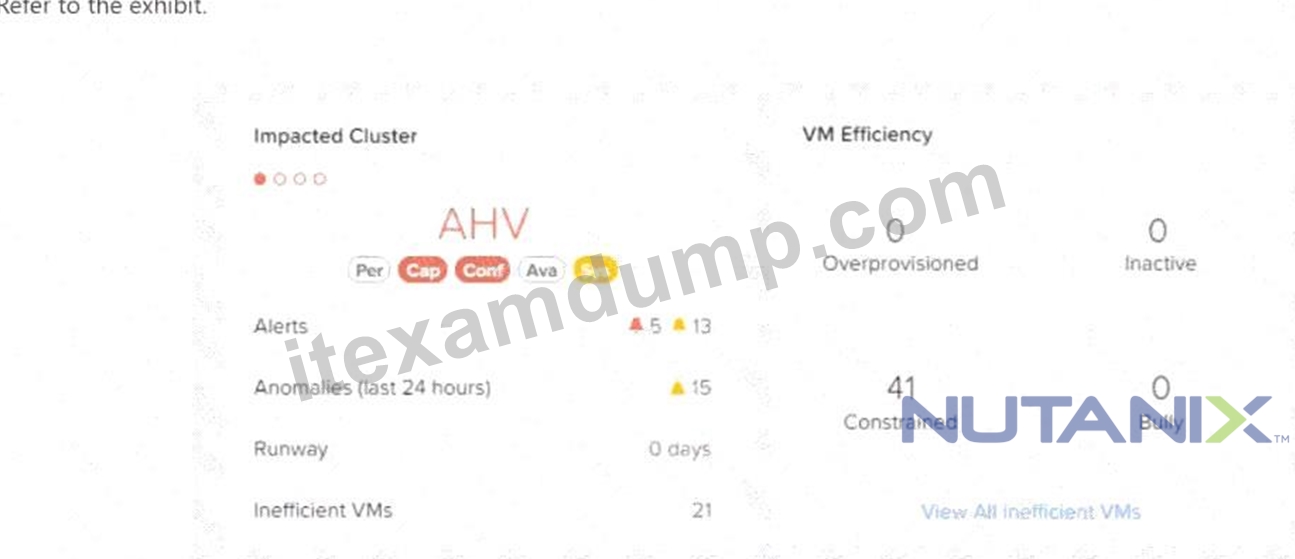
After logging into Prism Central, an administrator observes that there are a large number of constrained VMs.
What does this indicate about those VMs?
정답:C
설명:
In Prism Central VM efficiency and behavioral-learning views, Nutanix groups inefficient VMs into categories such as over-provisioned, inactive, bully, and constrained. A constrained VM is one that does not have enough resources for its workload and is therefore experiencing pressure. Nutanix documentation ties constrained status to signs such as CPU readiness, memory swapping, or other stress indicators that show the VM is not adequately provisioned for what it is trying to do. That means the best interpretation is that those VMs are lacking sufficient resources, which is option B. ( Nutanix Portal ) This category is different from the other distractors. An inactive VM is mostly idle and not making meaningful use of its assigned resources. An over-provisioned VM is wasting capacity because it was allocated too much. A VM that is merely "consuming too much CPU" could be a bully VM or simply a busy VM, but that alone does not define the constrained classification. Nutanix uses the constrained label to signal a right-sizing opportunity in the direction of adding or adjusting resources, not reclaiming them. Therefore the most accurate answer is B, because constrained VMs are the ones that are short on sufficient resources for their workload behavior. ( Nutanix Portal )
질문 # 33
......
Itexamdump의 Nutanix인증 NCP-MCI-7.5덤프는 다른 덤프판매 사이트보다 저렴한 가격으로 여러분들께 가볍게 다가갑니다. Nutanix인증 NCP-MCI-7.5덤프는 기출문제와 예상문제로 되어있어 시험패스는 시간문제뿐입니다.
NCP-MCI-7.5높은 통과율 덤프공부: https://www.itexamdump.com/NCP-MCI-7.5.html