2026 Latest PrepAwayExam NCM-MCI-6.10 PDF Dumps and NCM-MCI-6.10 Exam Engine Free Share: https://drive.google.com/open?id=1ywPiSD0A1uWTnFrbf-1BfzvClMCmajZB
If you hope to get a job with opportunity of promotion, it will be the best choice chance for you to choose the NCM-MCI-6.10 study question from our company. Because our NCM-MCI-6.10 study materials have the enough ability to help you improve yourself and make you more excellent than other people. The NCM-MCI-6.10 Learning Materials from our company have helped a lot of people get the certification and achieve their dreams. And you also have the opportunity to contact with the NCM-MCI-6.10 test guide from our company.
| Section | Objectives |
|---|---|
| Analyze and Optimize Network Performance | - Flow policies analysis and optimization - Physical and virtual network evaluation - Advanced network configuration - Overlay networking optimization |
| Advanced Configuration and Troubleshooting | - Security posture analysis - Risk mitigation configuration - Troubleshooting Nutanix services - CLI and API execution - Third-party integrations |
| Analyze and Optimize Storage Performance | - Storage configuration optimization - Storage internals and I/O analysis - Workload performance evaluation |
| Business Continuity | - BCDR compliance analysis - Workload resilience evaluation |
| Analyze and Optimize VM Performance | - VM resource optimization - Cluster and node metrics analysis |
If you do not have access to internet most of the time, if you need to go somewhere is in an offline state, but you want to learn for your NCM-MCI-6.10 exam. Don not worry, our products will help you solve your problem. We deeply believe that our latest NCM-MCI-6.10 Exam Torrent will be very useful for you to strength your ability, pass your exam and get your certification. Our study materials with high quality and high pass rate in order to help you get out of your harassment.
NEW QUESTION # 21
Task 13
An administrator found a CentOS VM, Cent_Down, on the cluster with a corrupted network stack. To correct the issue, the VM will need to be restored from a previous snapshot to become reachable on the network again.
VM credentials:
Username: root
Password: nutanix/4u
Restore the VM and ensure it is reachable on the network by pinging 172.31.0.1 from the VM.
Power off the VM before proceeding.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To restore the VM and ensure it is reachable on the network, you can follow these steps:
Log in to the Web Console of the cluster where the VM is running.
Click on Virtual Machines on the left menu and find Cent_Down from the list. Click on the power icon to power off the VM.
Click on the snapshot icon next to the power icon to open the Snapshot Management window.
Select a snapshot from the list that was taken before the network stack was corrupted. You can use the date and time information to choose a suitable snapshot.
Click on Restore VM and confirm the action in the dialog box. Wait for the restore process to complete.
Click on the power icon again to power on the VM.
Log in to the VM using SSH or console with the username and password provided.
Run the command ping 172.31.0.1 to verify that the VM is reachable on the network. You should see a reply from the destination IP address.
Go to VMS from the prism central gui
Select the VMand go to More -> Guest Shutdown
Go to Snapshots tab and revert to latest snapshot available
power on vm and verify if ping is working
NEW QUESTION # 22
An administrator regularly sees a WARN for backup_schedule_check and also receives alerts for Pulse not being enabled on Cluster 1.
Detailed information for backup_schedule_check:
Node xx.xx.xx.xx:
WARN: Backup schedule(s) exist for protection domain NoVMs; however, there are no entities in the protection domain.
Refer
to KB 1910 (http://portal.nutanix.com/kb/1910) for details on backup_schedule_check or Recheck with: ncc health_checks data_protection_checks protection_domain_checks backup_schedule_check.
This shows up in NCC, however, it is something set up by the company and they do not want the NCC check to be run.
Configure Cluster 1 to no longer have messages in NCC about the backup_schedule_check.
Turn off the alert for Pulse not being enabled, and resolve the alert. They would like messages about Pulse to be recorded, but do not want an alert.
Note: You may need to run the "Pulse is not enabled" check in order to have one to resolve.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure Cluster 1 from its Prism Element interface.
1. Disable the backup_schedule_check NCC Check
This will prevent the WARN message for the NoVMs protection domain.
* Log in to the Cluster 1 Prism Element (PE) interface.
* Navigate to the Health dashboard (click the "heart" icon in the top-left).
* In the left-hand menu, select NCC.
* In the search bar for the checks, type backup_schedule_check to find the specific check.
* Select the checkbox next to the backup_schedule_check in the list.
* Click the Disable button that appears above the table. This will stop this check from running during NCC health reports.
2. Configure and Resolve Pulse Alerts
This process involves two parts: disabling the alerting policy, and then enabling Pulse itself to resolve the underlying condition.
A. Disable the Alert Policy
This stops the system from generating a new alert if Pulse is ever disabled, satisfying the "do not want an alert" requirement.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type Pulse to find the policy.
* Select the checkbox for the alert policy named Pulse is not enabled (or pulse_disabled_alert).
* Click the Update button.
* Uncheck the Enable box for the policy.
* Click Save.
B. Enable Pulse (to Resolve the Condition)
This enables the Pulse service to record messages (as requested) and fixes the root cause of the alert, allowing it to be resolved.
* Click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Pulse.
* Click the Enable Pulse button (or "Update" if it's already partially configured).
* Check the box for Enable Pulse.
* (Note: Any "Enable alerts for Pulse" boxes would remain unchecked or be ignored, as the main Alert Policy itself is now disabled.)
* Click Save.
C. Resolve the Active Alert
* Navigate to the Alerts dashboard (click the "bell" icon in the top-left).
* Find the active alert: Pulse is not enabled.
* (Note: If the alert is not present, you would first go to the Health dashboard, run the check_pulse NCC check to generate it, and then return to the Alerts dashboard.)
* Select the checkbox next to the "Pulse is not enabled" alert.
* Click the Resolve button that appears at the top of the list. Since the underlying condition (Pulse being disabled) is now fixed, the alert will be successfully resolved.
NEW QUESTION # 23
Task 11
Running NCC on a cluster prior to an upgrade results in the following output FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%) Identify the CVM with the issue, remove the fil causing the storage bloat, and check the health again by running the individual disk usage health check only on the problematic CVM do not run NCC health check Note: Make sure only the individual health check is executed from the affected node
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To identify the CVM with the issue, remove the file causing the storage bloat, and check the health again, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and find the NCC health check output file from the list.
You can use the date and time information to locate the file. The file name should be something like ncc- output-YYYY-MM-DD-HH-MM-SS.log.
Open the file and look for the line that says FAIL: CVM System Partition /home usage at 93% (greater than threshold, 90%). Note down the IP address of the CVM that has this issue. It should be something like X.X.X.
X.
Log in to the CVM using SSH or console with the username and password provided.
Run the command du -sh /home/* to see the disk usage of each file and directory under /home. Identify the file that is taking up most of the space. It could be a log file, a backup file, or a temporary file. Make sure it is not a system file or a configuration file that is needed by the CVM.
Run the command rm -f /home/<filename> to remove the file causing the storage bloat. Replace <filename> with the actual name of the file.
Run the command ncc health_checks hardware_checks disk_checks disk_usage_check --cvm_list=X.X.X.
X to check the health again by running the individual disk usage health check only on the problematic CVM.
Replace X.X.X.X with the IP address of the CVM that you noted down earlier.
Verify that the output shows PASS: CVM System Partition /home usage at XX% (less than threshold, 90%).
This means that the issue has been resolved.
#access to CVM IP by Putty
allssh df -h #look for the path /dev/sdb3 and select the IP of the CVM
ssh CVM_IP
ls
cd software_downloads
ls
cd nos
ls -l -h
rm files_name
df -h
ncc health_checks hardware_checks disk_checks disk_usage_check
NEW QUESTION # 24
Due to new security requirements, an administrator has been tasked with updating the security settings for user accounts within Prism Element on Cluster 1.
An SSL Certificate Signing Request with Subject Alternative Name should be generated for submission to the security team's Certificate Authority with the following details:
countryName = US
stateOrProvinceName = North Carolina
localityName = Durham
organizationName = ACME
organizationalUnitName = Infrastructure
commonName = prism_element.ACME.org
emailAddress = administrator@ACME.org
Alternate names = cvm1.ACME.org, cvm2.ACME.org, cvm3.ACME.org
Encryption: RSA 2048, sha256
When the Certificate Signing Request is generated, place a copy of both the .cnf file and the .csr file on the desktop named 'prism_element_acme.cnf' and 'prism_element_acme.csr' Save a copy of the command(s) used for this scenario to a new file on the desktop named "Task 5.txt".
Note: You must copy and paste the command(s) and output from SSH to the "Task 5.txt" file to achieve all points available.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to generate the Certificate Signing Request (CSR) on Cluster 1.
This entire process is performed from an SSH session connected to a CVM (Controller VM) on Cluster 1.
1. Access Cluster 1 CVM
* From Prism Central, navigate to Hardware > Clusters and click on Cluster 1 to open its Prism Element (PE) interface.
* In the Cluster 1 PE, navigate to Hardware > CVMs to find the IP address of any CVM in the cluster.
* Use an SSH client (like PuTTY) to connect to the CVM's IP address.
* Log in with the admin user and password.
2. Create the Configuration File (.cnf)
To include the Subject Alternative Names (SANs), you must first create a configuration file.
* In the CVM's command line, create the .cnf file using a text editor:
vi prism_element_acme.cnf
* Press i to enter "Insert" mode.
* Paste the following text exactly into the editor:
Ini, TOML
[ req ]
default_bits = 2048
distinguished_name = req_distinguished_name
req_extensions = v3_req
prompt = no
[ req_distinguished_name ]
C = US
ST = North Carolina
L = Durham
O = ACME
OU = Infrastructure
CN = prism_element.ACME.org
emailAddress = administrator@ACME.org
[ v3_req ]
subjectAltName = @alt_names
[ alt_names ]
DNS.1 = cvm1.ACME.org
DNS.2 = cvm2.ACME.org
DNS.3 = cvm3.ACME.org
* Press Esc to exit "Insert" mode, then type :wq and press Enter to save and quit vi.
3. Generate the CSR and Key
* Run the following openssl command. This command uses the .cnf file to generate the new CSR (.csr) and a corresponding private key (.key), applying the sha256 encryption as requested.
Bash
openssl req -new -nodes -out prism_element_acme.csr -keyout prism_element_acme.key -config prism_element_acme.cnf -sha256
* The command will output the following, confirming the key generation:
* Generating a 2048 bit RSA private key
* ...................+++++
* ..................................+++++
* writing new private key to 'prism_element_acme.key'
* -----
4. Save Files to the Desktop
You will now copy the contents of the generated files from the CVM to your desktop.
* For Task 5.txt (Commands and Output):
* Open a new Notepad file on the desktop.
* Copy and paste all the commands you ran in the SSH session and their full output (as shown in steps 2 and 3) into this file.
* Save the file on the desktop as Task 5.txt.
* For prism_element_acme.cnf:
* In the CVM SSH session, display the file's content:
cat prism_element_acme.cnf
* Copy the entire text output (starting from [ req ]).
* Open a new Notepad file on the desktop.
* Paste the content and save the file as prism_element_acme.cnf.
* For prism_element_acme.csr:
* In the CVM SSH session, display the file's content:
cat prism_element_acme.csr
* Copy the entire text output, including the -----BEGIN CERTIFICATE REQUEST----- and ----- END CERTIFICATE REQUEST----- lines.
* Open a new C:\Users\admin\Desktop\Notepad file on the desktop.
* Paste the content and save the file as prism_element_acme.csr.
NEW QUESTION # 25
Task 1
An administrator needs to configure storage for a Citrix-based Virtual Desktop infrastructure.
Two VDI pools will be created
Non-persistent pool names MCS_Pool for tasks users using MCS Microsoft Windows 10 virtual Delivery Agents (VDAs) Persistent pool named Persist_Pool with full-clone Microsoft Windows 10 VDAs for power users
20 GiB capacity must be guaranteed at the storage container level for all power user VDAs The power user container should not be able to use more than 100 GiB Storage capacity should be optimized for each desktop pool.
Configure the storage to meet these requirements. Any new object created should include the name of the pool (s) (MCS and/or Persist) that will use the object.
Do not include the pool name if the object will not be used by that pool.
Any additional licenses required by the solution will be added later.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure the storage for the Citrix-based VDI, you can follow these steps:
Log in to Prism Central using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as VDI_Storage_Pool, and select the disks to include in the pool.
You can choose any combination of SSDs and HDDs, but for optimal performance, you may prefer to use more SSDs than HDDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container for the non-persistent pool, such as MCS_Pool_Container, and select the storage pool that you just created, VDI_Storage_Pool, as the source.
Under Advanced Settings, enable Deduplication and Compression to reduce the storage footprint of the non- persistent desktops. You can also enable Erasure Coding if you have enough nodes in your cluster and want to save more space. These settings will help you optimize the storage capacity for the non-persistent pool.
Click Save to create the container.
Go to Storage > Containers and click on Create Container again.
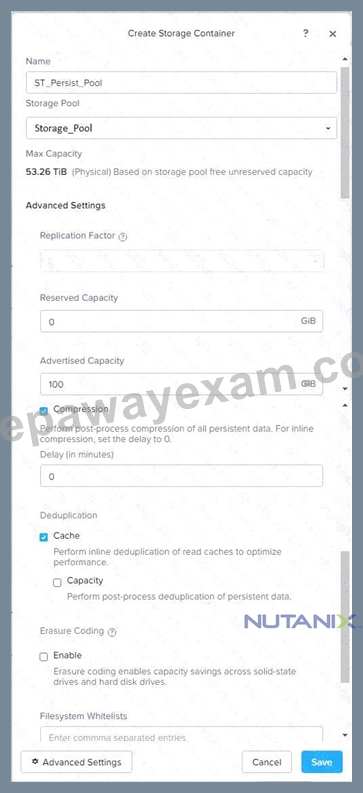
Enter a name for the new container for the persistent pool, such as Persist_Pool_Container, and select the same storage pool, VDI_Storage_Pool, as the source.
Under Advanced Settings, enable Capacity Reservation and enter 20 GiB as the reserved capacity. This will guarantee that 20 GiB of space is always available for the persistent desktops. You can also enter 100 GiB as the advertised capacity to limit the maximum space that this container can use. These settings will help you control the storage allocation for the persistent pool.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore for the non-persistent pool, such as MCS_Pool_Datastore, and select NFS as the datastore type. Select the container that you just created, MCS_Pool_Container, as the source.
Click Save to create the datastore.
Go to Storage > Datastores and click on Create Datastore again.
Enter a name for the new datastore for the persistent pool, such as Persist_Pool_Datastore, and select NFS as the datastore type. Select the container that you just created, Persist_Pool_Container, as the source.
Click Save to create the datastore.
The datastores will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on each datastore. You should see all nodes listed under Hosts.
You can now use Citrix Studio to create your VDI pools using MCS or full clones on these datastores. For more information on how to use Citrix Studio with Nutanix Acropolis, see Citrix Virtual Apps and Desktops on Nutanix or Nutanix virtualization environments.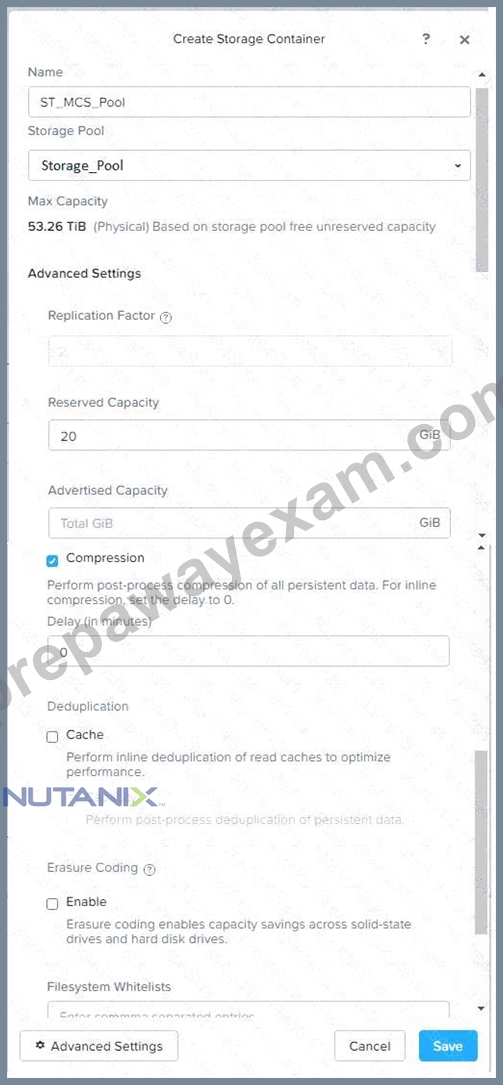
https://portal.nutanix.com/page/documents/solutions/details?targetId=BP-2079-Citrix-Virtual-Apps-and- Desktops:bp-nutanix-storage-configuration.html
NEW QUESTION # 26
......
Our company has always been following the trend of the NCM-MCI-6.10 certification. Our research and development team not only study what questions will come up in the NCM-MCI-6.10 exam. The content of our NCM-MCI-6.10 practice materials is chosen so carefully that all the questions for the exam are contained. And our study materials have three formats which help you to read, test and study anytime, anywhere. This means with our products you can prepare for exams efficiently. If you desire a NCM-MCI-6.10 Certification, our products are your best choice.
NCM-MCI-6.10 Practice Questions: https://www.prepawayexam.com/Nutanix/braindumps.NCM-MCI-6.10.ete.file.html
What's more, part of that PrepAwayExam NCM-MCI-6.10 dumps now are free: https://drive.google.com/open?id=1ywPiSD0A1uWTnFrbf-1BfzvClMCmajZB