P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by PrepAwayTest: https://drive.google.com/open?id=1pn_oQ4w2TkyB7Dw8yv551HXH58q6Eg87
We have 24/7 Service Online Support services. If you have any questions about our SPS-C01 guide torrent, you can email or contact us online. We provide professional staff Remote Assistance to solve any problems you may encounter. You will enjoy the targeted services, the patient attitude, and the sweet voice whenever you use SPS-C01 Exam Torrent. 7*24*365 Day Online Intimate Service of SPS-C01 questions torrent is waiting for you. "Insistently pursuing high quality, everything is for our customers" is our consistent quality principle on our SPS-C01 exam questions.
| Section | Objectives |
|---|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
If you do not have access to internet most of the time, if you need to go somewhere is in an offline state, but you want to learn for your SPS-C01 exam. Don not worry, our products will help you solve your problem. We deeply believe that our latest SPS-C01 Exam Torrent will be very useful for you to strength your ability, pass your exam and get your certification. Our study materials with high quality and high pass rate in order to help you get out of your harassment.
NEW QUESTION # 329
You have two Snowpark DataFrames, 'dfl' and 'df2 , both containing customer data, but with slightly different schemas. 'dfl' has columns 'customer_id', 'name', and 'email'. 'df2' has columns 'id', 'customer name', and 'email_address'. You want to perform a set- based operation to find all unique customer IDs present in 'dfl but NOT in 'df2' , considering that 'customer_id' in 'dfl corresponds to 'id' in 'df2. Which of the following code snippets will achieve this, ensuring that column names are correctly aligned before the operation?





Answer: B
Explanation:
Option D is the correct solution. First, 'customer_id')' renames the 'id' column in 'df2 to 'customer_id', aligning it with the 'customer_id' column in 'dfl Then, 'cifl performs the set difference operation, returning only the 'customer_id' values present in 'dfl& but not in the modified 'df2. 'exceptAll' (Option A) will include duplicates. Option B uses 'minus' which does not exist on Snowpark DataFrame. Options C uses 'subtract which also does not exist. Option E will cause unexpected results because the column name of dfl and df2 would be different.
NEW QUESTION # 330
You are tasked with building a Snowpark function to perform an upsert operation on a Snowflake table using a DataFrame. The function should take the target table name, a staging DataFrame, a join key column, and a list of columns to update. The function needs to handle potential schema evolution (i.e., columns may be added or removed from either the target table or the staging DataFrame) gracefully without causing the entire upsert to fail. Which of the following approaches, or combinations of approaches, would best address this requirement?
Answer: D,E
Explanation:
Approaches A and D are the most suitable for handling schema evolution during an upsert operation. Approach A involves dynamically generating the SQL WERGE statement by inspecting the schemas of both the target table and the staging DataFrame. This ensures that only the common columns are included in the update and insert clauses, preventing errors due to missing columns. Approach D suggests projecting the staging DataFrame to only include the columns that exist in the target table using DataFrame.select' . This effectively harmonizes the schema of the staging data with the target table's schema, avoiding issues during the 'merge' operation. While Snowflake does have some schema evolution capabilities, explicitly handling it in the code provides more control and predictability.
NEW QUESTION # 331
A Snowpark application is designed to process data residing in a Snowflake table called 'ORDERS'. The application needs to create a temporary view named 'TEMP ORDERS VIEW based on a filtered subset of this table. The view should only be accessible within the current Snowpark session and should be automatically dropped when the session ends. What is the MOST efficient and correct Python code snippet using Snowpark to achieve this?
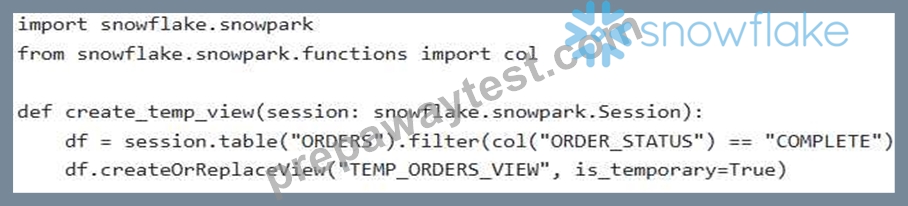
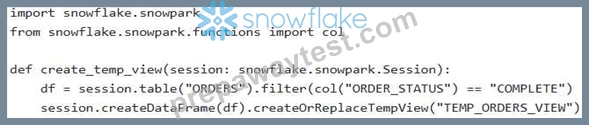
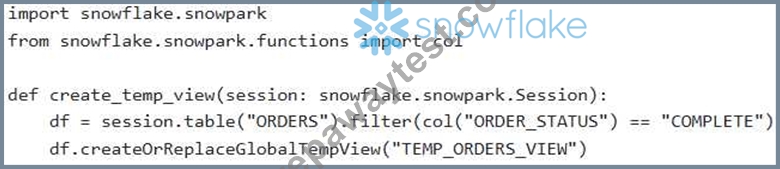
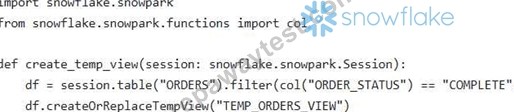
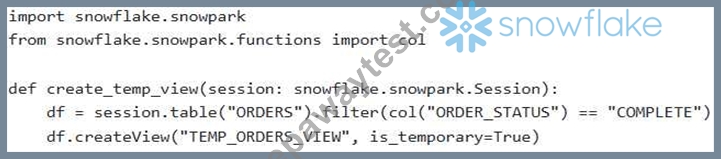
Answer: D
Explanation:
Option A, , is the most efficient and directly creates a temporary view scoped to the session. The 'createOrRepIaceTempView' method is the correct Snowpark API call for creating such views. Options B and D, 'createOrReplaceView' with or 'createView' with , are not valid Snowpark API calls. Option C, createOrReplaceGlobalTempViews , creates a global temporary view, accessible across sessions, which is not the requirement. Option E is adding a redundant step by creating a dataframe from another dataframe.
NEW QUESTION # 332
You have a Snowpark DataFrame 'customer df with a 'customer name' column. You need to create a new column 'initials' that contains the initials of each customer's name. For example, if 'customer name' is 'John Doe', 'initials' should be 'JD'. You must handle names with multiple words correctly. Which Snowpark SQL expression using the "col()' function is the most efficient and correct way to define the 'initials' column?





Answer: E
Explanation:
Option D is the most robust and efficient solution. It uses a regular expression to extract the first letter of each word in the name, handling multiple words correctly, and converting it to uppercase. Option A is incorrect because it only handles two-word names and relies on string concatenation, which can be less efficient than using the 'concat function. Option B is incorrect as 'array_accumulate' is not used in Snowpark to compute initials. Option C is incorrect as it is too basic and relies on two-word names only. Option E is incorrect as it extracts only the first two characters from the name.
NEW QUESTION # 333
You are developing a Snowpark application that performs feature engineering on a dataset of customer transactions. This involves calculating several complex aggregate features such as rolling averages, medians, and custom ratios. You want to optimize the performance of this feature engineering process using a Snowpark-optimized warehouse. Which of the following strategies would be MOST effective in achieving optimal performance?
Answer: C,D
Explanation:
Using 'GROUP BY and window functions allows Snowflake to optimize the calculations within its engine. Leveraging UDTFs allows custom computations while still benefiting from Snowflake's optimization capabilities. Python UDFs are generally slower than equivalent SQL or Java/Scala UDTFs due to inter-process communication overhead. Materializing intermediate DataFrames can help in some scenarios but can also introduce overhead if not managed carefully. Java Stored procedures could be used, but UDTF would be more optimized way.
NEW QUESTION # 334
......
The experts in our company have been focusing on the SPS-C01 examination for a long time and they never overlook any new knowledge. The content of our SPS-C01 study materials has always been kept up to date. We will inform you by E-mail when we have a new version. With our great efforts, our SPS-C01practice dumps have been narrowed down and targeted to the SPS-C01 examination. We can ensure you a pass rate as high as 99%!
Latest SPS-C01 Test Blueprint: https://www.prepawaytest.com/Snowflake/SPS-C01-practice-exam-dumps.html
DOWNLOAD the newest PrepAwayTest SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1pn_oQ4w2TkyB7Dw8yv551HXH58q6Eg87