Databricks-Certified-Data-Engineer-Professional Prep Torrent - Databricks Certified Data Engineer Professional Exam Exam Torrent & Databricks-Certified-Data-Engineer-Professional Test Braindumps

You can also customize your Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam dumps as per your needs. We believe that this assessment of preparation is essential to ensuring that you strengthen the concepts you need to succeed. Based on the results of your self-assessment tests, you can focus on the areas that need the most improvement.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Modeling and Storage | 20% | - Storage Optimization
- Data Modeling
- File Formats
|
| Topic 2: Data Processing | 28% | - ETL Pipelines
- Spark SQL
- Data Transformation
- Structured Streaming
|
| Topic 3: Databricks Lakehouse Platform | 24% | - Data Management
- Lakehouse Architecture
- Delta Lake
- Unity Catalog
|
| Topic 4: Monitoring and Troubleshooting | 16% | - Monitoring
- Performance Optimization
- Troubleshooting
|
| Topic 5: Data Quality and Governance | 12% | - Data Lineage
- Governance
- Data Quality
|
>> Dumps Databricks-Certified-Data-Engineer-Professional Cost <<
Pass Guaranteed Quiz 2026 Databricks-Certified-Data-Engineer-Professional: Latest Dumps Databricks Certified Data Engineer Professional Exam Cost
Passing the Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional exam is your best career opportunity. The rich experience with relevant certificates is important for enterprises to open up a series of professional vacancies for your choices. Databricks Databricks-Certified-Data-Engineer-Professional learning quiz bank and learning materials look up the latest questions and answers based on the topics you choose. This choice will serve as a breakthrough of your entire career, so prepared to be amazed by high quality and accuracy rate of our Databricks-Certified-Data-Engineer-Professional Study Guide.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q195-Q200):
NEW QUESTION # 195
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States.
The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.
Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
- A. Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.
- B. Databricks notebooks send all executable code from the user's browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.
- C. Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.
- D. Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.
- E. Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.
Answer: D
Explanation:
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees.
Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs.
NEW QUESTION # 196
Which statement regarding spark configuration on the Databricks platform is true?
- A. Spark configuration properties can only be set for an interactive cluster by creating a global init script.
- B. The Databricks REST API can be used to modify the Spark configuration properties for an interactive cluster without interrupting jobs.
- C. Spark configuration properties set for an interactive cluster with the Clusters UI will impact all notebooks attached to that cluster.
- D. Spark configuration set within an notebook will affect all SparkSession attached to the same interactive cluster
- E. When the same spar configuration property is set for an interactive to the same interactive cluster.
Answer: C
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
NEW QUESTION # 197
A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data. They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline. Which configuration should the team use when writing data to the Delta table?
- A. mergeSchema = true
- B. validateSchema = false
- C. overwriteSchema = true
- D. ignoreChanges = false
Answer: A
Explanation:
Setting mergeSchema to true allows Delta Lake to automatically evolve the table schema by incorporating new columns from the source data during writes. This enables append-only pipelines to handle schema changes seamlessly in both batch and streaming workloads without breaking the pipeline.
NEW QUESTION # 198
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Incremental state information should be maintained for 10 minutes for late-arriving data.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
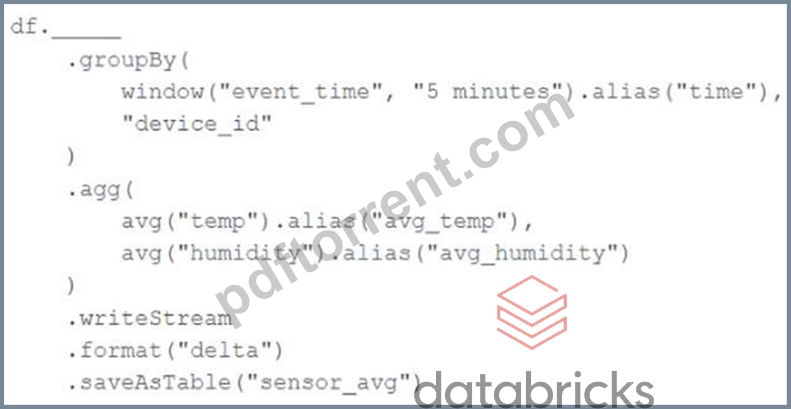
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. awaitArrival("event_time", "10 minutes")
- B. slidingWindow("event_time", "10 minutes")
- C. delayWrite("event_time", "10 minutes")
- D. await("event_time + `10 minutes'")
- E. withWatermark("event_time", "10 minutes")
Answer: E
Explanation:
This is because the question asks for incremental state information to be maintained for 10 minutes for late-arriving data. The withWatermark method is used to define the watermark for late data. The watermark is a timestamp column and a threshold that tells the system how long to wait for late data. In this case, the watermark is set to 10 minutes. The other options are incorrect because they are not valid methods or syntax for watermarking in Structured Streaming.
NEW QUESTION # 199
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
- A. Use coalesce() after the aggregation.
- B. Repartition by region before aggregation.
- C. Caching the DataFrame df.
- D. Use broadcast join.
Answer: B
Explanation:
Repartitioning the DataFrame by the grouping key ensures that records with the same region are colocated in the same partitions before the aggregation runs. This significantly reduces the amount of data shuffled during the groupBy operation, leading to more efficient execution.
NEW QUESTION # 200
......
Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional practice test software always keeps track of previous Databricks-Certified-Data-Engineer-Professional practice exam attempts and shows the changes and improvements in every attempt. All the Databricks Certified Data Engineer Professional Exam questions given in Databricks Certified Data Engineer Professional Exam pdf questions file and practice test software are very similar to the actual Databricks Certified Data Engineer Professional Exam Databricks-Certified-Data-Engineer-Professional Exam Questions. So it eliminates the hassle of Databricks-Certified-Data-Engineer-Professional exam fear. The desktop Databricks-Certified-Data-Engineer-Professional practice exam software is compatible with windows based computers. There are many customers support team of PDFTorrent always to fix any problems.
Databricks-Certified-Data-Engineer-Professional Exam Tutorials: https://www.pdftorrent.com/Databricks-Certified-Data-Engineer-Professional-exam-prep-dumps.html
- 100% Pass Authoritative Databricks-Certified-Data-Engineer-Professional - Dumps Databricks Certified Data Engineer Professional Exam Cost 🅾 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and easily obtain a free download on 「 www.prepawaypdf.com 」 🆖Databricks-Certified-Data-Engineer-Professional Test Dumps Pdf
- Databricks Dumps Databricks-Certified-Data-Engineer-Professional Cost: Databricks Certified Data Engineer Professional Exam - Pdfvce High-effective Company 🙅 Search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 and download it for free on ⮆ www.pdfvce.com ⮄ website 🧂New Databricks-Certified-Data-Engineer-Professional Test Camp
- Databricks-Certified-Data-Engineer-Professional Reliable Real Test 👏 Latest Databricks-Certified-Data-Engineer-Professional Test Vce ⚔ Databricks-Certified-Data-Engineer-Professional Latest Dumps Pdf 🎢 The page for free download of ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ on ▷ www.pdfdumps.com ◁ will open immediately 💡Databricks-Certified-Data-Engineer-Professional Reliable Exam Dumps
- Efficient Dumps Databricks-Certified-Data-Engineer-Professional Cost by Pdfvce 🔼 Search for “ Databricks-Certified-Data-Engineer-Professional ” and download it for free on 《 www.pdfvce.com 》 website 😖Minimum Databricks-Certified-Data-Engineer-Professional Pass Score
- Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional Marvelous Dumps Cost 🔝 Search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ and download it for free immediately on ▛ www.troytecdumps.com ▟ 🤢Latest Databricks-Certified-Data-Engineer-Professional Test Vce
- Pass Guaranteed Databricks-Certified-Data-Engineer-Professional - High Pass-Rate Dumps Databricks Certified Data Engineer Professional Exam Cost 🗽 Copy URL ▛ www.pdfvce.com ▟ open and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download for free 🌛Databricks-Certified-Data-Engineer-Professional Test Centres
- Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional Marvelous Dumps Cost 🐙 Copy URL ✔ www.examcollectionpass.com ️✔️ open and search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ to download for free ✋Latest Databricks-Certified-Data-Engineer-Professional Test Vce
- 2026 Perfect Databricks Dumps Databricks-Certified-Data-Engineer-Professional Cost 🏨 Search for [ Databricks-Certified-Data-Engineer-Professional ] and download it for free on 《 www.pdfvce.com 》 website 🚘Reliable Databricks-Certified-Data-Engineer-Professional Exam Dumps
- Exam Databricks-Certified-Data-Engineer-Professional Questions Answers 🆔 Databricks-Certified-Data-Engineer-Professional Pdf Free 🎇 Databricks-Certified-Data-Engineer-Professional Pdf Free 🧊 Enter ☀ www.vceengine.com ️☀️ and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ to download for free 🚖Databricks-Certified-Data-Engineer-Professional Valid Braindumps Ebook
- Databricks Dumps Databricks-Certified-Data-Engineer-Professional Cost: Databricks Certified Data Engineer Professional Exam - Pdfvce High-effective Company 🤹 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and download it for free immediately on ➠ www.pdfvce.com 🠰 🐂New Databricks-Certified-Data-Engineer-Professional Test Pdf
- Minimum Databricks-Certified-Data-Engineer-Professional Pass Score 💱 Databricks-Certified-Data-Engineer-Professional Reliable Real Test ⏰ Databricks-Certified-Data-Engineer-Professional Sample Questions Answers 📈 Search for “ Databricks-Certified-Data-Engineer-Professional ” and easily obtain a free download on 《 www.prep4away.com 》 🎫Minimum Databricks-Certified-Data-Engineer-Professional Pass Score
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes