Our PDF format is great for those who prefer to print out the questions. Databricks Databricks-Certified-Professional-Data-Engineer dumps come in a downloadable PDF format that you can print out and prepare at your own pace. The PDF works on all smart devices, which means you can go through Databricks Databricks-Certified-Professional-Data-Engineer Dumps at your convenience. The ability to print out the Databricks-Certified-Professional-Data-Engineer PDF dumps enables users who find it easier and more comfortable than working on a computer.
Databricks Certified Professional Data Engineer exam is a certification program designed for data professionals who want to validate their expertise in building and maintaining data pipelines using Databricks. Databricks is a cloud-based data engineering platform that provides a unified analytics engine for big data processing, machine learning, and streaming analytics. Databricks-Certified-Professional-Data-Engineer Exam is designed to test a candidate's ability to design, build, and optimize data pipelines using Databricks, as well as their proficiency in data modeling, data warehousing, and data integration.
>> Databricks-Certified-Professional-Data-Engineer Reliable Exam Voucher <<
Our Databricks Databricks-Certified-Professional-Data-Engineer exam questions are designed to provide you with the most realistic Databricks-Certified-Professional-Data-Engineer experience possible. Each question is accompanied by an accurate answer, prepared by our team of experts. We also offer free Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions updates for 1 year after purchase, as well as a free Databricks-Certified-Professional-Data-Engineer practice exam questions demo before purchase.
Databricks Certified Professional Data Engineer is a certification exam offered by Databricks for data engineers. Databricks-Certified-Professional-Data-Engineer exam evaluates the ability of a candidate to design and implement data solutions using Databricks. Databricks is a unified data analytics platform that enables data teams to collaborate on data engineering, machine learning, and analytics tasks. Databricks Certified Professional Data Engineer Exam certification is designed to validate the skills and proficiency of data engineers in using Databricks for data engineering tasks.
Databricks Certified Professional Data Engineer exam is a hands-on exam that requires the candidate to complete a set of tasks using Databricks. Databricks-Certified-Professional-Data-Engineer Exam evaluates the candidate's ability to design and implement data pipelines, work with data sources and sinks, and perform transformations using Databricks. Databricks-Certified-Professional-Data-Engineer exam also tests the candidate's ability to optimize and tune data pipelines for performance and reliability.
NEW QUESTION # 89
A team of data engineer are adding tables to a DLT pipeline that contain repetitive expectations for many of the same data quality checks.
One member of the team suggests reusing these data quality rules across all tables defined for this pipeline.
What approach would allow them to do this?
Answer: C
Explanation:
Maintaining data quality rules in a centralized Delta table allows for the reuse of these rules across multiple DLT (Delta Live Tables) pipelines. By storing these rules outside the pipeline's target schema and referencing the schema name as a pipeline parameter, the team can apply the same set of data quality checks to different tables within the pipeline. This approach ensures consistency in data quality validations and reduces redundancy in code by not having to replicate the same rules in each DLT notebook or file.
Reference:
Databricks Documentation on Delta Live Tables: Delta Live Tables Guide
NEW QUESTION # 90
A nightly job ingests data into a Delta Lake table using the following code: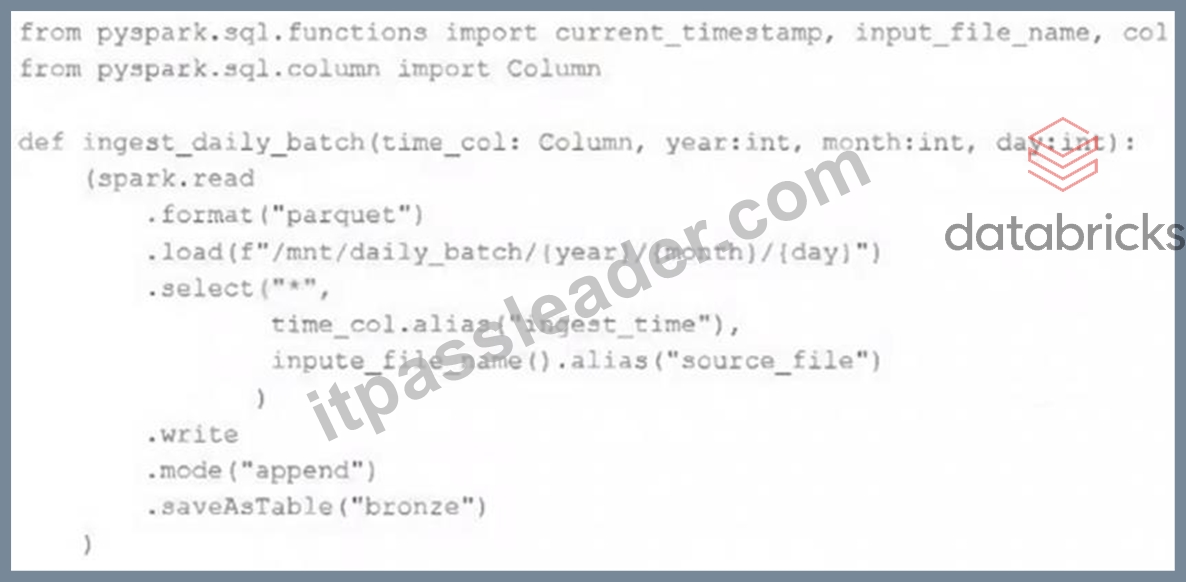
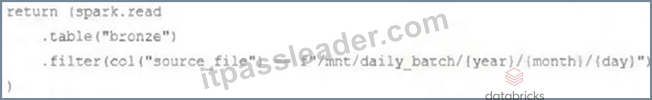
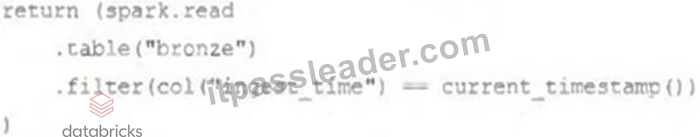
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
Answer: B
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 91
In order to facilitate near real-time workloads, a data engineer is creating a helper function to leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank: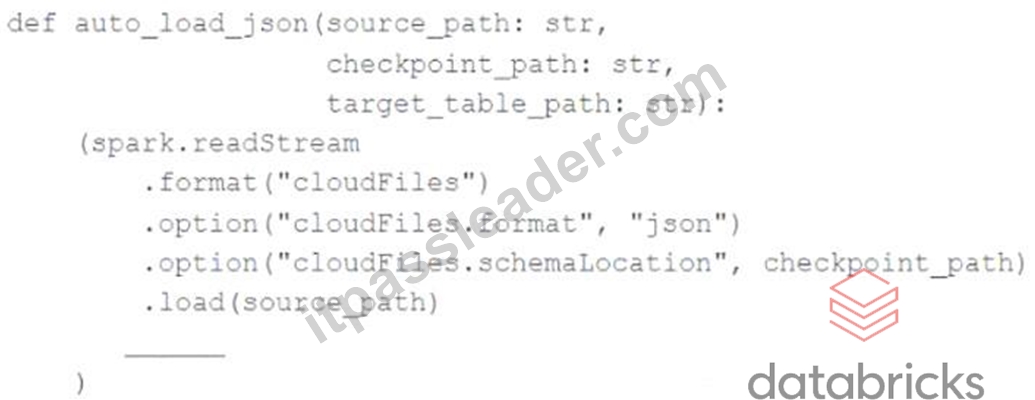
Which response correctly fills in the blank to meet the specified requirements?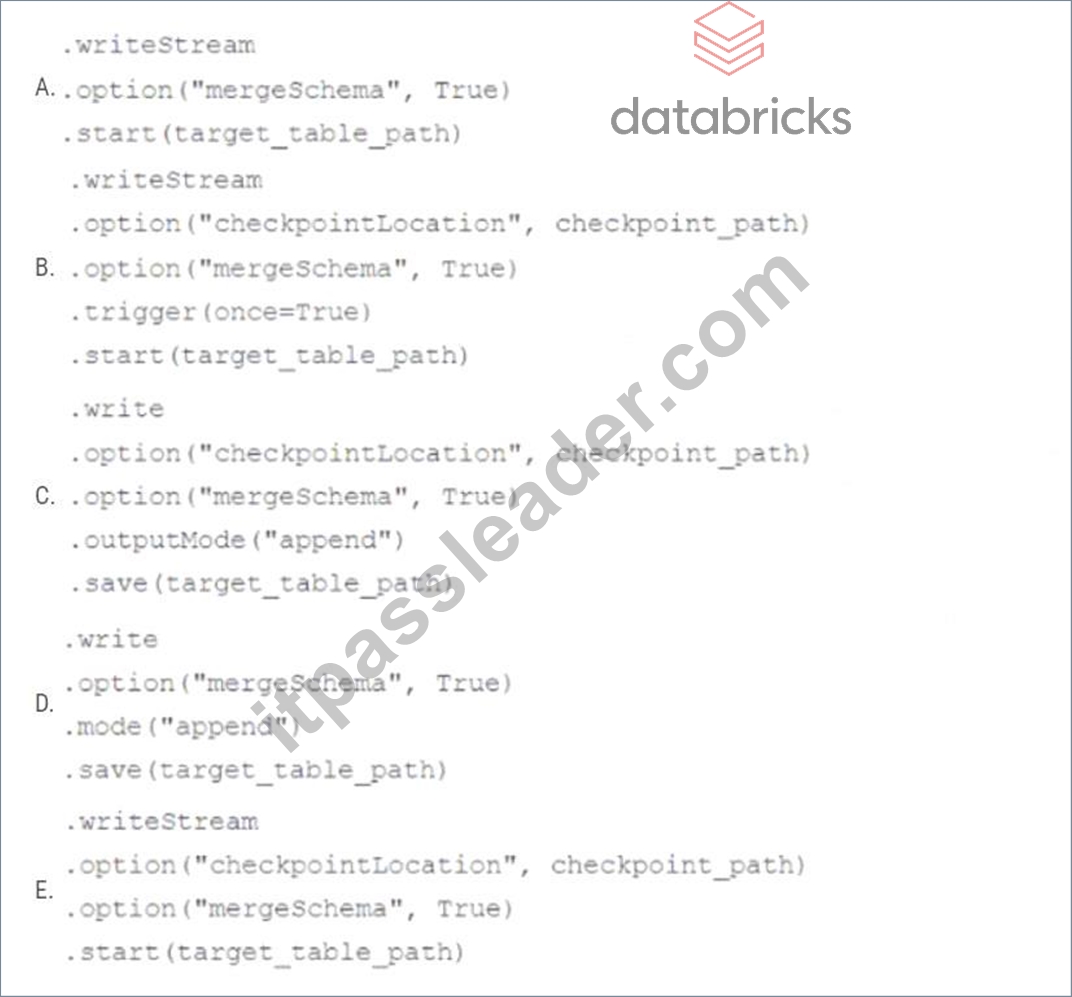
Answer: C
Explanation:
Option B correctly fills in the blank to meet the specified requirements. Option B uses the "cloudFiles.
schemaLocation" option, which is required for the schema detection andevolution functionality of Databricks Auto Loader. Additionally, option B uses the "mergeSchema" option, which is required for the schema evolution functionality of Databricks Auto Loader. Finally, option B uses the "writeStream" method, which is required for the incremental processing of JSON files as they arrive in a source directory. The other options are incorrect because they either omit the required options, use the wrong method, or use the wrong format. References:
* Configure schema inference and evolution in Auto Loader: https://docs.databricks.com/en/ingestion
/auto-loader/schema.html
* Write streaming data: https://docs.databricks.com/spark/latest/structured-streaming/writing-streaming- data.html
NEW QUESTION # 92
Which of the following SQL keywords can be used to append new rows to an existing Delta table?
Answer: C
NEW QUESTION # 93
Given the following error traceback (from display(df.select(3*"heartrate"))) which shows AnalysisException: cannot resolve 'heartrateheartrateheartrate', which statement describes the error being raised?
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "select() expects column names or Column expressions."
Exact extract: "Use col("name") (or df["name"]) to reference a column; Python string operations act on strings, not columns." In Python, "heartrate"*3 is string multiplication that yields "heartrateheartrateheartrate". select() then looks for a column literally named that string. Because no such column exists, Spark raises an analysis error that it "cannot resolve" that column. The correct expression to multiply the column is df.select((F.col("heartrate")*3).alias("heartrate_x3")).
Reference:
NEW QUESTION # 94
......
Databricks-Certified-Professional-Data-Engineer Standard Answers: https://www.itpassleader.com/Databricks/Databricks-Certified-Professional-Data-Engineer-dumps-pass-exam.html