What are the Benefits of Preparing with the DumpsValid Databricks Certified-Data-Engineer-Professional Exam Dumps?

The Certified-Data-Engineer-Professional study guide to good meet user demand, will be a little bit of knowledge to separate memory, every day we have lots of fragments of time. The Certified-Data-Engineer-Professional practice dumps can allow users to use the time of debris anytime and anywhere to study and make more reasonable arrangements for their study and life. Choosing our Certified-Data-Engineer-Professional simulating materials is a good choice for you, and follow our step, just believe in yourself, you can do it perfectly!
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 7. Develop unit and integration tests for data processing code
- 8. Compare streaming tables and materialized views
- Using Python and Tools for Development
- 1. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Develop User-Defined Functions using Pandas/Python UDFs
|
| Topic 2: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
| Topic 3: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Topic 5: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
|
| Topic 6: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Topic 7: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Topic 8: Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 9: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
|
| Topic 10: Cost & Performance Optimisation | - Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
|
>> Prep Certified-Data-Engineer-Professional Guide <<
Certified-Data-Engineer-Professional Sample Questions Pdf, Certified-Data-Engineer-Professional Flexible Testing Engine
The sources and content of our Certified-Data-Engineer-Professional practice dumps are all based on the real Certified-Data-Engineer-Professional exam. And they are the masterpieces of processional expertise these area with reasonable prices. Besides, they are high efficient for passing rate is between 98 to 100 percent, so they can help you save time and cut down additional time to focus on the Certified-Data-Engineer-Professional Actual Exam review only. We understand your drive of the certificate, so you have a focus already and that is a good start.
Databricks Certified Data Engineer Professional Sample Questions (Q205-Q210):
NEW QUESTION # 205
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. Whenever a table is being created, make sure that the location keyword is used.
- B. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- C. When configuring an external data warehouse for all table storage. leverage Databricks for all ELT.
- D. Whenever a database is being created, make sure that the location keyword is used
- E. When tables are created, make sure that the external keyword is used in the create table statement.
Answer: A
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
NEW QUESTION # 206
The data governance team has instituted a requirement that the "user" table containing Personal Identifiable Information (PII) must have the appropriate masking on the SSN column. This means that anyone outside of the HRAdminGroup should see masked social security numbers as ***-**-
****.
The team created a masking function:

What does the data governance team need to do next to achieve this goal?
- A. CREATE TABLE users
(name STRING);
ALTER TABLE users CREATE COLUMN ssn CREATE MASK ssn_mask; - B. CREATE TABLE users
(name STRING, ssn STRING);
ALTER TABLE users ALTER COLUMN ssn SET MASK ssn_mask; - C. CREATE TABLE users
(name STRING, int STRING);
ALTER TABLE users ALTER COLUMN ssn CREATE MASK if is_member('HRAdminGroup'); - D. CREATE TABLE users
(name STRING, ssn INT MASKED ssn_mask);
Answer: B
Explanation:
In Databricks, after creating a masking function, you apply it to a column using ALTER TABLE
<table> ALTER COLUMN <column> SET MASK <mask_function>. The table must already include the column (here, ssn as STRING). This ensures that only users in the HRAdminGroup see the unmasked SSN, while all others see the masked value.
NEW QUESTION # 207
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impressions led to monetizable clicks.
In the code below, Impressions is a streaming DataFrame with a watermark ("event_time", "10 minutes")
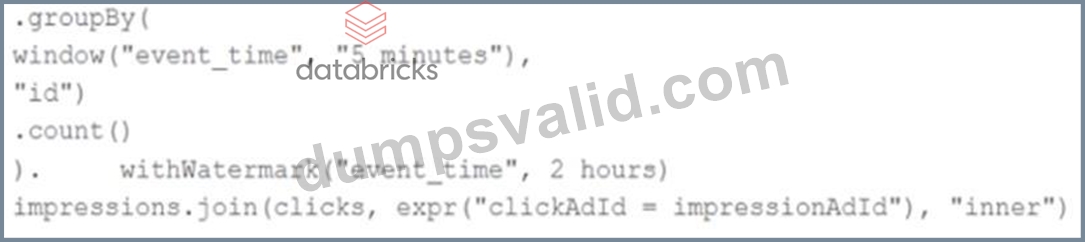
The data engineer notices the query slowing down significantly.
Which solution would improve the performance?
- A. Joining on event time constraint: clickTime >= impressionTime - interval 3 hours and removing watermarks
- B. Joining on event time constraint: clickTime == impressionTime using a leftOuter join
- C. Joining on event time constraint: clickTime >= impressionTime AND clickTime <= impressionTime interval 1 hour
- D. Joining on event time constraint: clickTime + 3 hours < impressionTime - 2 hours
Answer: C
NEW QUESTION # 208
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
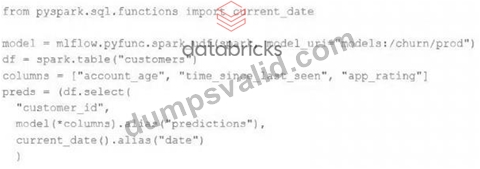
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A.
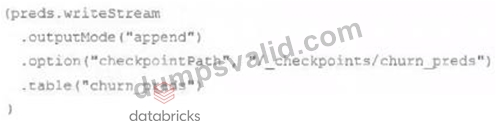
- B.
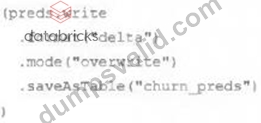
- C. preds.write.mode("append").saveAsTable("churn_preds")
- D. preds.write.format("delta").save("/preds/churn_preds")
- E.
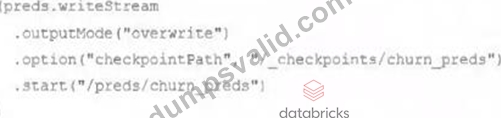
Answer: C
NEW QUESTION # 209
A data engineer is building a streaming data pipeline to ingest JSON files from cloud storage into a Delta Lake table. The pipeline must process files incrementally, handle schema evolution automatically, ensure exactly-once processing, and minimize manual infrastructure management.
How should the data engineer fulfill these requirements?
- A. Use Lakeflow Spart Declarative Pipelines with Auto Loader and enabling schema inference with
"cloudFiles.schemaEvolutionMode"= "addNewColumns" - B. Use Auto Loader in batch mode with a daily job to overwrite the Delta table.
- C. Use Lakeflow Spark Declarative Pipelines with a static DataFrame read, merge schema with spark.conf.set ("spark.databricks.delta.schema.autoMerge.enabled", "true")
- D. Use traditional Spark Structured Streaming with Auto Loader, manually configuring checkpoints location and enabling schema inference with "mergeSchema"= "true"
Answer: A
Explanation:
Lakeflow Spark Declarative Pipelines combined with Auto Loader provide fully managed incremental file ingestion with exactly-once guarantees and minimal operational overhead.
Enabling schema inference and evolution allows new columns in incoming JSON files to be incorporated automatically, satisfying the requirements for streaming ingestion, schema evolution, and reduced manual infrastructure management.
NEW QUESTION # 210
......
With the high employment pressure, more and more people want to ease the employment tension and get a better job. The best way for them to solve the problem is to get the Certified-Data-Engineer-Professional certification. Because the certification is the main symbol of their working ability, if they can own the Certified-Data-Engineer-Professional certification, they will gain a competitive advantage when they are looking for a job. An increasing number of people have become aware of that it is very important for us to gain the Certified-Data-Engineer-Professional Exam Questions in a short time. And our Certified-Data-Engineer-Professional exam questions can help you get the dreamng certification.
Certified-Data-Engineer-Professional Sample Questions Pdf: https://www.dumpsvalid.com/Certified-Data-Engineer-Professional-still-valid-exam.html
- Reliable Certified-Data-Engineer-Professional Exam Tutorial 🧦 Certified-Data-Engineer-Professional Exam Materials 💳 Exam Certified-Data-Engineer-Professional Guide 💺 Search for ➽ Certified-Data-Engineer-Professional 🢪 on ➤ www.pdfdumps.com ⮘ immediately to obtain a free download ⏏Certified-Data-Engineer-Professional Download Free Dumps
- Certified-Data-Engineer-Professional Online Training Materials 🤍 Valid Certified-Data-Engineer-Professional Exam Online 🧹 Certified-Data-Engineer-Professional Online Training Materials 📅 Go to website [ www.pdfvce.com ] open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 🚕Reliable Certified-Data-Engineer-Professional Real Exam
- Certified-Data-Engineer-Professional Exam Engine 👋 Exam Certified-Data-Engineer-Professional Guide 🦱 Valid Certified-Data-Engineer-Professional Exam Online 🦘 Copy URL [ www.prepawayexam.com ] open and search for ▶ Certified-Data-Engineer-Professional ◀ to download for free 🛕Certified-Data-Engineer-Professional Exam Engine
- Free PDF Prep Certified-Data-Engineer-Professional Guide - Top Databricks Certification Training - Updated Databricks Databricks Certified Data Engineer Professional 👑 Search for ⮆ Certified-Data-Engineer-Professional ⮄ and download exam materials for free through ☀ www.pdfvce.com ️☀️ 👨Reliable Certified-Data-Engineer-Professional Exam Tutorial
- Certified-Data-Engineer-Professional Valid Braindumps Sheet 📰 Exam Certified-Data-Engineer-Professional Actual Tests 🍡 Certified-Data-Engineer-Professional Download Free Dumps 🦩 Search for { Certified-Data-Engineer-Professional } and easily obtain a free download on ( www.pass4test.com ) 🍋Pdf Certified-Data-Engineer-Professional Version
- 100% Pass Quiz Databricks - Certified-Data-Engineer-Professional Newest Prep Guide 🧖 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free on ➤ www.pdfvce.com ⮘ website 🧺Latest Certified-Data-Engineer-Professional Real Test
- 100% Pass Quiz Databricks - Certified-Data-Engineer-Professional Newest Prep Guide 🚘 Open ➡ www.pdfdumps.com ️⬅️ enter ▷ Certified-Data-Engineer-Professional ◁ and obtain a free download 🍲Training Certified-Data-Engineer-Professional Tools
- Guaranteed Passing Certified-Data-Engineer-Professional online Textbook 🗳 Immediately open ( www.pdfvce.com ) and search for 「 Certified-Data-Engineer-Professional 」 to obtain a free download ⚪Exam Certified-Data-Engineer-Professional Actual Tests
- Training Certified-Data-Engineer-Professional Tools 🕐 Certified-Data-Engineer-Professional Study Dumps 🥏 Exam Certified-Data-Engineer-Professional Actual Tests 🛥 Search for ✔ Certified-Data-Engineer-Professional ️✔️ and download it for free on ⇛ www.practicevce.com ⇚ website 😸Exam Certified-Data-Engineer-Professional Actual Tests
- Certified-Data-Engineer-Professional Exam Engine 🐥 Latest Certified-Data-Engineer-Professional Test Guide 🟥 Latest Certified-Data-Engineer-Professional Real Test 🐅 Open ⇛ www.pdfvce.com ⇚ and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download exam materials for free 🍊Reliable Certified-Data-Engineer-Professional Real Exam
- Hot Prep Certified-Data-Engineer-Professional Guide 100% Pass | Pass-Sure Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 100% Pass 🪒 Search for ( Certified-Data-Engineer-Professional ) and obtain a free download on 【 www.dumpsquestion.com 】 👐Reliable Certified-Data-Engineer-Professional Real Exam
- justpaste.me, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes