BONUS!!! Download part of DumpsReview NCP-BC-7.5 dumps for free: https://drive.google.com/open?id=1TmbfA1jlvtKIVBvIFwcKGMtc6Fj01BcY
We will free provide you part of the exercises of Nutanix Certification NCP-BC-7.5 Exam on the Internet to let you try to test our product's quality. After your trail you will find DumpsReview's exercises is the most comprehensive one and is what you want to.
| Section | Objectives |
|---|---|
| Topic 1: Disaster Recovery Fundamentals | - Business Continuity Principles - DR Concepts (RPO, RTO, SLAs) |
| Topic 2: Recovery Operations | - Failover and Failback Procedures - Recovery Plans and Orchestration - Test Recovery Workflows |
| Topic 3: Prism Central Management | - Cluster and Site Management - DR Monitoring and Operations |
| Topic 4: Data Protection and Backup Integration | - Snapshot Management - Backup Solutions Integration |
| Topic 5: Nutanix Disaster Recovery Architecture | - Protection Domains - Nutanix Leap Overview - Replication Types (Sync/Async) |
Are you still worried about the exam? Don't worry! Our NCP-BC-7.5 exam torrent can help you overcome this stumbling block during your working or learning process. Under the instruction of our NCP-BC-7.5 test prep, you are able to finish your task in a very short time and pass the exam without mistakes to obtain the NCP-BC-7.5 certificate. We will tailor services to different individuals and help them take part in their aimed exams after only 20-30 hours practice and training. Moreover, we have experts to update NCP-BC-7.5 quiz torrent in terms of theories and contents on a daily basis.
NEW QUESTION # 14
An administrator is creating a recovery plan between two availability zones. The production VMs use a subnet that does not exist at the recovery AZ. To ensure the VMs can successfully connect after a failover, what must be configured?
Answer: B
Explanation:
When failing over a virtual machine between different physical locations or availability zones, it is common for the network topology at the recovery site to differ from the primary site. If a VM is recovered into a site where its original subnet is unavailable, it will lose connectivity.
To resolve this, Nutanix Recovery Plans include a " Network Mapping " section. The administrator must configure these mappings to explicitly define which production subnet at the source site corresponds to which valid subnet at the recovery site. During the failover process, the orchestrator uses this mapping to automatically re-configure the VM ' s virtual network interface (vNIC) to connect to the correct local VLAN or overlay network at the destination. While " matching subnet names " (Option D) can simplify management, it is not a requirement if the mapping is correctly defined. Synchronous replication (Option B) does not address the networking layer, as it is a storage-level feature. Network mapping is therefore the essential task for ensuring that workloads are not only recovered but also accessible following a failover.
NEW QUESTION # 15
After an unplanned outage, all VMs were successfully failed over to the recovery site, and users are now accessing workloads from there. The DR dashboard shows the failover is complete and replication from the original primary site has stopped. As part of post-failover cleanup, what is the most appropriate next action to ensure the DR configuration reflects the current production state and is ready for future protection?
Answer: A
Explanation:
Following a successful unplanned failover, the " Recovery Site " has technically become the new " Production Site " . However, the data protection relationship is now one-sided; while the VMs are running at the recovery site, they are likely no longer being replicated anywhere because the original protection policy was designed to move data from the (now failed) primary site to the recovery site.
The most critical post-failover task is to " re-protect " the workloads. This involves updating the Protection Policies in Prism Central to establish a new replication direction, typically from the current active site (the old recovery site) back to the original primary site (once it is restored) or to a third availability zone. Without re- protection, the business is running its production workloads without a safety net, leaving them vulnerable to a second failure. Deleting recovery points (Option A) is dangerous as it removes the only historical data available. Leaving the environment as-is (Option B) ignores the lack of ongoing protection. Initiating an immediate failback (Option D) is often impossible or unwise until the original site is fully stabilized and the data has been synchronized back. Therefore, establishing a new protection stream is the mandatory next step for operational resilience.
NEW QUESTION # 16
An administrator performed an unplanned failover from AZ1 (primary) to AZ2 (recovery). Later, AZ1 is restored and the administrator wants to fail back the entities to AZ1. Which two statements are correct?
(Choose two.)
Answer: C,D
Explanation:
Nutanix Disaster Recovery is designed to be bi-directional, supporting both failover and failback . In an unplanned failover, the primary site (AZ1) is assumed to have crashed. Once AZ1 is brought back online, the system must synchronize any data changes that occurred while the VMs were running at AZ2.
Statement C is correct because once the VMs are powered on at AZ2, the Nutanix Cerebro service automatically reverses the protection policy. New recovery points are created at AZ2 and replicated back to AZ1. For a successful, modern failback with zero data loss from the cloud session, the administrator must wait for these recovery points to replicate back to AZ1 before initiating the failback.
Statement B is also correct and describes a specific " recovery of last resort " scenario. If AZ1 is restored but connectivity to AZ2 is permanently lost (e.g., the cloud provider has an issue), an administrator can still " Unplanned Failover " back to AZ1 using the historical snapshots that existed locally on AZ1 before the original outage. This would result in data loss equal to the time the VMs were running at AZ2, but it allows for service restoration when the recovery site itself fails. These two statements highlight the flexibility of the Nutanix DR architecture in handling both controlled failback and emergency local restoration.
NEW QUESTION # 17
An administrator has received the following alert: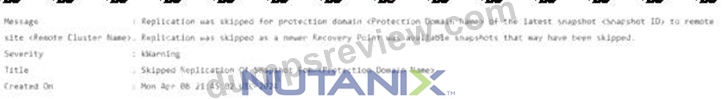
Replication was skipped for protection domain < Protection Domain Name > of the latest snapshot < Snapshot ID > to remote site < Remote Cluster Name > . Replication was skipped as a newer Recovery Point was available snapshots that may have been skipped.
The administrator begins gathering troubleshooting information and determines the following:
* The VM has been replicating to this cluster successfully for at least 6 months
* The bandwidth has been sufficient to this point and hasn ' t caused an issue before
* Network connectivity is good and all necessary ports remain open and reachable
* There aren ' t hardware issues, and software is up to date
What else could have caused this alert?
Answer: D
Explanation:
The Nutanix Cerebro service manages replication by scheduling snapshots and transferring the delta changes to the remote site. In an asynchronous replication schedule, if a new snapshot is taken before the previous one has finished replicating, the system faces a choice. To ensure that the most current data is available at the recovery site as quickly as possible, Nutanix may " skip " the replication of an older pending snapshot in favor of starting the replication of the newest one.
In this scenario, all infrastructure components (bandwidth, ports, hardware) are verified as healthy and have supported successful replication for months. This points toward a data-level issue rather than a connectivity issue. A " significant one-time surge in change rate " (Option D) means the VM generated a massive amount of new data blocks (churn) in a short period. Because the " Snapshot-on-wire " transfer size is directly tied to the number of changed blocks, this specific snapshot would take much longer than usual to replicate. If the transfer time exceeds the RPO interval, the next scheduled snapshot will trigger. The Cerebro service will see that it has a newer recovery point ready to go and will skip the " stuck " or slow-moving older snapshot to maintain the most recent RPO possible at the target. This behavior generates the " Replication was skipped " warning to notify the administrator that the historical sequence was interrupted due to a temporary imbalance between data churn and available throughput.
NEW QUESTION # 18
An administrator performs these steps while configuring Nutanix Disaster Recovery:
* Create VMs on Site A in a container named SalesA
* Create a new container on Site B named SalesB
* Create new Protection Policy name Async
* Place all the new Sales VMs in the Protection Policy named Async
* Set a schedule to begin taking hourly snapshots immediately
After performing the steps, replications begin without any errors. After two hours, the administrator checks on the progress on the remote site and finds that the SalesB container is showing 0 bytes.
What went wrong?
Answer: D
Explanation:
In a Nutanix Disaster Recovery environment using Protection Policies (Prism Central-based), the system needs to know which storage container at the recovery site should receive the replicated data from the primary site. This is known as " Container Mapping. " By default, Nutanix uses an " Automatic Container Mapping " feature to simplify administration.
The automatic mapping logic relies on matching names. If a VM is in a container named SalesA at Site A, the system will look for a container named SalesA at Site B to land the data. If the administrator manually created a container at the recovery site but named it SalesB (as in this scenario), the automatic mapping will fail because the names do not match. The system will instead attempt to find a container with the same name, and if it fails to find one, it may create a new one automatically or replication might fail. The fact that SalesB shows 0 bytes confirms that no data was ever sent to that specific container. To fix this, the administrator should either rename the destination container to match the source (SalesA) or manually configure a " Storage Container Mapping " in Prism Central that explicitly links the SalesA container on Cluster A to the SalesB container on Cluster B.
NEW QUESTION # 19
......
As the saying goes, knowledge has no limits. You may be old but the spirit of endless learning won't be old. If you attend the test of NCP-BC-7.5 certification you will update your stocks of knowledge and improve your actual abilities, buying our NCP-BC-7.5 exam practice materials can help you pass the test smoothly. There are no threshold limits to attend the NCP-BC-7.5 test such as the age, sexuality, education background and your job conditions, and anybody who wishes to improve their volume of knowledge and actual abilities can attend the NCP-BC-7.5 test.
Associate NCP-BC-7.5 Level Exam: https://www.dumpsreview.com/NCP-BC-7.5-exam-dumps-review.html
DOWNLOAD the newest DumpsReview NCP-BC-7.5 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1TmbfA1jlvtKIVBvIFwcKGMtc6Fj01BcY