DEA-C02 Reliable Braindumps Free | DEA-C02 Dump

BONUS!!! Download part of PassLeaderVCE DEA-C02 dumps for free: https://drive.google.com/open?id=1945oNPYNu2R0KrDdwaZoa6fOfn7eFRWo
Our passing rate is very high to reach 99% and our DEA-C02 exam torrent also boost high hit rate. Our DEA-C02 study questions are compiled by authorized experts and approved by professionals with years of experiences. They are compiled according to the latest development conditions in the theory and practice and the questions and answers are based on real exam. Our DEA-C02 study questions are linked tightly with the exam papers in the past and conform to the popular trend in the industry. Our product convey you more important information with less amount of the questions and answers. Thus we can be sure that our DEA-C02 guide torrent are of high quality and can help you pass the exam with high probability.
| Section | Objectives |
|---|
| Data Engineering Fundamentals | - Data pipelines concepts and patterns
- Snowflake architecture for data engineering
|
| Performance and Optimization | - Warehouse sizing and scaling
- Clustering and partition strategies
- Query optimization techniques
|
| Data Ingestion and Integration | - Snowpipe usage and automation
- Staging data and loading mechanisms
- Batch and streaming ingestion approaches
|
| Data Transformation and Processing | - Streams and Tasks for ELT pipelines
- Handling semi-structured data (JSON, Avro, Parquet)
- SQL-based transformations in Snowflake
|
| Security and Data Governance | - Secure data sharing
- Data masking and encryption
- Role-based access control (RBAC)
|
>> DEA-C02 Reliable Braindumps Free <<
Snowflake DEA-C02 Dump - DEA-C02 Test Guide Online
Our materials can make you master the best DEA-C02 questions torrent in the shortest time and save your much time and energy to complete other thing. What most important is that our DEA-C02 study materials can be download, installed and used safe. We can guarantee to you that there no virus in our product. Not only that, we also provide the best service and the best DEA-C02 Exam Torrent to you and we can guarantee that the quality of our DEA-C02 learning dump is good. So please take it easy after the purchase and we won’t let your money be wasted.
Snowflake SnowPro Advanced: Data Engineer (DEA-C02) Sample Questions (Q347-Q352):
NEW QUESTION # 347
A Snowflake data pipeline ingests data from multiple external sources into a RAW DATA table. A transformation process then moves the data to a ANALYTICS DATA table, applying several complex UDFs written in Java and Python for data cleansing and enrichment. Performance is significantly slower than expected. Which combination of techniques would BEST improve the performance of this transformation pipeline?
- A. Rewrite the UDFs in SQL or Snowpark Python/Java for better integration with the Snowflake engine and leverage vectorization where possible; cache intermediate results using temporary tables.
- B. Reduce the number of UDF calls by consolidating them into a single, more complex UDF. Replace the transformation pipeline with a series of COPY INTO statements.
- C. Use external functions instead of UDFs to offload the processing to an external compute environment and configure auto-scaling for the virtual warehouse.
- D. Implement data partitioning in the RAW DATA table based on ingestion time and switch to using stored procedures instead of transformation pipelines.
- E. Increase the virtual warehouse size and re-cluster the ANALYTICS DATA table based on the most frequently filtered columns.
Answer: A
Explanation:
Rewriting UDFs in SQL or Snowpark allows the Snowflake engine to optimize them more effectively. Using temporary tables to cache intermediate results prevents redundant computation. Option A helps, but addressing UDF performance is more crucial. Option C might add complexity. Option D is irrelevant to UDF performance. Option E is counterproductive; consolidating UDFs can reduce parallelism and COPY INTO is for initial data loading, not transformation.
NEW QUESTION # 348
You are tasked with calculating the daily moving average of sales for each product category in your Snowflake data warehouse using Snowpark Python. You need to handle cases where there might be missing sales data for certain days. You have the following sales data available in a table named with columns: (DATE), (VARCHAR), and 'sales_amount' (NUMBER). Which of the following Snowpark Python code snippets correctly calculates the 7-day moving average of sales amount per product category, filling in missing sales days with 0, and handles potential division by zero?
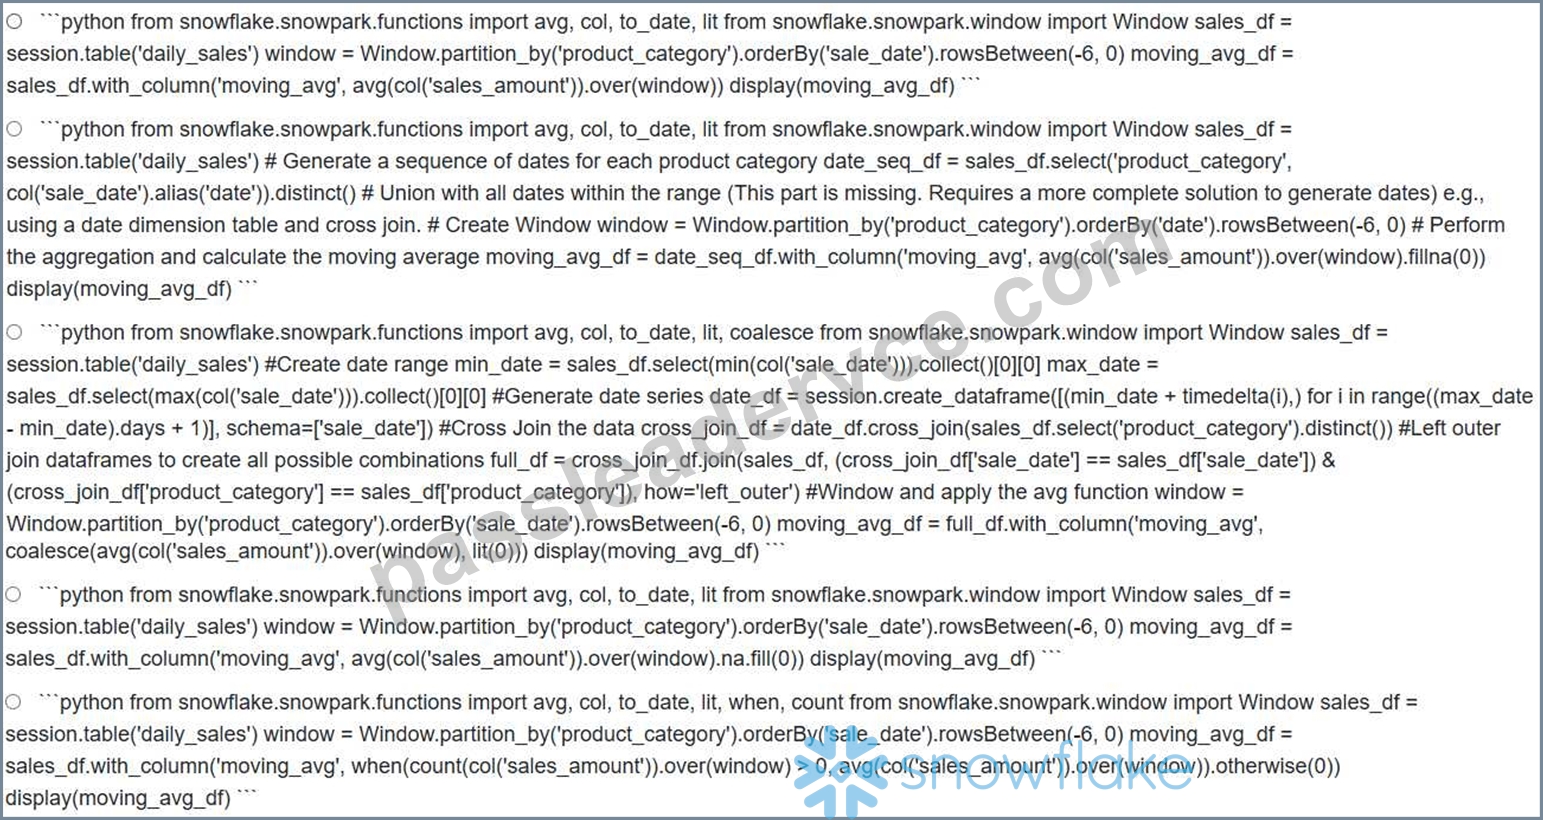
- A. Option A
- B. Option C
- C. Option D
- D. Option B
- E. Option E
Answer: B
Explanation:
Option C correctly addresses the problem by first generating a date series to account for missing dates. The solution then does cross join to generate the data, followed by the window aggregation and coalesce, which correctly uses the avg window operation filling zero for the null values.
NEW QUESTION # 349
You are designing a data sharing solution in Snowflake where a provider account shares a view with a consumer account. The view is based on a table that undergoes frequent DML operations (inserts, updates, deletes). The consumer account needs to see a consistent snapshot of the data, even during these DML operations. Which of the following strategies, or combination of strategies, would be MOST effective in ensuring data consistency from the consumer's perspective, and what considerations should be made?
- A. Creating a stream on the base table in the provider account and building a view on top of the stream. This way, changes are only reflected when the stream is consumed, allowing for batch processing and controlled updates in the consumer account.
- B. A and B
- C. Creating a standard view in the provider account and relying on Snowflake's inherent transactional consistency. The consumer account will always see a consistent snapshot of the data as it existed at the beginning of their query execution. No additional configurations are necessary.
- D. Using Snowflake's Time Travel feature by querying the view with a specific 'AT' or 'BEFORE' clause in the consumer account. The provider account needs to inform the consumer account of a specific timestamp that guarantees consistency, adding administrative overhead.
- E. Creating a materialized view in the provider account and sharing that materialized view. This adds compute costs to the provider but ensures a consistent snapshot for the consumer account. The materialized view needs to be refreshed periodically, based on the rate of DML changes.
Answer: C
Explanation:
Snowflake's architecture inherently provides transactional consistency. When the consumer account queries the shared view, they will see a consistent snapshot of the data as it existed at the beginning of their query execution. No additional mechanisms like Time Travel (A) or materialized views (B) are strictly necessary to ensure consistency. While streams (D) can be useful for change data capture, they don't directly guarantee consistency for a standard view shared with a consumer. Time travel in this case would also require significant coordination overhead.
NEW QUESTION # 350
Consider the following Snowflake Javascript UDF designed to convert temperatures between Celsius and Fahrenheit:
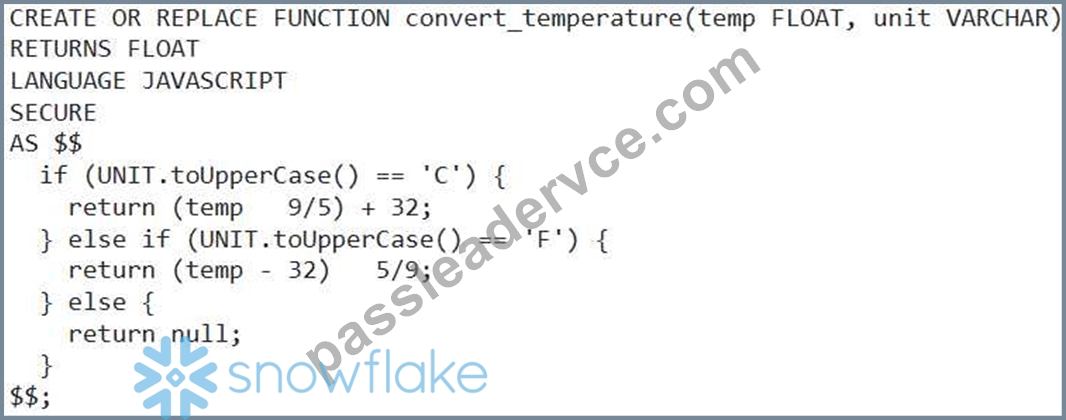
Which statement regarding the UDF's security and behavior is MOST accurate?
- A. The 'SECURE' keyword ensures that the UDF's code is completely hidden from all users, including those with the ACCOUNTADMIN role.
- B. The UDF is not vulnerable to SQL injection because Javascript UDFs in Snowflake are sandboxed and prevent direct SQL execution.
- C. The UDF will always return a value, even if the input 'unit is invalid, due to the implicit type conversion in JavaScript.
- D. The UDF is vulnerable to SQL injection because the 'unit' parameter is not validated against a predefined list of acceptable values.
- E. While the ' SECURE keyword hides the UDF's source code from users without sufficient privileges, users with the ACCOUNTADMIN role can still view the source code.
Answer: B
Explanation:
JavaScript UDFs in Snowflake are sandboxed, preventing SQL injection vulnerabilities. The SECURE keyword hides the UDF definition from users without appropriate privileges, but not from users with sufficient privileges like ACCOUNTADMIN. The UDF explicitly returns NULL for invalid unit values.
NEW QUESTION # 351
A data engineer observes that a Snowflake query, used for generating a daily sales report, consistently runs slower each day, despite the dataset size remaining relatively stable. The query joins a large sales table (SALES) with a smaller product dimension table (PRODUCT) on PRODUCT ID. You've already confirmed that virtual warehouse sizing is adequate and data clustering is enabled on SALES(SALE DATE). Analyze the following scenarios and identify the MOST likely cause of the performance degradation and potential solution:
- A. The join between SALES and PRODUCT is causing excessive data spill to local storage due to an inefficient join order. Consider using a JOIN hint, specifically a BROADCAST hint on the PRODUCT table (small table).
- B. The statistics on the PRODUCT table are outdated. Run 'ANALYZE TABLE PRODUCT' to refresh them.
- C. The Snowflake query optimizer is selecting a suboptimal execution plan because the query is complex. Rewrite the query using temporary tables to break down the logic into smaller steps.
- D. The data clustering on SALES(SALE DATE) is ineffective as the query also filters on PRODUCT CATEGORY, which isn't clustered. Re-cluster SALES by both SALE DATE and PRODUCT CATEGORY.
- E. The virtual warehouse is being overwhelmed by concurrent queries. Implement workload management rules to prioritize the sales report query.
Answer: A
Explanation:
The most likely cause is inefficient join processing leading to data spilling. Broadcasting the smaller PRODUCT table to all nodes improves join performance by avoiding data redistribution. Option A might help, but broadcasting is more impactful. Option C is incorrect because only one column can be explicitly used for clustering. Option D is a last resort; the optimizer should handle a simple join. Option E is less likely if the overall data volume hasn't changed.
NEW QUESTION # 352
......
Snowflake DEA-C02 certified examinations questions are collected and edited by latest exam teaching program and real test questions materials. We are engaged in updating our training materials constantly. If you are afraid that once you purchase our current version of DEA-C02 Certified examinations questions, then there is new update version, current version will be out, please rest assured that you can download free our latest version one we release new version within one year.
DEA-C02 Dump: https://www.passleadervce.com/SnowPro-Advanced/reliable-DEA-C02-exam-learning-guide.html
- New DEA-C02 Test Sims 💛 Reliable DEA-C02 Test Labs ⏳ DEA-C02 Valid Test Voucher 🐱 Immediately open ⏩ www.prepawayete.com ⏪ and search for 【 DEA-C02 】 to obtain a free download ⚪Examcollection DEA-C02 Questions Answers
- Use Snowflake DEA-C02 PDF Format on Smart Devices 🥓 Download ▷ DEA-C02 ◁ for free by simply entering “ www.pdfvce.com ” website 🦳Examcollection DEA-C02 Questions Answers
- Snowflake DEA-C02 Exam Questions: Attain Your Professional Career Targets [2026] 🟩 Enter ▛ www.prep4away.com ▟ and search for ⮆ DEA-C02 ⮄ to download for free 💛Cost Effective DEA-C02 Dumps
- Pass Guaranteed 2026 DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) Fantastic Reliable Braindumps Free 🧰 Download 【 DEA-C02 】 for free by simply entering 【 www.pdfvce.com 】 website 🆔Exam Dumps DEA-C02 Demo
- Exam DEA-C02 Question 🏍 Exam Dumps DEA-C02 Demo 🏺 Official DEA-C02 Practice Test 🙁 Copy URL 「 www.practicevce.com 」 open and search for ➤ DEA-C02 ⮘ to download for free 👴Exam Dumps DEA-C02 Demo
- Pass Guaranteed Quiz 2026 Snowflake Perfect DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) Reliable Braindumps Free 👞 Download 「 DEA-C02 」 for free by simply searching on ➤ www.pdfvce.com ⮘ 🛒Brain Dump DEA-C02 Free
- DEA-C02 Labs 🖕 Pass4sure DEA-C02 Study Materials 🆓 Exam DEA-C02 Quiz 📤 Search for ▷ DEA-C02 ◁ and obtain a free download on ⇛ www.dumpsmaterials.com ⇚ 🐮DEA-C02 Updated Test Cram
- Use Snowflake DEA-C02 PDF Format on Smart Devices 🛵 Open website ⇛ www.pdfvce.com ⇚ and search for ⮆ DEA-C02 ⮄ for free download 🍪Official DEA-C02 Practice Test
- HOT DEA-C02 Reliable Braindumps Free: SnowPro Advanced: Data Engineer (DEA-C02) - The Best Snowflake DEA-C02 Dump 🏹 Simply search for ▶ DEA-C02 ◀ for free download on “ www.testkingpass.com ” 🎵Brain Dump DEA-C02 Free
- Pass Guaranteed 2026 Professional DEA-C02: SnowPro Advanced: Data Engineer (DEA-C02) Reliable Braindumps Free 🚅 ▛ www.pdfvce.com ▟ is best website to obtain ✔ DEA-C02 ️✔️ for free download 🐞Exam Dumps DEA-C02 Demo
- Use Snowflake DEA-C02 PDF Format on Smart Devices 🎀 Copy URL 《 www.prepawaypdf.com 》 open and search for ✔ DEA-C02 ️✔️ to download for free 🧑DEA-C02 Detailed Study Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, hashnode.com, rare-books.library.sites.carleton.edu, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest PassLeaderVCE DEA-C02 PDF Dumps and DEA-C02 Exam Engine Free Share: https://drive.google.com/open?id=1945oNPYNu2R0KrDdwaZoa6fOfn7eFRWo