P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Exam4Free: https://drive.google.com/open?id=1OgBidEwuMcdIQ3hp5bAQbwo7mrFkqzgf
Exam4Free is growing faster and many people find that obtaining a certificate has outstanding advantage over other peer, especially for promotion or applying for a large company. Exam4Free helps fresh people enter into this area and help experienced workers have good opportunities for further development. Thus our passing rate of best SPS-C01 Study Guide materials is nearly highest in this area. That's why we grows rapidly recent years and soon become the pioneer in SPS-C01 qualification certificate learning guide providers. Our SPS-C01 study guide will be your best choice to help you clear exam certainly.
| Section | Objectives |
|---|---|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Data Engineering with Snowpark | - Pipeline development
|
Under the hatchet of fast-paced development, we must always be cognizant of social long term goals and the direction of the development of science and technology. Adapt to the network society, otherwise, we will take the risk of being obsoleted. Although our SPS-C01 exam dumps have been known as one of the world’s leading providers of exam materials, you may be still suspicious of the content. For your convenience, we especially provide several demos for future reference and we promise not to charge you of any fee for those downloading. Therefore, we welcome you to download to try our SPS-C01 Exam for a small part. Then you will know whether it is suitable for you to use our SPS-C01 test questions. There are answers and questions provided to give an explicit explanation. We are sure to be at your service if you have any downloading problems.
NEW QUESTION # 271
You've developed a Snowpark Python UDTF that performs complex data transformation. This UDTF needs to be operationalized within a data pipeline. You want to ensure high performance and scalability. Which of the following strategies will be MOST effective in operationalizing this UDTF?
Answer: C
Explanation:
Registering the UDTF as a permanent function allows it to be reused across multiple sessions and data pipelines. Appropriate resource allocation, such as selecting an appropriate warehouse size, ensures sufficient compute resources for the UDTF's execution. Vectorization within the UDTF implementation can significantly improve performance by processing data in batches. External functions introduce additional complexity and potential latency. Temporary functions are not suitable for operationalization. Option D is incorrect because it negates the benefits of Snowpark's scalability. Option E is incorrect because proper resource sizing is necessary.
NEW QUESTION # 272
A Snowpark Python application is failing intermittently with a 'net.snowflake.client.jdbc.SnowflakeSQLException: SQL execution error: Remote service internal error [Errorld: ...l' when calling 'df.collect()' on a DataFrame that results from joining multiple tables and applying a complex filter. The data volume is substantial, but within the warehouse's expected capacity. Which of the following actions are MOST likely to resolve this issue? (Select two)
Answer: C,E
Explanation:
Options B and C are the most likely to resolve the issue. Option B addresses potential memory pressure within Snowflake by breaking down the query and persisting intermediate results. Option C acknowledges that the error might be transient due to resource contention and implements retry logic. Increasing (A) is unlikely to solve a remote service internal error. 'df.toPandas()' (D) might exacerbate the problem by moving more data to the client. Using (E) is a workaround, but doesn't address the underlying problem within Snowpark and could reduce performance if not carefully optimized.
NEW QUESTION # 273
You are developing a Snowpark stored procedure in Python to perform sentiment analysis on customer reviews. The procedure relies on a custom Python library, 'sentiment_analyzer.py' , which is not available in Snowflake's default Anaconda channel. You also need to include the 'nltk' library. Which of the following approaches is the MOST efficient and recommended way to make both dependencies available to your stored procedure within Snowflake?
Answer: A
Explanation:
Option C is the most efficient and recommended approach. Snowflake allows importing dependencies from a stage as a ZIP file. This avoids the complexity of creating a custom Anaconda package (Option B) or manually managing dependencies on each virtual warehouse node (Option D), which is not supported. Directly including the code (Option E) makes the procedure large and difficult to manage. Using (Option A) is generally discouraged as it's less robust for dependency management in Snowpark stored procedures.
NEW QUESTION # 274
Consider a Snowflake table 'orders' with columns 'order_id', 'customer_id', 'order_date', and 'status'. You need to update the 'status' of all orders placed before January 1, 2023, to 'Archived'. Which of the following approaches is the most efficient and idiomatic way to achieve this using Snowpark DataFrames, assuming 'orders df DataFrame represents the 'orders' table?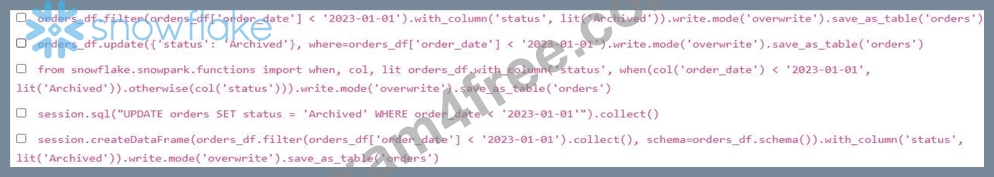
Answer: C,E
Explanation:
Options C and D are both valid and efficient solutions. Option C leverages Snowpark's 'with_column' and 'when' functions to conditionally update the 'status' column within the DataFrame and persists the changes back to the table using 'save_as_table'. Using lit function makes sure that 'Archived' status is passed as a literal. Option D uses a direct SQL update statement executed through the Snowpark session. This bypasses DataFrame operations but directly modifies the table, which can sometimes be more efficient for simple update operations. Option A is almost correct but the with_column and filter are applied separately. Option B doesn't work due to the way update functions are implemented in Snowpark. Option E unnecessarily collects the filtered data back to the driver, creating a new DataFrame from the collected data, then applying 'with_column'. This is an inefficient approach.
NEW QUESTION # 275
You are using Snowflake Notebooks to develop a Snowpark application and want to leverage a custom Python library that is not available in the default environment. What steps are necessary to make this library available within your Snowflake Notebook?
Answer: C
Explanation:
Snowflake Notebooks primarily use conda environment specification files ('environment.yml') (B) to manage dependencies. You specify the required libraries in the 'environment.ymr file, upload it to a stage, and use it when creating or updating the Notebook environment. Uploading raw .pV files (A) might work for simple modules, but lacks dependency management. Using '!pip install' (C and E) directly in the notebook is not the intended way to manage dependencies in Snowflake Notebooks for production scenarios and might not persist across sessions.
NEW QUESTION # 276
......
When you have adequately prepared for the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) questions, only then you become capable of passing the Snowflake exam. There is no purpose in attempting the Snowflake SPS-C01 certification exam if you have not prepared with Exam4Free's Free Snowflake SPS-C01 PDF Questions. It's time to get serious if you want to validate your abilities and earn the Snowflake SPS-C01 Certification. If you hope to pass the Snowflake Certified SnowPro Specialty - Snowpark exam on your first attempt, you must be studied with real SPS-C01 exam questions verified by Snowflake SPS-C01.
Latest SPS-C01 Exam Questions: https://www.exam4free.com/SPS-C01-valid-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Exam4Free: https://drive.google.com/open?id=1OgBidEwuMcdIQ3hp5bAQbwo7mrFkqzgf