DumpExam try hard to makes Databricks Databricks Certified Data Engineer Professional exam preparation easy with its several quality features. Our Certified-Data-Engineer-Professional exam dumps come with 100% refund assurance. We are dedicated to your accomplishment, hence pledges you victory in Certified-Data-Engineer-Professional Certification exam in a single attempt. If for any reason, a user fails in Certified-Data-Engineer-Professional exam then he will be refunded the money after the process. Also, we offer one year free updates to our Certified-Data-Engineer-Professional Exam esteemed users; and these updates will be entitled to your account right from the date of purchase. Also the 24/7 Customer support is given to users, who can email us if they find any haziness in the Certified-Data-Engineer-Professional exam dumps, our team will merely answer to your all Certified-Data-Engineer-Professional exam product related queries.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Topic 2: Data Modeling | ~10% | - Apply dimensional modeling techniques - Design scalable Delta Lake schemas and clustering |
| Topic 3: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
| Topic 4: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 5: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 6: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables - Diagnose common pipeline and job failures |
| Topic 7: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Topic 8: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 9: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
>> Certified-Data-Engineer-Professional Valid Test Sims <<
So rest assured that with the DumpExam Certified-Data-Engineer-Professional exam questions you will get everything that is necessary for Certified-Data-Engineer-Professional exam preparation and success. Take a decision right now and just get registered in the Databricks Certified-Data-Engineer-Professional certification exam and start preparation with DumpExam Certified-Data-Engineer-Professional Exam Questions.You do not need to get worried about it choose the right DumpExam Databricks Certified Data Engineer Professional exam questions formats and start this journey without wasting further time.
NEW QUESTION # 179
The data science team has created and logged a production model using MLflow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, loads the customers table containing the customer_id key column into a DataFrame, and defines the feature columns needed for the model.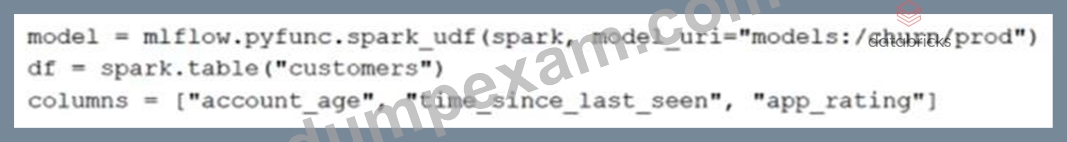
Which code block will output a DataFrame with the schema "customer_id LONG, predictions DOUBLE"?
Answer: E
Explanation:
This code block applies the Spark UDF created from the MLflow model to the DataFrame df by selecting the existing customer_id column and the new column produced by the model, which is aliased to predictions. The model(*columns) part is where the UDF is applied to the columns specified in the columns list, and alias("predictions") is used to name the output column of the model's predictions. This will result in a DataFrame with the desired schema: "customer_id LONG, predictions DOUBLE".
NEW QUESTION # 180
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
Answer: C
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 181
A data engineer is setting up a pipeline to ingest data from a message bus system that occasionally delivers duplicate messages. The duplicate messages can be a week apart. The target is a Databricks Delta Lake table where each record should appear exactly once. Which Databricks ingestion pattern should be implemented to handle potential duplicates where events can arrive outside of the configured watermark?
Answer: A
Explanation:
Using MERGE INTO with a unique key enforces idempotent writes at the Delta Lake table level.
This approach reliably handles duplicates even when events arrive far outside any streaming watermark, ensuring that each logical record is written exactly once regardless of arrival time.
NEW QUESTION # 182
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
Answer: C
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column.
NEW QUESTION # 183
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
Answer: C
Explanation:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
NEW QUESTION # 184
......
Any questions related with our Certified-Data-Engineer-Professional study prep will be responded as soon as possible, and we take good care of each exam candidates’ purchase order, sending the updates for you and solve your questions on our Certified-Data-Engineer-Professional exam materials 24/7 with patience and enthusiasm. So do not capitulate to difficulties, because we will resolve your problems of the Certified-Data-Engineer-Professional Training Materials. You will get the most useful help form our service on the Certified-Data-Engineer-Professional training guide.
Latest Certified-Data-Engineer-Professional Test Labs: https://www.dumpexam.com/Certified-Data-Engineer-Professional-valid-torrent.html