What's more, part of that PassTestking DP-800 dumps now are free: https://drive.google.com/open?id=1RKqleCrT-qpH5ND0XWbZRonB7yJMP1l3
Passing Microsoft real exam is not so simple. Choose right DP-800 exam prep is the first step to your success. The valid braindumps of PassTestking is a good guarantee to your success. If you choose our latest practice exam, it not only can 100% ensure you pass DP-800 Real Exam, but also provide you with one-year free updating exam pdf.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Latest DP-800 Braindumps Pdf <<
It is evident to all that the DP-800 test torrent from our company has a high quality all the time. A lot of people who have bought our products can agree that our DP-800 test questions are very useful for them to get the certification. There have been 99 percent people used our DP-800 Exam Prep that have passed their exam and get the certification. It means that our DP-800 test questions are very useful for all people to achieve their dreams, and the high quality of our DP-800 exam prep is one insurmountable problem.
NEW QUESTION # 57
Which tool helps orchestrate data pipelines for AI workflows?
Answer: D
Explanation:
Azure Data Factory automates data movement and transformation pipelines.
NEW QUESTION # 58
You have an Azure SQL database that contains a table named Tickets_Embeddings.
Tickets_Embeddings contains a VECTOR(1536) column.
Embeddings are generated by using text-embedding-ada-002 and the /openai/v1/embeddings endpoint.
After a review of the current environment, the following changes are requested:
- The AI architect has recommended switching to text-embedding-3-small.
- The security team requires authentication by using Microsoft Entra
managed identities only. Storing API keys in an application is
prohibited.
Which two actions should you include in the solution? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: C,E
Explanation:
To migrate your Azure SQL database to use the text-embedding-3-small model while implementing Microsoft Entra managed identity authentication, you should take the following actions:
[B]
Regenerate all the embeddings: Even though text-embedding-ada-002 and the default configuration of text-embedding-3-small both use 1,536 dimensions, the underlying vector representations are mathematically incompatible. Comparing an "ada" vector to a "v3-small" vector using cosine similarity will yield incorrect results. You must re-embed your existing data using the new model to maintain search accuracy.
[C]
Change the endpoint: To switch models, you must update your application code or database configuration (such as an AI_GENERATE_EMBEDDINGS function call or a stored procedure) to point to the new Azure OpenAI deployment endpoint for text-embedding-3-small.
Why these actions are necessary:
Incompatibility: Vectors generated by different models exist in different latent spaces. While you do not need to Alter the database tables (since the VECTOR(1536) column type remains identical for both models), the actual data inside those columns must be replaced.
Managed Identity: To meet the requirement of using Microsoft Entra managed identities and prohibiting API keys, you must configure your application or the Azure SQL DB to authenticate with Azure OpenAI using a managed identity. This involves granting the identity the Cognitive Services OpenAI User role and updating your connection strings/calls to exclude the api-key header.
Reference:
https://microsoftlearning.github.io/mslearn-postgresql/Instructions/Labs/13-generate-vector- embeddings-azure-openai.html
NEW QUESTION # 59
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.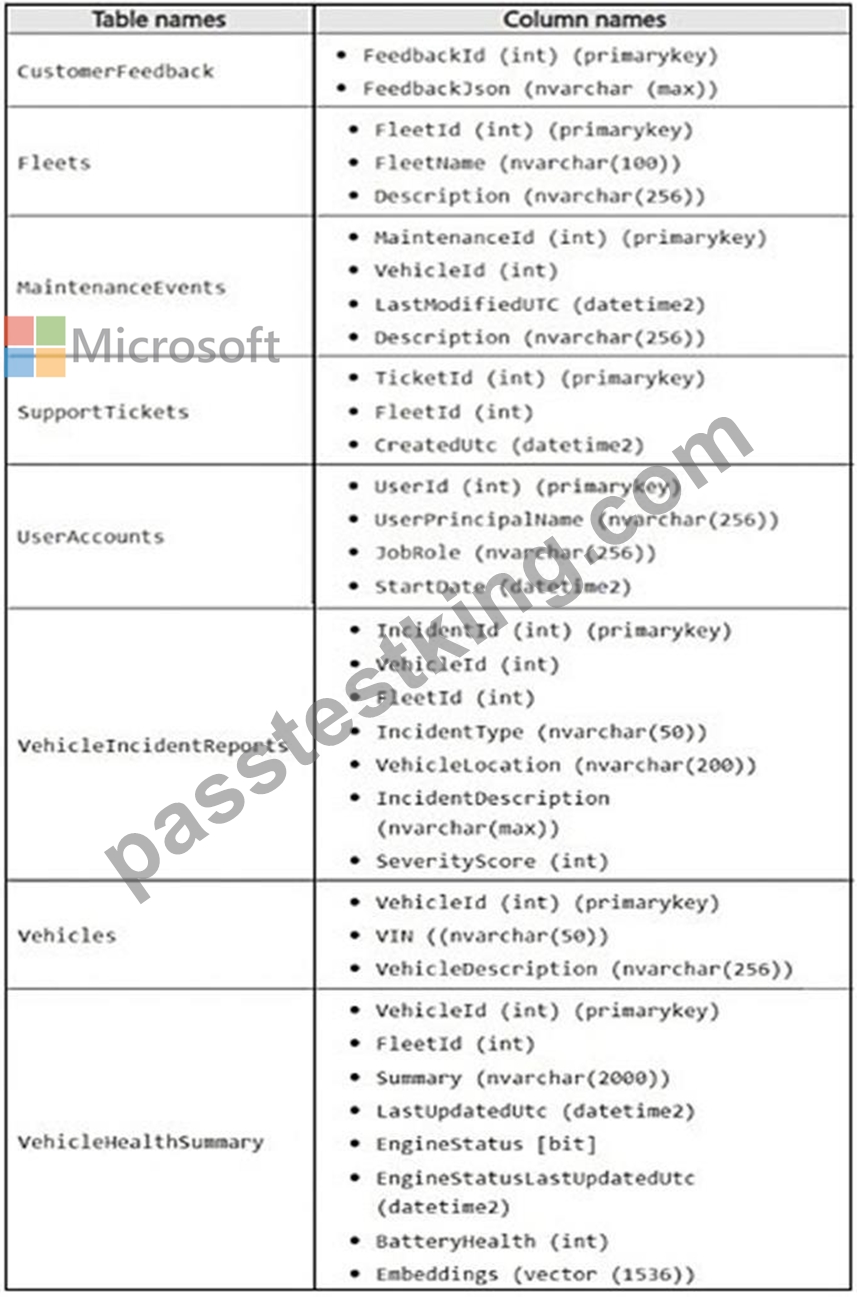
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.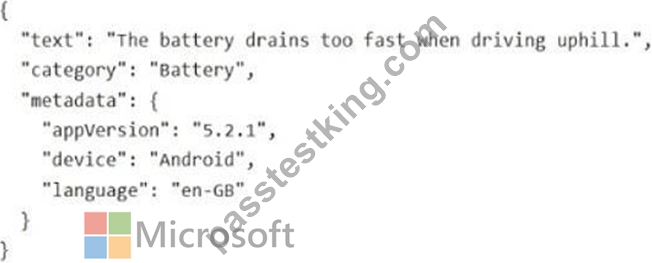
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.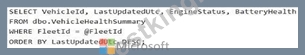
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
Answer: C
Explanation:
Scenario: VehicleIncidentReports often contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
The column you should use to generate embeddings is IncidentDescription.
Why this is the correct choice:
Semantic Meaning: Embeddings are designed to capture the semantic meaning of rich, unstructured text. The IncidentDescription column likely contains the detailed natural language notes about weather, traffic, and location that the analysts are struggling to search effectively using standard methods.
Vector Search: By converting the text in IncidentDescription into mathematical vectors (embeddings), you can perform a semantic vector search. This allows the database to find
"similar" incidents based on the context of the description rather than just matching exact keywords or categories.
Incorrect:
[Not A]
VehicleLocation: Typically contains specific coordinates or addresses which are better handled by spatial data types or exact matching.
[Not C]
IncidentType: Is likely a categorical label (e.g., "Fender Bender", "Multi-car pileup") and too simple for meaningful embedding generation.
[Not D]
SeverityScore: Is a numeric value that represents a magnitude, not a semantic concept.
Reference:
https://learn.microsoft.com/en-us/sql/t-sql/spatial-geography/spatial-types-geography
NEW QUESTION # 60
You have an Azure SQL database that supports a customer-facing API. The API calls a stored procedure named dbo.GetCustomerOrders thousands of times per hour.
After a deployment that updated indexes and statistics, users report that the API endpoint backed by dbo.
Getcustomerorders is slower. In Query Store, the same query now has two persisted execution plans. During the last hour, the newer plan had a significantly higher average duration and CPU time than the older plan.
You need to restore the previous performance quickly, without changing the API code.
Which Transact-SQL command should you run?
Answer: D
Explanation:
The scenario says Query Store already shows two persisted execution plans for the same query, and the older plan performed much better than the newer one during the last hour. Microsoft documents that sp_query_store_force_plan is used to force a particular plan for a particular query in Query Store .
That makes it the fastest way to restore the previously good plan without changing application code , which is exactly what the question requires.
Why the other options are not the best fit:
* sp_query_store_set_hints is for adding or updating Query Store hints to influence compilation behavior, but when you already know the exact older good plan, Microsoft points to plan forcing as the direct remedy.
* DBCC FREEPROCCACHE clears cached plans broadly and is disruptive; it does not guarantee a return to the known good plan.
* ALTER DATABASE is too general and does not directly restore the prior execution plan.
So the right Transact-SQL command is:
EXEC sp_query_store_force_plan
using the relevant @query_id and @plan_id from Query Store for the older, better-performing plan.
Microsoft also notes that when a plan is forced, SQL Server tries to use that plan whenever it encounters the query again.
NEW QUESTION # 61
Vou have an Azure SQL database named SalesDB that contains a table named dbo. Articles, dbo.Articles contains two million articles with embeddmgs. The articles are updated frequently throughout the day.
You query the embeddings by using VECTOR_SEARQi
Users report that semantic search results do NOT reflect the updates until the following day.
Vou need to ensure that the embeddings are updated whenever the articles change. The solution must minimize CPU usage on SalesDB Which embedding maintenance method should you implement?
Answer: A
Explanation:
The correct answer is B because the problem is not the vector search operator itself. The problem is that embeddings are becoming stale when article content changes . Microsoft documents that change data capture (CDC) tracks insert, update, and delete operations on source tables, which makes it the right mechanism to identify only the rows that changed.
This also best satisfies the requirement to minimize CPU usage on SalesDB . With CDC, the database only records the row changes, and the embedding regeneration work can be moved to an external process such as an Azure Functions app. That avoids running embedding generation inline inside the database for every update and avoids repeatedly recalculating embeddings for unchanged rows. In contrast, an hourly full-table regeneration would be extremely wasteful on a table with two million frequently updated articles, and a trigger that calls embedding generation per row would push expensive AI work into the transactional path of the database.
Option A is incorrect because changing from VECTOR_SEARCH to VECTOR_DISTANCE does not regenerate embeddings; it only changes the retrieval method. Microsoft states that VECTOR_SEARCH is the ANN search function, while VECTOR_DISTANCE performs exact distance calculation, so neither option addresses stale embedding data.
So the right design is:
* use CDC to detect only changed articles,
* process those changes outside the database,
* regenerate embeddings only for changed rows,
* write back the refreshed embeddings for current semantic search results.
NEW QUESTION # 62
......
It is universally acknowledged that DP-800 certification can help present you as a good master of some knowledge in certain areas, and it also serves as an embodiment in showcasing one’s personal skills. However, it is easier to say so than to actually get the DP-800 certification. We have to understand that not everyone is good at self-learning and self-discipline, and thus many people need outside help to cultivate good study habits, especially those who have trouble in following a timetable. Buy our DP-800 Exam Questions, we will help you pass the DP-800 exam without difficulty.
DP-800 Exam Online: https://www.passtestking.com/Microsoft/DP-800-practice-exam-dumps.html
What's more, part of that PassTestking DP-800 dumps now are free: https://drive.google.com/open?id=1RKqleCrT-qpH5ND0XWbZRonB7yJMP1l3