SPS-C01日本語版復習指南 & SPS-C01専門トレーリング

無料でクラウドストレージから最新のJapancert SPS-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1F_GY5nAnzYq2XHseXICS-7gh79SLGY1N
あなたの利益を保障するために、あなたのSPS-C01問題集を購入した後、我々はSPS-C01対策の一年間の無料更新を提供します。我々の専門家たちは毎日更新を検査していますから、この一年間で、もし更新があったら、更新したSPS-C01問題集は自動的にあなたのメールアドレスに送られます。我々Japancertはあなたの持っている商品は最新的のを保証しています。
Snowflake SPS-C01 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Topic 1: Data Transformations and DataFrame Operations | 35% | - Persisting transformed data
- Window functions
- Complex data pipelines
- Filtering, Aggregating, and Joining DataFrames
- Using built-in functions
|
| Topic 2: Performance Optimization and Best Practices | 20% | - Minimizing data transfer
- Warehouse sizing for Snowpark
- Debugging and explain plans
- Vectorized UDFs
- Query pushdown and optimization
- Caching strategies
|
| Topic 3: Snowpark API for Python | 30% | - DataFrame creation and manipulation
- User-Defined Functions (UDFs) and Stored Procedures
- Working with Semi-structured data
- Establishing connections and session management
- Reading and writing data
|
| Topic 4: Snowpark Concepts | 15% | - Snowpark DataFrames and query plans
- Snowpark architecture and core concepts
- Snowpark Sessions and connection management
- Stored procedures and conditional logic
- Client-side vs. Server-side execution
- Transformations vs. Actions
|
>> SPS-C01日本語版復習指南 <<
SPS-C01専門トレーリング、SPS-C01試験感想
Japancertの実践教材は、学生だけでなくオフィスワーカーにも適用されます。 職場の退役軍人だけでなく、新しく採用された新人にも適用されます。 SPS-C01の学習教材は、非常にシンプルで理解しやすい言語を使用して、すべての人が学習して理解できるようにします。 また、SPS-C01の実際のテストでは、教科書を読むのがつまらないことを回避できますが、Snowflake演習を行う過程で重要な知識をすべて習得できます。 そして、SPS-C01試験問題の高い合格率は98%以上です。 Snowflake Certified SnowPro Specialty - Snowpark学習ガイドを試してみませんか?
Snowflake Certified SnowPro Specialty - Snowpark 認定 SPS-C01 試験問題 (Q159-Q164):
質問 # 159
You have a Snowpark DataFrame representing customer transactions. This DataFrame is used in multiple downstream operations within your Snowpark application. Which of the following strategies would be MOST effective for optimizing the performance of these downstream operations by materializing the results of the 'df DataFrame, and what considerations should be made regarding resource usage?
- A. Use 'df.checkpoint()' to truncate the DataFrame lineage. This will prevent re-computation in any downstream operations. Monitor the impact on storage costs.
- B. Using a local variable to store the DataFrame. This method is most suitable for materializing the results of the DataFrame.
- C. Use to materialize the DataFrame in memory. This is the most efficient approach as it minimizes disk I/O. Consider the size of the DataFrame relative to available memory to avoid memory pressure.
- D. Write the DataFrame to a persistent Snowflake table using and then read it back into a new DataFrame. This ensures data persistence but may introduce overhead due to data serialization and deserialization. Only use this method if persistence is required beyond the session.
- E. Create a temporary table using 'df.write.save_as_table('temp_transactions', temporary-True)'. This persists the DataFrame to Snowflake storage, reducing the need for repeated computations. Monitor the size of the temporary table and its impact on storage costs.
正解:C、E
解説:
Using materializes the DataFrame in memory, which is faster for repeated access but requires sufficient memory. Creating a temporary table using temporary=TrueV persists the DataFrame to Snowflake storage, reducing recomputation at the cost of storage 1/0. Choosing between these options depends on the DataFrame's size, available memory, and the frequency of access. Writing to a persistent table adds unnecessary overhead unless persistence is required. Using a local variable will only persist the result within the scope of that variable, not across multiple Snowpark operations. Checkpointing is used for lineage truncation not caching.
質問 # 160
Consider the following Snowpark code snippet designed to create a temporary table:
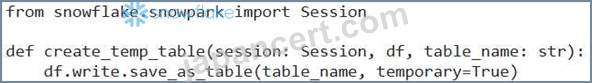
A developer encounters an error when calling this function. The error message indicates that the table already exists. How should the developer modify the code to handle this scenario gracefully, preventing the error and ensuring the temporary table is either created or overwritten?
- A. Use to create the temporary table.
- B. Add the 'mode='overwrite" option to the function. This will replace the existing table with the new data.
- C. Add the 'mode='append" option to the function. This will append the data to the existing table.
- D. Add the 'mode='ignore" option to the function. This will silently skip the creation if the table already exists.
- E. First drop the table using 'session.sql(fDROP TABLE IF EXISTS {table_name}')' before calling .
正解:B、E
解説:
The option will replace the existing table if it exists. Alternatively, explicitly dropping the table using session.sql(fDROP TABLE IF EXISTS {table_name}')' ensures that a new table is created, even if one with the same name already exists. mode='ignore" would just skip the operation and no table may exist after execution. 'mode='append'' may fail as well as temporary tables typically do not allow appending. createOrReplaceTempView creates a temporary view , not a temporary table.
質問 # 161
You are developing a Snowpark Python application that performs advanced machine learning model training on a large dataset stored in Snowflake. You observe that the application is memory-intensive, causing frequent spilling to disk and slowing down the training process.
Which of the following strategies, when implemented in conjunction, is MOST likely to improve the performance of your Snowpark application in this memory-constrained scenario?
- A. Enable caching for intermediate results and switch to a Snowpark-optimized warehouse with a smaller size to force early spilling to disk.
- B. Reduce the batch size for data loading, utilize Snowpark's optimized data types for columns with small value ranges, and use memory profiling tools to identify memory leaks in your Python code and optimize the application.
- C. Increase the size of the Snowpark-optimized warehouse with 'MEMORY OPTIMIZED server type, use appropriate data types to minimize memory footprint, and optimize UDFs to minimize intermediate data creation.
- D. Switch to a larger Snowflake warehouse size and increase the parameter to ' True'.
- E. Increase the 'MAX CONCURRENCY LEVEL' parameter at the session level and rewrite the model training code in SQL using stored procedures.
正解:B、C
解説:
Reducing the batch size reduces the memory footprint of each batch. Using optimized data types reduces memory usage for each column. Profiling helps identify and fix memory leaks in the code. Increasing warehouse size helps improve performance. MEMORY_OPTIMIZED server type will allocate higher memory. Optimizing UDFs can improve performance significantly. Using Native Execution will utilize the native execution engine of Snowflake for faster query processing. Option A utilizes native execution (if supported) but doesn't address memory constraints. Option C rewriting model training code in SQL might not be feasible. Option D switching to smaller warehouse exacerbates the memory problem. Reducing batch size, memory profiling and optimized UDF/Data type are key. Using a memory-optimized warehouse type is also important.
質問 # 162
You are developing a Snowpark stored procedure in Python that needs to access and modify a temporary table within the same session.
Which of the following approaches is the MOST efficient and recommended way to achieve this?
- A. Using 'session.sql('CREATE TEMPORARY TABLE followed by subsequent 'session.sql('lNSERT INTO and 'session.sql('SELECT statements to interact with the temporary table.
- B. Using to create a DataFrame representing the temporary table, and then performing all operations using DataFrame transformations.
- C. Creating a global temporary table using 'CREATE GLOBAL TEMPORARY TABLE outside the stored procedure and then accessing it within the stored procedure using 'session.table()'.
- D. Using 'session.createOrReplaceTempView()' to create a temporary view based on a DataFrame, and then querying the view using 'session.sql('SELECT
- E. Using the Python DB API (e.g., 'snowflake.connector' ) within the stored procedure to establish a separate connection to Snowflake and interact with the temporary table.
正解:B
解説:
Option B, using 'session.createDataFrame()' and DataFrame transformations, is the most efficient and recommended approach. Snowpark DataFrames are optimized for execution within the Snowflake engine. Using DataFrame transformations allows Snowpark to leverage its query optimization capabilities. Option A, using 'session.sql()' repeatedly, involves parsing and executing SQL statements for each operation, which is less efficient. Option C, using a separate connection, introduces unnecessary overhead and complexity. Option D, global temporary tables, are not session-specific. Option E, creating a temporary view and then querying it with SQL, is also less efficient than using DataFrame operations directly.
質問 # 163
A data engineering team is building a Snowpark application in Python to perform advanced time series analysis on sensor data stored in Snowflake. They need to leverage a specific, but older, version of the 'pandas' library (version 1.1.5) that is not available in the default Snowflake Anaconda channel. Which of the following approaches is the MOST efficient and recommended way to ensure this specific version of 'pandas' is available to their Snowpark application, while minimizing security risks and operational overhead?
- A. Package the pandas 1.1.5 library within the Snowpark application code itself, by including it in the application deployment package.
- B. Create a new Snowflake Anaconda environment and install pandas 1.1.5 into this environment, then configure the Snowpark session to use this custom environment. Ensure the 'snowflake-snowpark-python' package is also included.
- C. Build a custom Anaconda channel outside of Snowflake, and configure the Snowpark session to point to that channel.
- D. Use 'conda install pandas==l .1.5' within the Snowpark Python code directly. This will install pandas at runtime.
- E. Upload the pandas 1.1.5 wheel file directly into a Snowflake stage and reference it within the session configuration using along with
正解:B
解説:
Creating a new Snowflake Anaconda environment is the most efficient and secure way to manage specific package versions. It leverages Snowflake's built-in dependency management capabilities and avoids external dependencies or manual package management within the application code. Options A and D introduce potential security risks and maintenance overhead. Option B is inefficient for dependency management. Option E will not work, as it tries to install dependencies at runtime, which isn't supported in Snowpark.
質問 # 164
......
JapancertはSnowflake試験問題集を提供するウエブダイトで、ここによく分かります。最もよくて最新で資料を提供いたします。こうして、君は安心でSPS-C01試験の準備を行ってください。弊社の資料を使って、100%に合格を保証いたします。もし合格しないと、われは全額で返金いたします。
SPS-C01専門トレーリング: https://www.japancert.com/SPS-C01.html
- 真実的なSPS-C01日本語版復習指南一回合格-権威のあるSPS-C01専門トレーリング 🔡 時間限定無料で使える➥ SPS-C01 🡄の試験問題は《 www.goshiken.com 》サイトで検索SPS-C01日本語pdf問題
- 信頼できるSPS-C01日本語版復習指南と一番優秀なSPS-C01専門トレーリング 🥭 サイト「 www.goshiken.com 」で《 SPS-C01 》問題集をダウンロードSPS-C01日本語版対策ガイド
- SPS-C01資料的中率 🏂 SPS-C01試験参考書 ⬇ SPS-C01日本語版対策ガイド 🤶 URL ( www.passtest.jp )をコピーして開き、「 SPS-C01 」を検索して無料でダウンロードしてくださいSPS-C01資格関連題
- 素晴らしいSPS-C01日本語版復習指南一回合格-真実的なSPS-C01専門トレーリング 🙎 ⏩ www.goshiken.com ⏪サイトにて最新➠ SPS-C01 🠰問題集をダウンロードSPS-C01トレーリング学習
- 信頼できるSPS-C01日本語版復習指南と一番優秀なSPS-C01専門トレーリング 🌁 ☀ www.japancert.com ️☀️サイトで⮆ SPS-C01 ⮄の最新問題が使えるSPS-C01復習問題集
- 試験の準備方法-正確的なSPS-C01日本語版復習指南試験-ハイパスレートのSPS-C01専門トレーリング 🧼 サイト( www.goshiken.com )で▶ SPS-C01 ◀問題集をダウンロードSPS-C01日本語対策問題集
- SPS-C01試験の準備方法|効果的なSPS-C01日本語版復習指南試験|最新のSnowflake Certified SnowPro Specialty - Snowpark専門トレーリング 👌 ✔ www.passtest.jp ️✔️を開き、➡ SPS-C01 ️⬅️を入力して、無料でダウンロードしてくださいSPS-C01復習問題集
- 真実的なSPS-C01日本語版復習指南一回合格-権威のあるSPS-C01専門トレーリング 😠 ▷ www.goshiken.com ◁に移動し、➤ SPS-C01 ⮘を検索して無料でダウンロードしてくださいSPS-C01試験情報
- SPS-C01トレーリング学習 😮 SPS-C01模擬体験 🚬 SPS-C01資料的中率 🎥 ✔ SPS-C01 ️✔️を無料でダウンロード▶ www.shikenpass.com ◀で検索するだけSPS-C01日本語対策問題集
- ユニークなSPS-C01日本語版復習指南 - 合格スムーズSPS-C01専門トレーリング | 実用的なSPS-C01試験感想 Snowflake Certified SnowPro Specialty - Snowpark 🕰 時間限定無料で使える( SPS-C01 )の試験問題は“ www.goshiken.com ”サイトで検索SPS-C01学習範囲
- SPS-C01難易度受験料 👸 SPS-C01日本語版対策ガイド 👜 SPS-C01復習問題集 ✊ ➡ www.japancert.com ️⬅️には無料の「 SPS-C01 」問題集がありますSPS-C01受験トレーリング
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.zazzle.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
ちなみに、Japancert SPS-C01の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1F_GY5nAnzYq2XHseXICS-7gh79SLGY1N