Our company has been engaged in compiling professional Databricks-Certified-Professional-Data-Engineer exam quiz in this field for more than ten years. Our large amount of investment for annual research and development fuels the invention of the latest Databricks-Certified-Professional-Data-Engineer study materials, solutions and new technologies so we can better serve our customers and enter new markets. We invent, engineer and deliver the best Databricks-Certified-Professional-Data-Engineer Guide questions that drive business value, create social value and improve the lives of our customers.
| Section | Objectives |
|---|---|
| Topic 1: Security, Governance, Monitoring, and Optimization | - Cost optimization and performance tuning - Implement Unity Catalog governance and access control - Monitor and optimize Spark workloads |
| Topic 2: Data Ingestion and Transformation | - Ingest data using Apache Spark and Databricks - Handle batch and streaming data pipelines - Transform and clean datasets using Spark SQL and DataFrame APIs |
| Topic 3: Production Pipelines and Orchestration | - Build and manage workflows using Databricks Jobs - Automate ETL pipelines and scheduling - Pipeline reliability and fault tolerance |
| Topic 4: Data Modeling and Storage | - Schema evolution and data partitioning strategies - Delta Lake table design and optimization - Design scalable data lakehouse architectures |
>> Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Ppt <<
So, when you get the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer exam dumps material for your Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer certification exam, you have to check whether they are providing you the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer Practice Test or not. You must choose those who shall give you the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer questions and not those who are giving you copied sheets only.
NEW QUESTION # 160
A new data engineer notices that a critical field was omitted from an application that writes its Kafka source to Delta Lake. This happened even though the critical field was in the Kafka source. That field was further missing from data written to dependent, long-term storage. The retention threshold on the Kafka service is seven days. The pipeline has been in production for three months.
Which describes how Delta Lake can help to avoid data loss of this nature in the future?
Answer: E
Explanation:
This is the correct answer because it describes how Delta Lake can help to avoid data loss of this nature in the future. By ingesting all raw data and metadata from Kafka to a bronze Delta table, Delta Lake creates a permanent, replayable history of the data state that can be used for recovery or reprocessing in case of errors or omissions in downstream applications or pipelines. Delta Lake also supports schema evolution, which allows adding new columns to existing tables without affecting existing queries or pipelines. Therefore, if a critical field was omitted from an application that writes its Kafka source to Delta Lake, it can be easily added later and the data can be reprocessed from the bronze table without losing any information. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delta Lake core features" section.
NEW QUESTION # 161
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFramedf. The pipeline needs to calculate the average humidity and average temperature for each non- overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFramedfhas the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block: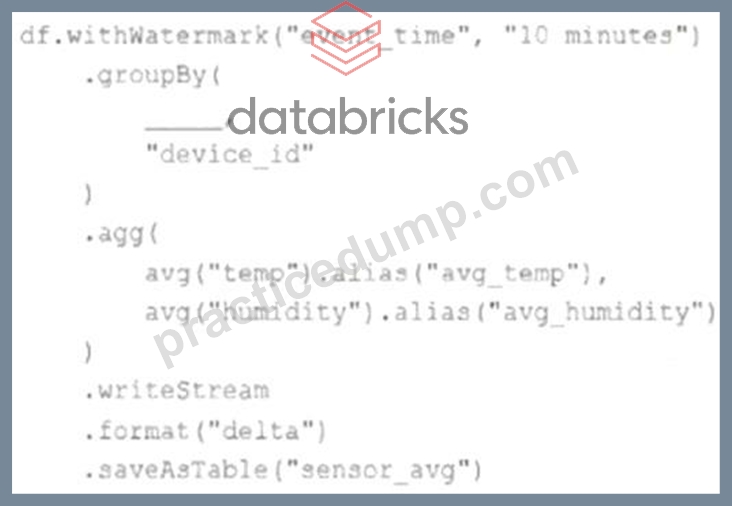
Choose the response that correctly fills in the blank within the code block to complete this task.
Answer: B
Explanation:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five-minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time". Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "WINDOW" section.https://www.databricks.com/blog/2017/05/08/event-time-aggregation- watermarking-apache-sparks-structured-streaming.html
NEW QUESTION # 162
Which of the following results in the creation of an external table?
Answer: E
Explanation:
Explanation
Answer is CREATE TABLE transactions (id int, desc string) USING DELTA LOCATION
'/mnt/delta/transactions'
Anytime a table is created using Location it is considered an external table, below is the current syntax.
Syntax
CREATE TABLE table_name ( column column_data_type...) USING format LOCATION "dbfs:/"
NEW QUESTION # 163
What is the main difference between the bronze layer and silver layer in a medallion architecture?
Answer: A
Explanation:
Explanation
Medallion Architecture - Databricks
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence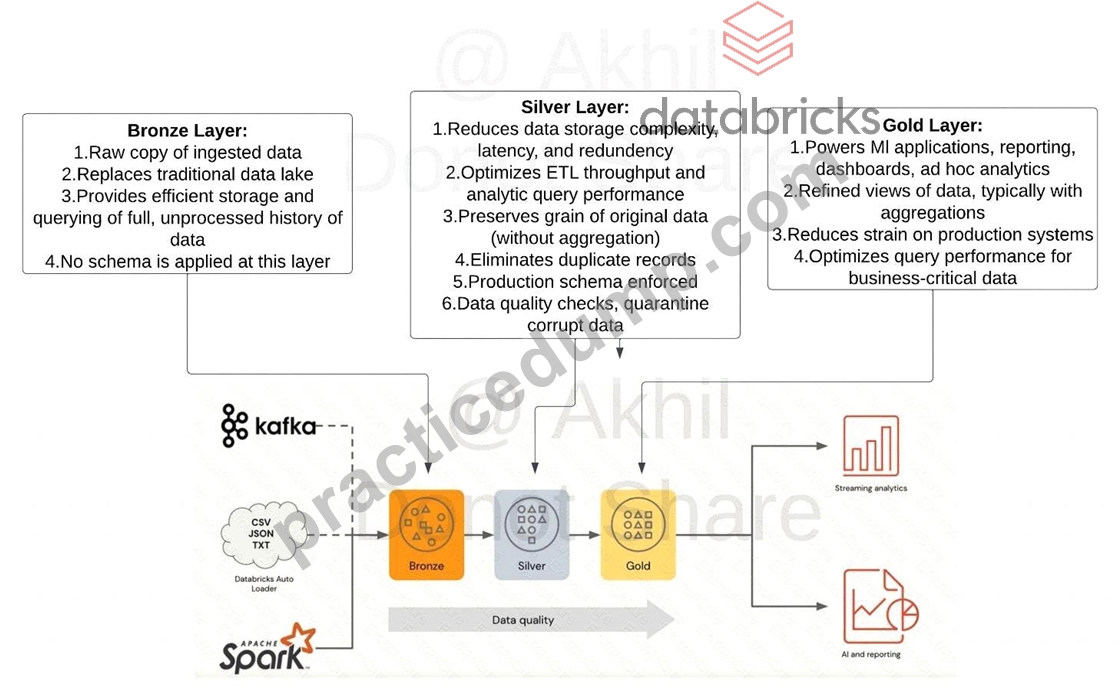
NEW QUESTION # 164
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
Answer: A
Explanation:
Comprehensive and Detailed
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
Why not the others?
B: Uses @dlt.expect_or_drop, which drops invalid records instead of quarantining them. This violates the requirement that quarantined data should be available.
C: Same as B, but applies expectations in bulk with expect_all_or_drop. Again, bad data is dropped, not quarantined.
D: Adds an is_quarantined flag in the same table. While it marks bad records, it does not separate them into a distinct quarantine table as required by the business use case.
Therefore, Option A is the only solution aligned with Databricks documentation for quarantining invalid data into a dedicated table while keeping valid data in the main pipeline.
NEW QUESTION # 165
......
The Databricks-Certified-Professional-Data-Engineer certificate is the bridge between "professional" and "unprofessional", and it is one of the ways for students of various schools to successfully enter the society and embark on an ideal career. It is also one of the effective ways for people in the workplace to get more opportunities. But few people can achieve it for the limit of time or other matters. But with our Databricks-Certified-Professional-Data-Engineer Exam Questions, it is as easy as pie. Just buy our Databricks-Certified-Professional-Data-Engineer training guide, then you will know how high-effective it is!
Databricks-Certified-Professional-Data-Engineer Prep Guide: https://www.practicedump.com/Databricks-Certified-Professional-Data-Engineer_actualtests.html