P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by VCE4Plus: https://drive.google.com/open?id=1kBWHXxch_dI-N-HFrLVVKOe7S2Pqi9GI
Today, in an era of fierce competition, how can we occupy a place in a market where talent is saturated? The answer is a certificate. What the certificate main? All kinds of the test SPS-C01 certification, prove you through all kinds of qualification certificate, it is not hard to find, more and more people are willing to invest time and effort on the SPS-C01 Exam Guide, because get the test SPS-C01 certification is not an easy thing, so, a lot of people are looking for an efficient learning method. Our SPS-C01 exam questions are the right tool for you to pass the SPS-C01 exam.
| Section | Objectives |
|---|---|
| Data Engineering with Snowpark | - Pipeline development
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Testing, Debugging, and Deployment | - Production readiness
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
The VCE4Plus is committed from the day first to ace the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam questions preparation at any cost. To achieve this objective VCE4Plus has hired a team of experienced and qualified Snowflake SPS-C01 certification exam experts. They utilize all their expertise to offer top-notch Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam dumps. These SPS-C01 exam questions are being offered in three different but easy-to-use formats.
NEW QUESTION # 158
You are building a Snowpark application that processes a large number of PDF files stored in a Snowflake stage. You need to extract text from each PDF file using a Python UDF and store the extracted text in a Snowflake table. You are considering different approaches for loading the PDF files into the UDE Which of the following approaches would provide the BEST performance and scalability, while minimizing network traffic and memory usage?
Answer: C
Explanation:
Option C is the most efficient approach. 'snowflake.snowpark.files.SnowflakeFile' allows the UDF to directly access the PDF files stored in the Snowflake stage without transferring the entire file to the client. This minimizes network traffic and memory usage. Option A requires loading all PDF files into a pandas DataFrame, which can consume a significant amount of memory. Option B has issues relating to the file size and content restrictions and isn't suitable for many files. Option D involves downloading all files to a local directory, which is not scalable and introduces unnecessary overhead. Option E using 'GET OBJECT is outside the scope of the python api.
NEW QUESTION # 159
You are troubleshooting a Snowpark application that fails to connect to Snowflake intermittently. The error message indicates an issue with the specified account identifier Which of the following actions could help resolve this issue? Select all that apply.
Answer: A,C,D
Explanation:
A faulty account identifier would obviously cause issues. Also, It is crucial to verify that the account identifier is correctly specified, including the region if your account is not in the default AWS US West (Oregon) region. Also check if Snowflake service outage and if connecting IP address has access to Snowflake. Option B is relevant to authorization, but not directly to account identifier issues. Option E might help in some situations, but it is not directly related to account identifier problems, so we can exclude it. Note that, network policies can cause intermittent connection issues.
NEW QUESTION # 160
You are using Snowpark in Python within a Jupyter Notebook environment to analyze sales data'. You've established a connection to Snowflake and loaded your data into a Snowpark DataFrame named 'sales ff. You need to calculate the cumulative sales for each product category over time. The 'sales_df' DataFrame has columns 'SALE DATE' (DATE), 'PRODUCT CATEGORY' (VARCHAR), and 'SALE AMOUNT' (NUMBER). Which of the following approaches, or combination of approaches, will correctly calculate the cumulative sales while optimizing for Snowflake's performance and scalability? (Select all that apply)
Answer: A,B,C
Explanation:
Options A, C, and E are correct. Option A utilizes Snowpark's DataFrame transformations with window functions, which are optimized for Snowflake's engine and can efficiently handle large datasets. This leverages Snowflake's parallel processing capabilities. Option C involves creating a stored procedure within Snowflake. This approach pushes the computation to the Snowflake server, potentially improving performance, especially if the cumulative sales calculation is complex. This also benefits from Snowflake's optimization capabilities. Option E executes a SQL query with a window function that's optimized. Option B is incorrect because iterating through rows in a Jupyter Notebook will be extremely slow and inefficient for large datasets. It defeats the purpose of using Snowpark for distributed data processing. Calculating cumulative sales this way doesn't leverage Snowflake's capabilities. Option D is partially correct in that it orders the data, but using a UDF for cumulative sum calculation will likely be less efficient than using native window functions within Snowflake.
NEW QUESTION # 161
You are working with a Snowpark DataFrame named containing information about products, including 'CATEGORY , 'SUBCATEGORY , and 'PRICE'. You want to determine the maximum price for each subcategory within each category. Furthermore, you need to filter the results to only include categories that have more than 5 subcategories. Which of the following Snowpark Python code snippets accomplishes this task? (Select all that apply)





Answer: A,E
Explanation:
The correct options are D and E. They both address the requirement and count distinct subcategories within each category. Option D: Correctly calculates the maximum price for each subcategory within each category. Then separately calculates the count of DISTINCT subcategories for each category. Filters the categories to include only those with more than 5 subcategories. Joins the two resulting DataFrames to provide the final output. This is a standard and explicit way to accomplish the task. Using countDistinct to ensure each subcategory is only counted once. Option E: Aggregates Max Price and CountDistinct of subcategory into same dataframe, this addresses all requirements in a more concise manner. Option A: Does not give the right result since 'count' will not give the countDistinct. Also using 'COUNT(SUBCATEGORYV in category_countS dataframe results in count of all rows in the group instead of the number of groups (number of Subcategories). Option B: Window functions is irrelevant here, and requires more coding while can be handled efficiently by aggregating and countDistinct combination Option C: Option C doesn't aggregate maximum price for each subcategory within each category as the question mentions.
NEW QUESTION # 162
Consider the following Snowpark code snippet that aims to calculate the rank of each employee based on their salary within their respective department. What are potential issues with this code, and how can you improve it? (Select all that apply.)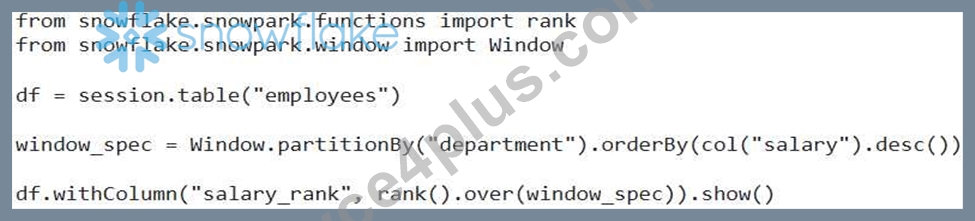
Answer: A,B,D
Explanation:
Options B, D, and E are correct. B: The 'orderBy' clause needs the 'col' function call in D: Null values in the salary column can lead to unexpected ranking results, and should be addressed beforehand. E: Applying window functions on very large DataFrames can be resource-intensive, so filtering data beforehand can improve performance. Option A is incorrect because there are indeed issues with the code. Option C: 'rank()' function does not produce dense ranks. function is used for contiguous ranks.
NEW QUESTION # 163
......
With the Snowflake SPS-C01 certification exam you can do your job nicely and quickly. You should keep in mind that the Snowflake SPS-C01 certification exam is a valuable credential and will play an important role in your career advancement. With the right Snowflake SPS-C01 Exam Preparation, commitment and dedication you can make this challenge easy and quick.
SPS-C01 Test Assessment: https://www.vce4plus.com/Snowflake/SPS-C01-valid-vce-dumps.html
DOWNLOAD the newest VCE4Plus SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1kBWHXxch_dI-N-HFrLVVKOe7S2Pqi9GI