
What's more, part of that PrepAwayETE MLA-C01 dumps now are free: https://drive.google.com/open?id=1fvbg7rXsdFRn-dxt2wbV0QQu9E4iix3j
Our AWS Certified Machine Learning Engineer - Associate (MLA-C01) PDF file is portable which means customers can carry this real questions document to any place. You just need smartphones, or laptops, to access this AWS Certified Machine Learning Engineer - Associate (MLA-C01) PDF format. These AWS Certified Machine Learning Engineer - Associate (MLA-C01) questions PDFs are also printable. So candidates who prefer to study in the old way which is paper study can print AWS Certified Machine Learning Engineer - Associate (MLA-C01) questions PDF as well.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Related Certifications: | AWS Certified AI Practitioner AWS Certified Machine Learning - Specialty |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Exam Format: | Ordering, Multiple choice, Case study, Multiple response, Matching |
| Exam Price: | 150 USD |
| Certificate Validity Period: | 3 years |
| Passing Score: | 720 (scaled score 100–1000) |
| Exam Duration: | 130 minutes |
| Available Languages: | Simplified Chinese, English, Korean, Japanese |
| Recommended Training: | AWS Certified Machine Learning Engineer - Associate Official Exam Guide AWS Training and Certification |
| Exam Registration: | Pearson VUE Registration AWS Certification Portal |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
>> Amazon MLA-C01 Latest Test Labs <<
To keep pace with the times, we believe science and technology can enhance the way people study. Especially in such a fast-pace living tempo, we attach great importance to high-efficient learning. Therefore, our MLA-C01 study materials base on the past exam papers and the current exam tendency, and design such an effective simulation function to place you in the real exam environment. We promise to provide a high-quality simulation system with advanced MLA-C01 Study Materials. With the simulation function, our MLA-C01 training guide is easier to understand and pass the MLA-C01 exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 209
An ML engineer has a custom container that performs k-fold cross-validation and logs an average F1 score during training. The ML engineer wants Amazon SageMaker AI Automatic Model Tuning (AMT) to select hyperparameters that maximize the average F1 score.
How should the ML engineer integrate the custom metric into SageMaker AI AMT?
Answer: D
Explanation:
Amazon SageMaker Automatic Model Tuning extracts objective metrics directly from training logs. For custom containers, AWS requires the ML engineer to define a metric definition that specifies a regular expression to parse the desired metric value from standard output.
The ObjectiveMetricName in the tuning job must match the metric captured by the regex. This is the only supported method for integrating custom metrics with SageMaker AMT.
TrainingInputMode does not define metrics. CloudWatch metrics cannot be used as tuning objectives. AMT cannot read metrics from S3 artifacts.
AWS documentation explicitly states that regex-based metric definitions are required for custom metrics in hyperparameter tuning jobs.
Therefore, Option B is the correct and AWS-verified solution.
NEW QUESTION # 210
A healthcare company wants to detect irregularities in patient vital signs that could indicate early signs of a medical condition. The company has an unlabeled dataset that includes patient health records, medication history, and lifestyle changes.
Which algorithm and hyperparameter should the company use to meet this requirement?
Answer: C
Explanation:
The requirement is to detect irregularities (anomalies) in patient data using an unlabeled dataset, which clearly defines an unsupervised anomaly detection problem. According to AWS documentation, Amazon SageMaker Random Cut Forest (RCF) is purpose-built for detecting anomalies in high-dimensional, continuous datasets such as healthcare metrics and time-series-like records.
RCF works by constructing multiple random decision trees that partition the data. Observations that are isolated closer to the root of these trees are more likely to be anomalies. AWS explicitly recommends RCF for use cases such as fraud detection, system monitoring, and healthcare anomaly detection.
The num_trees hyperparameter controls the number of trees in the forest. Increasing num_trees improves anomaly detection accuracy and stability by averaging anomaly scores across more trees, which is especially important in sensitive domains like healthcare. AWS documentation notes that larger forests provide better generalization and more reliable anomaly scores.
Option A (XGBoost) is a supervised learning algorithm and requires labeled data, making it unsuitable.
Option B (k-means) performs clustering but does not explicitly detect anomalies. Option C (DeepAR) is designed for time-series forecasting, not anomaly detection in unlabeled datasets.
Therefore, using Amazon SageMaker Random Cut Forest with a higher num_trees value is the most appropriate, scalable, and AWS-recommended solution.
NEW QUESTION # 211
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)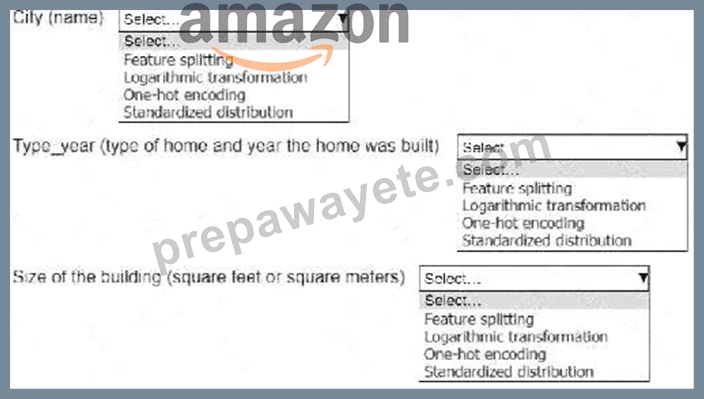
Answer:
Explanation: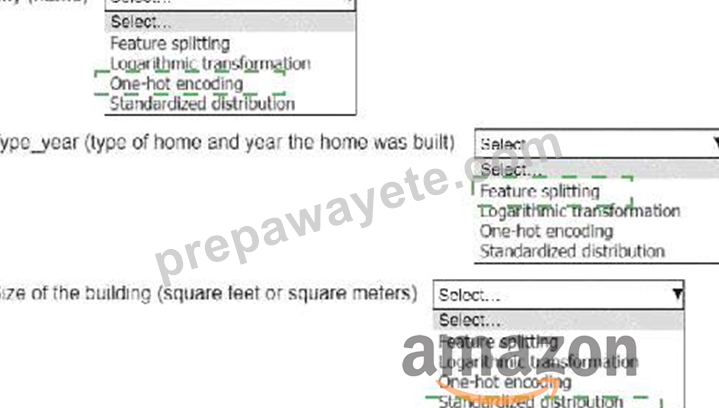
Explanation:
City (name): One-hot encoding
Type_year (type of home and year the home was built): Feature splitting Size of the building (square feet or square meters): Standardized distribution City (name): One-hot encoding Why? The " City " is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like " New York " or " Los Angeles " ), which the model can interpret.
Type_year (type of home and year the home was built): Feature splitting Why? " Type_year " combines two pieces of information into one column, which could confuse the model.
Feature splitting separates this column into two distinct features: " Type of home " and " Year built, " enabling the model to process each feature independently.
Size of the building (square feet or square meters): Standardized distribution Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 212
A company has a Retrieval Augmented Generation (RAG) application that uses a vector database to store embeddings of documents. The company must migrate the application to AWS and must implement a solution that provides semantic search of text files. The company has already migrated the text repository to an Amazon S3 bucket.
Which solution will meet these requirements?
Answer: A
Explanation:
The key requirement is semantic search over text documents that already reside in Amazon S3. AWS provides Amazon Kendra, a fully managed service specifically designed for semantic and natural language search across unstructured text.
Amazon Kendra natively supports S3 connectors, which can ingest documents directly from an S3 bucket, automatically process the text, generate embeddings, and index the content for semantic retrieval. This removes the need for the company to manage embedding generation, vector storage, or similarity search infrastructure. Queries can be expressed in natural language, making Kendra well suited for RAG-style applications.
Option A and B require building and maintaining a custom embedding pipeline and do not provide a true vector similarity search engine using SQL. SageMaker Feature Store is not intended to function as a vector database for semantic search.
Option D is incorrect because Amazon Textract is an OCR service for extracting text from scanned documents and images; it does not support semantic search.
Therefore, ingesting documents using the Amazon Kendra S3 connector and querying Kendra is the correct and AWS-recommended solution.
NEW QUESTION # 213
An ML engineer is using an Amazon SageMaker Studio notebook to train a neural network by creating an estimator. The estimator runs a Python training script that uses Distributed Data Parallel (DDP) on a single instance that has more than one GPU.
The ML engineer discovers that the training script is underutilizing GPU resources. The ML engineer must identify the point in the training script where resource utilization can be optimized.
Which solution will meet this requirement?
Answer: A
Explanation:
To pinpoint inefficiencies inside a training script, AWS recommends using Amazon SageMaker Profiler.
SageMaker Profiler provides fine-grained visibility into CPU, GPU, memory, I/O usage, and framework-level operations during training.
By adding profiler annotations directly to the training script, the ML engineer can identify bottlenecks such as inefficient data loading, synchronization delays in DDP, or idle GPU time between training steps.
CloudWatch metrics provide high-level utilization trends but cannot identify exact code-level inefficiencies.
CloudTrail is an auditing service and is irrelevant to performance profiling. Model Monitor focuses on data and model quality, not training resource utilization.
Therefore, SageMaker Profiler is the correct tool.
NEW QUESTION # 214
......
New MLA-C01 Exam Format: https://www.prepawayete.com/Amazon/MLA-C01-practice-exam-dumps.html
DOWNLOAD the newest PrepAwayETE MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1fvbg7rXsdFRn-dxt2wbV0QQu9E4iix3j