2026 Latest iPassleader SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1CQSu3SUKEFrooOGZBWYzK8UdCy6u5gEC
iPassleader SPS-C01 exam braindumps are authorized legal products which is famous for its high passing rate. Our dumps can cover nearly 95% questions of the real test, our answers and explanations are edited by many experienced experts and the correct rate is 100%. Our Snowflake SPS-C01 Exam Braindumps provide three versions to satisfy different kinds of customers' habits: PDF version, Soft test engine and APP test engine.
| Section | Objectives |
|---|---|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Data Engineering with Snowpark | - Pipeline development
|
| Testing, Debugging, and Deployment | - Production readiness
|
iPassleader's Snowflake SPS-C01 Exam Training materials provide the two most popular download formats. One is PDF, and other is software, it is easy to download. The IT professionals and industrious experts in iPassleader make full use of their knowledge and experience to provide the best products for the candidates. We can help you to achieve your goals.
NEW QUESTION # 289
You are tasked with building a Snowpark application that receives a DataFrame 'new customers_df containing customer data'. Your application needs to insert this data into the 'CUSTOMERS' table in Snowflake. The 'CUSTOMERS table has columns 'CUSTOMER ONT), 'NAME' (VARCHAR), and 'JOIN DATE' (DATE). However, contains all columns as VARCHAR. Which of the following approaches ensures the correct data types are inserted into the 'CUSTOMERS' table, minimizing errors and maximizing performance? Assume the 'session' object is already defined and a valid connection exists.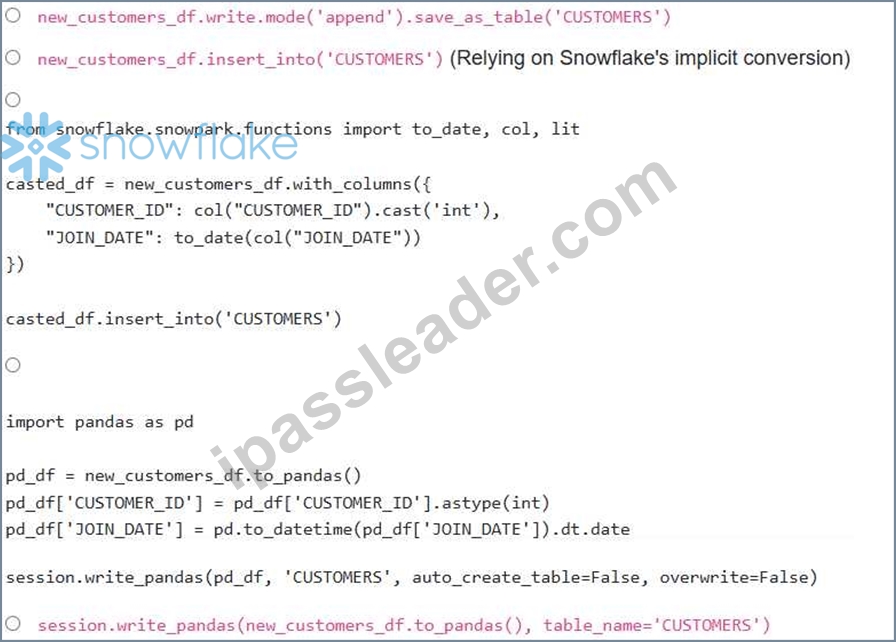
Answer: E
Explanation:
Option C provides explicit casting of the VARCHAR columns to their respective data types (INT and DATE) using Snowpark functions before inserting them into the 'CUSTOMERS' table. This approach ensures data type compatibility and prevents potential errors during the insertion process. Option A, while seemingly simple, might lead to data type mismatch errors if Snowflake cannot implicitly convert the VARCHAR values to INT and DATE. Option B relies on implicit conversion, which is risky. Option D, although it converts to pandas, performs the correct transformations. However, converting to a Pandas DataFrame and using session.write_pandas is less performant and not necessary when using Snowpark. Option E, does not do type conversions and assumes the dataframe is already in required format.
NEW QUESTION # 290
You have two Snowpark DataFrames, 'customers' and 'orders'. The 'customers' DataFrame has columns and 'customer name'. The 'orders' DataFrame has columns 'order id', 'customer id', and 'order amount'. You need to find all customers who have NOT placed any orders. Which of the following Snowpark set operations correctly implements this?





Answer: E
Explanation:
Option D is correct. It first selects the distinct 'customer_id' from both DataFrames. Then, it uses the 'minus' (or 'except_') set operation to find the difference between the customer IDs in the 'customers DataFrame and the customer IDs in the 'orders' DataFrame. This effectively returns the customer IDs of customers who have not placed any orders. The 'join' operation is not a set operation, and options B and C are not valid syntax for Snowpark. Option E is syntactically correct in Snowpark, and equivalent to Option D. However, since the question has to have one answer, Option D is kept.
NEW QUESTION # 291
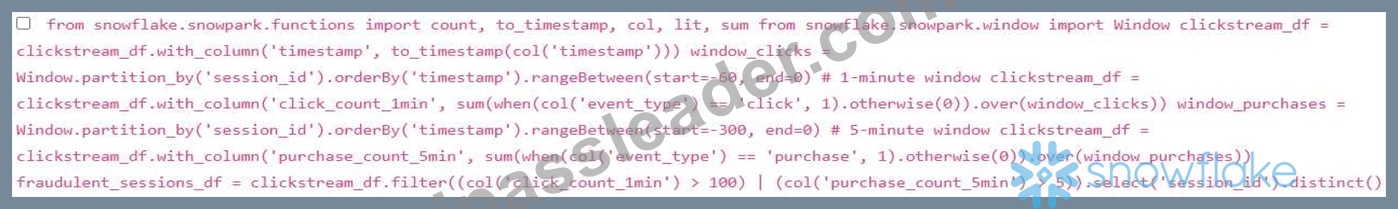
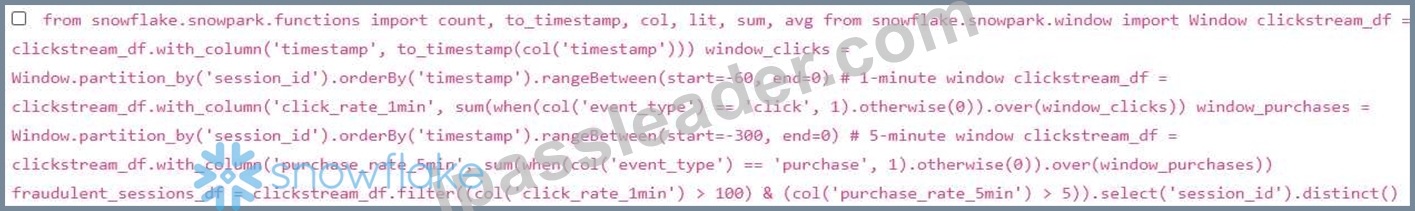
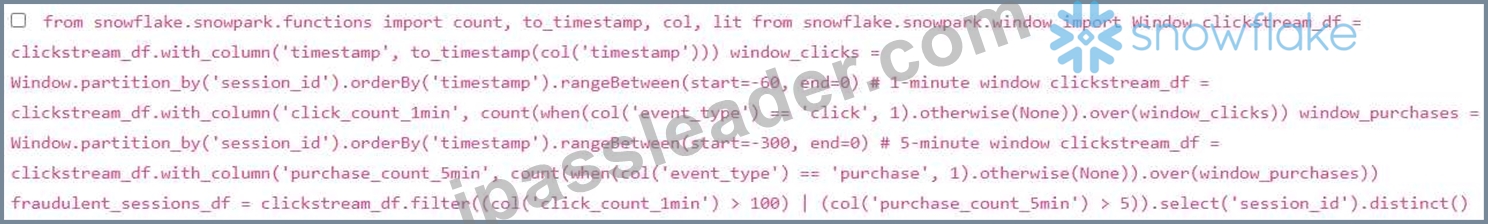
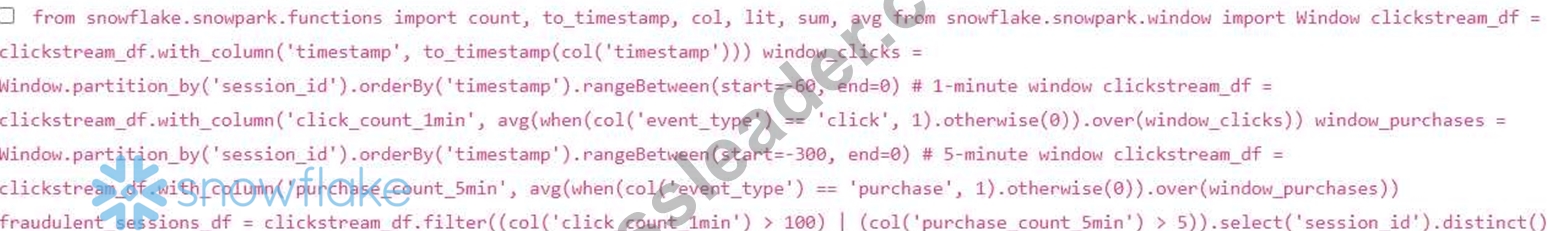
You are using Snowpark for Python to process a large dataset of website clickstream data'. The dataset contains columns such as 'session_id', 'user_id', 'timestamp', 'page_url', and 'event_type' (e.g., 'click', 'pageview', 'purchase'). You want to identify fraudulent user sessions based on the following criteria: A user session is considered fraudulent if it contains more than 100 clicks within a I-minute window. A user session is considered fraudulent if it contains more than 5 purchase events within a 5-minute window. Which of the following code snippets demonstrates the most efficient way to identify fraudulent sessions using Snowpark for Python? Select two that apply.

Answer: B,D
Explanation:
Options A and E are the most efficient and correct because they use window functions to calculate the click and purchase counts within the specified time windows and then filter the results based on the fraud criteria. Option A uses 'sum' on a conditional aggregation to count clicks and purchases. Option E Uses 'Count' and 'Otherwise(None)'. Option B is inefficient because it uses a UDF, which is slower than using built-in window functions. Options C and D are incorrect because 'click_rate_1min','purchase_rate_5min' are calculated incorrectly by making comparison, furthermore Option D uses average instead of SUM.
NEW QUESTION # 292
Consider the following Snowpark Python code snippet that defines and registers a User-Defined Table Function (UDTF):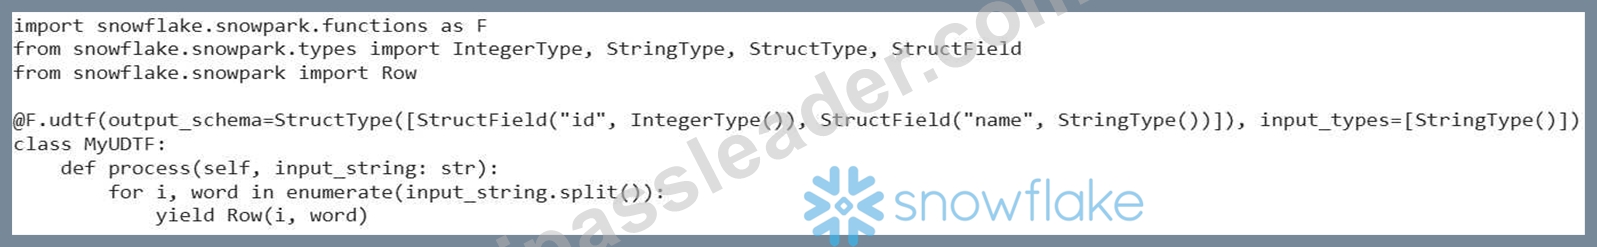
Which of the following statements is MOST accurate regarding the behavior and limitations of this UDTF when used in a Snowpark DataFrame transformation?
Answer: E
Explanation:
Option E is the most accurate. When a Snowpark UDTF receives NULL as input, it's passed as 'None' in Python. The provided code defines the 'output_schema' which describes the structure and types of the rows that the UDTF will return. Option A is incorrect because, while Snowflake distributes UDTF processing, the code itself doesn't guarantee parallelism within a single input string. Option B is incorrect; UDTFs can be used with any DataFrame, regardless of whether it's backed by a persistent table. Option C is incorrect because NULL values in the input DataFrame will be passed as 'None' to the 'process' method. Option D is incorrect; Snowpark distributes UDTF execution across worker nodes, not within the driver process.
NEW QUESTION # 293
You are tasked with deploying a Snowpark Python application that utilizes a third-party library, 'scikit-learn' , for machine learning tasks. The application will be executed as a Snowflake Stored Procedure. What are the necessary steps to ensure the 'scikit-learn' library is available within the Snowpark environment?
Answer: E
Explanation:
The correct approach is to create a Snowflake Anaconda environment with the required packages and then specify that environment when creating the Snowpark Stored Procedure. This ensures that the environment is available during execution. A is incorrect as session.add_import() is for local file imports. B is not the recommended and reliable approach. C is overly complex. E is incorrect as the environment in Snowflake must contain the dependency.
NEW QUESTION # 294
......
Our SPS-C01 practice materials not only reflect the authentic knowledge of this area, but contents the new changes happened these years. They are reflection of our experts’ authority. By assiduous working on them, they are dependable backup and academic uplift. So our experts’ team made the SPS-C01 Guide dumps superior with their laborious effort. Of course the quality of our SPS-C01 exam quiz is high.
SPS-C01 Reliable Dumps: https://www.ipassleader.com/Snowflake/SPS-C01-practice-exam-dumps.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by iPassleader: https://drive.google.com/open?id=1CQSu3SUKEFrooOGZBWYzK8UdCy6u5gEC